


Statistical Learning and Machine Learning: Classification, Regression, and Clustering

Course notes connecting SVMs, k-NN, K-Means, Naive Bayes, decision trees, regression, PCA/LDA, HMMs, n-grams, anomaly detection, evaluation, and model selection within one statistical-learning framework.
Statistical learning estimates relationships, decision boundaries, probability distributions, or latent structure from observed examples. Instead of encoding every decision as a hand-written rule, it represents regularities in data through a model. Its mathematical foundation is developed in Probability and Statistics; the focus here is how that foundation becomes classification, regression, clustering, dimensionality reduction, and anomaly detection.
Unit 1: Foundations of Statistical Learning
1.1. Data, Models, and Learning
A learning problem can be described through observations, features, and targets. An observation x is the feature vector supplied to the model; y is the target or label when one exists.
data
↓
feature representation
↓
model family
↓
objective / loss
↓
parameter estimation or search
↓
prediction on unseen data
The goal is not to memorize training examples but to capture structure that remains useful on new observations. Training performance and real-world performance are therefore different quantities.
1.2. Statistical Inference and Prediction
Classical statistics often emphasizes inference about parameters, effects, and uncertainty. Machine learning often shifts emphasis toward predictive performance on unseen data. The boundary is not sharp: regression, Bayesian estimation, sampling, likelihood, and regularization are shared tools.
A model that explains variation well is not automatically the best predictor, and a strong predictor does not by itself establish a causal relation.
1.3. Parametric and non-parametric Methods
A parametric method chooses a model form and estimates a finite parameter set. Linear and logistic regression are examples.
A non-parametric method makes a weaker fixed-form assumption rather than having no assumptions at all. k-Nearest Neighbors, kernel density methods, and several tree methods fall in this broad family. Distance, neighborhood, smoothness, or splitting criteria still provide inductive bias.
1.4. Generative and Discriminative Models
A generative model represents a joint distribution or the process that generates data conditional on a class:
p(x, y)
or
p(x | y) p(y)
Naive Bayes is a classic example.
A discriminative model focuses directly on the target conditional on the input or on a decision function:
p(y | x)
or
f(x) -> y
Logistic regression and SVMs are typical examples.
1.5. Learning Paradigms
- Supervised learning: labeled
x -> yexamples; classification and regression are the main tasks. - Unsupervised learning: no target label; clustering, density estimation, and some forms of dimensionality reduction search for structure in the inputs.
- Semi-supervised learning: a small labeled set is combined with a larger unlabeled set.
- Self-supervised learning: targets are derived from the structure of the data itself.
- Self-supervised learning: targets are derived from the structure of the data itself. / - Reinforcement learning: an agent learns a policy from rewards produced by interaction with an environment; it is a distinct sequential decision problem.
Avoiding accuracy-only evaluation under class imbalance. Consider a test set of 1200 cases with 200 positives and 1000 negatives. A classifier produces TP = 160, FN = 40, FP = 100, and TN = 900. Its accuracy is (160+900)/1200 ≈ 88.33%, but positive predictive precision is 160/(160+100) ≈ 61.54%, recall is 160/(160+40) = 80%, and specificity is 900/(900+100) = 90%. An always-negative classifier would already achieve 83.33% accuracy on this distribution. Selection therefore requires a task-specific metric, decision threshold, and calibration assessment. If the threshold is tuned from data, the final evaluation set must remain separate from selection. Related records from the same subjects or events must not leak across training and test partitions.
Unit 2: Representation, Scale, and Distance
For learning methods based on scale and distance, inspect variable units and distributions first. Estimate normalization parameters using training data only, then apply the same transformation to validation and test observations. Encoding categorical features can change what distance means, so verify that the representation matches the task. The degradation of neighborhood structure at high dimension is not automatically solved by simply adding more data.
2.1. The Data Matrix
A data set is commonly represented with observations in rows and features in columns:
X ∈ R^(n×p)where n is the number of observations and p the number of features. A target vector y is stored separately when present.
A categorical variable encoded with numbers does not thereby gain arithmetic meaning. Encoding 1=Ankara, 2=Istanbul does not imply that Istanbul is twice Ankara. Measurement level affects the valid notions of distance and the assumptions a model can make.
2.2. Scaling
Distance- and margin-based methods are sensitive to scale. If one feature is measured in kilometers and another lies in [0,1], the large-scale variable can dominate raw Euclidean distance.
Standardization is commonly written as:
z = (x - μ) / σMin-max scaling maps values into a selected range. Transformation parameters must be learned from the training data only and then applied unchanged to validation and test data. Fitting a scaler to the full data set before splitting leaks information.
Preprocessing parameters such as means and standard deviations must be estimated on training data alone. If the complete dataset has a mean of 50 but the training subset has a mean of 40, transforming a validation observation using (x−50)/s leaks information from observations that should remain unseen. The same problem affects imputation, categorical encoding, feature selection and PCA. Each cross-validation fold must refit preprocessing exclusively on its training portion. Putting columns on comparable numerical scales does not imply that they are equally important scientifically; the influence of each feature on a distance measure still needs domain-specific validation.
2.3. Similarity and Dissimilarity
For numeric data the Minkowski distance is:
d(x,y) = (Σ |x_i-y_i|^p)^(1/p)with Euclidean distance at p=2 and Manhattan distance at p=1.
Sparse text and high-dimensional vectors often use cosine similarity:
cos(x,y) = (x·y) / (||x|| ||y||)Nominal features may require matching-based distances; binary features may use Jaccard similarity. The distance measure is part of the model because it defines what “near” and “similar” mean.
2.4. Neighborhoods in High Dimensions
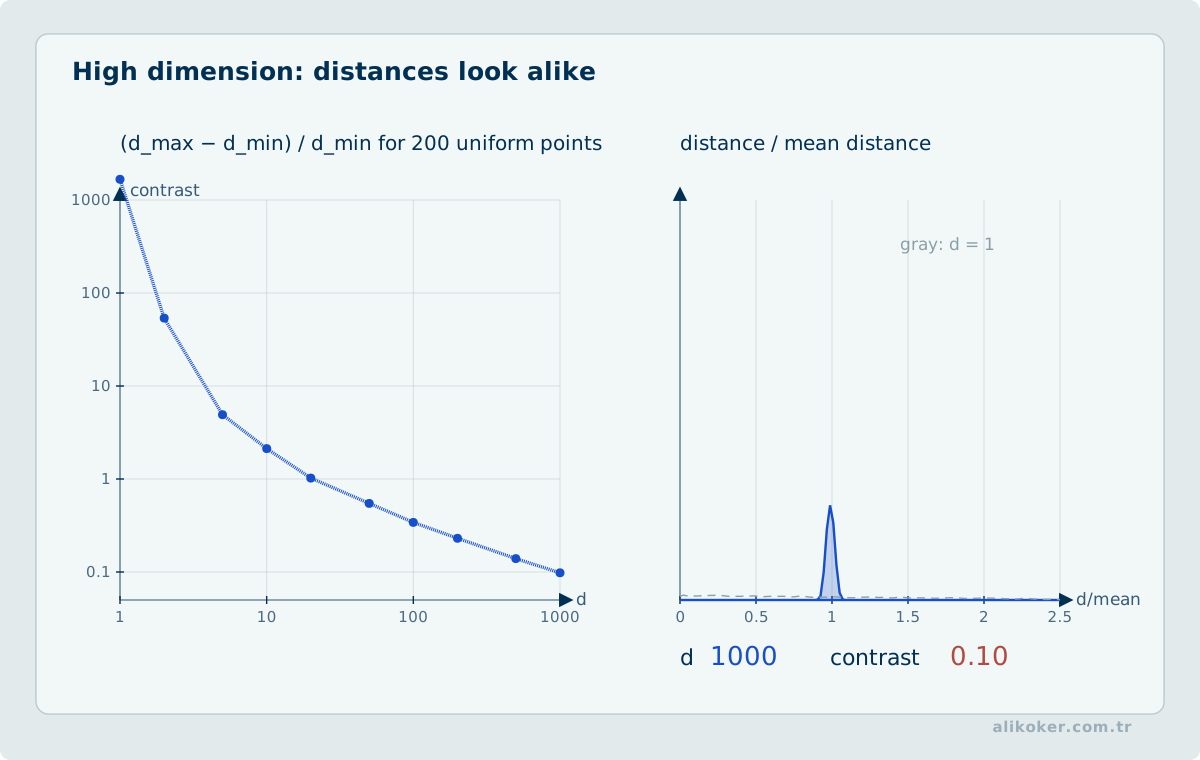
As dimension grows, data become sparse and pairwise distances can become less distinctive. This family of effects is known as the curse of dimensionality. k-NN, density estimation, and clustering are especially exposed. Feature selection and dimensionality reduction can therefore change model geometry rather than merely reduce runtime.
Unit 3: Objectives, Likelihood, and Generalization
Learning-objective selection begins by identifying which errors are operationally most costly. Choose a loss consistent with that priority; regularization, sample weighting, and decision thresholds affect behavior differently. Separate model-selection data from final evaluation data. Models with equal accuracy may differ substantially in calibration, subgroup errors, and robustness to distribution shift.
3.1. Empirical Risk
For model f_θ and per-example loss L, a common training objective is:
R_emp(θ) = (1/n) Σ L(y_i, f_θ(x_i))Minimizing training loss is only a proxy for the expected error on new data.
3.2. Maximum Likelihood
For a probabilistic model p(x | θ) or p(y | x, θ), maximum likelihood chooses parameters that make the observed data most probable:
θ_MLE = argmax_θ Π p(z_i | θ)Log-likelihood is normally used for numerical stability:
θ_MLE = argmax_θ Σ log p(z_i | θ)3.3. MAP Estimation
With a prior p(θ), maximum a posteriori estimation becomes:
θ_MAP = argmax_θ p(data | θ) p(θ)Several forms of regularization can be interpreted through corresponding parameter priors.
3.4. Negative log-likelihood, cross-entropy, and KL Divergence
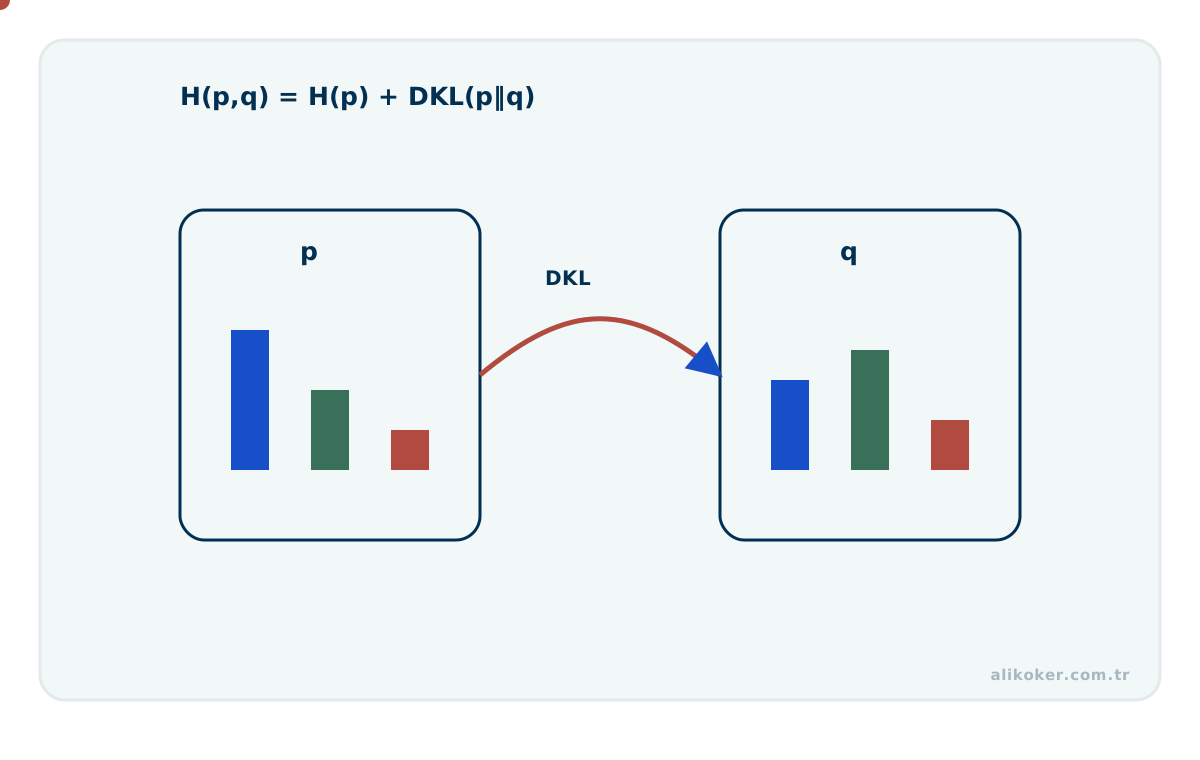
Likelihood-based training selects parameters that make the observed targets probable. Moving a product likelihood into log space improves numerical behavior and creates an additive objective:
NLL(theta) = - sum_i log p(y_i | x_i, theta).For categorical classification, the negative log-likelihood is the familiar cross-entropy loss under the usual target representation. For a data distribution p and model distribution q,
H(p,q) = H(p) + KL(p || q),so with fixed data distribution, minimizing cross-entropy also minimizes the corresponding KL(p||q) term. The loss is therefore tied to a probabilistic modeling assumption rather than being an arbitrary scoring rule.
3.5. Bias and Variance
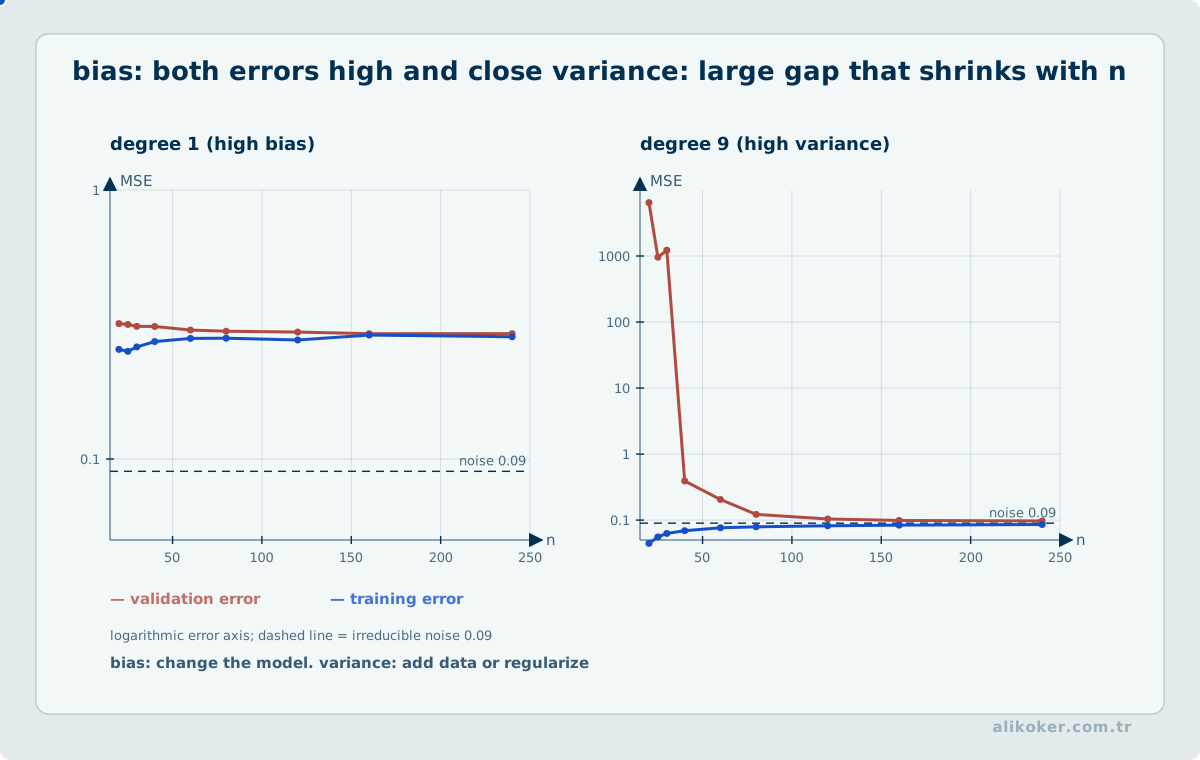
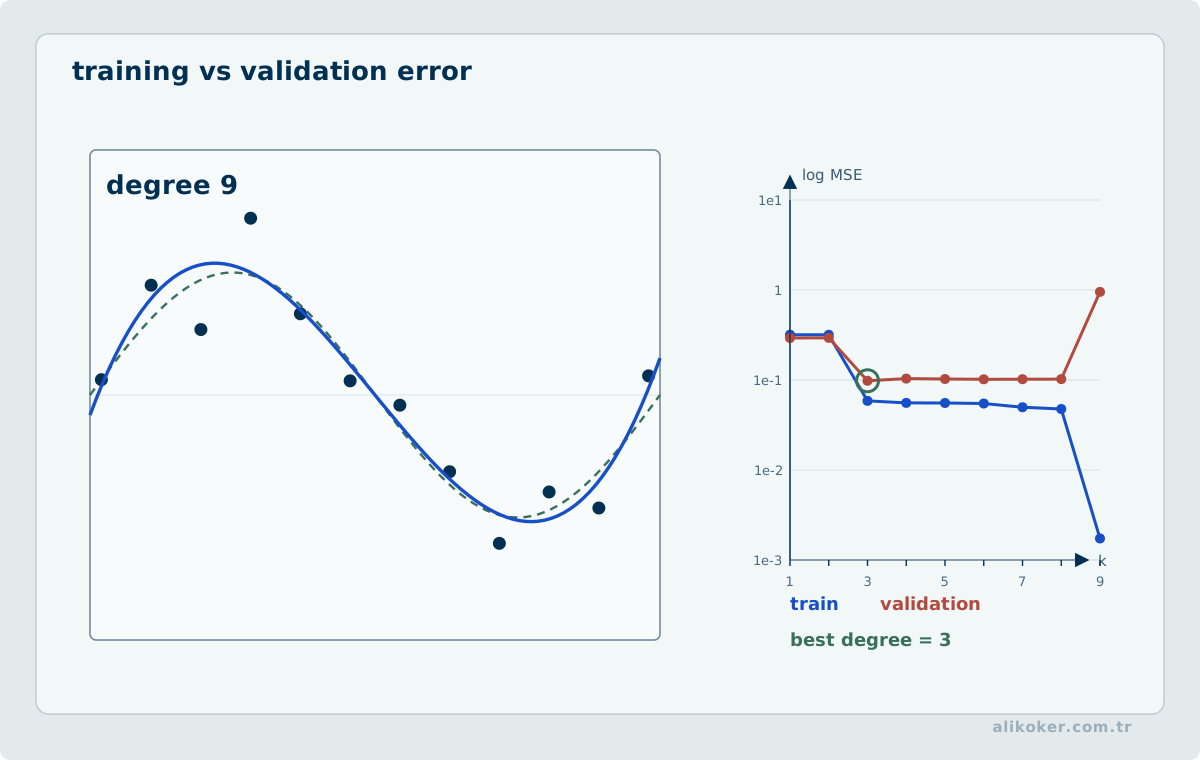
A model that is too rigid may have high bias and miss real structure. A model that is too flexible may have high variance and follow sampling noise. Model selection balances these sources of error under the available data and operational costs.
3.6. No Free Lunch
No single learning algorithm is uniformly best over every possible problem. Performance comes from matching the assumptions of a method to the structure of the data. Comparisons should therefore use the same data split, metrics, and computational budget.
Unit 4: Regression and Probabilistic Classification
4.1. Linear Regression
A simple linear model is:
Y = β0 + β1 X + εand multiple regression extends it to:
Y = β0 + β1X1 + ... + βpXp + εLeast squares minimizes:
min_β Σ (y_i - ŷ_i)^2Coefficient interpretation, residual structure, multicollinearity, and influential observations should be read together with the inferential treatment in Probability and Statistics.
4.1.1. From a Loss Function to a Parameter Update
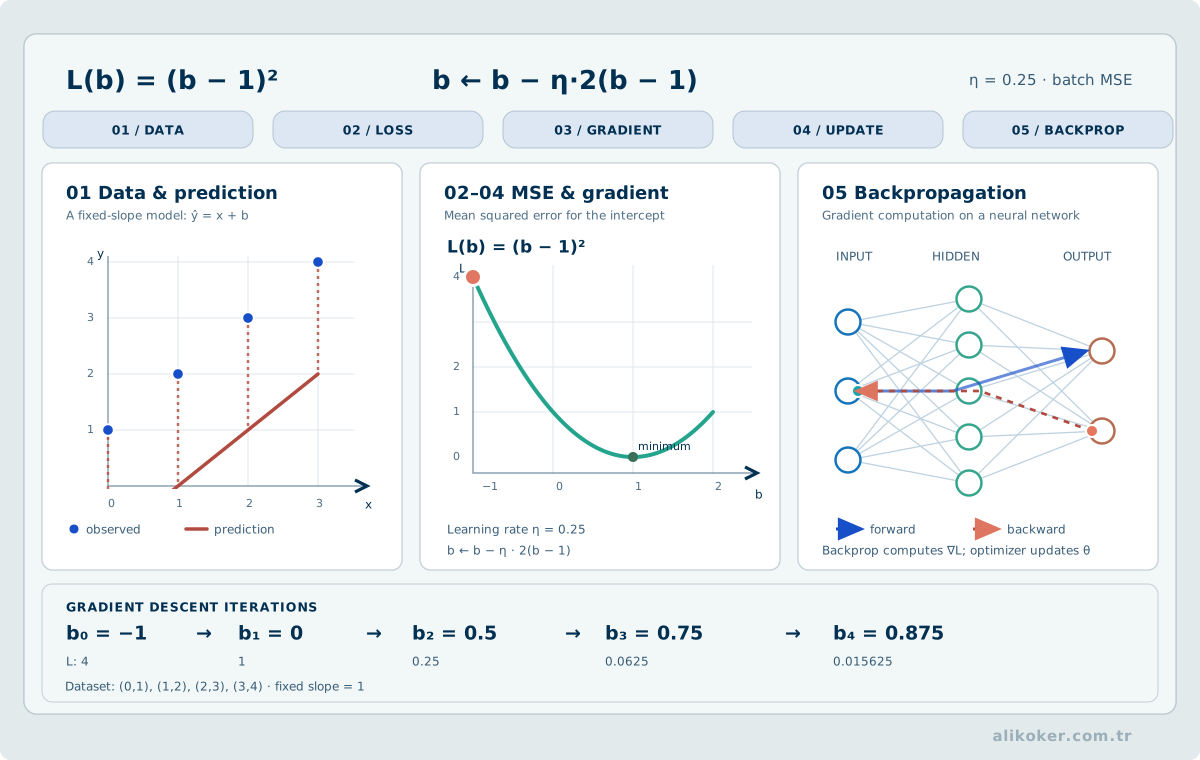
An optimization step makes sense only after defining both how the model predicts and what constitutes an error. For f(x) = m*x + b, m is the slope and b the intercept. Averaging signed residuals is not a suitable loss: positive and negative residuals can cancel. Mean squared error (MSE) removes this cancellation.
L(m,b) = (1/n) * Σ_i (m*x_i + b - y_i)^2

g_m = ∂L/∂m = (2/n) * Σ_i x_i * (m*x_i + b - y_i)
g_b = ∂L/∂b = (2/n) * Σ_i       (m*x_i + b - y_i)

m_new = m - η*g_m
b_new = b - η*g_b
A partial derivative indicates how the loss changes locally with one parameter; the two partial derivatives form a gradient vector. The negative-gradient direction is the direction of steepest local decrease for a sufficiently small step. The learning rate η controls step size rather than direction.
To isolate the underlying mechanism, the animation holds the slope **fixed at m = 1** and trains only the intercept. The observations are (x,y) = (0,1), (1,2), (2,3), (3,4), yielding exactly L(b) = (b - 1)^2. With b = -1, the four predictions are -1, 0, 1, 2, and their MSE is 4. The derivative is dL/db = 2(b - 1); for η = 0.25, the successive states are:
step     b         dL/db      L(b)
0       -1        -4         4
1        0        -2         1
2        0.5      -1         0.25
3        0.75     -0.5       0.0625
4        0.875    -0.25      0.015625
At each step the derivative is evaluated at the current parameter, followed by b_new = b - 0.25 * dL/db. Loss is divided by four on every iteration for this particular objective and learning rate. Such behavior is not universal: with η = 1, the parameter oscillates across the minimum and the loss does not decrease. When slope and intercept are both trained by least squares, the objective is a convex quadratic in m,b; uniqueness additionally requires a full-column-rank design matrix.
Lower training loss does not by itself establish better generalization. Validation data should separately inform model complexity and stopping decisions. Not every machine-learning algorithm relies on derivatives or gradient descent.
4.2. Polynomial Regression
“Linear” in linear regression refers to linearity in the parameters, not necessarily in the raw input. For example:
Y = β0 + β1X + β2X^2 + εis still linear in its coefficients. Higher degree increases flexibility and also the risk of overfitting.
4.3. Logistic Regression
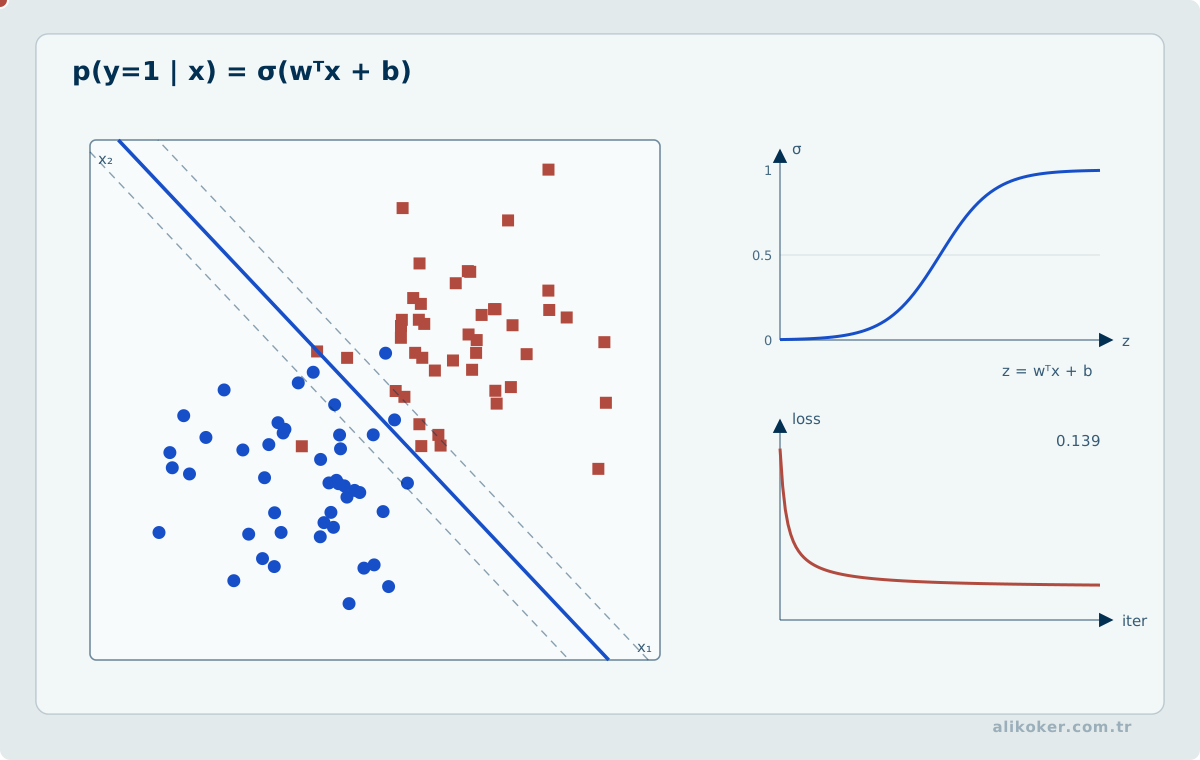
For binary classification:
z = β0 + β^T xcan be mapped to a probability with the sigmoid:
p(y=1|x) = 1 / (1 + e^(-z))A 0.5 threshold is not mandatory; it should reflect false-positive and false-negative costs. Despite its name, logistic regression is principally a classification method.
4.4. The Relationship Between Logit, Sigmoid, and Softmax
The linear score z in logistic regression is not itself a probability. In a binary model it represents the logarithm of the odds for the positive class:
logit(p) = ln(p/(1-p)) = z
sigmoid(z) = 1/(1+exp(-z))
At p=0.8, the odds are 4 and the logit is ln(4). As p approaches either boundary, the magnitude of the logit can grow without bound; logits and probabilities must not be compared as if they shared a scale. For several mutually exclusive classes, a score vector can be normalized with softmax:
softmax(z_i) = exp(z_i-m) / sum_j exp(z_j-m)
m = max_j z_j
Subtracting the same maximum score leaves the probabilities unchanged while reducing overflow risk. A sigmoid models a single binary outcome; softmax couples mutually exclusive alternatives through a shared denominator. Multilabel classification may instead use an independent sigmoid for each label. Neither transformation guarantees that the resulting model probabilities are calibrated; that property must be assessed separately.
4.5. Ridge, Lasso, and Elastic Net
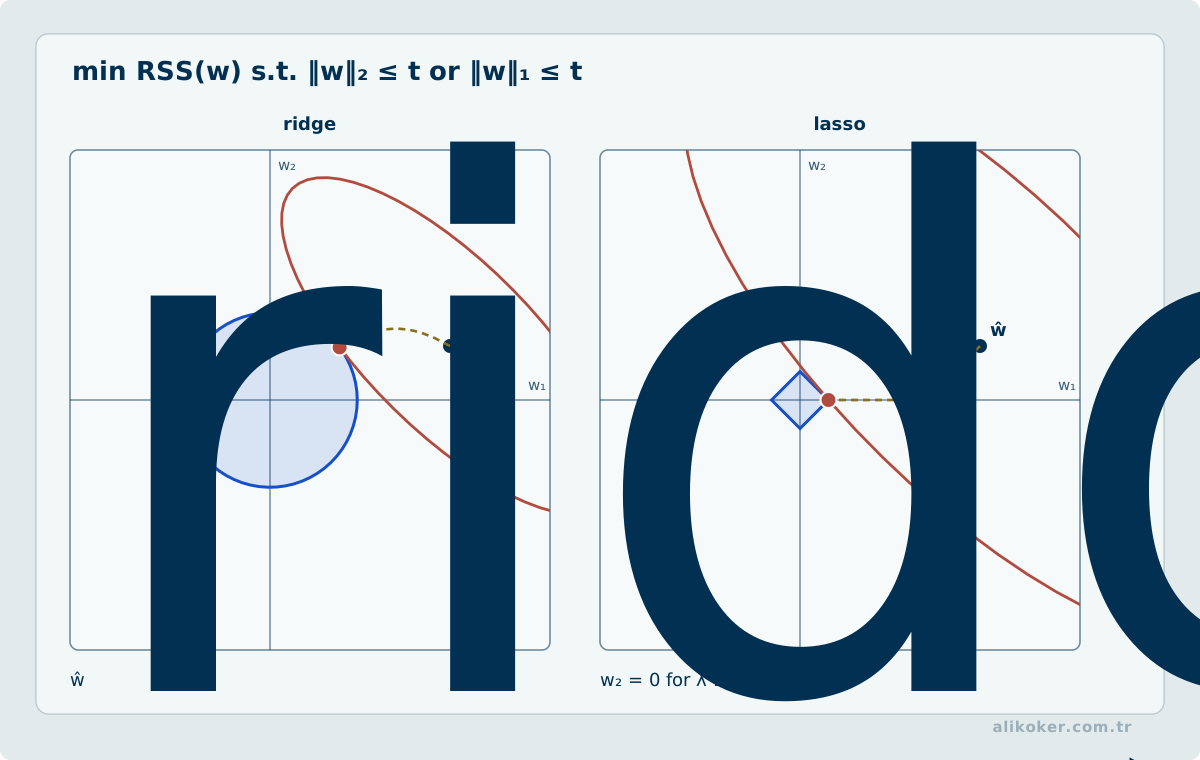
Ridge:
min_β SSE + λ Σ β_j^2Lasso:
min_β SSE + λ Σ |β_j|Elastic Net combines both penalties. Ridge shrinks coefficients; Lasso can drive some coefficients to zero and produce sparse solutions. Penalty strength should be selected by validation rather than chosen from training fit alone.
4.6. PCR and PLS
Principal Components Regression first maps predictors to PCA components and then performs regression. Since PCA does not use y, high-variance directions are not guaranteed to be the most predictive ones.
Partial Least Squares constructs components using covariance with the target as well as predictor structure. Both can be useful when predictors are numerous and strongly correlated.
4.7. Other Regression Families
- Support Vector Regression (SVR): extends margin ideas to continuous targets.
- Gaussian Process Regression (GPR): places a Gaussian-process prior over functions and can provide predictive uncertainty as well as a mean prediction; the kernel defines the covariance structure.
- Ordinal regression: for ordered categorical outcomes.
- Poisson regression: for count outcomes under a Poisson mean structure.
- Negative-binomial regression: can model overdispersed counts when Poisson assumptions are too restrictive.
The model family should match the nature of the target and the error process.
In weighted least squares, appropriate weights can account for unequal error variances, but estimating weights from an unknown variance structure introduces additional uncertainty. Weighting does not repair an incorrect conditional mean model. Quantile regression instead estimates a selected conditional τ-quantile using an asymmetric absolute loss, permitting effects to be compared across different portions of the response distribution.
A generalized additive model (GAM) introduces smooth functions into an additive predictor: g(E[Y|X]) = β₀ + f₁(X₁) + … + fₚ(Xₚ). Smoothness penalties and effective degrees of freedom govern the balance between flexibility and overfitting. Unlike an ordinary GLM with a linear predictor, a GAM admits constrained nonlinear component functions.
4.8. Generalized Linear Models
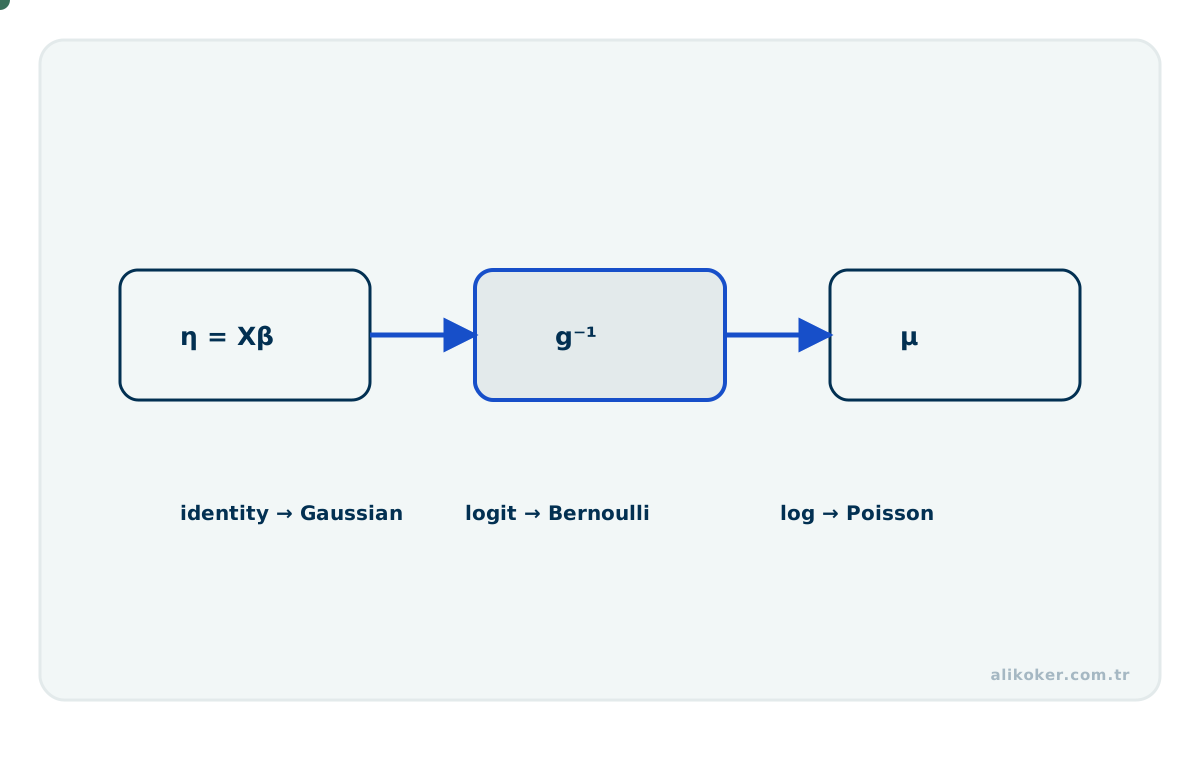
Linear and logistic regression can be placed inside the generalized linear model (GLM) framework instead of being memorized as unrelated formulas. A GLM separates a response distribution, a linear predictor, and a link function connecting the mean response to that predictor.
- Gaussian response with identity link leads to ordinary linear regression.
- Bernoulli response with logit link leads to logistic regression.
- Poisson response with log link provides a natural count model.
When a Poisson model's mean-equals-variance restriction is inadequate, overdispersion may be present; a negative-binomial family can model additional dispersion.
This reframes model selection from "which algorithm?" toward the structure of the response distribution and link function.
4.9. Geometry of L1 and L2 Regularization
L2 regularization constrains an Euclidean norm, while L1 uses the sum of absolute coefficient values. When loss contours meet these different constraint geometries, the corners of the L1 region make exact zero coefficients more likely.
Sparsity in Lasso is therefore not a coincidence of a particular optimizer. Ridge instead tends to shrink correlated coefficients together. Because feature scale directly affects the penalty, standardization is part of the modeling pipeline rather than a cosmetic preprocessing choice.
Unit 5: k-Nearest Neighbors
5.1. Core Idea
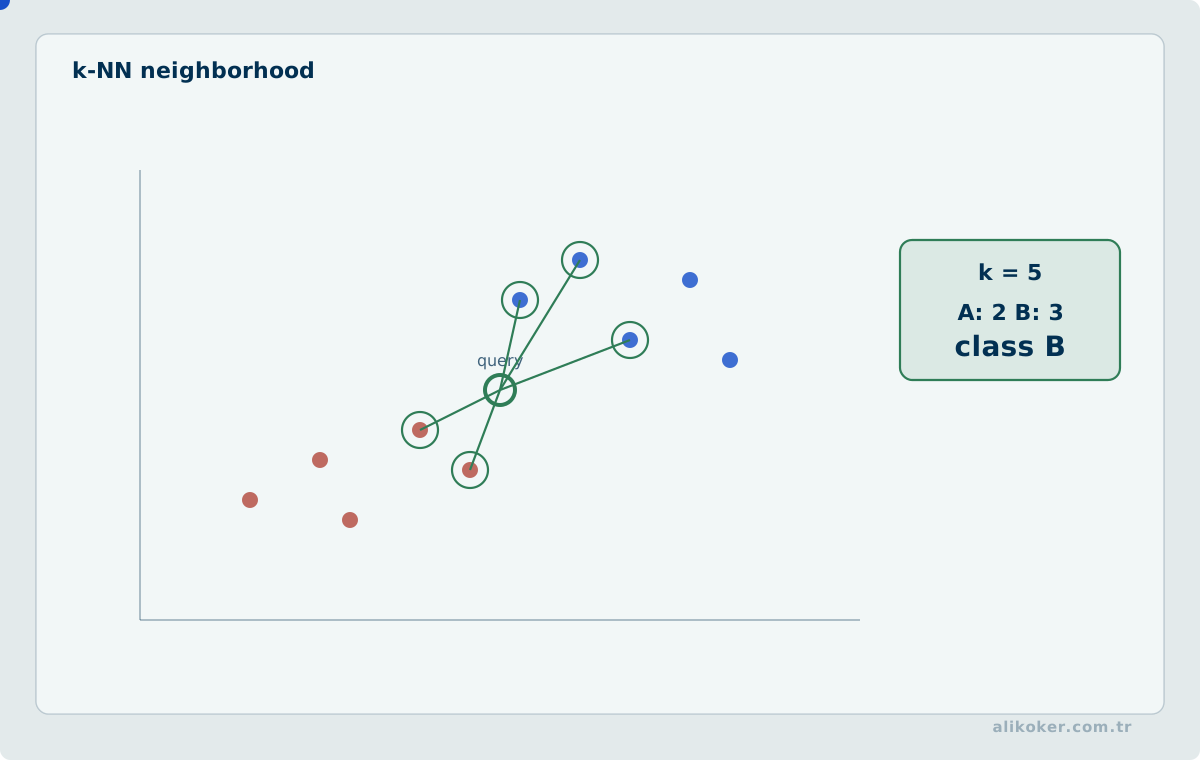
k-Nearest Neighbors (k-NN) predicts a new observation from the nearest k training examples. Because it does not fit a complex global parametric model during training, it is often called instance-based or lazy learning.
Classification uses a local vote:
ŷ = majority class among the k nearest neighborsRegression can average the target values of the neighbors.
5.2. Choosing K
k=1 creates a very local boundary and can be sensitive to noise. Large k values smooth the prediction but can erase genuine local structure. k is a hyperparameter and should be selected by validation.
5.3. Weighted Voting
Closer neighbors can receive larger weight, for example:
w_i = 1 / (d_i + ε)with explicit handling for zero distance.
5.4. Computational Cost
A naive query compares the new point with all training examples. KD-trees and ball trees can help at low or moderate dimension, but high-dimensional indexing deteriorates. Approximate-nearest-neighbor methods provide a different speed–accuracy trade-off for large vector spaces.
5.5. Strengths and Limitations
k-NN is simple, locally explainable, and can express nonlinear boundaries. It is also:
- scale sensitive,
- sensitive to irrelevant features,
- vulnerable to the curse of dimensionality,
- potentially expensive at query time,
- affected by class imbalance.
Preprocessing is therefore part of the algorithmic design.
Unit 6: Bayesian Classification and Naive Bayes
6.1. Bayes' Theorem
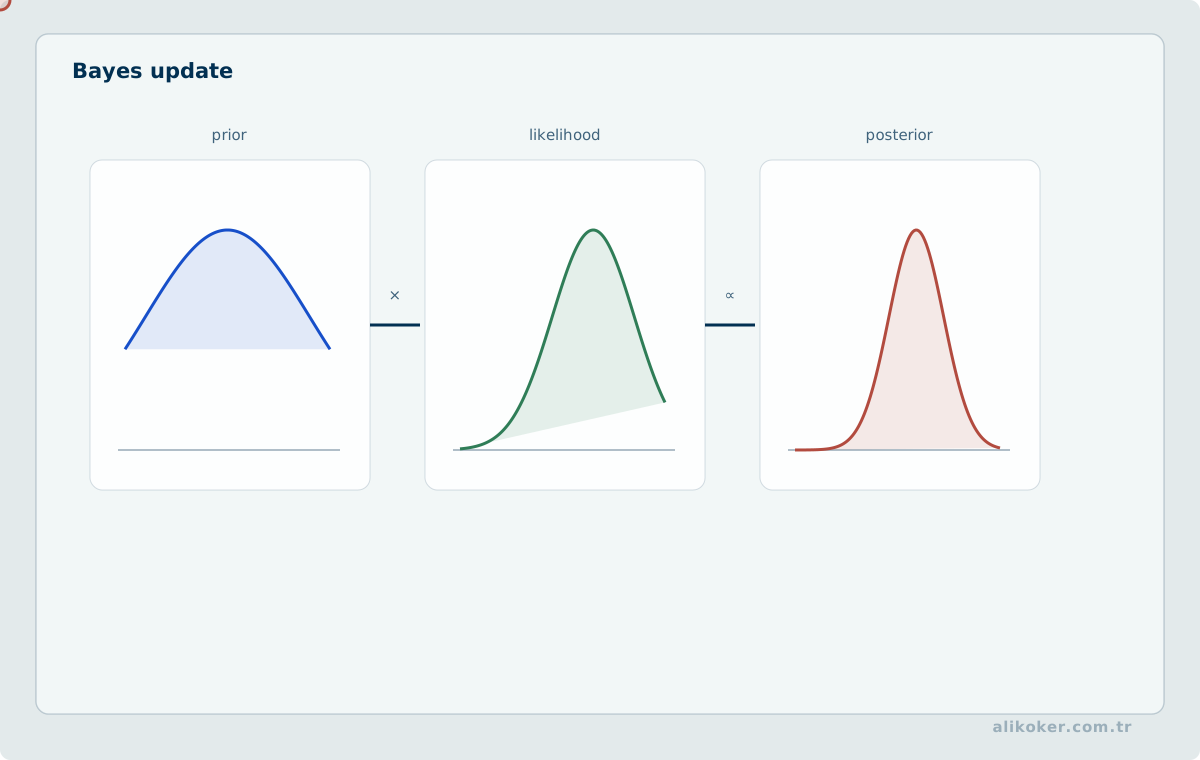
For class C and observed features x:
P(C | x) = P(x | C) P(C) / P(x)When comparing classes, the common denominator can be omitted:
P(C | x) ∝ P(x | C) P(C)P(C) is the prior, P(x|C) the likelihood, and P(C|x) the posterior.
6.2. The Naive Assumption
Naive Bayes assumes conditional independence of the features given the class:
P(x1,...,xp | C) = Π P(x_j | C)The assumption is rarely exact, yet the classifier can be a strong baseline, especially for sparse high-dimensional text data.
The conditional-independence assumption in Naive Bayes is not a claim that features are independent in general: it approximates their joint likelihood as a product of individual likelihoods given the class. Closely related word forms can violate this assumption and distort probability calibration, even when the resulting decision rule remains useful. A feature absent from the examples of one class may otherwise receive probability zero, collapsing a product of likelihoods. Smoothing reduces this numerical problem in count-based variants; the smoothing strength, class imbalance and probability calibration still need independent validation.
6.3. Gaussian, Multinomial, and Bernoulli Variants
- Gaussian Naive Bayes: continuous features modeled with class-conditional Gaussian distributions.
- Multinomial Naive Bayes: count features such as token frequencies.
- Bernoulli Naive Bayes: binary feature presence/absence.
The representation determines which variant is appropriate.
6.4. Zero Counts and Laplace Smoothing
An unseen token can make a raw product probability zero. Additive smoothing uses:
P(w|C) = (count(w,C) + α) / (Σ count(.,C) + α|V|)with α=1 for classical add-one smoothing.
6.5. Log-space Computation
Products of many small probabilities can underflow numerically. The equivalent log-space score is:
log P(C|x) ∝ log P(C) + Σ log P(x_j|C)6.6. Spam Classification
Naive Bayes with token or n-gram count features is a classic spam-filtering baseline. Spam Detection with Data-Mining Techniques applies the idea together with text features and classification metrics.
Unit 7: Support Vector Machines
7.1. Maximum Margin
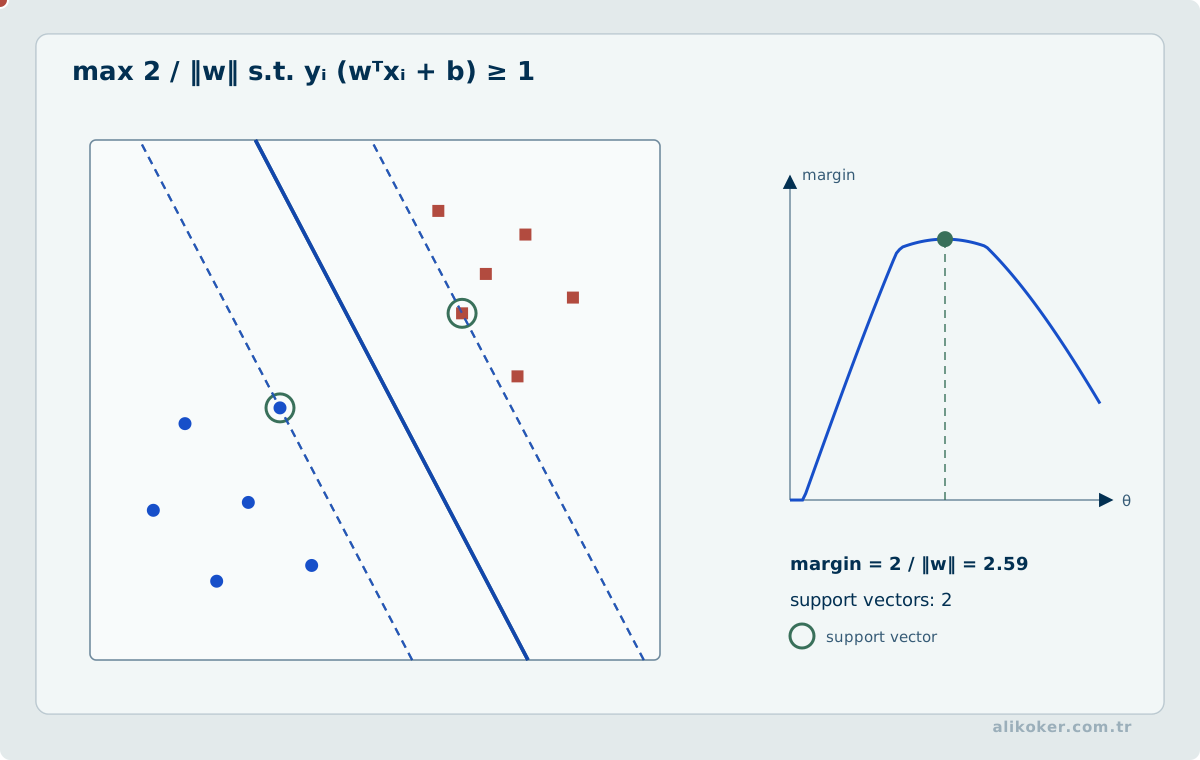
A linear binary decision surface is:
w^T x + b = 0An SVM seeks not just a separator but one with a large margin to the closest observations from the two classes. The observations that determine that geometry are the support vectors.
7.2. Hard Margin
For perfectly separable data:
y_i (w^T x_i + b) >= 1with objective:
min 1/2 ||w||^2Real data often contain noise and overlap, making hard-margin assumptions too strict.
7.3. Soft Margin and C
Slack variables ξ_i permit controlled violations:
min 1/2 ||w||^2 + C Σ ξ_iLarge C penalizes training violations more strongly; small C permits a wider margin with more violations. Neither direction is universally better.
In a soft-margin support vector machine, increasing C increases the penalty for margin violations on training examples; it does not guarantee better generalization. Fitting an incorrectly labeled outlier may distort the separating boundary. Reducing C permits more violations but can also oversimplify the model. Kernel settings and feature scaling change this tradeoff. Parameter selection should not rely on training accuracy alone: it requires validation that respects group or temporal independence, with the final test set remaining untouched until model selection is complete.
7.4. Kernels
A nonlinear feature map φ(x) can be represented implicitly with:
K(x,z) = φ(x)^T φ(z)Common kernels include linear, polynomial, RBF/Gaussian, and sigmoid kernels. With an RBF kernel, γ controls locality and interacts strongly with feature scaling and C.
7.5. Multiclass SVM
The basic SVM is binary. Multiclass classification is commonly implemented with one-vs-rest or one-vs-one decompositions; evaluation should account for the strategy used by the implementation.
7.6. SVR
Support Vector Regression extends the margin framework to continuous targets, often using an ε-insensitive region around the prediction function.
Unit 8: Decision Trees and Ensemble Learning
8.1. Decision Trees
A decision tree repeatedly splits the data using feature tests. Internal nodes represent tests; leaves represent final predictions. A path from root to leaf can often be written as a human-readable rule.
8.2. Entropy and Information Gain
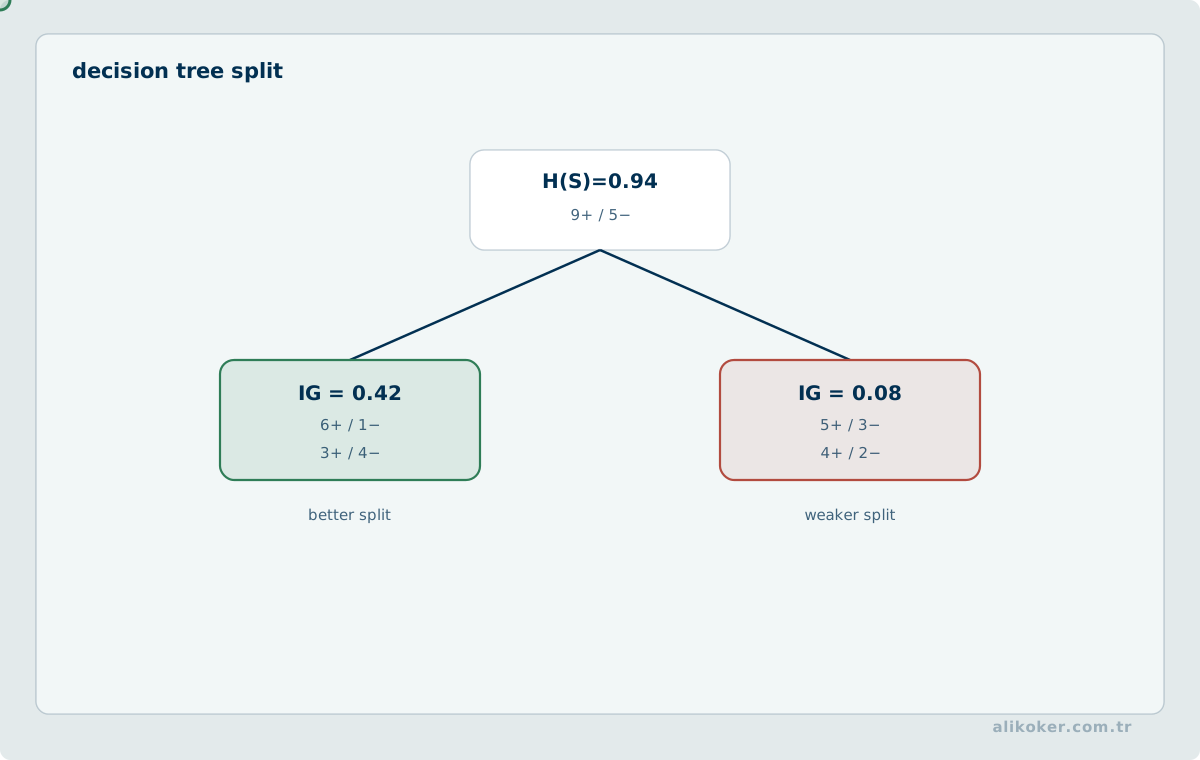
For class probabilities p_k:
H = -Σ p_k log2 p_kA split can be scored by the reduction in entropy. ID3 is classically associated with information gain, while C4.5 uses gain ratio to reduce preference for high-cardinality attributes.
8.3. Gini Impurity
CART commonly uses:
Gini = 1 - Σ p_k^2for classification. Regression trees use continuous-error objectives such as squared error.
8.4. Overfitting and Pruning
Deep trees can partition training data too finely and develop high variance. Maximum depth, minimum leaf size, minimum split gain, and pruning limit complexity.
8.5. Bagging and Random Forest
Bagging trains models on bootstrap samples and aggregates their outputs. Random Forest additionally considers a random subset of features at each split, reducing correlation among trees.
Classification commonly uses voting; regression commonly uses averaging.
8.6. Boosting
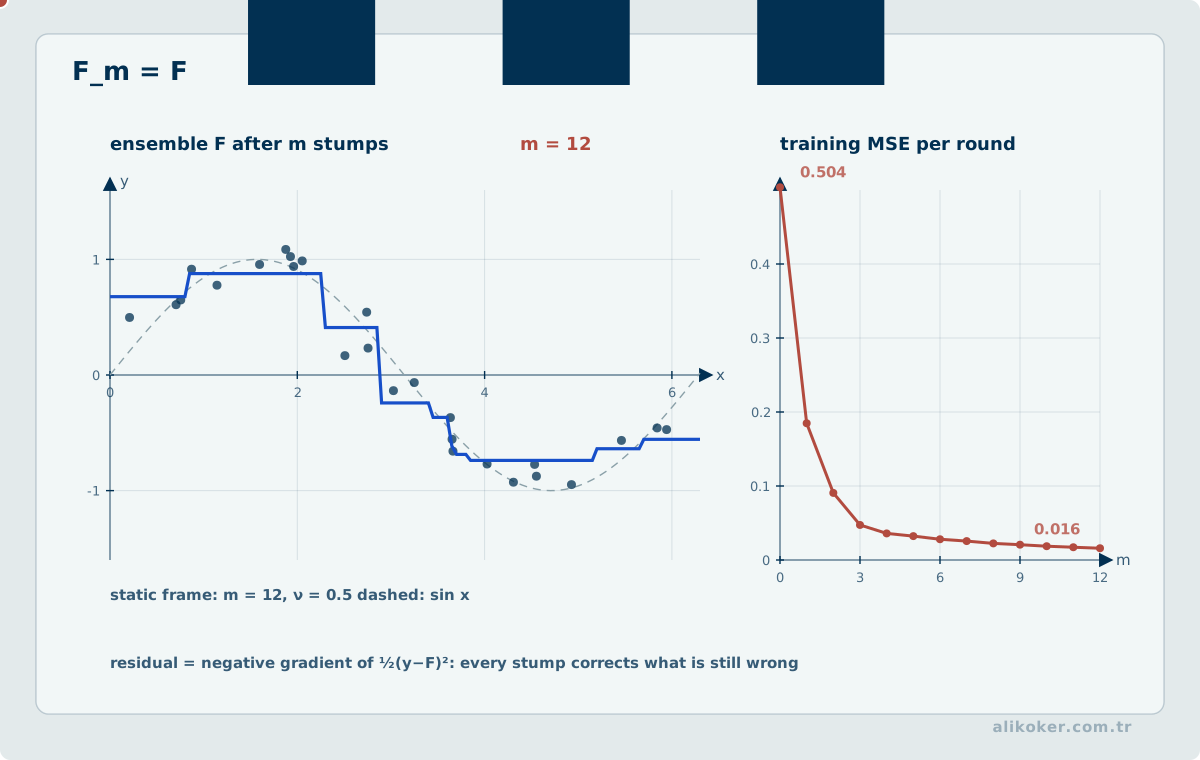
Boosting builds learners sequentially so later learners focus on earlier errors. AdaBoost and gradient boosting implement this general idea differently. Ensembles still require validation; they do not automatically dominate a well-matched simpler model.
8.7. Variable Relevance and Interaction Selection in Random Forests
A random forest can reduce the high variance of a single tree by combining tree predictions. Yet calling a predictor important does not establish a causal effect on the response. Importance scores derived from total impurity reduction may favor variables offering many candidate splits. Permutation importance also requires care with strongly correlated features: scrambling one variable may destroy the observed joint distribution while much of its information remains available through other features.
Interaction analysis must allow for predictors that appear weak marginally but become informative conditional on another variable. Ranking only individual effects and keeping the top few may therefore miss important dependencies. Tree ensembles designed for interaction analysis should be assessed on held-out data and, where possible, against sensitivity to confounding. An interaction detected in observational data is not an intervention effect unless a separate causal-identification argument supports that reading.
Bayesian additive regression trees (BART) model the response as a sum of regularized contributions from relatively small trees rather than one large tree. Priors over tree structures and terminal-node values constrain flexibility, while posterior sampling permits an assessment of predictive uncertainty. Random forests, gradient boosting and BART belong to the tree-model family, but their fitting objectives and interpretations of uncertainty differ.
Unit 9: Clustering and Mixture Models
9.1. The Clustering Problem
Clustering groups unlabeled examples according to a selected notion of similarity. A cluster has no intrinsic physical name: interpretation is supplied after the algorithm by domain knowledge.
Clustering quality cannot be established by a single internal score. A measure such as silhouette depends on the selected distance geometry and cluster shape and may penalize naturally separated but interlocking structures. K-means favors comparatively compact Euclidean clusters, whereas density-based procedures can recover very different shapes. Stability of cluster membership under defensible changes in feature scale provides evidence beyond one reported score. Assigning human-readable names to clusters is a separate interpretation problem, not part of the optimization objective itself.
9.2. K-Means
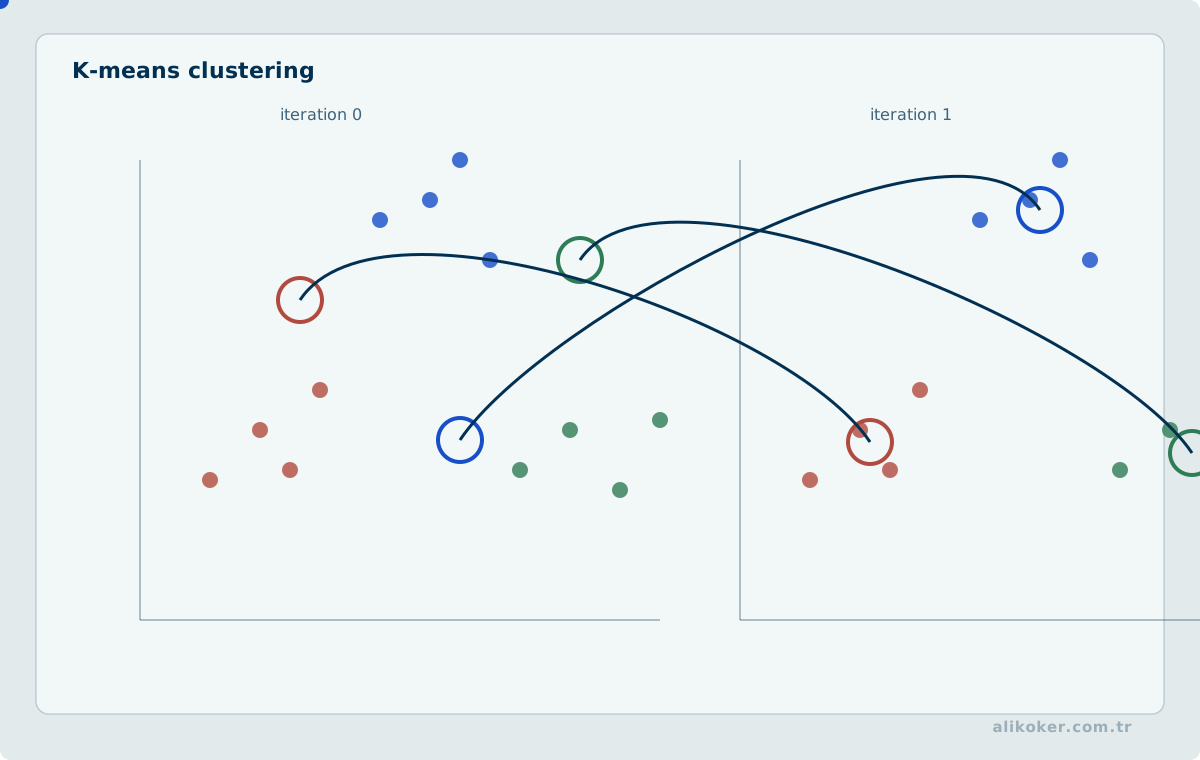
K-Means minimizes within-cluster squared distance:
J = Σ_k Σ_{x_i ∈ C_k} ||x_i - μ_k||^2The Lloyd iteration is:
- initialize
Kcenters, - assign each point to its nearest center,
- recompute each center as the mean of its assigned points,
- repeat until assignments/centers stabilize.
The objective does not increase from one iteration to the next, but the final solution need not be the global optimum and depends on initialization.
9.3. K-Means++ and Choosing K
K-Means++ improves initialization by spreading initial centers. The elbow method is heuristic; silhouette scores compare cohesion with separation. Some data sets do not contain one natural value of K.
K-means can converge to different local solutions on the same observations depending on initial centroids. With two large separated groups and a small intermediate group, minimizing within-cluster squared error may fail to preserve the small group as a distinct cluster. Multiple initializations, feature-scale sensitivity and stability across candidate cluster counts should be examined. A silhouette value or elbow curve cannot establish a true number of categories by itself. For exploratory clustering, robustness on new data and substantive interpretation matter. Sparse text representations require additional care about Euclidean distance, vector normalization and the role of cosine similarity.
9.4. K-Medoids, PAM, CLARA, and CLARANS
K-Medoids uses an observed data point as the representative of each cluster. This can be more robust to outliers and can work with dissimilarities where a mean is not meaningful.
PAM is the classical medoid algorithm. CLARA applies PAM to samples for scalability. CLARANS searches sampled neighborhoods of medoid solutions.
9.5. Fuzzy C-Means
Fuzzy C-Means gives each observation a degree of membership in multiple clusters instead of a single hard assignment. The mathematics of graded membership is developed in Fuzzy Logic.
9.6. Hierarchical Clustering
Agglomerative clustering starts from individual points and merges them; divisive clustering starts from the full data set and splits it. Single, complete, average, and Ward linkage can produce materially different dendrograms.
AGNES and DIANA are classical hierarchical methods. BIRCH uses summary structures for scalability; CURE/CAMELEON-style approaches extend cluster representation and connectivity for more complex geometry.
9.7. DBSCAN
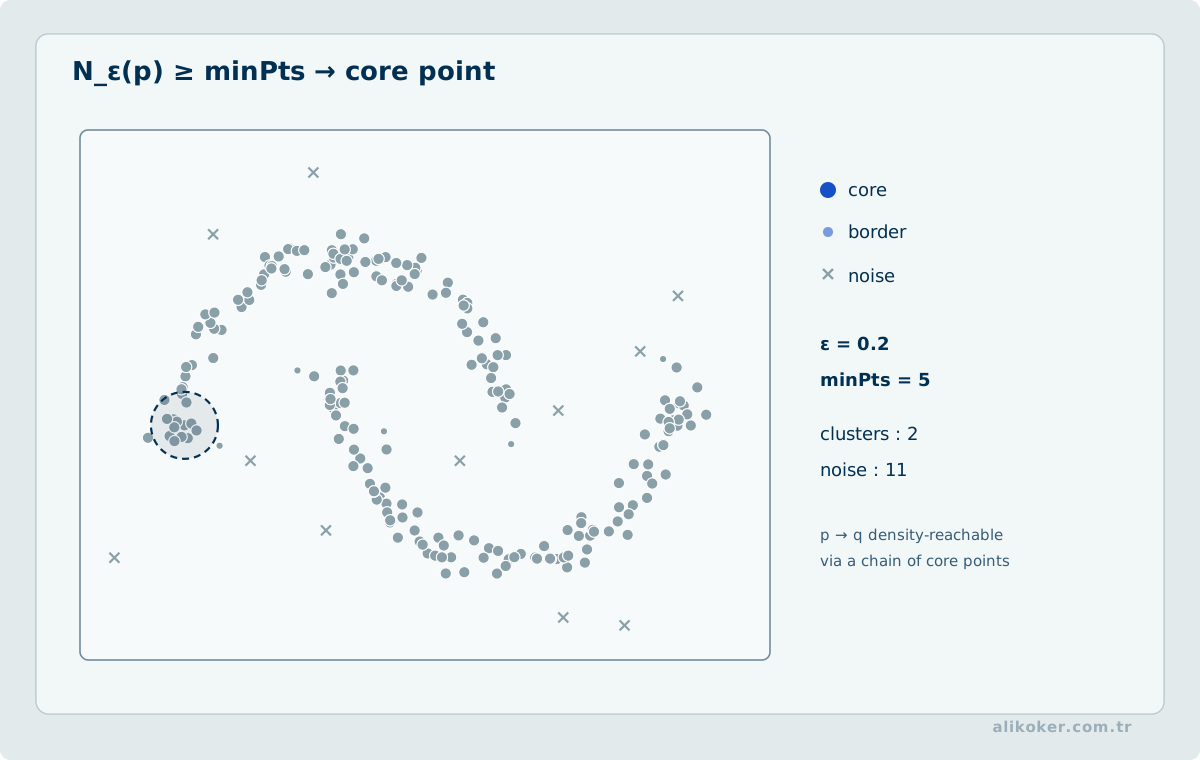
DBSCAN uses an ε neighborhood and minPts to identify dense regions and noise without requiring the number of clusters in advance. It can find non-spherical clusters but struggles when one global density threshold cannot represent all regions.
9.8. Gaussian Mixtures and EM
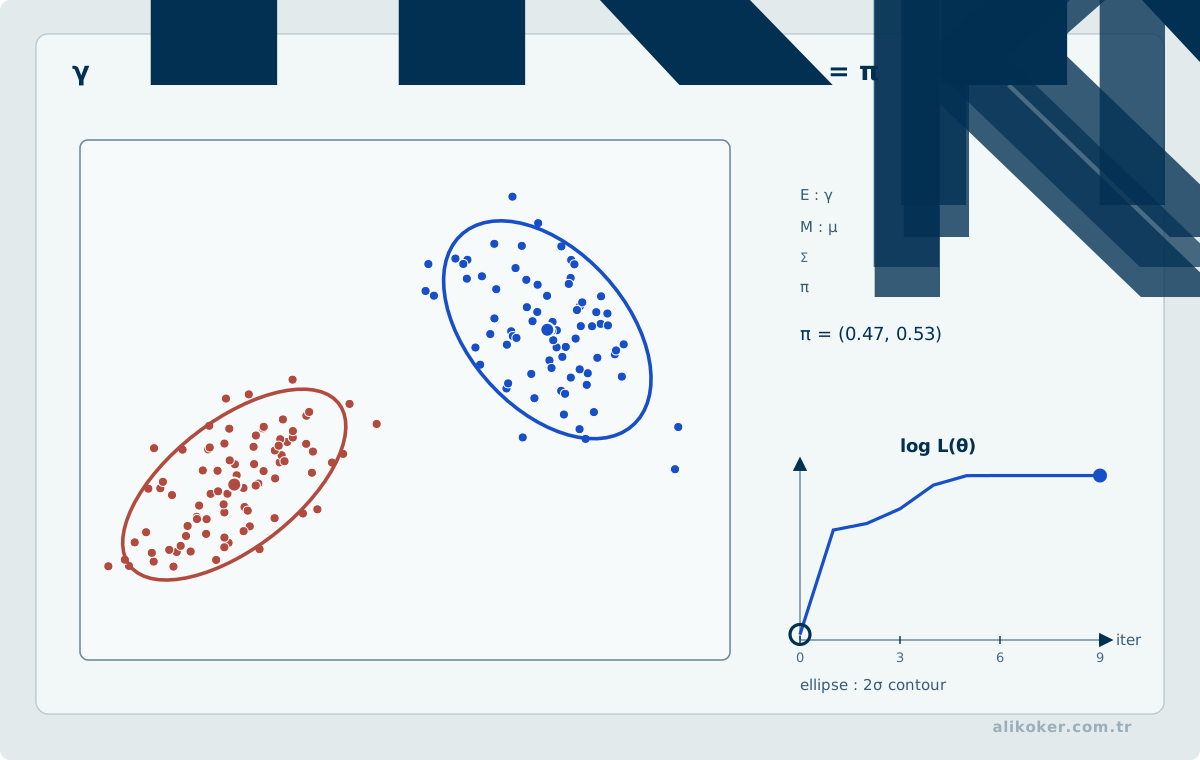
A Gaussian Mixture Model represents the data as a mixture of Gaussian components:
p(x) = Σ_k π_k N(x | μ_k, Σ_k)Each observation has a probabilistic responsibility for each component. Expectation-Maximization alternates:
E step: estimate component responsibilities
M step: update parameters from those responsibilities
GMMs therefore provide soft probabilistic membership in contrast to the hard assignments of standard K-Means.
9.9. Reading EM Through Latent Variables
In mixture models, component membership is a latent variable. Expectation-Maximization (EM) avoids directly optimizing those missing assignments by alternating two steps:
- the E step computes expected latent memberships under current parameters;
- the M step updates parameters under the resulting expected complete-data objective.
EM is designed not to decrease likelihood at each iteration, but it does not generally guarantee a global optimum. Initialization, the number of components, and local optima can matter. K-Means can also be related to this alternating assignment/update view under an appropriate limiting model.
Unit 10: Dimensionality Reduction and Feature Selection
10.1. Selection versus Transformation
Feature selection keeps a subset of existing variables. Dimensionality reduction commonly creates new axes. They solve related but different problems.
10.2. PCA
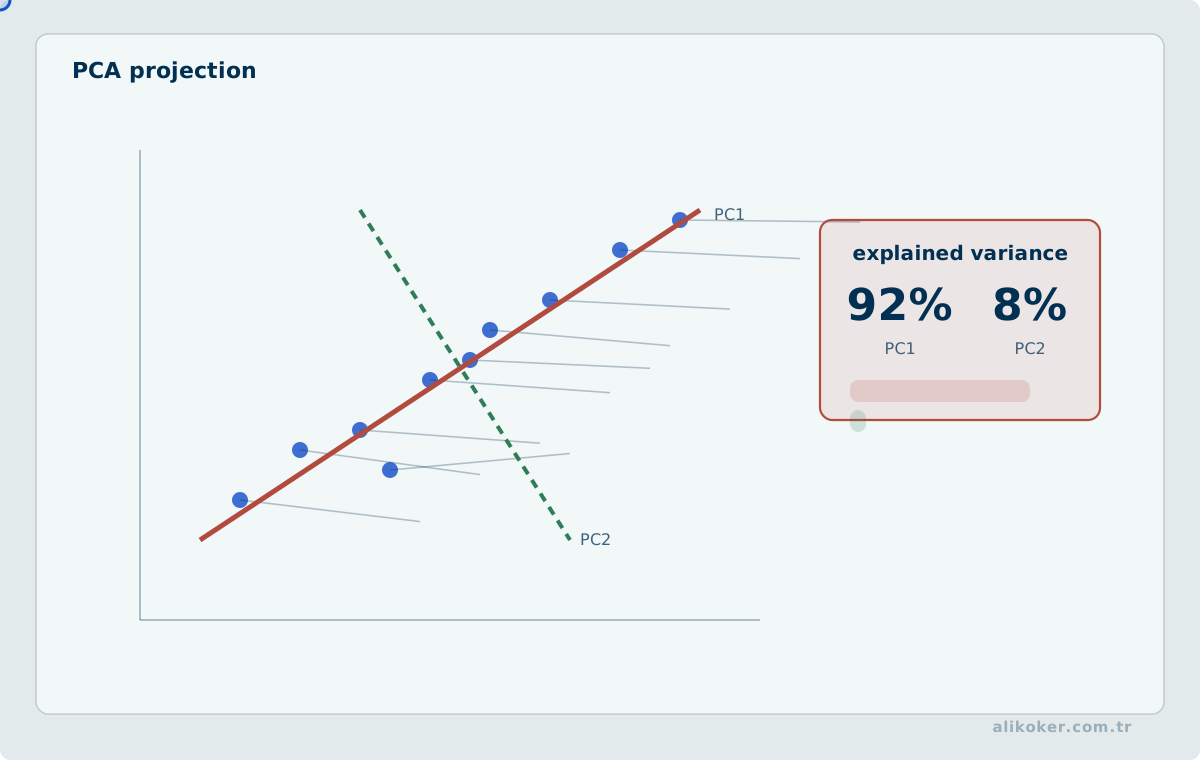
Principal Component Analysis finds orthogonal linear directions that capture high variance. For centered data it can be computed from covariance eigenvectors or through SVD.
PCA does not use labels. High variance is therefore not necessarily the direction that best separates classes. Scaling can materially change PCA when input units differ.
PCA selects directions by variation in the inputs, not by predictive relevance to a label. Suppose two measured features have variances 100 and 1 respectively, while the target classes differ consistently only along the second feature. Retaining the single component of greatest variance may discard the most useful discriminative information. Centering and, where justified, scaling form part of the learned PCA pipeline and cannot be refitted independently on the test set. Explained variance is a measure of retained input variability, not a substitute for downstream task performance.
10.3. SVD
A matrix can be decomposed as:
X = U Σ V^TA truncated decomposition retains the largest singular values to produce a lower-rank approximation. SVD is mathematically closely related to common PCA computations.
10.4. LDA
Linear Discriminant Analysis uses class labels and seeks projections that increase between-class separation relative to within-class scatter. Conceptually:
J(w) = (w^T S_B w) / (w^T S_W w)With C classes, the discriminant subspace has dimension at most C-1.
PCA and LDA therefore answer different questions: PCA preserves unlabeled variance; LDA uses class-separation information.
10.5. Feature-selection Families
Filter methods use model-independent measures such as correlation, information gain, or statistical tests. Wrapper methods evaluate subsets through model performance. Embedded methods perform selection as part of model fitting, as with Lasso or some tree-based procedures.
Selection must be performed inside the training process; selecting features after examining the test set contaminates evaluation.
Unit 11: Anomaly and Outlier Detection
11.1. Context Matters
An outlier is an observation that differs substantially from expected behavior, but unusual does not always mean erroneous. Useful distinctions include:
- point outlier: one observation departs from the overall distribution,
- contextual outlier: unusual only under a particular time, location, or condition,
- collective outlier: a group is abnormal even when individual members appear ordinary.
Noise may represent measurement uncertainty, whereas an anomaly may be the event of interest.
11.2. Statistical Approaches
When a distributional model is credible, low-probability regions can define anomaly candidates. Gaussian z-scores, Grubbs-style tests, boxplots/IQR, histograms, and mixture models represent different levels of parametric commitment.
If the distributional model is wrong, a low-probability score can also be wrong. Outliers can themselves distort estimated parameters, making robust statistics important.
11.3. Regression Residuals
Large residuals:
r_i = y_i - ŷ_ican indicate abnormal behavior. A poor regression model, however, also produces large residuals; model error and anomaly must not be conflated.
11.4. Proximity and Density
k-NN distances can score isolated points. Local Outlier Factor compares local density with the density of neighbors. Values near one indicate similar local density, whereas substantially larger values can indicate a locally sparse observation.
High dimension weakens distance and density notions, so representation quality matters.
11.5. Clustering-based Detection
Candidates may include points far from cluster centers, members of very small/sparse clusters, or observations labeled as noise by DBSCAN. The approach fails when normal data do not form meaningful clusters.
11.6. Classification-based Detection
With labeled normal/anomalous examples, ordinary binary classifiers can be used. When anomaly labels are scarce, one-class methods such as one-class SVM learn a boundary around normal observations.
Applications include intrusion detection, fraud, sensor faults, medical monitoring, image/audio analysis, and textual anomalies. The operational definition of anomaly must be specified for each domain.
11.7. Calibration of Outlier Scores and Event Metrics
Isolation Forest, LOF and one-class models do not output scores on a shared probabilistic scale. The threshold must be selected on separate validation data with event prevalence, false-alert cost and review capacity in mind. For overlapping windows, pointwise F1 and event-onset delay should be reported separately; shared event fragments across training and test data can cause leakage. The detection-theory background is developed in Anomaly Detection.
Unit 12: n-grams and Statistical Language Models
12.1. Local Sequence Context
An n-gram is a contiguous sequence of n units. The unit may be a word, character, syllable, token, or domain-specific symbol.
1-gram = unigram
2-gram = bigram
3-gram = trigram
n-gram = contiguous sequence of length n
The word “gram” does not mean a weight in this terminology.
12.2. Chain Rule and Markov Approximation
A full sequence probability is:
P(w1,...,wT) = Π_t P(w_t | w1,...,w_{t-1})Estimating full history is data intensive. An n-gram language model approximates history with the preceding n-1 units:
P(w_t | history) ≈ P(w_t | w_{t-n+1},...,w_{t-1})For a bigram:
P(w_t | w_{t-1})12.3. Count-based Estimation
The maximum-likelihood bigram estimate is:
P(w_i | w_{i-1}) = count(w_{i-1}, w_i) / count(w_{i-1})Unseen sequences receive zero probability under raw counts, motivating smoothing, backoff, and interpolation.
12.4. Word and Character n-grams
Word n-grams capture local lexical and syntactic patterns. Character n-grams can be robust to spelling variation and morphology. In agglutinative languages such as Turkish, character/subword representations can reduce some sparsity created by many surface word forms.
12.5. Naive Bayes and Text Classification
n-gram counts can be features for Multinomial Naive Bayes. Unigrams ignore local order; bigrams can capture part of expressions such as “not good.” Larger n increases context but also expands the feature space and data sparsity.
12.6. Speech Recognition
In classical automatic speech recognition, the acoustic model scores how well candidate sequences match the signal while an n-gram language model scores linguistic plausibility. The architecture is discussed in Automatic Speech Recognition.
12.7. Difference from Modern Language Models
An n-gram model is a fixed-window count-based statistical model. Transformer language models use distributed vector representations and attention. Both can assign probabilities to sequences, but their representation and generalization mechanisms differ fundamentally.
Unit 13: Probabilistic Graphical Models and Hidden Markov Models
13.1. Bayesian Networks
A Bayesian network represents conditional dependencies among random variables with a directed acyclic graph. Each node carries a distribution conditional on its parents, giving the factorization:
P(X1,...,Xn) = Π_i P(X_i | Parents(X_i))The graph exposes conditional structure, but an observational Bayesian network is not automatically a causal graph.
Naive Bayes can be viewed as a highly constrained special case: the class is a common parent of the features, which are assumed conditionally independent given that class.
13.2. Markov Chains
The Markov assumption states that, under the selected state representation, the next state depends on the current state rather than the full past:
P(S_t | S_1,...,S_{t-1}) = P(S_t | S_{t-1})This connects the stochastic-process treatment in Probability and Statistics to sequential learning.
13.3. Hidden Markov Models
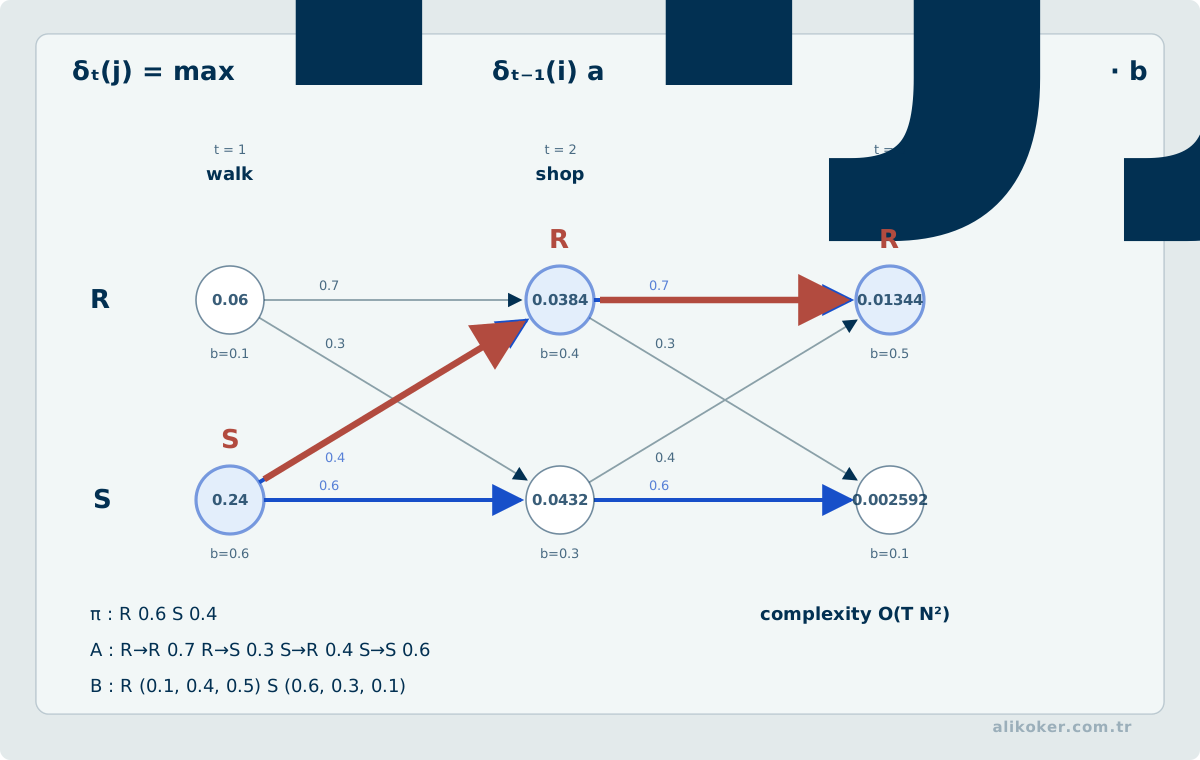
A Hidden Markov Model (HMM) combines an unobserved state sequence with observations emitted by those states:
hidden state S_t
   ↓ emission
 observation O_t
Its basic components are:
- initial-state probabilities,
- transition probabilities,
- observation/emission distributions.
Classical inference problems include:
- evaluation: probability of an observation sequence,
- decoding: most probable hidden-state sequence,
- learning: estimation of model parameters from data.
Forward–backward, Viterbi, and Baum–Welch/EM methods are classical solutions.
13.4. Speech and Sequential Data
In classical speech recognition, HMM states represent temporal structure, the acoustic model scores observations, and an n-gram model supplies linguistic sequence probability. The full architecture is described in Automatic Speech Recognition.
Bayesian networks and HMMs show why statistical learning is broader than drawing decision boundaries: many tasks are fundamentally about conditional dependence and latent state structure.
13.5. Markov Random Fields and Belief Propagation
Bayesian networks express dependencies with a directed acyclic graph, whereas a Markov Random Field (MRF) uses an undirected graph and factorizes the joint distribution over local interactions. An undirected edge does not mean that one variable causes another; it indicates direct participation in a common probabilistic interaction.
For positive distributions, the Hammersley-Clifford theorem connects the graph Markov properties to a Gibbs factorization over clique potentials. The representation can be written as:
P(x) = (1 / Z) * product_C psi_C(x_C)Each psi_C is a non-negative potential, not necessarily a normalized probability. The partition function Z normalizes the product over all configurations. Treating an arbitrary local potential as if it were already a probability is therefore incorrect.
In a pairwise MRF, factors can be restricted to vertices and edges. Graph separation helps expose conditional independencies. Unlike the directed temporal structure of an HMM, an MRF is often a more natural representation when interactions are symmetric and local rather than causal or sequential.
Belief propagation computes local messages in order to obtain marginals. On a tree, a sum-product message can be read conceptually as:
m(i -> j, x_j) =
    sum over x_i [
        local_potential(i)
        * edge_potential(i,j)
        * product of messages from neighbors of i except j
    ]
With the proper schedule, inference on trees is exact. Reusing the update iteratively on graphs with cycles gives loopy belief propagation, where convergence and exactness are no longer guaranteed in general. This distinction separates an exact graphical-model algorithm from an approximation that merely reuses the same local message form.
Unit 14: Model Evaluation
14.1. Training, Validation, and Test
- training: estimate model parameters,
- validation: choose models and hyperparameters,
- test: estimate final generalization after choices are complete.
Repeatedly tuning against the test set turns it into a validation set.
14.2. Confusion Matrix
                 Actual +    Actual -
Predicted +         TP           FP
Predicted -         FN           TN
14.3. Accuracy
Accuracy = (TP + TN) / (TP + TN + FP + FN)Accuracy can be misleading under strong class imbalance. A classifier that predicts only the majority class may appear highly accurate while missing every rare event.
14.4. Precision, Recall, Specificity, and F1
Precision = TP / (TP + FP)
Recall    = TP / (TP + FN)
Specificity = TN / (TN + FP)
F1 = 2 * Precision * Recall / (Precision + Recall)
Precision matters when false positives are costly; recall matters when false negatives are costly. Metric choice should follow operational cost.
Positive predictive value can change when class prevalence changes, even if sensitivity and specificity stay fixed. Consider a screening classifier with 90% sensitivity and 90% specificity in a population with 1% prevalence. Out of 10,000 independent cases, roughly 100 are positive and 9,900 negative, yielding about 90 true positives and 990 false positives. Precision is then 90/(90+990) ≈ 8.3%. High sensitivity and specificity alone therefore do not establish operational usefulness. Confusion matrices should be interpreted against sampling fractions, false-alarm costs, threshold choice and the prevalence expected in deployment.
14.5. ROC and PR Curves
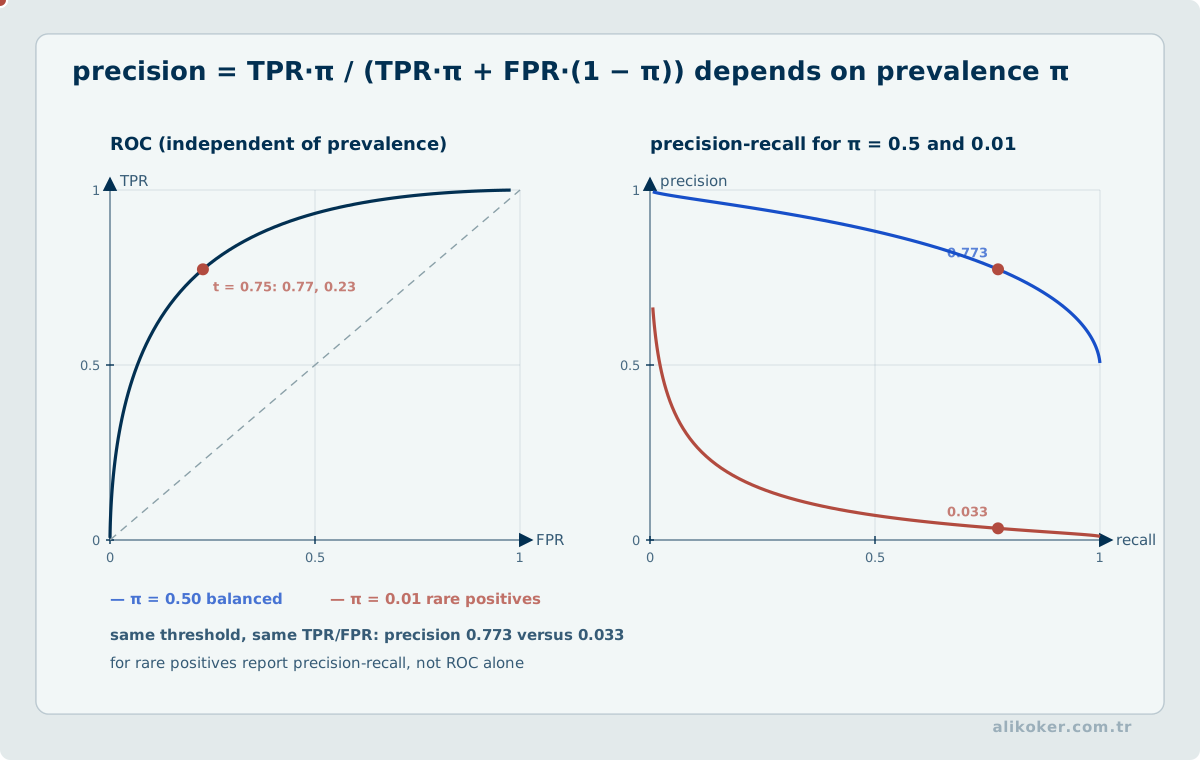
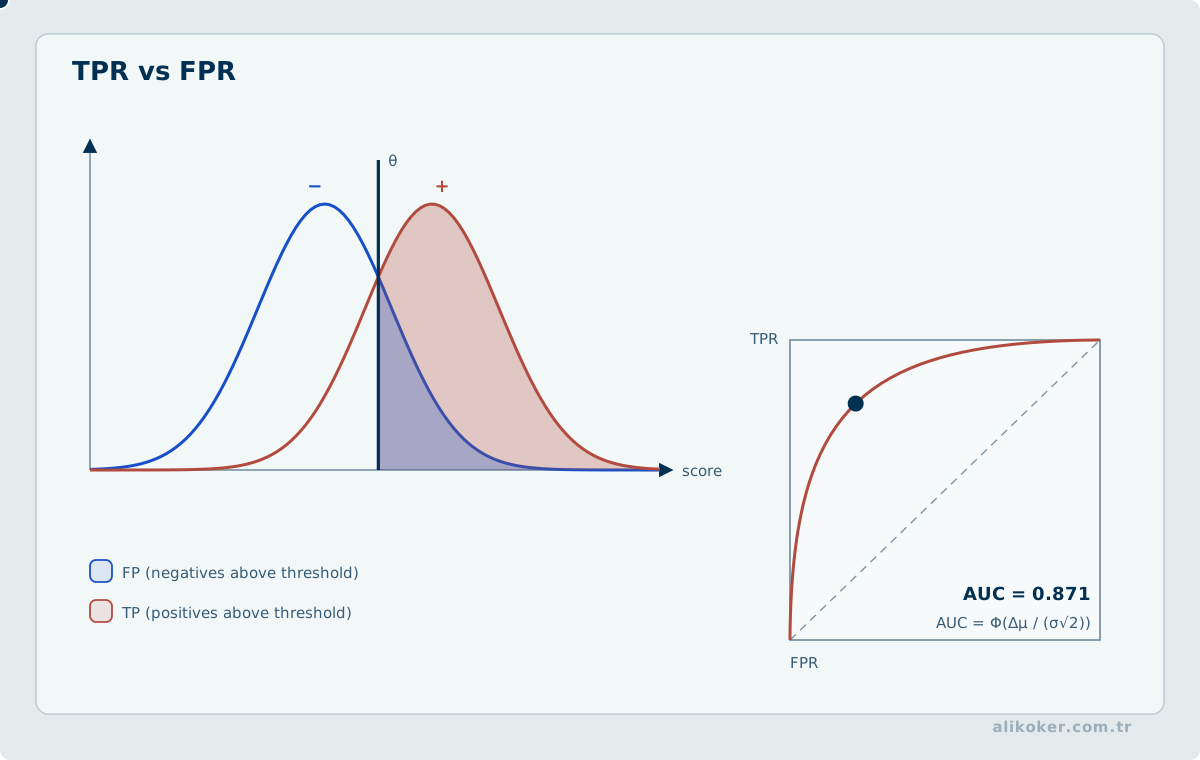
Changing the threshold traces the TPR/FPR trade-off in ROC space. Precision–recall curves can be more informative when positives are rare. AUC does not reveal the cost at one particular deployment threshold.
14.6. Calibration
A model is well calibrated around a score of 0.8 if roughly 80% of examples receiving that score are positive. Ranking discrimination and probability calibration are separate properties.
14.7. Regression Metrics
MAE  = mean(|y-ŷ|)
MSE  = mean((y-ŷ)^2)
RMSE = sqrt(MSE)
R²   = 1 - SSE/SST
Squared-error metrics emphasize large errors more strongly than MAE. A high R² can still coexist with operationally unacceptable error magnitude.
14.8. Clustering Metrics
Inertia summarizes within-cluster dispersion. Silhouette combines cohesion and separation. When external labels exist, measures such as adjusted Rand index can compare structures, but a cluster is not necessarily a ground-truth class.
14.9. Sensitivity, Specificity, and the Decision Threshold Are Different Objects
Sensitivity/recall and specificity are computed from the confusion matrix, but their values depend on the decision threshold used to convert a score into a class. For a model in which larger scores indicate the positive class, raising the threshold typically produces:
higher threshold -> fewer positive decisions -> sensitivity tends to fall
                                            -> specificity tends to rise
This is an operating policy, not merely a model-ranking metric. The same scoring model can be deployed with different thresholds for different applications.
Class prevalence also changes precision/positive predictive value directly. If the positive prevalence is pi, then:
PPV = sensitivity * pi /
      (sensitivity * pi + (1 - specificity) * (1 - pi))
Precision can therefore collapse as pi becomes small even when sensitivity and specificity stay unchanged. A precision value measured on a balanced evaluation set cannot be transferred blindly to production when real prevalence is very different.
There is no universal best threshold. False-positive and false-negative costs, analyst capacity, alert budgets, safety/security consequences, and downstream automation all matter. ROC-AUC can summarize ranking behavior across thresholds, but it does not by itself select the deployment threshold.
14.10. Selective Classification and the Risk–Coverage Curve
A classifier is not required to answer every input. In applications where errors have high consequences, uncertain inputs may be deferred for clarification or human review. Coverage denotes the share of inputs assigned an automatic decision; selective risk is the error rate among those accepted inputs. As the acceptance threshold rises, the evaluator observes whether selective risk falls as coverage decreases. One overall accuracy figure conceals both rejected cases and the classes from which they came.
In multiclass systems based on lexical similarity, the largest score must not be mistaken for a calibrated probability of correctness. The margin between candidates, whether the expression belongs to the supported domain, and whether required arguments are explicitly available may all contribute. However, combining several similarity scores derived from the same word n-grams as independent evidence can create unjustified certainty. Thresholds should be calibrated by class and risk slice using independently held-out examples.
Consider a dataset that must distinguish “open the record” from “do not open the record.” Overall F1 is insufficient: treating a negative command as an affirmative action requires its own error metric. Filling the evaluation set with near-duplicates derived from training templates is equally misleading; training and testing must be separated by utterance families and task types.
14.11. Machine Identity and Time Dependence in predictive-maintenance Data
A fault classifier may learn from consecutive 1 s vibration windows. Randomly allocating adjacent windows from the same bearing to training and test sets, however, lets the model recognize machine-specific signatures rather than general fault behavior. Suppose observations come from six machines: four can be reserved for training, one for model selection, and one never-seen machine for final testing. Such separation does not prove generalization by itself; uncertainty must still be reported when there are few independent machines.
Assume the test period contains 10 genuinely faulty windows and the system issues 20 alarms, 8 of which are correct. Window-level precision is 8/20 = 40% and recall is 8/10 = 80%. Yet one continuing failure generating a hundred repeated alarms is not a hundred independent maintenance events. Event-level lead time, false alarms per machine, and planned versus unplanned downtime costs need separate evaluation. Remaining-useful-life estimation has a different target from healthy/fault classification and may require handling censored operating histories.
14.12. Thresholds, Calibration, and Uncertainty under Class Imbalance
Suppose a detection benchmark contains 1,000 events with 20 real positives. A model finding 18 positives and producing 82 false alerts has recall 18/20=0.90 but precision 18/100=0.18. High sensitivity therefore does not remove operational workload. Precision–recall curves respond more strongly to prevalence than ROC-AUC; probability calibration and cost-sensitive threshold choice must be assessed separately.
Comparisons on the same held-out examples must account for sampling uncertainty. Repeated use of test labels to choose hyperparameters or thresholds produces optimistic final estimates. Multiple seeds, temporal test slices, and uncertainty intervals make single-score comparisons less misleading.
14.13. Paired Model Comparison and Uncertainty
When two classifiers are evaluated on the same test examples, their outcomes are not independent samples. It matters which examples both models get right or wrong. A paired comparison can define a per-example difference \(d_i=s_A(i)-s_B(i)\); the mean \(\bar d=n^{-1}\sum_i d_i\) measures the observed performance gap on that dataset. Uncertainty must nevertheless reflect the dependence structure of the observations.
In a paired bootstrap, the same sampled indices are used to evaluate both models in every resample, producing an empirical distribution of their difference. If observations are repeated for the same person or device, or are temporally correlated, resampling individual rows as if independent can understate uncertainty. Resampling by group or time block is more appropriate. Reporting intervals on a test set already used to select the model does not undo selection bias.
A small metric gain is not necessarily an engineering improvement. Latency, memory, subgroup errors, false-positive costs, and acceptable operational risk must be assessed together. Testing many candidate models, thresholds, and feature subsets while reporting only the winner induces optimistic selection. The comparison protocol should be fixed before observing the final test outcomes.
When two models are evaluated on the same test observations, per-observation loss differences are often a better starting point than pretending the estimates are independent. What a resampling experiment measures depends on whether preprocessing, selection, and model training are repeated within each resample. In grouped or time-dependent data, naive independent bootstrap can produce misleadingly narrow intervals.
For small performance differences, interval width, effect size, and deployment cost should be considered jointly. Repeated selection among many models and metrics creates additional optimism in the reported winner.
Unit 15: Model Selection, Regularization, and Leakage
15.1. Cross-validation
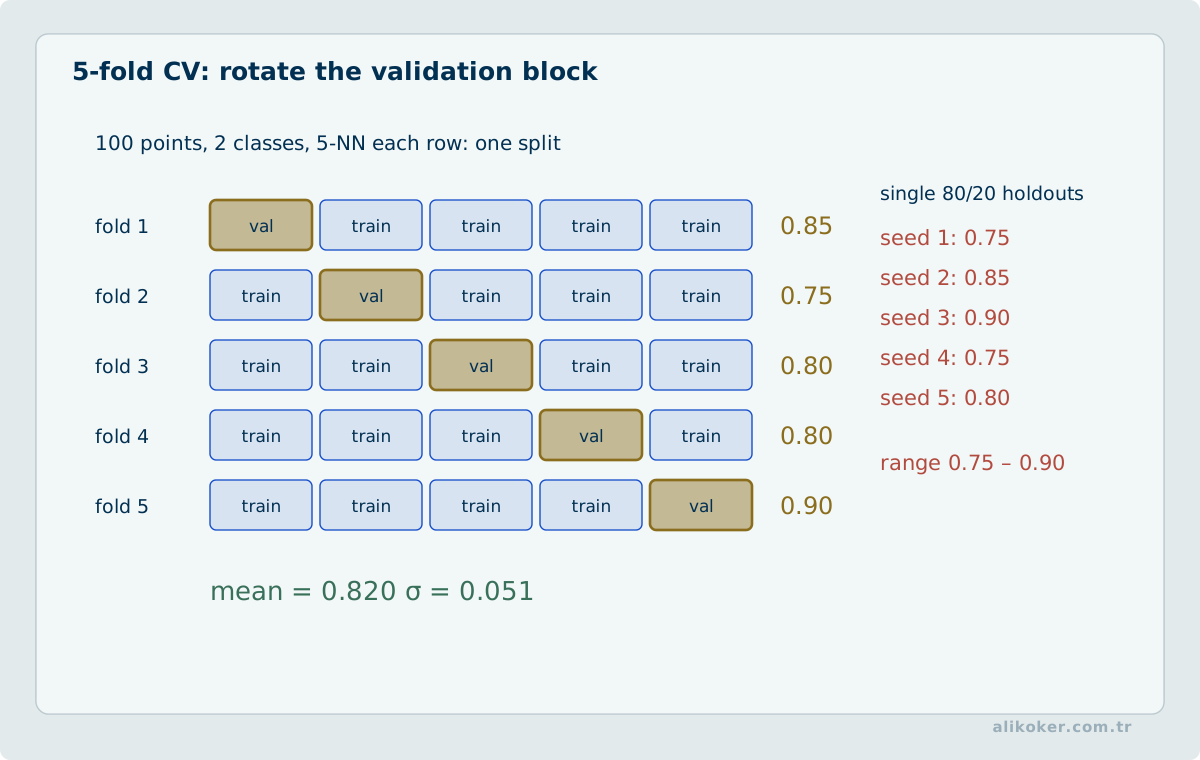
k-fold cross-validation partitions data into k folds and rotates the validation fold. Stratified folds preserve class proportions for classification. Time-dependent data require temporal splits so future observations do not leak into the past.
Time-series validation must prevent later observations from informing earlier predictions. Random splitting can place highly correlated measurements from the same machine in both training and test sets, inflating apparent predictive performance. A forward-chaining evaluation trains only on past periods and scores on subsequent periods. Normalization constants, imputation statistics, and target-dependent feature transforms must also be fitted within each training window. A chronological split does not eliminate leakage if preprocessing was performed on the full dataset first.
15.2. Hyperparameter Selection
Neighbor count k, SVM C/γ, tree depth, K-Means K, and regularization strengths are hyperparameters rather than fitted model parameters. Grid search, random search, or adaptive search can be used, but the test set must remain outside the search loop.
Nested cross-validation can separate hyperparameter selection from performance estimation when unbiased comparison is important.
15.3. Search Budgets and Sequential Hyperparameter Selection
Grid search enumerates the Cartesian product of predefined parameter values: m candidates along each of d axes produce m^d combinations. Random search may distribute a limited budget more effectively when only a few dimensions strongly influence performance. Sequential model-based search fits a response model to completed trials and selects the next configuration using an acquisition objective such as expected improvement or uncertainty.
When training cost differs between trials, the objective is not just the best validation score; improvement must be assessed against compute time. Early stopping can bias comparisons when configurations receive unequal budgets. The search procedure, parameter ranges, trial budget, and failed runs should be recorded; the final test set must remain outside the acquisition process.
15.4. Data Leakage
Leakage includes more than accidentally copying the target into the features. Examples include:
- fitting scalers on the entire data set,
- selecting features using test outcomes,
- placing records from the same subject into training and test,
- using future information for a past prediction,
- splitting near-duplicate augmented examples across folds.
Evaluation should reproduce the information boundary that will exist at prediction time.
A random row split can leave strong dependencies between seemingly distinct observations. Segments from the same speaker, measurements from one device, or passages derived from the same source document may appear in both training and test sets, producing an optimistic estimate of generalization. The split unit should be the dependency group that would be unavailable at prediction time, rather than an arbitrary row. Preprocessing, feature selection, and normalization parameters must likewise be learned on training data only; the held-out distribution must not influence those steps.
Random row-level train/test splits can overstate generalization when correlated observations from the same person, device or production batch appear on both sides. For instance, 1,000 consecutive sensor readings from one device should not be split as if they were 1,000 independent future devices. Group-aware splitting, or chronological evaluation for forecasting, is more appropriate. Repeatedly selecting thresholds, features or hyperparameters on the held-out test set turns that set into part of model development. The evaluation unit must reflect what genuinely new person, device, period or site the model will encounter in deployment.
15.5. Class Imbalance
Class weighting, controlled resampling, threshold selection, PR metrics, and cost-sensitive learning can address rare classes. Synthetic methods such as SMOTE belong inside the training fold only.
15.6. Learning Curves
Training and validation error as a function of data size can help distinguish underfitting, high variance, and potential benefit from more data. More data cannot fix a wrong target definition, systematic label error, or deployment distribution mismatch by itself.
15.7. Stability of Feature Selection in High Dimensions
When the number of predictors p approaches or exceeds the sample count, small changes in the observations may yield different selected subsets with nearly identical predictive accuracy. The ℓ₁ penalty in lasso encourages sparsity, but the choice among correlated predictors may be sensitive to the data split. Ridge shrinks coefficients without generally setting them exactly to zero. Variable selection should therefore be evaluated not only by prediction error but also by how reproducibly a variable is selected under resampling.
If an interaction x_j x_k is included, the hierarchy rule governing its main effects x_j and x_k must be explicit. The number of pairwise interactions grows on the order of p(p−1)/2; blindly constructing all pairs inflates memory use and multiple-comparison burden. When screening is required, screening, scaling and penalty tuning must all be repeated inside each training fold of cross-validation. Information from the held-out fold must not influence feature selection.
15.8. Temporal Splits, Leakage, and model-selection Bias
Independent and identically distributed observations are often an inadequate assumption for temporal data. Random train–test splits can place adjacent measurements of the same event, or repeated records from the same entity, in both partitions. This leaks information unavailable at prediction time. For time-dependent prediction, training must not include future observations, and each feature must be computable from information actually available at the decision timestamp. A day's eventual total event count, for example, is not a valid feature for a forecast made at the start of that day.
Hyperparameter tuning and final evaluation serve different purposes. Repeated inspection of validation performance can indirectly overfit model selection to that validation set. Reserve the final test set until model structure, hyperparameters, and thresholds are frozen. Forward-moving rolling-origin evaluations can better represent deployment than a single random split, although uncertainty may increase in small temporal windows.
Accuracy alone is inadequate for imbalanced binary classification. Precision, recall, and false-alarm rate must be examined across decision thresholds. Choosing a threshold after inspecting the final test set biases the reported result upward. A model score should not be described as an event probability unless suitable calibration has been established independently. Report performance by relevant data slices and periods to expose distribution shift.
AIC penalizes maximized log likelihood for model complexity and, under particular assumptions, approximates expected predictive discrepancy: AIC = 2k − 2log L̂. BIC = k ln(n) − 2log L̂ rests on different asymptotic assumptions and selection objectives; k is the free-parameter count and n the sample size. These criteria require comparable likelihood definitions on the same observations and are not interchangeable with cross-validation error.
Selecting features and then reporting conventional intervals as though the model had been fixed in advance can cause post-selection inference bias. Model averaging can include uncertainty across plausible models rather than condition on one selected model, but remains sensitive to the candidate set and weighting rule. If variable or hyperparameter selection is performed outside resampling folds, evaluation may be optimistically biased.
Unit 16: Statistical Learning in Production
16.1. Training and Inference Must Share One Pipeline
The production system includes preprocessing, feature extraction, category dictionaries, missing-value policy, and decision thresholds, not just a serialized model.
raw data
→ validation
→ preprocessing
→ features
→ model
→ score
→ threshold / decision
→ monitoring
If production preprocessing differs from training, model behavior changes even when the model file is identical.
16.2. Distribution Shift
Data drift changes the input distribution. Concept drift changes the relationship between inputs and targets. Performance can decay because the world changed even when the code did not.
Monitoring may include feature distributions, class proportions, calibration, error types, latency, and missing-value rates.
16.3. Reproducibility
At minimum record:
- data version,
- split strategy,
- random seed,
- preprocessing configuration,
- model/library version,
- hyperparameters,
- evaluation metrics.
The same source code can produce different results under different data or splits.
16.4. Experiment Lineage and Reproducible Model Packages
Deployed prediction behavior is the combination of model weights + feature definitions + transformation parameters + decision threshold. An experiment record should bind together the training dataset's content identity, row/group split manifest, feature schema, label definition, randomness settings, and evaluation protocol. A filename or code revision alone cannot guarantee the same outcome when raw data changes.
Means, variances, category mappings, and missing-value policies learned during preprocessing must not be recomputed independently at inference. Retraining produces a separately validated version; historical production decisions should remain traceable to the version and input snapshot used at the time. Conditions under which numerical kernels and parallel execution prevent bitwise determinism must be documented.
16.5. Interpretability
Linear coefficients, tree paths, and nearest examples can support direct forms of explanation, but interpretability is not causality. A threshold or coefficient estimated from observational data does not by itself prove the effect of an intervention.
16.6. Online Learning, Incremental Updates, and Temporal Validation
Data do not have to arrive as one static batch. Incremental learning updates model state with new examples or mini-batches; online learning more tightly interleaves prediction, feedback, and updating with the data stream.
Random cross-validation can leak future information in temporal data. Rolling-origin or forward-chaining evaluation keeps each test period after its training window. Under drift, metrics should be examined across time slices rather than only through one global average.
Reliable updating therefore requires traceability across the data version, training interval, feature contract, model version, and evaluation window.
16.7. Parameter Uncertainty versus Predictive Uncertainty
A point prediction does not imply absence of uncertainty. A useful distinction is between aleatoric uncertainty, arising from irreducible observation variability, and epistemic uncertainty, arising from limited model or parameter knowledge.
In classical regression, a confidence interval concerns uncertainty around the mean relation, while a prediction interval additionally includes variability of a future observation. In a Bayesian model, the posterior predictive distribution can integrate parameter uncertainty directly.
In production systems, uncertainty and decision thresholds should be designed separately. An uncalibrated high confidence score must not automatically be interpreted as a true probability of correctness.
Unit 17: Position Among AI Method Families
Statistical learning is one part of artificial intelligence rather than a synonym for the entire field:
Artificial intelligence
├─ symbolic search, logic, and planning
├─ statistical learning
│  ├─ regression / Bayesian models
│  ├─ k-NN / SVM / decision trees
│  ├─ clustering / dimensionality reduction
│  └─ n-grams / classical pattern recognition
├─ neural networks and deep learning
├─ fuzzy logic
├─ evolutionary computation and genetic algorithms
└─ reinforcement learning
Artificial Neural Networks and Learning Models covers connectionist representations, architectures, and learning procedures.
Fuzzy Logic models graded membership rather than probability; Fuzzy C-Means is a useful intersection in which a clustering task uses graded membership.
Genetic Algorithms and Their Applications search through populations, selection, and variation rather than estimating a statistical model directly. Genetic search can still tune an SVM, select features, or optimize other learning systems; method families can be composed.
The broader historical and philosophical context is developed in Artificial Intelligence: Philosophy, Theory and Practice. The key engineering question is not which method is “more intelligent,” but which assumptions, data structure, error costs, and computational budget make a learning mechanism appropriate.
17.1. Selecting a Method Family for the Same Problem
A task does not require the most complex model simply because it is called an AI problem. Data volume, feature structure, error cost, latency, and explainability should drive model choice. On small or tabular datasets, a regularized linear model or tree ensemble may be more reliable than a much larger neural network.
problem → data → baseline → measurement → added complexity if justified17.2. Representation Learning versus Classical Feature Engineering
Classical statistical learning often relies on explicit domain-designed features. Deep learning can learn more of the representation, but data acquisition, normalization, sampling, and label semantics remain engineered choices.
Statistical learning is therefore not merely a historical stage before modern AI. Calibration, uncertainty, tabular modeling, interpretable baselines, and controlled experimental design remain central uses.
17.3. Probability Calibration and out-of-distribution Data
Correct ranking and reliable probabilities are different properties. Softmax or sigmoid outputs should not automatically be interpreted as calibrated probabilities; reliability diagrams and Brier score can help assess calibration.
Models can also be overconfident on out-of-distribution inputs. OOD detection usually combines data-quality rules, representation distance, model uncertainty, or domain-specific constraints.
In production, abstaining can be a valid prediction. High-uncertainty cases can be routed for human review or additional data rather than forced into an automated decision.
17.4. Designing a Fair Model Comparison
SVM, KNN, tree-based, and clustering methods should be compared under the same preprocessing and data-split rules. If scaling or feature selection is fitted on the full dataset, test information can leak into training.
Hyperparameter selection belongs inside validation or nested cross-validation. Keeping the test set for final evaluation reduces optimistic comparison.
Average score alone is incomplete. Class imbalance, calibration, error slices, learning curves, and sensitivity to dataset size help explain which method is appropriate under which conditions.
Unit 18: Embedding Similarity Is Not a Probability
Cosine similarity is widely used in modern retrieval systems, but its statistical meaning must be interpreted correctly.
A cosine score of 0.92 does not mean 92% probability of correctness, semantic identity, or entity identity. Score distributions depend on the embedding model, corpus, and task.
For nonzero vectors, cosine similarity is
cos(x, y) = (x · y) / (‖x‖₂ ‖y‖₂)
The result measures directional proximity, not the conditional probability that two objects match. Its practical interpretation depends on the score distributions for relevant and irrelevant pairs. Suppose most relevant pairs score between 0.70–0.90, while many irrelevant pairs fall between 0.65–0.80. A threshold of 0.75 then leaves a substantial overlap: the number of incorrect matches depends on both the distributions and the prevalence of true matches.
Turning a similarity score into an estimated probability requires a separate calibration procedure and representative labeled data. Even after calibration, the estimate applies to a specified label and population. Same person, same topic, and relevant document are different target variables. A document-retrieval similarity score cannot establish personal identity.
If a threshold is needed, it should be selected on development data using precision-recall trade-offs rather than an intuitive universal constant.
Choose the threshold on a development set and evaluate it on a held-out test set that did not influence the choice. When positive pairs are rare, precision–recall curves deserve particular attention: even a modest false-positive rate can produce many incorrect matches in a large candidate population. Record the embedding version, normalization rules, threshold, and test distribution; otherwise identical numeric scores from different runs need not be comparable.
This distinction is foundational for semantic retrieval in Retrieval-Augmented Generation and Natural Language Processing.
Unit 19: Improvement Requires a Baseline
A complex model receiving a high score does not prove that the complexity was necessary.
Start with strong simple baselines:
majority baseline
linear model
BM25 / lexical
simple tree
   |
   v
complex candidate
A valid comparison also requires the same query population, relevance labels, and evaluation protocol. If one candidate is tested on easier cases, observed improvements may reflect dataset selection rather than modeling. Leakage arises when related records from the same user, entity, document, or time period appear across supposedly independent train and test partitions.
Compare not only final quality but also failure slices, latency, memory, maintenance cost, and distribution shift.
For paired evaluation, compute the per-query difference Δᵢ = mᵢ(B) − mᵢ(A), where m_i is an appropriate query-level metric. A paired bootstrap can estimate uncertainty while resampling the independent unit—typically the query, not every retrieved document. Report the distribution of gains and regressions, not just the mean difference.
Operational comparisons should include tail latency, particularly p95 and p99, temporary memory allocation, and worst-case behavior. A statistically measurable quality gain does not make a candidate preferable if it violates deployment resource or latency constraints.
Small metric differences can be sampling noise. Confidence intervals, bootstrap methods, or task-appropriate paired tests help quantify uncertainty.
Unit 20: Evaluation for Ranking Problems
Classification metrics do not fully describe ranked retrieval.
Useful metrics include Recall@K, Precision@K, Mean Reciprocal Rank, and nDCG.
These metrics do not replace user evaluation, but they let the retrieval layer be measured independently from a downstream generator.
For the top K results, precision and recall have different denominators:
P@K = |R ∩ Tₖ| / K; Recall@K = |R ∩ Tₖ| / |R|,
where R is the complete set of relevant documents and T_K denotes the first K returned results. If two of four relevant documents appear among the top five, then P@5=2/5 and R@5=2/4. When the first relevant document appears at rank three, that query contributes 1/3 to Mean Reciprocal Rank.
Graded judgments call for an ordering-sensitive measure. A common definition is DCG@K=Σ_{i=1}^{K}(2^{rel_i}-1)/log_2(i+1); nDCG@K divides this by the ideal DCG for the query. A policy is needed for queries whose ideal gain is zero. Average metrics per query rather than implicitly pooling all returned documents: these aggregation choices answer different questions. Duplicate results, tied scores, incomplete relevance judgments, and inaccessible documents also require explicit, deterministic evaluation rules.
Unit 21: Benchmarks, Slices, and Distribution
Aggregate benchmark scores can hide production failures.
A slice may be defined by language variant, query length, label prevalence, source identity, document type, or collection period. Report the sample count, metric, and uncertainty for each slice. A large percentage increase on ten cases is usually far less stable than an increase supported by thousands of representative cases.
A Turkish semantic-retrieval benchmark can include separate slices for standard Turkish, ASCII Turkish, proper names, technical terminology, long suffix chains, and cross-language retrieval.
MTEB similarly demonstrates that no embedding method dominates all task families. Model selection is therefore a generalization problem over the target distribution, not merely a leaderboard choice.
Evaluation splits should prevent repeated or near-duplicate records from the same person, document, or adjacent time window from leaking into both training and test data. When names and terminology change over time, track their error profiles separately rather than relying on a single aggregate score. Qualitative examination of failures is especially valuable in low-volume slices where numerical estimates are unstable.
Unit 22: Robust Temporal Signal Detection and Alert Consolidation
Finding an unusual time-series observation is not equivalent to measuring distance from the mean. In sparse, bursty, or heavy-tailed data, conventional mean and standard deviation can be strongly influenced by a few extremes.
A robust baseline can use the median for location and median absolute deviation for scale:
center = median(x)

MAD = median(|x_i - center|)

robustScale ≈ MAD / 0.6745
If MAD is zero, an implementation should not blindly divide. A controlled fallback such as sample standard deviation may be reasonable when real variation exists; if the series is effectively constant, the method should report that the statistic is not informative.
22.1. EWMA
An exponentially weighted moving average gives more influence to recent observations:
S_t = λ X_t + (1-λ) S_(t-1)Larger λ reacts faster to new data.
EWMA is not, by itself, an anomaly classifier. It is a statistical process-monitoring view.
22.2. CUSUM
CUSUM accumulates deviations so that a sequence of small changes in the same direction can become visible.
positive accumulation =
    max(0, previous + deviation - allowance)

negative accumulation =
    min(0, previous + deviation + allowance)
Crossing a threshold creates a persistent-shift candidate.
22.3. Consolidate Methods into One Temporal Event
The same period may be highlighted by robust deviation, EWMA, and CUSUM.
Showing three separate incidents can create alert multiplication.
A better representation is:
temporalCandidate(date)
├─ ROBUST_DEVIATION
├─ EWMA_SHIFT
└─ CUSUM_SHIFT
The number of agreeing methods is not a probability of correctness. It indicates that several statistical views of the same observations highlight the same region.
22.4. Missing Intervals Are Not Zero Observations
true zero:
  the interval was observed and event count was zero

missing interval:
  reliable observation is unavailable
Confusing the two can distort means, variance, CUSUM, and period comparisons.
22.5. Period Splits and Relationship Change
For two neighbor sets:
A = relationships in period 1
B = relationships in period 2
Jaccard similarity can summarize persistence:
J = |A ∩ B| / |A ∪ B|The analysis can separately count continuing, newly observed, and no-longer-observed relationships.
Newly observed means absent from the first selected window and present in the second; it does not establish historical first occurrence.
22.6. Semantic Boundary of Anomaly Candidates
A statistical anomaly means unusual relative to a baseline. It does not by itself mean suspicious, erroneous, malicious, or causally important.
22.7. Deterministic Tie Breaking
Random ordering among tied scores weakens reproducibility.
A stable order can use:
primary score
secondary score
evidence count
stable identifier
Robust temporal analytics is a combined problem of baseline design, coverage, method diversity, alert consolidation, and disciplined interpretation.
22.8. Robust Evaluation in Machine Learning
Robust statistics asks how much an estimator degrades under small departures from an idealized model. In statistical learning, the median and MAD are basic robust summaries for heavy-tailed errors and outliers; the influence function describes local sensitivity to contamination, while the breakdown point characterizes how much contamination an estimator can withstand before losing stability. In heavy-tailed or contaminated data, decisions based only on the mean and standard deviation can be misleading.
- Report cross-validation as a distribution or interval rather than a mean alone.
- Examine how outliers alter coefficients or decision boundaries.
- Measure class imbalance and calibration errors even when headline accuracy is high.
Unit 23: Framing Text Classification and Clustering as Statistical-Learning Problems
Text can be processed by generic classification and clustering algorithms, but its geometry differs from ordinary tabular data. Document representations are commonly high-dimensional and sparse. The same meaning may have multiple surface forms, while one term may carry multiple meanings. Representation and evaluation therefore matter before the choice of algorithm.
23.1. Two Families of text-classification Approaches
Text categories can be defined through two broad method families:
- knowledge engineering: domain rules, dictionaries, and concept relationships,
- statistical learning: decision boundaries or class scores learned from labeled examples.
They are not necessarily mutually exclusive. High-precision rules and learned models may cover different error modes within the same pipeline.
SVMs, k-NN, logistic models, and neural networks still obey the general principles of classification. What is text-specific is the scale and sparsity of the feature space, class imbalance, labeling ambiguity, and the prevalence of multilabel examples.
23.2. The Role of Unlabeled Data
Document collections often contain much more unlabeled than labeled material. This motivates semi-supervised and self-supervised approaches. Unlabeled data, however, do not provide correct labels automatically; pseudo-label or bootstrapping errors can amplify over iterations.
A controlled loop is preferable:
seed / gold labels
      ↓
candidate expansion
      ↓
confidence filter
      ↓
manual or held-out validation
      ↓
next iteration
23.3. The Cluster Hypothesis in Text
A classical information-retrieval assumption is that relevant documents tend to be more similar to one another than to irrelevant documents. This cluster hypothesis is not a universal law; it depends on the representation and similarity function.
Clustering can serve at least two distinct goals:
- organize search results into topical groups for navigation,
- discover dominant structure in a collection without predefined labels.
23.4. Scatter/Gather as Interactive Clustering
Scatter/Gather turns clustering into an exploratory operator:
collection
   ↓ scatter
candidate clusters
   ↓ select
subcollection
   ↓ gather / recluster
The user progressively narrows the corpus rather than consuming one monolithic result set. Clustering thus becomes part of a human-guided discovery process.
23.5. Cluster Type and Similarity
Text clustering may be:
- flat or hierarchical,
- hard or soft.
Cosine similarity is common in sparse vector spaces, but the geometry changes with the representation. Thresholds and neighborhoods that work for TF-IDF should not be assumed to transfer unchanged to dense embedding spaces.
23.6. Cluster Labeling Is a Separate Problem
A mathematically coherent cluster may still be unusable if its label is opaque. Candidate labels may come from:
- a medoid-document title,
- dominant centroid terms,
- a short discriminative term or phrase.
A good cluster label should distinguish the cluster from its neighbors rather than restate the entire cluster vocabulary.
23.7. Evaluating Text Clustering
With reference labels, an external measure such as purity can be defined as:
Purity(C_i) = max_j |C_i ∩ L_j| / |C_i|Entropy and mutual information provide other views of cluster-to-label agreement. Yet when the real purpose is to improve search navigation or downstream analysis, the most relevant evaluation is often task utility.
Therefore:
good objective ≠ good user outcomeAn algorithm can improve an internal clustering score while degrading precision/recall trade-offs or user task performance.
23.8. Experimental Design for Multilabel Intents and Candidate Reranking
A single utterance may express more than one classification target. “Compare last week and show the sources” contains comparison, period selection, and evidence display requirements. Multilabel learning can treat each label as an independent binary problem, but doing so discards dependencies between labels. Mutually incompatible actions and mandatory parameters must therefore be checked when predicted labels are converted into a typed execution plan.
To evaluate a learned reranker for short text, all compared methods should first receive the same candidate pool. If one method generates more candidates, candidate discovery and ranking quality become confounded. Lexical matching, edit distance, morphological compatibility, and dialogue context are represented using a stable feature schema. Linear and nonlinear models are compared on the same grouped holdout; negation, out-of-domain statements, and multi-turn corrections are reported as separate slices.
Success cannot be summarized by the predicted labels alone. Exact label-set accuracy, plan completeness, false clarification, and unauthorized-action rates must be considered together. A model that finds more labels but introduces an incorrect argument has not improved task completion. Successfully running a non-decisive learned model is likewise not evidence of a production benefit.
References
- Arthur P. Dempster; Nan M. Laird; Donald B. Rubin. “Maximum Likelihood from Incomplete Data via the EM Algorithm.” Journal of the Royal Statistical Society: Series B, 1977.
- Chandola, Varun; Banerjee, Arindam; Kumar, Vipin. “Anomaly Detection: A Survey.” ACM Computing Surveys, 41(3), 2009. https://doi.org/10.1145/1541880.1541882
- Christopher D. Manning; Prabhakar Raghavan; Hinrich Schütze. Introduction to Information Retrieval. Cambridge University Press, 2008.
- Christopher M. Bishop. Pattern Recognition and Machine Learning. Springer, 2006.
- Corinna Cortes; Vladimir Vapnik. “Support-Vector Networks.” Machine Learning, 1995.
- Daniel Jurafsky; James H. Martin. Speech and Language Processing. Prentice Hall, 2009.
- Ethem Alpaydın. Introduction to Machine Learning. MIT Press, 2010.
- Gareth James; Daniela Witten; Trevor Hastie; Robert Tibshirani. An Introduction to Statistical Learning. Springer, 2013.
- Göran Kauermann; Helmut Küchenhoff; Christian Heumann. Statistical Foundations, Reasoning and Inference: For Science and Data Science. Springer, 2021. https://doi.org/10.1007/978-3-030-69827-0
- J. MacQueen. “Some Methods for Classification and Analysis of Multivariate Observations.” Proceedings of the Fifth Berkeley Symposium on Mathematical Statistics and Probability, 1967.
- Kevin P. Murphy. Machine Learning: A Probabilistic Perspective. MIT Press, 2012.
- Leo Breiman. “Random Forests.” Machine Learning, 2001.
- Leonard Kaufman; Peter J. Rousseeuw. Finding Groups in Data: An Introduction to Cluster Analysis. Wiley, 1990.
- Markus M. Breunig; Hans-Peter Kriegel; Raymond T. Ng; Jörg Sander. “LOF: Identifying Density-Based Local Outliers.” SIGMOD, 2000.
- Martin Ester; Hans-Peter Kriegel; Jörg Sander; Xiaowei Xu. “A Density-Based Algorithm for Discovering Clusters in Large Spatial Databases with Noise.” KDD, 1996.
- Mor Harchol-Balter. Performance Modeling and Design of Computer Systems: Queueing Theory in Action. Cambridge University Press, 2013.
- Muennighoff, N.; Tazi, N.; Magne, L.; Reimers, N. “MTEB: Massive Text Embedding Benchmark.” 2022. https://arxiv.org/abs/2210.07316
- NIST/SEMATECH. CUSUM Control Charts. e-Handbook of Statistical Methods. https://www.itl.nist.gov/div898/handbook/pmc/section3/pmc323.htm
- NIST/SEMATECH. EWMA Control Charts. e-Handbook of Statistical Methods. https://www.itl.nist.gov/div898/handbook/pmc/section3/pmc324.htm
- Peter J. Huber; Elvezio M. Ronchetti. Robust Statistics. 2nd ed. Wiley, 2009.
- Peter J. Rousseeuw. “Silhouettes: A Graphical Aid to the Interpretation and Validation of Cluster Analysis.” Journal of Computational and Applied Mathematics, 1987.
- Reimers, N.; Gurevych, I. “Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks.” EMNLP-IJCNLP, 2019. https://arxiv.org/abs/1908.10084
- Ronen Feldman; James Sanger. The Text Mining Handbook: Advanced Approaches in Analyzing Unstructured Data. Cambridge University Press, 2007.
- Stuart Lloyd. “Least Squares Quantization in PCM.” IEEE Transactions on Information Theory, 1982.
- Thomas M. Cover; Peter E. Hart. “Nearest Neighbor Pattern Classification.” IEEE Transactions on Information Theory, 1967.
- Trevor Hastie, Robert Tibshirani, Jerome Friedman. The Elements of Statistical Learning, 2nd ed. Springer, 2009.
- Trevor Hastie; Robert Tibshirani; Jerome Friedman. The Elements of Statistical Learning. Springer, 2009.
- Walter W. Piegorsch, Richard A. Levine, Hao Helen Zhang, Thomas C. M. Lee (eds.). Computational Statistics in Data Science. Wiley, 2022. ISBN 9781119561071.
- Naveenkumar, P.; Sharma, V.; Devarajan, G.; Abdullah, A.; Elngar, A. A. (eds.). Handbook of AI-Based Mechatronics Systems and Smart Solutions in Industrial Automation. CRC Press, 2026. DOI: https://doi.org/10.1201/9781032615790.
- Chunwei Zhang, Tianpeng Li, Ying Dai, Li Sun, and Ardashir Mohammadzadeh. Practical Neural Networks in Python and MATLAB. Springer Nature, 2026. DOI: https://doi.org/10.1007/978-3-032-14746-2.
- Cybellium Ltd. Mastering Neural Networks. Cybellium, undated electronic edition (supplied copy).
- Charu C. Aggarwal. Outlier Analysis, 2nd ed.. Springer, 2017. https://doi.org/10.1007/978-3-319-47578-3