


Artificial Neural Networks and Learning Models

Historical foundations, neuron models, perceptrons and MLPs; backpropagation, Gauss–Newton, Levenberg–Marquardt and RLS training; LVQ, ART, RNNs, CNNs, Transformers, generative, graph and tensor networks; system identification, compression, and rigorous evaluation.
Artificial neural networks are computational models inspired by biological nervous systems, not literal software replicas of the brain. A network combines numerical inputs, weighted connections, processing units, and a learning procedure that adjusts parameters from data. The neuron metaphor is useful for orientation, but it should not be read as a claim that an artificial unit reproduces the full biophysics of a living cell.
Their practical value comes from learning mappings or representations from examples rather than requiring every decision rule to be written by hand. Pattern recognition, classification, forecasting, and representation learning are common cases. This does not make classical numerical or rule-based methods obsolete: depending on the problem, a neural model may be the main solver, one stage of a hybrid pipeline, or the wrong tool altogether.
Computers can exceed human performance in speed and repeatability for narrowly defined calculations, while human learning integrates perception, experience, causality, and context on a much broader scale. The engineering goal of an artificial neural network is therefore not to reproduce human intelligence in full, but to construct a parameterized system that can learn useful transformations and decision boundaries from data.
Unit 1: Historical Development and Computational Foundations
1.1. HISTORY AND FUTURE
1.1.1. History
The history of neural networks is not a sequence in which one architecture was invented on a single date and then simply replaced by the next. Mathematical neuron models, pattern recognition, associative memory, optimization, recurrent systems, and eventually high-performance computing developed along partly independent lines and repeatedly converged. Linear associators, correlation-matrix memory, ART, SOM, Hopfield, Boltzmann, RBF, PNN, and GRNN fit into this broader set of verifiable milestones.
- 1943: Warren McCulloch and Walter Pitts published a mathematical model that treated simplified neuron-like units as elements of logical computation.
- 1958: Frank Rosenblatt described the perceptron and its learning procedure in detail, establishing an influential early example of adjusting classifier parameters from examples.
- Late 1960s and 1970s: Research on linear associators, correlation-matrix memories, and other associative-memory models expanded. Discussion of the representational limits of single-layer perceptrons made the need for effective learning in multilayer systems more visible. Adaptive Resonance Theory (ART) also emerged as a separate line of work on stable pattern learning and classification.
- 1974: Paul Werbos's doctoral work provided an early systematic account of propagating derivative information backwards through multilayer structures in the context of learning systems.
- 1982: John Hopfield published his formulation of recurrent networks as associative memories governed by an energy-like function. In the same year, Teuvo Kohonen's self-organizing maps (SOMs) became a major model for unsupervised topological representation learning.
- 1985: David Ackley, Geoffrey Hinton, and Terrence Sejnowski published a learning algorithm for Boltzmann machines. Stochastic energy-based networks later influenced restricted Boltzmann machines and deep belief networks.
- 1986: David Rumelhart, Geoffrey Hinton, and Ronald Williams made backpropagation a practical and reproducible method for learning hidden representations in multilayer networks.
- Late 1980s and early 1990s: Specialized families such as radial-basis-function networks (RBF), probabilistic neural networks (PNN), and general regression neural networks (GRNN) were used for classification, prediction, and function approximation.
- 1997: Sepp Hochreiter and Jürgen Schmidhuber published Long Short-Term Memory (LSTM), explicitly targeting the weak error flow that makes long-range dependencies difficult to learn with conventional recurrent backpropagation.
- 1998: Yann LeCun and colleagues documented convolutional neural networks in real document and handwriting-recognition systems, demonstrating the structural value of local receptive fields and weight sharing for image-like data.
- 2012: The deep convolutional network trained by Alex Krizhevsky, Ilya Sutskever, and Geoffrey Hinton on ImageNet with GPU acceleration made the combined effect of large datasets, accelerator hardware, and deep models difficult to ignore.
- 2017: The Transformer architecture showed that sequence modelling could be built around self-attention without requiring recurrence or convolution. Neural-network architecture consequently became as much about attention, representation, and parallel execution structure as about traditional neuron connectivity.
1.1.2. Future
The future of neural networks is not simply a progression toward larger parameter counts. For real-time and critical systems, obtaining comparable quality with lower latency, lower energy consumption, less memory traffic, and more predictable execution can matter more than increasing model size. Low-precision arithmetic, sparse computation, reduced data movement, compiler-level optimization, and hardware-software co-design are therefore likely to remain central engineering topics.
GPU-class accelerators are already routine, while FPGA and ASIC implementations offer a different design point by mapping selected dataflows onto more specialized hardware paths. Dedicated NPUs are part of the same trend. Optical computing, analog in-memory computation, and neuromorphic circuits pursue further reductions in data-movement cost for selected workloads, but it would be premature to treat them as general replacements for GPUs.
1.2. MODEL FAMILIES AND LEARNING ALGORITHMS
Perceptron, Multilayer Perceptron (MLP), backpropagation, Learning Vector Quantization (LVQ), Adaptive Resonance Theory (ART), recurrent/Elman structures, CNNs, LSTM/GRU, attention, Transformers, Generative models, regularization, optimization, ablation, distribution shift, and production monitoring are examined alongside the corresponding model families.
1.3. Historical Sequence Is Not a Ranking of Model Quality
Historical priority and present-day adoption are different questions. McCulloch and Pitts (1943) proposed a threshold-based computational neuron; Hebb (1949) discussed connection changes associated with joint activity. Rosenblatt's perceptron (1958) made the trainable linear decision boundary explicit, while Widrow and Hoff's LMS rule and ADALINE (1960) introduced least-squares error minimization. The 1969 analysis by Minsky and Papert identified limitations of single-layer perceptrons, not an impossibility theorem for all multilayer networks. Hopfield's energy-based networks (1982), the popularization of backpropagation for multilayer models (1986), practical document-recognition CNNs in the 1990s, long short-term memory (1997), advances in deep representation learning during the 2000s, Transformers (2017), and subsequent scaling research addressed distinct computational problems.
This chronology does not establish a single architecture that supersedes all its predecessors. Prototype methods such as LVQ and ART remain useful historical examples of online classification or constrained-resource learning, but are not equivalents of convolutional or attention-based learning. Representation, objective function, inference cost, and validation must be evaluated independently.
Unit 2: Biological Inspiration and the Mathematical Neuron
2.1. BIOLOGICAL NEURONS
Much of neural-network terminology comes from neuroscience. The analogy needs a boundary: dendrites, soma, axon, and synapses are biological structures, whereas inputs, weights, aggregation, and activation are mathematical operations that only approximate selected functional ideas.
2.1.1. Dendrite
- Dendrites are branched structures that play a major role in receiving electrochemical signals from other cells.
- In the artificial-neuron analogy, they roughly correspond to multiple input channels entering the same processing unit.
2.1.2. Axon
- The axon carries electrical activity generated by the cell toward other cells.
- The closest artificial analogue is the ability of one computed output to feed many downstream units.
2.1.3. Connections
- Biological neurons influence one another through connections with different strengths and dynamics rather than through identical wires.
- Artificial networks represent this influence primarily with weights; the effect of a connection depends on the weight together with input scale, activation functions, and the rest of the network.
2.1.4. Soma
- The soma, or cell body, is the metabolic centre of the neuron and participates in integrating incoming activity.
- Simplified neural-network diagrams compare it with the point at which weighted inputs are combined, but the biological nucleus should not be equated with a mathematical summation operation.
2.1.5. Synapse
- A synapse is the junction through which one neuron influences another cell.
- The useful learning analogy lies in the fact that biological connection strengths can change; artificial networks express a much simpler version of this idea by updating weights during training.
2.2. BASIC COMPONENTS
An artificial neuron has biological terminology but is fundamentally a parameterized computational unit. In a common formulation, an input vector is multiplied by weights, combined with a bias or threshold term, and passed through a nonlinear activation. Connecting many such units in layers produces the representational capacity of the network.
A convenient five-part view of the core elements is inputs, weights, a summation function, an activation function, and an output. Scaling and limiting can be additional transformations applied after activation, depending on the architecture.
2.2.1. Inputs
- Inputs are the numerical features processed by the network. They may be raw values or derived representations such as audio frames, pixels, embeddings, or engineered measurements.
- Their scale and distribution affect training, so normalization or standardization may be necessary.
2.2.2. Weights
- Each connection is represented by a coefficient that determines how its input contributes to later computation.
- A large absolute weight does not by itself prove feature importance; input scale, nonlinearities, and downstream layers also matter.
- During training, the optimization algorithm updates weights in a direction intended to reduce the loss function.
2.2.3. Summation Function
- The common artificial-neuron operation is a weighted sum such as
z = Σ(w_i x_i) + b. - Historical and specialized network models can use different aggregation rules, including minimum, maximum, voting, distance, or normalization-based operations.
2.2.4. Activation Function
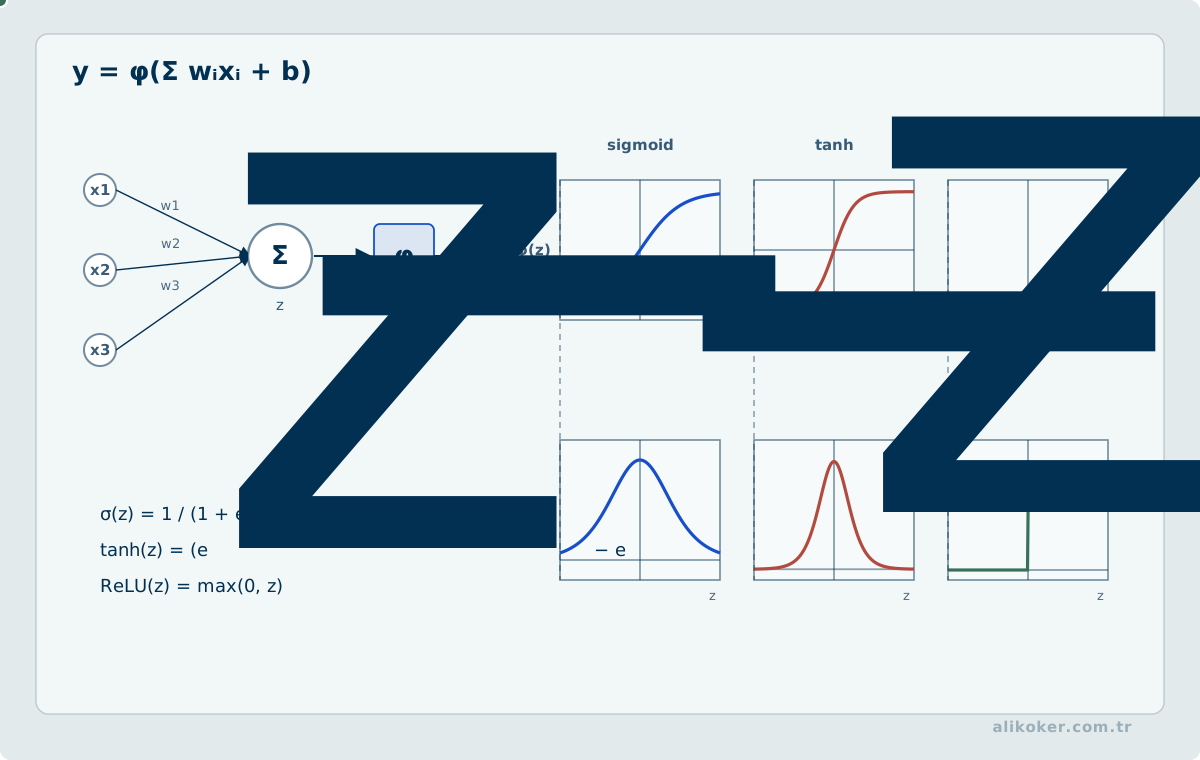
- The activation function transforms the aggregated value into the unit's output and gives the network nonlinear representational capacity.
- Sigmoid, tanh, ReLU, and their variants have been used widely in different periods and architectures.
Historical functions include:
- hard threshold/sign,
- linear,
- sigmoid,
- hyperbolic tangent.
Modern networks also use ReLU and variants:
ReLU(x) = max(0, x)Sigmoid maps to (0, 1) and is useful for binary-probability outputs under the appropriate loss; tanh maps to (-1, 1). Saturating activations can produce small gradients in deep networks.
2.2.5. Scaling and Limiting
- Some systems map activation outputs into a defined physical or numerical range.
- Scaling may be a simple multiplication; limiting constrains values to lower and upper bounds.
2.2.6. Output Function
- A processing unit's value can feed many units in the next layer or become part of the model output.
- The final layer depends on the task: regression may emit continuous values, binary classification may use a score, and multiclass models may emit multiple logits or probabilities.
2.2.7. Layer Structure
A feed-forward network contains input representation, one or more hidden layers and output layer. A layer's role depends on architecture; the "input layer" may simply denote supplied features rather than trainable neurons.
2.2.8. Network Structure by Connection Direction
In a feed-forward network, information moves from input toward output without a recurrent state path in the connection graph. This is the basic structure for fixed input-output mappings.
In a recurrent network, previous state can influence later computation. Feedback allows temporal or sequential information to be carried through an internal state. The Elman network, with its context units, and the Hopfield network, with recurrent connections and stable states, are classical examples.
Connection direction and learning paradigm are different classifications. A feed-forward network can be trained with different objectives and optimization methods, whereas recurrence adds state dependence to the computation graph. Elman, Hopfield, LSTM, and GRU architectures are examined in the recurrent-network and later-model units.
2.3. Mathematical Neuron, Shape Checking, and Trainable Parameters
A layer computes z = Wx + b and a = f(z). For x ∈ R^d, W ∈ R^(m×d), and b ∈ R^m, both z and a are m-dimensional. With biases enabled the layer contains m*d + m trainable parameters, irrespective of whether its activation is nonlinear. Composing two affine layers without a nonlinearity reduces to one affine transformation: additional depth alone therefore does not guarantee greater expressive power.
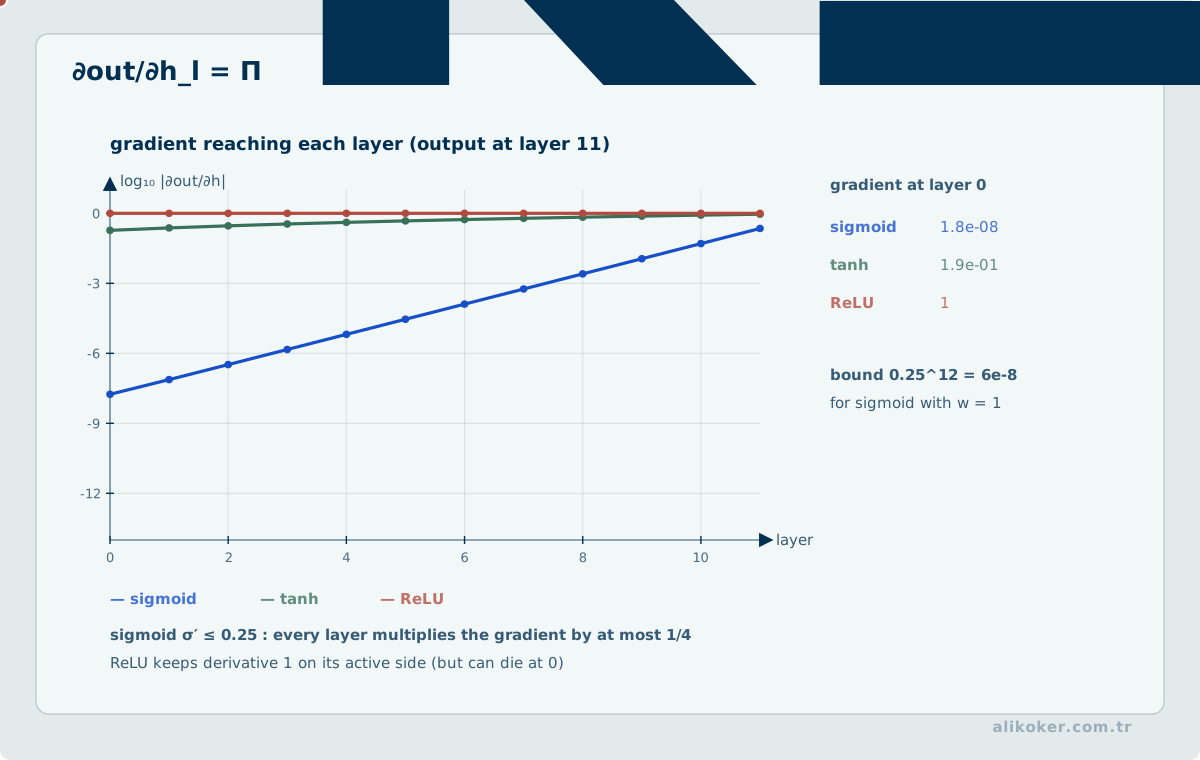
The sigmoid derivative is σ(z)(1-σ(z)), while the derivative of tanh is 1-tanh²(z). Both approach zero at large absolute activations and may contribute to vanishing gradients through repeated products. ReLU has unit slope on its positive branch but zero slope on the negative branch, raising the possibility of inactive units. Activation choice must be interpreted together with parameter initialization, normalization, numeric range, and the training objective.
Unit 3: Learning Paradigms, Data, and Representation
Before turning a learning problem into a neural network task, define the prediction target and the cost of errors. Examine data provenance, labeling, and separation of training and evaluation sets. Establish a simple baseline, then measure any gain from a more complex model under the same testing conditions. Evaluate error types, distribution shift, and interpretability needs rather than mean accuracy alone. An experiment that does not address memorization cannot by itself establish successful learning.
3.1. LEARNING
Training updates model parameters from examples according to an error signal or another learning objective. Training performance and generalization are different; behavior on data not used to fit the parameters must be evaluated separately.
3.1.1. Training, Validation and Test
Data should be separated according to purpose:
- training data update model parameters,
- validation data guide model/hyperparameter selection and stopping,
- test data estimate final generalization after design decisions are complete.
Repeatedly tuning against the test set leaks test information into the design and invalidates its role as an independent estimate.
There is no universally correct split ratio. The partition should reflect sample count, class balance, temporal dependence, subject/device/event grouping, and data-leakage risk.
3.1.2. Learning Process
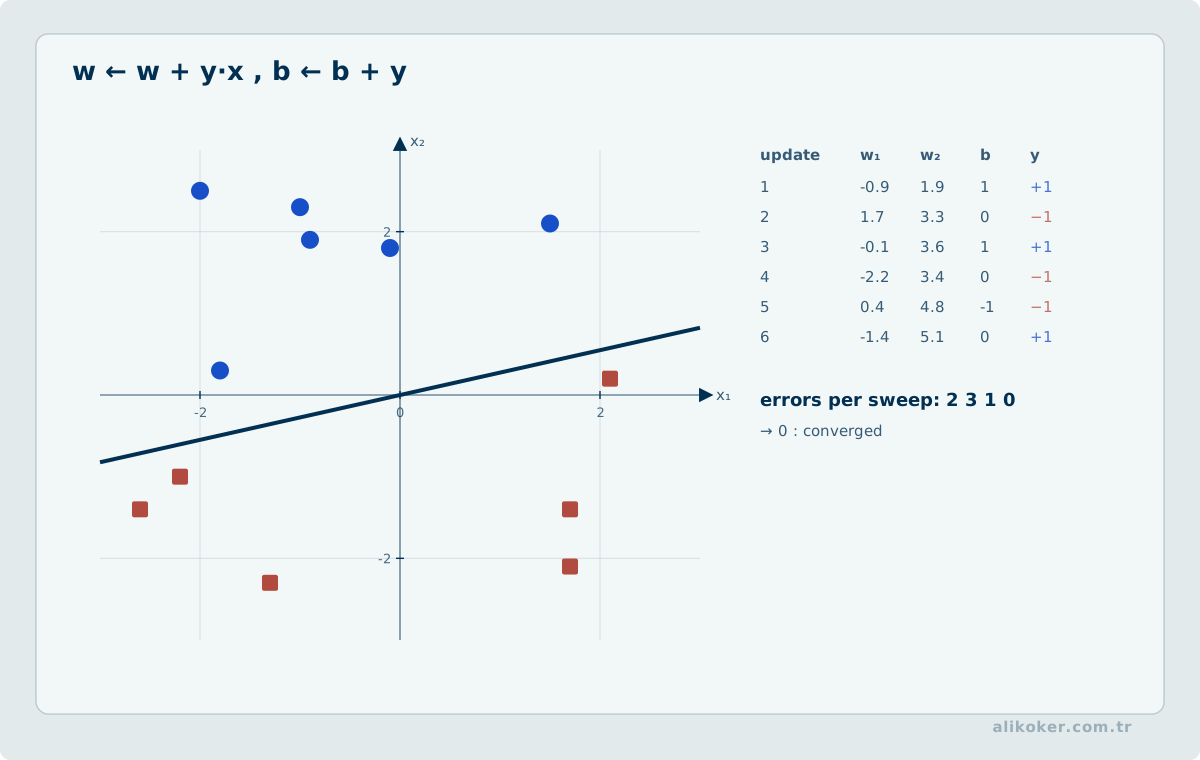
- Collect examples that represent the problem and define the target metric.
- Select the input representation, network topology, aggregation operations, and activation functions.
- Initialize weights and bias or threshold terms using an appropriate scheme.
- Present training samples individually or in mini-batches.
- Compute model outputs through the forward pass.
- Compare outputs with targets or another learning objective to obtain a loss value.
- In differentiable models, backpropagation computes gradients of the loss with respect to parameters.
- An optimization step updates the weights, and the process repeats until a stopping criterion or training budget is reached.
3.1.3. Supervised Learning
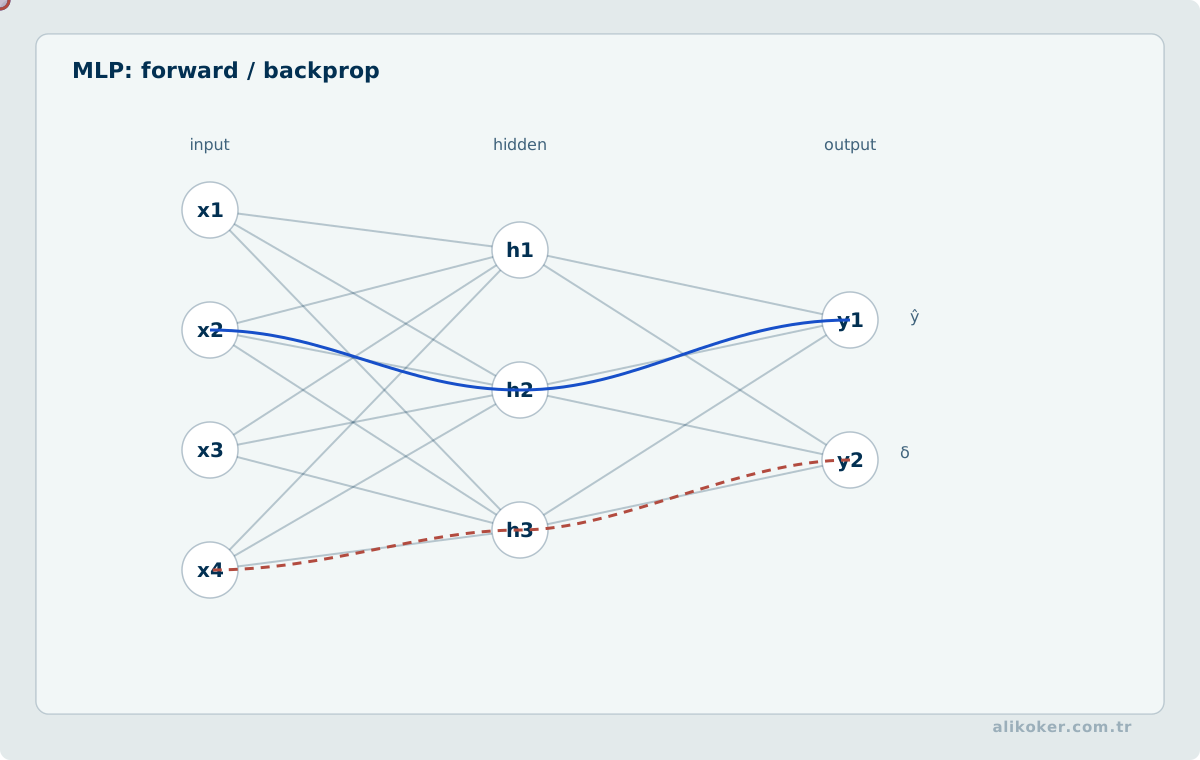
- Supervised learning provides a target value, class label, or expected output with each training input.
- A loss function measures the difference between prediction and target, and parameters are adjusted to reduce that loss.
- Classification and regression are common supervised tasks.
3.1.4. Unsupervised Learning
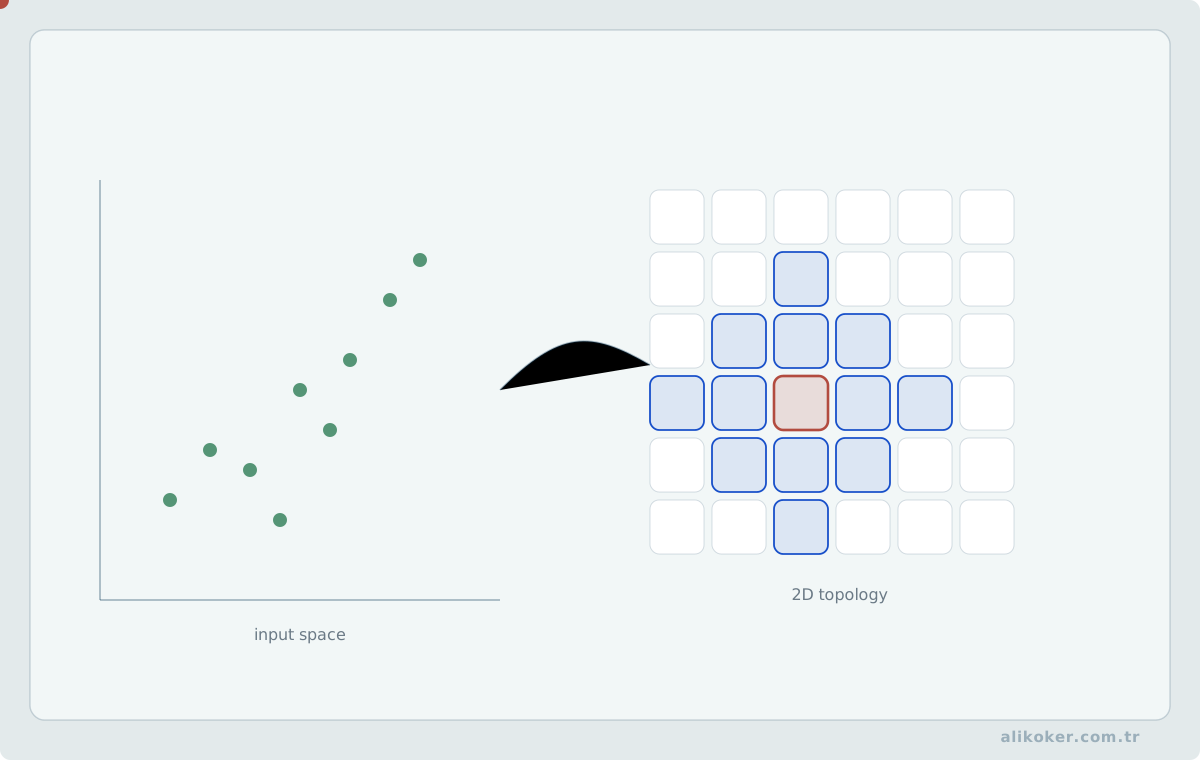
- Unsupervised learning provides no direct target label for each input; the model attempts to discover structure in the input distribution or relationships among samples.
- Clustering, density modelling, and some forms of representation learning fall into this category.
3.1.5. Reinforcement Learning
- In reinforcement learning, an agent does not receive the complete correct answer for every step. It receives rewards or penalties through interaction with an environment.
- The objective is to learn a policy that improves expected cumulative return over time rather than merely minimizing an immediate classification error.
- Feedback may be delayed, and the exploration-versus-exploitation trade-off becomes part of the learning problem.
3.1.6. Self-Supervised and Semi-Supervised Learning
Self-supervised learning derives supervision from the data itself and is central to large-scale representation learning.
Semi-supervised learning combines a smaller labeled set with a larger amount of unlabeled data.
3.1.7. Hetero-association and Auto-association
An auto-associative model learns to reproduce or recover a representation related to its input:
x -> xA hetero-associative model maps one pattern to a different associated target:
x -> yThese concepts appear historically in associative-memory neural models and still provide a useful way to distinguish reconstruction from cross-pattern mapping.
3.1.8. Learning Paradigms and Strategies
Learning may update parameters:
- online, after individual examples,
- in mini-batches,
- in full batches,
- competitively,
- through error correction,
- through correlation/Hebbian-style rules.
The algorithm must specify not only the model but also how examples are selected, how errors are computed, how parameters are initialized and when training stops.
3.1.9. Adaptation and Generalization
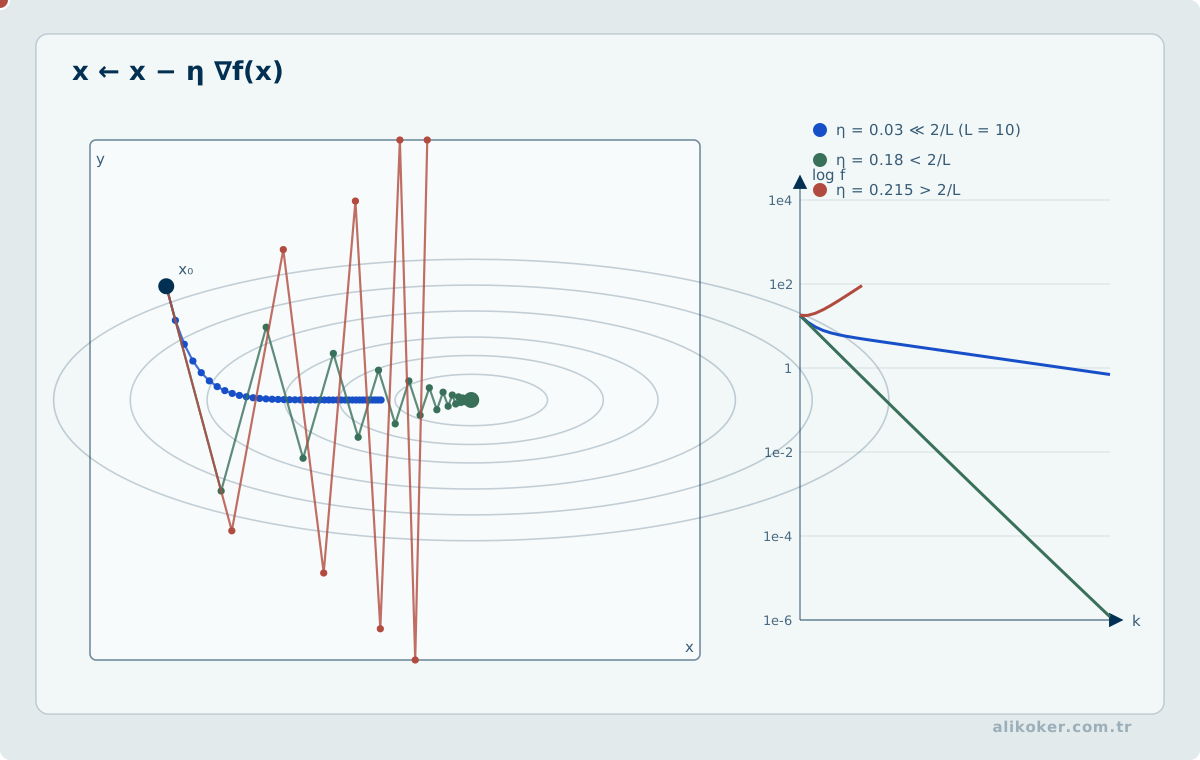
A model that only reproduces its training examples has not necessarily learned a useful function. Generalization is performance on data not used to fit the parameters.
The achievable generalization depends on:
- data quality and representativeness,
- model capacity,
- regularization,
- optimization,
- distribution shift,
- label noise,
- evaluation design.
3.2. REPRESENTATION, ROBUSTNESS AND EXPLAINABILITY
How learned information is represented, how a model behaves under noise or missing inputs, and how its decisions can be inspected are distinct but related engineering concerns.
3.2.1. Distributed Representation
Knowledge in a neural network is generally distributed across parameters rather than stored as one explicit rule per concept. This can provide graceful behavior and representation capacity, but makes explanations harder than in a transparent rule system.
3.2.2. Noise and Incomplete Data
Neural networks can be robust to noisy inputs when trained for the relevant distribution. Robustness is not automatic. Adversarial inputs, missing values, out-of-distribution samples and sensor failures can still cause confident errors.
3.2.3. Explainability
Model inspection may use feature attribution, activation analysis, surrogate models or domain-specific probes. These techniques provide evidence about behavior but do not convert a complex model into a fully transparent causal explanation.
3.3. Define the Sampling Unit Before Splitting Data
Randomly assigning data rows to training and test sets does not always create independent observations. Samples from one person, sensor, machine part, or continuous recording can reveal a source identity across splits. The split unit should therefore sometimes be a person, experiment, time block, or device, rather than an individual row. Forward-chaining evaluation suits time series; group-level splitting suits repeated measurements of the same physical entity.
Normalization statistics, feature selection, imputation parameters, and learned augmentation choices must be fitted within the training split. Validation supports hyperparameter choice, whereas a held-out test set serves as a final estimate only while it remains outside model selection. Performance on the collection environment does not automatically imply performance under the target deployment distribution.
Unit 4: Perceptron, ADALINE, and Early Learning Rules
Neural-network model selection depends on more than architecture. The learning algorithm, loss function, regularization, data distribution, experimental design, and production behavior must be evaluated together. The progression from Perceptron and ADALINE extends through Multilayer Perceptrons (MLPs), backpropagation, Learning Vector Quantization (LVQ), Adaptive Resonance Theory (ART), recurrent networks, CNNs, LSTM/GRU, attention, Transformers, and generative models.
4.1. Single-layer Networks
A single-layer linear threshold classifier forms a decision boundary:
w^T x + b = 0It can separate linearly separable classes but cannot represent arbitrary nonlinear classification boundaries.
4.2. Perceptron
For binary targets and a misclassified example, a classic perceptron update has the form:
w <- w + eta (target - output) xunder one common coding convention.
The perceptron convergence theorem guarantees convergence in finite updates when the training set is linearly separable and assumptions are met. It does not guarantee convergence for non-separable data.
4.3. XOR Limitation
XOR cannot be separated by one linear decision boundary. This illustrates the limitation of a single-layer perceptron and motivates hidden layers/nonlinear feature transformations.
4.4. ADALINE
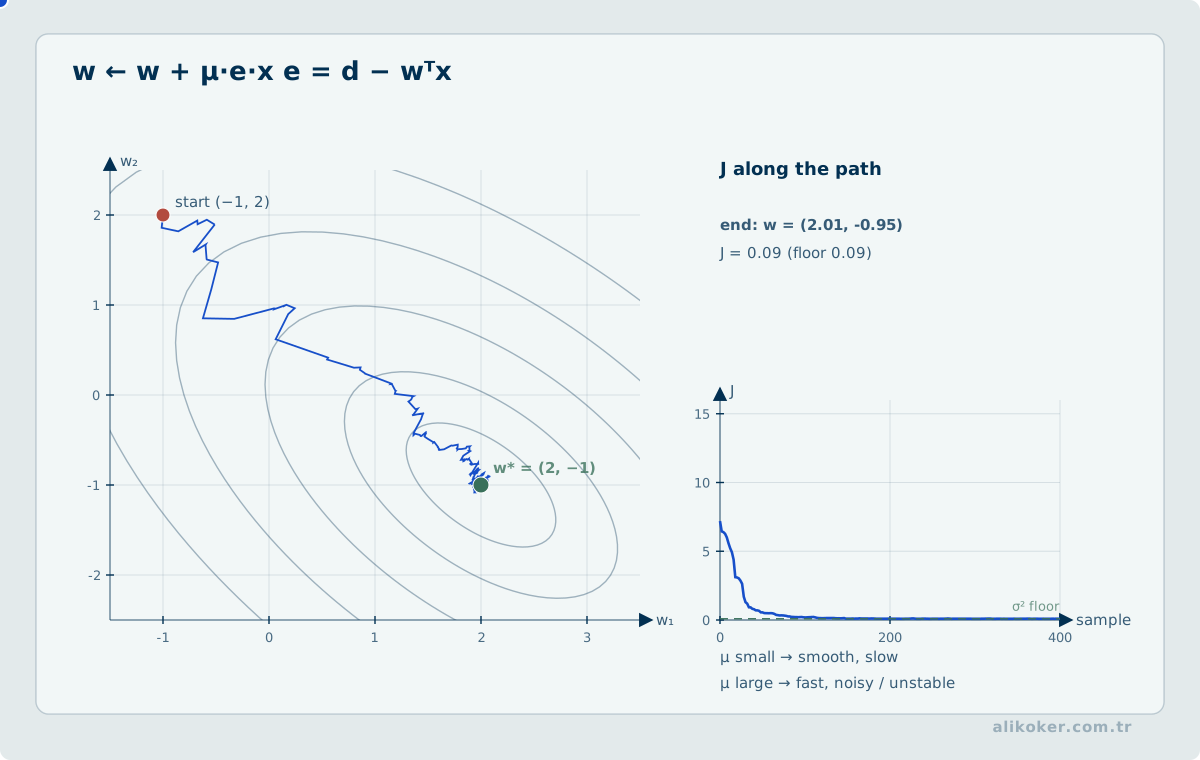
ADALINE uses a linear activation during learning and adjusts weights to reduce a mean-squared error criterion, historically through the Widrow-Hoff/LMS rule.
A basic gradient form is:
w <- w - eta * dL/dwThe update direction must follow the derivative of the defined loss; notation should not obscure the sign convention.
4.5. MADALINE
MADALINE combines multiple ADALINE units. It is historically important as an early multilayer adaptive architecture, although its training methods differ from contemporary generic backpropagation.
Unit 5: Multilayer Networks, Forward Propagation, and Backpropagation
This unit treats the forward pass, loss computation, backpropagation, and weight update as one iterative supervised-learning optimization loop.
input -> hidden layers -> output -> loss
  ^                              |
  |                              v
  +---- weight update <- backpropagation

forward pass -> error -> gradient -> update -> next forward pass
Before training a multilayer perceptron, examine input scales, the target distribution, and whether the loss matches the task. Each iteration computes predictions in the forward pass, evaluates loss, and propagates derivatives backward through the chain rule. Update magnitude depends on learning rate; decreasing training loss does not establish generalization. Inspect training and validation curves together to distinguish overfitting from optimization instability.
5.1. Multilayer Perceptron
An MLP composes affine transformations and nonlinear activations:
h = phi(W1 x + b1)
y_hat = psi(W2 h + b2)
With sufficient hidden capacity and suitable activations it can represent nonlinear decision functions that a single linear layer cannot.
5.2. Solving XOR
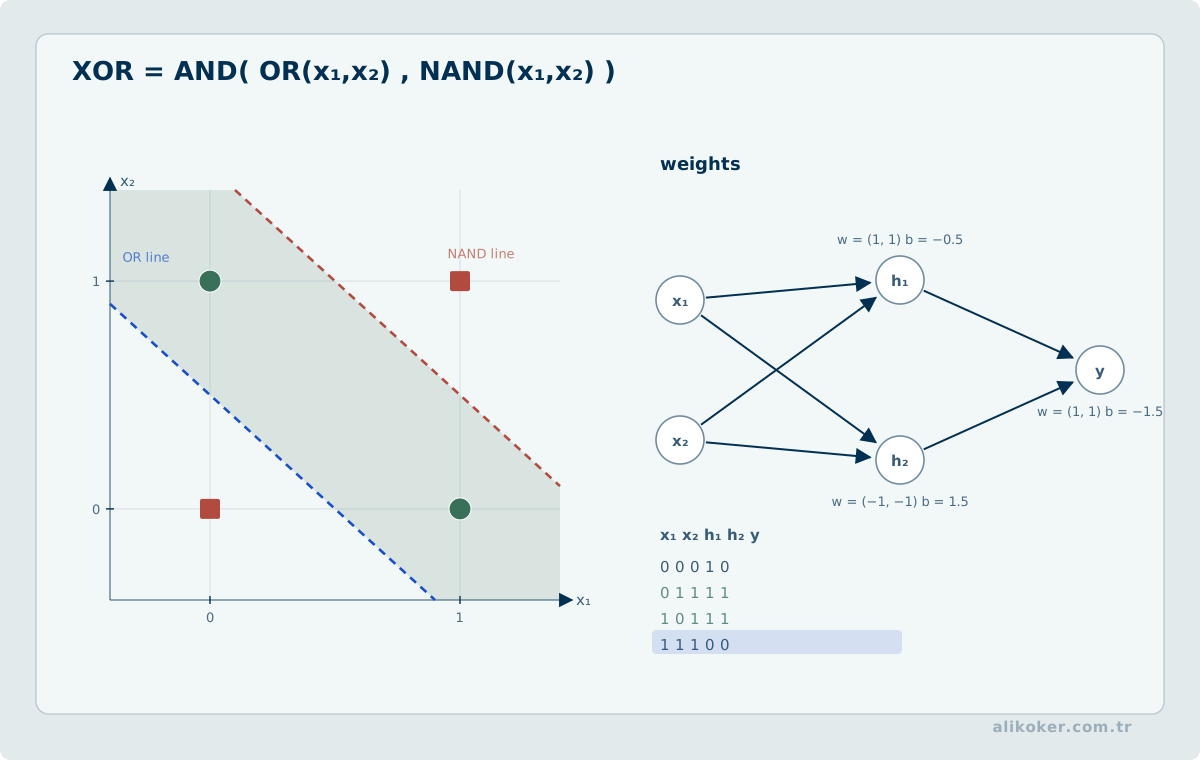
A hidden layer can construct intermediate regions/features that separate XOR. The important lesson is not a particular hand-coded weight set but that composition of nonlinear units changes the representable function class.
5.3. Forward Propagation
A feed-forward pass computes layer outputs in order. For layer l:
z^(l) = W^(l) a^(l-1) + b^(l)
a^(l) = phi(z^(l))
The output and target define a loss.
5.4. Backpropagation
Backpropagation applies the chain rule to compute derivatives of the loss with respect to each parameter efficiently.
For output error signal delta^(L), a hidden-layer error is propagated conceptually as:
delta^(l) = (W^(l+1)^T delta^(l+1)) .* phi'(z^(l))and weight gradient:
dL/dW^(l) = delta^(l) a^(l-1)^TGradient descent then updates parameters:
W <- W - eta * dL/dW
b <- b - eta * dL/db
The exact output delta depends on activation and loss. For example, softmax with cross-entropy leads to a particularly simple derivative under standard formulation.
5.4.1. Tracing the Chain Rule Numerically
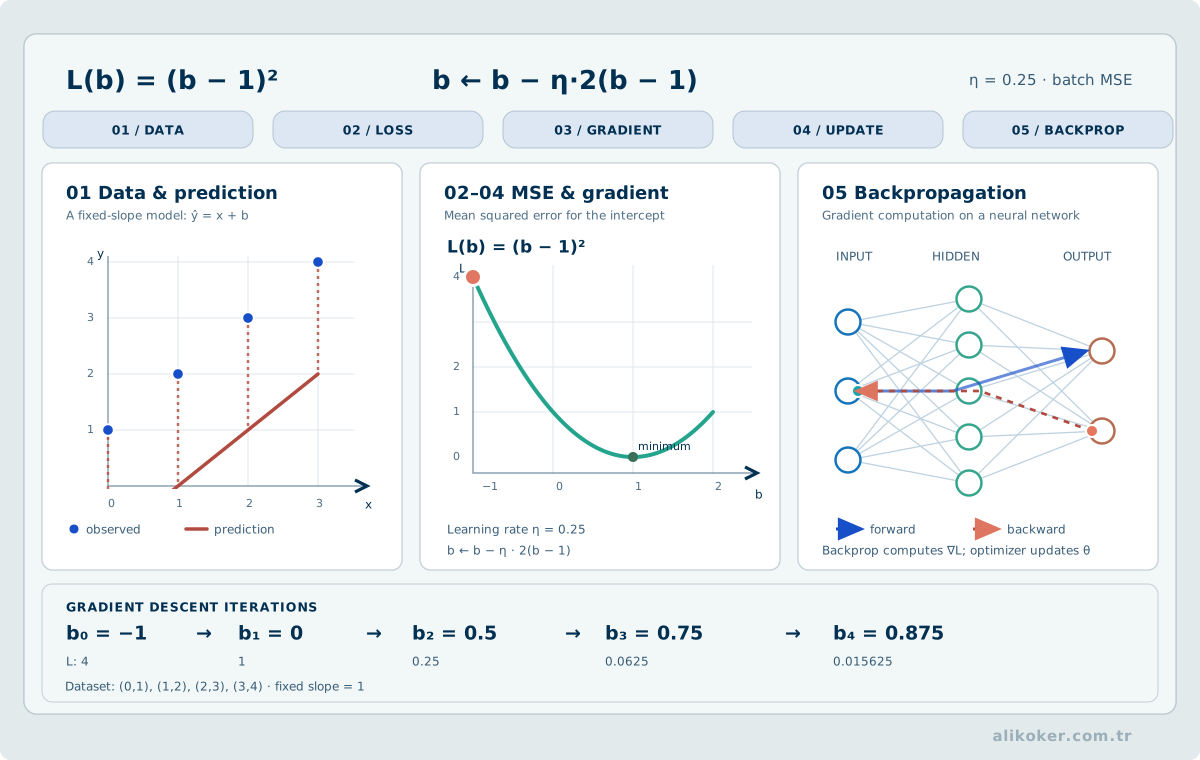
The gradient descent example in statistical learning makes the connection between parameter values and loss visible. A multilayer network adds a computational-graph dependency: each earlier weight needs a derivative of the final loss. Backpropagation computes these derivatives; the optimizer performs the separate parameter update.
Consider a two-weight computation graph with linear activations, x = 2, target y = 3, and initial weights w1 = 0.5, w2 = 1. The purpose of the linear setup is to expose the chain rule without obscuring arithmetic. It is not an example of the additional representational power of nonlinear hidden layers.
Forward pass:
h = w1 * x = 0.5 * 2 = 1
y_hat = w2 * h = 1 * 1 = 1
L = 0.5 * (y_hat - y)^2 = 2

Backward pass (chain rule):
dL/dy_hat = y_hat - y = -2
dL/dw2 = (dL/dy_hat) * h = -2
dL/dw1 = (dL/dy_hat) * w2 * x = -4

Optimizer (η = 0.1, simultaneous updates):
w2_new = 1 - 0.1 * (-2) = 1.2
w1_new = 0.5 - 0.1 * (-4) = 0.9

Next forward pass:
h_new = 0.9 * 2 = 1.8
y_hat_new = 1.2 * 1.8 = 2.16
L_new = 0.5 * (2.16 - 3)^2 = 0.3528
Both gradients are evaluated using the same forward pass and the old parameter values. Recomputing the first-layer gradient with the already updated w2 would be a different update procedure. For nonlinear activations, the chain rule introduces the corresponding φ'(z) factors. Whenever one parameter reaches the loss along multiple computational-graph paths, its gradient contributions are summed.
The training iteration preserves the distinction among example/batch selection, forward pass, loss computation, backpropagation, optimizer update, and validation. Retaining intermediate activations for the backward pass consumes memory; activation checkpointing exchanges additional computation for reduced activation storage. In dense layers, the core arithmetic for one example scales approximately with the number of weights, while batch size increases both total arithmetic and intermediate-tensor storage. Successful optimization on the training set still requires an independent generalization assessment.
5.5. Training Procedure
A practical training loop is:
- initialize parameters,
- select a batch/example,
- perform forward propagation,
- compute loss,
- backpropagate gradients,
- update parameters,
- evaluate validation behavior,
- stop according to a defined criterion.
Randomizing/shuffling training examples can reduce systematic ordering effects in stochastic methods.
5.6. Error Surfaces
Neural-network objectives are generally non-convex. Saddle points, flat regions and different local minima can occur. The goal of optimization is useful generalization, not necessarily discovery of one globally unique parameter vector.
5.7. Backpropagation as Repeated Chain Rule
Backpropagation is an efficient way to apply the chain rule through a computational graph. For a layer
z = W a + b, a_next = φ(z),
the backward pass propagates the loss gradient from later layers to earlier activations and parameters.
The important engineering consequence is that gradient scale depends on activation derivatives, weight scale, depth, normalization, and the loss function. Vanishing and exploding gradients are consequences of repeatedly multiplying Jacobian factors.
Initialization and normalization should be chosen together with the activation. Saturating activations and poorly scaled weights can make learning slow even when the network has enough capacity.
5.8. Validation, Calibration, and Decision Thresholds
Training loss measures optimization on the observed training set. It does not establish generalization.
A separate validation set supports model and hyperparameter selection; the final test set should remain isolated from that process. Under class imbalance, accuracy alone can hide failure on minority classes.
For probabilistic classifiers, calibration asks whether predicted confidence matches observed frequency. The decision threshold should follow application cost, recall/precision trade-offs, and operational capacity rather than being fixed automatically at 0.5.
5.9. Automatic Differentiation, Computational Graphs, and Backpropagation
Backpropagation is best understood as systematic application of the chain rule on a computational graph rather than as a collection of manually derived formulas. Each node carries a local operation and local derivative, and total derivatives are assembled along graph paths.
Forward-mode automatic differentiation propagates derivative information with an input direction and naturally resembles a JVP. Reverse mode begins from an output sensitivity and propagates it toward inputs and parameters, corresponding to VJP structure. This is why reverse mode matches neural networks with many parameters and a scalar loss.
Automatic differentiation is neither symbolic differentiation nor finite differences. Symbolic differentiation creates a new expression; finite differences approximate derivatives from perturbed evaluations; automatic differentiation chains exact local derivative rules through executed operations, typically reaching accuracy close to machine precision.
5.10. Gradient Accumulation, Graph Lifetime, and Numerical Trust
A parameter can influence the loss through several graph paths. Reverse-mode differentiation must sum the gradient contributions from those paths. Mini-batch gradient accumulation similarly combines contributions from several examples before an optimizer step.
In dynamic computational graphs, deciding which intermediate activations to retain determines memory cost. Checkpointing intentionally discards selected intermediates and recomputes them during the backward pass, trading computation for memory.
The existence of a numerical gradient does not prove correctness. Finite-difference gradient checks on small synthetic cases, loss-scale checks, NaN/Inf monitoring, and layer-wise gradient norms are useful implementation tests. Full gradient checking is too expensive at production scale, so correctness should be established with small controlled tests.
Backpropagation is more precisely the application of the chain rule to a composed computation than the literal sending of an error value backward. For a neuron with z = wx, y = z and squared loss L = (y−t)^2/2, the gradient is dL/dw = (y−t)x. With x=2, w=3 and t=4, the output is 6 and the gradient is 4; a learning rate of 0.1 gives the updated weight 3−0.1×4 = 2.6. This demonstrates that learning does not copy a target label into a weight. Deeper networks apply the same chain rule through activation derivatives and shared parameters.
5.11. Numerical Gradient Check for a two-parameter Neuron
Take z = wx + b, a = σ(z), and L = (a-t)²/2. With x=2, t=1, w=0, and b=0, the initial output is a=0.5 and the loss is L=0.125. The chain rule yields ∂L/∂z = (a-t)a(1-a) = -0.125, ∂L/∂w = -0.25, and ∂L/∂b = -0.125. At learning rate 0.1, one gradient step gives w=0.025, b=0.0125, and logit 0.0625. The example separates gradient computation by backpropagation from the parameter update chosen by the optimizer.
An analytical gradient can be checked against the central finite difference [L(θ+ε)-L(θ-ε)]/(2ε). Excessive ε leads to truncation error and tiny ε can magnify floating-point cancellation. Use a small deterministic network with stochastic layers disabled and matched numerical precision. Correct gradients do not imply convergence to a global optimum.
Unit 6: Training and Optimization Algorithms
6.1. Modern Optimization
Stochastic gradient descent with momentum remains a strong baseline. Adaptive optimizers such as Adam use moving estimates of first and second gradient moments. An optimizer does not remove the need to select learning-rate schedules, regularization and validation protocol.
6.2. First-order Methods, Gauss–Newton, and Levenberg–Marquardt
For a least-squares objective F(θ) = (1/2)∑ r_i(θ)² with residual Jacobian J_ij = ∂r_i/∂θ_j, the gradient is g = Jᵀr and the exact Hessian is H = JᵀJ + ∑ r_i ∇²r_i. Gauss–Newton neglects the latter sum and solves (JᵀJ) Δθ = -Jᵀr. Levenberg–Marquardt stabilizes the step by solving (JᵀJ + λD) Δθ = -Jᵀr, where D can be the identity or an appropriate diagonal scaling. Larger λ makes updates more conservative; lower damping approaches the Gauss–Newton step. Numerically stable linear factorization is preferable to explicitly inverting a matrix.
A dense Hessian for p parameters can require O(p²) memory, explaining the scalability of SGD and Adam-like first-order optimizers for large networks. GN/LM are especially relevant when a tractable residual vector, a least-squares objective, and a computable Jacobian are available. Applying the identical least-squares formula to cross-entropy without specifying an appropriate curvature approximation would be unjustified.
6.3. Online Training of a Linear Readout Using RLS
Let the fixed feature extractor produce φ_t ∈ R^d, with target y_t and linear readout weights w_t. For forgetting factor 0 < ρ ≤ 1, compute k_t = P_(t-1) φ_t / (ρ + φ_tᵀ P_(t-1) φ_t), w_t = w_(t-1) + k_t(y_t - φ_tᵀw_(t-1)), and P_t = ρ^(-1)(P_(t-1) - k_t φ_tᵀP_(t-1)). In the scalar case φ=1, starting at P=1, w=0, ρ=1 and observing y=2 gives k=0.5, w=1, P=0.5. A second identical target gives k=1/3, w=4/3, P=1/3. Initialization and regularization still influence finite-sample behavior.
RLS needs O(d²) covariance storage and care for numerical stability. Suitable for fixed or linearly parameterized features, it is not synonymous with backpropagation through a complete multilayer architecture. Covariance symmetry, positive definiteness, weak excitation, and distribution shifts should be monitored.
6.4. Gradient Checking and Numerical Differentiation Limits
A decreasing training loss does not by itself establish that backpropagation is implemented correctly. An analytical derivative can be compared with a central finite difference for each selected weight:
\[ \frac{\partial L}{\partial w_i}\approx\frac{L(w_i+h)-L(w_i-h)}{2h}. \]
Under smoothness assumptions the central difference has \(O(h^2)\) truncation error, while an excessively small \(h\) increases rounding and subtractive-cancellation error. Several reasonable step sizes should be examined rather than trusting one value. The check is performed on a small network with fixed deterministic inputs and parameters; random operations such as dropout are disabled or controlled consistently.
Both absolute and scaled error, for example \(\lvert g_a-g_n\rvert/\max(1,\lvert g_a\rvert,\lvert g_n\rvert)\), can be examined. Near-zero gradients, saturated activations, and nondifferentiable points require special care. Finite differences are not a replacement for training-time differentiation; they are a diagnostic technique for small models and automatic-differentiation implementations. Passing a gradient check does not establish generalization performance.
Unit 7: Network Design, Regularization, and Generalization
This unit separates the roles of training, validation, and test data in model selection and estimation of generalization performance.
dataset
   |
   +--> training -----> update weights
   |
   +--> validation ---> model / threshold / stopping decisions
   |
   +--> test ---------> final generalization estimate only
A network architecture should not be selected from one trial. Keep training and validation partitions fixed while varying layer width, regularization, and learning rate through controlled experiments. If performance improves, also compare parameter count, inference latency, and errors on shifted data. The selected model should satisfy defined accuracy, resource, and reliability limits rather than simply yielding the highest single score.
7.1. Performance Measurement
A loss used for optimization is not necessarily the only evaluation metric. Classification may require accuracy, precision, recall, F-score, ROC/PR analysis or calibrated error costs. Regression may use MAE, MSE/RMSE or domain-specific tolerances.
Metrics must be selected from the operational consequence of errors.
7.2. Overfitting
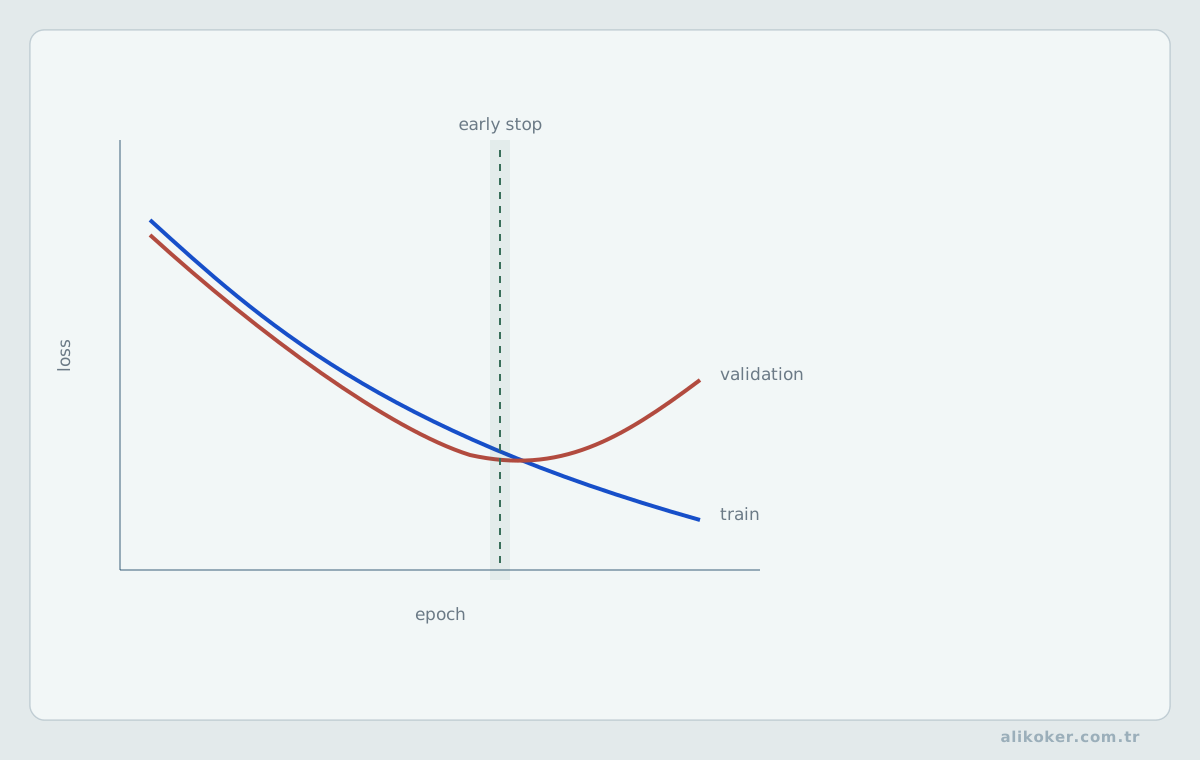
Overfitting occurs when the learned model captures training-specific noise/patterns that do not generalize. Symptoms include improving training error while validation error stops improving or worsens.
Controls include:
- more representative data,
- regularization,
- early stopping,
- appropriate capacity,
- augmentation where semantically valid,
- cross-validation for limited datasets.
7.3. Example Selection
Training examples should cover the expected deployment distribution. Random train/test splitting can be misleading when samples from the same subject, session, machine or time period leak correlated information across splits.
7.4. Input and Output Representation
Input scale and encoding directly affect optimization. Categorical variables, bounded numerical measurements, images and time series require different representation choices.
Outputs should match the task: linear outputs for unconstrained regression, logistic-style outputs for binary probabilities, softmax-like normalized outputs for mutually exclusive classes, or structured outputs for more complex tasks.
7.5. Weight Initialization
Initializing every hidden weight identically prevents symmetry breaking. Random initialization with variance scaled to layer fan-in/fan-out improves signal/gradient propagation. Later Xavier/Glorot and He-style initializations formalize this principle for common activation families.
7.6. Learning Rate and Momentum
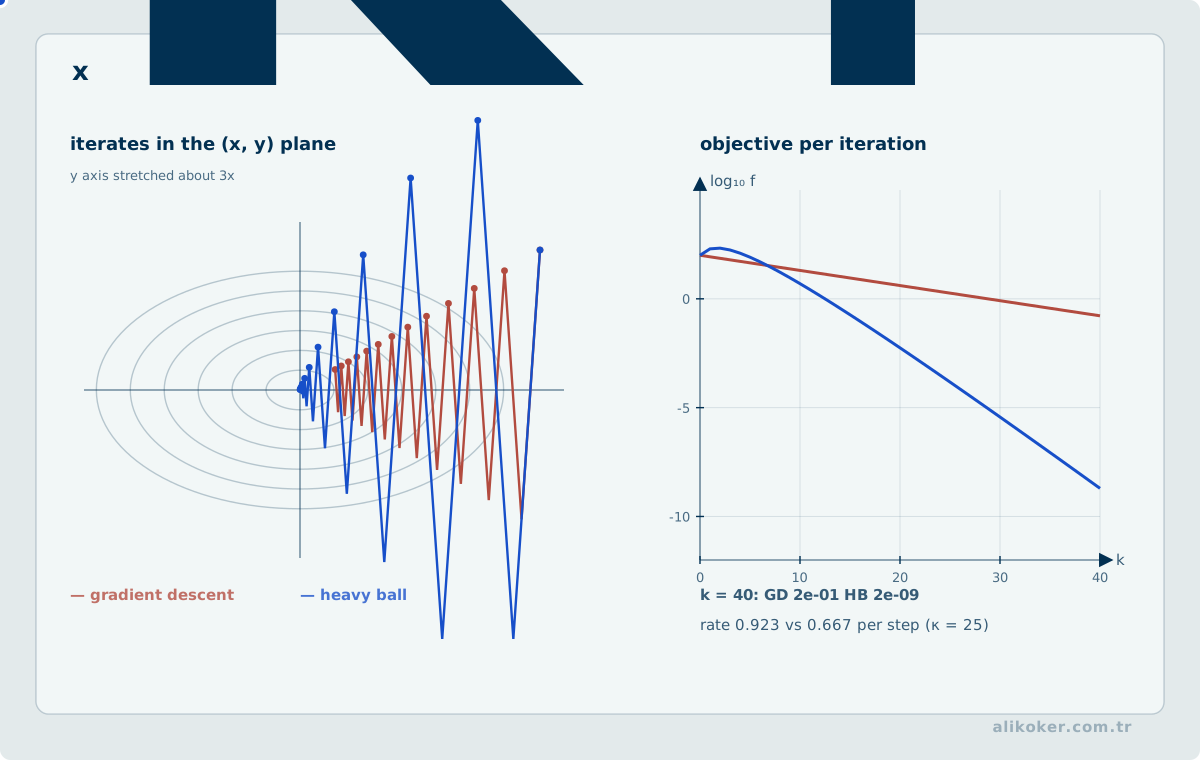
A learning rate that is too large can destabilize training; one that is too small can make optimization impractically slow.
Classical momentum accumulates a velocity-like term so updates retain direction across iterations and can smooth oscillation:
v_t = beta v_(t-1) + gradient_term
w_t = w_(t-1) + v_t
with sign convention determined by the update definition.
7.7. Scaling
Features with very different numeric ranges can create poorly conditioned optimization. Standardization or bounded scaling should be fit using training data only and then applied consistently to validation/test/deployment data.
7.8. Stopping Criteria
Training can stop after:
- a maximum epoch count,
- objective convergence,
- validation-based early stopping,
- reaching a domain performance target.
Stopping because training error is nearly zero is not automatically desirable.
7.9. Hidden Layers and Units
There is no universal formula for the correct number of hidden units. Capacity should be selected empirically against data scale, validation behavior, latency/memory constraints and regularization.
Constructive methods grow a network; pruning methods remove weak parameters/units. Modern architecture search and sparsification extend these ideas but do not eliminate the need for independent evaluation.
7.10. Feature Fusion, Calibration, and Generalization in Small Networks
A decision problem with a bounded feature set does not require a large neural network. Its input may contain normalized lexical match strength, candidate-score margin, stem–affix compatibility, negation, and context validity. A single hidden layer can learn interactions that a linear classifier misses, such as phonetic similarity being useful only when morphology agrees. However, many features originating from the same signal make memorization easier on a small training set.
A random row split is often inadequate for evaluating the trained model. If variants of the same utterance template appear in both training and test data, performance can appear artificially high. Splits should be grouped by expression family, task, and, when relevant, time. Feature scaling, missing-value handling, and lexicon version are part of the model artifact; storing weights alone may not reproduce the original prediction.
Three numerical outputs do not automatically represent calibrated probabilities. Decisions such as acceptance, clarification, and abstention require calibration and a separate cost matrix. Inference may be implemented as fixed-weight matrix–vector operations, while training loops, random initialization, and weight updates remain outside the production path. A learned score can never replace invariants such as record authorization or the negation of an action.
7.11. Regularization
Regularization includes weight penalties, dropout, data augmentation, early stopping and architecture constraints. The purpose is not simply to make weights small but to improve generalization under the expected data distribution.
7.12. Normalization
Batch normalization uses mini-batch statistics during training and running statistics for inference under its standard form. Layer normalization normalizes within each sample representation and is common in Transformer architectures. The correct choice depends on architecture and batch/sequence behavior.
7.13. Capacity, Overparameterization, and Generalization
Having more trainable parameters than training observations does not, by itself, prove poor generalization. The learned function also depends on optimizer-induced implicit bias, label noise, data independence, and regularization. Low training error demonstrates successful fitting, not out-of-sample reliability. When training and validation losses diverge, early stopping or capacity changes may help; repeatedly redesigning the network after reviewing test results creates selection bias.
Record parameter count, per-sample inference cost, and independent validation performance as distinct measurements. A smaller parameter count does not guarantee lower latency: matrix dimensions, memory transfers, kernel launches, and the target processor all affect the actual cost.
Unit 8: Industrial Prediction with Multilayer Networks
8.1. Problem Definition
An industrial prediction problem begins with a measurable target and a clear decision/use of the prediction. Sensor variables should be selected for causal/operational relevance, not simply because they are available.
8.2. Experimental Design
If training data come from controlled experiments, the experiment must span the operating region in which the model will later be used. A network cannot be expected to interpolate reliably into regions that are absent or poorly sampled, and extrapolation is especially risky.
8.3. Inputs and Outputs
Inputs may include process settings, environmental measurements and lagged state. Outputs may represent quality, energy, yield or another process variable.
Leakage must be prevented: a feature that becomes available only after the target event cannot be used for real-time prediction even if it produces excellent retrospective accuracy.
8.4. Optimization Through a Learned Model
A trained model can be used as a surrogate inside an optimization loop, but an optimizer may exploit model errors and drive inputs toward unsupported regions. Input constraints and validation against the physical process are therefore necessary.
Unit 9: Competitive Learning, LVQ, and Pattern Recognition
9.1. Purpose
LVQ is a prototype-based supervised classification family associated with Kohonen. Each prototype/codebook vector represents a region and carries a class label.
9.2. Structure and Distance
Given input x, the closest prototype under the chosen metric is found:
c = argmin_j ||x - w_j||The winning prototype determines the class.
9.3. LVQ1 Update
A common LVQ1 rule moves the winning prototype toward a correctly classified sample:
w_c <- w_c + alpha (x - w_c)and away from a sample of another class:
w_c <- w_c - alpha (x - w_c)The learning rate is commonly reduced over training.
9.4. Decision Regions
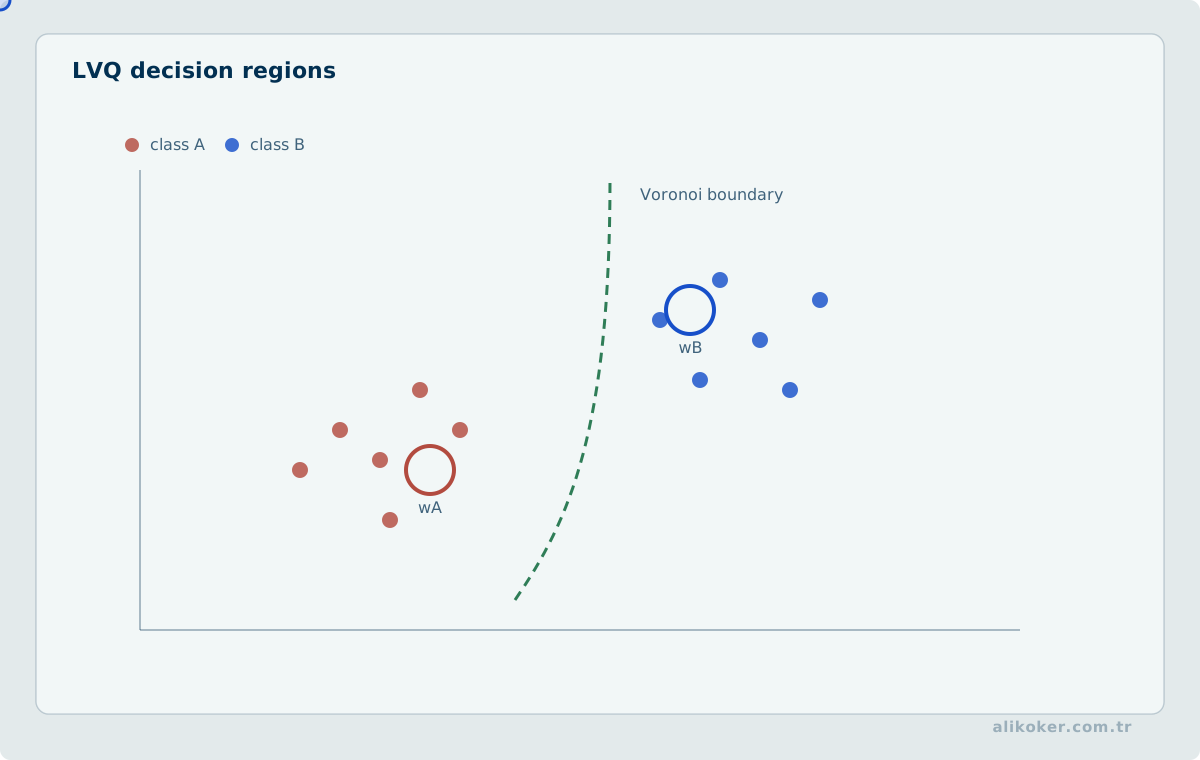
Nearest-prototype classification partitions feature space into Voronoi-like regions. The quality therefore depends strongly on feature scaling, distance metric and prototype placement.
9.5. LVQ2 and Boundary Refinement
LVQ2-style variants focus updates on samples near class boundaries and adjust prototypes from competing classes. The exact window conditions and variant definitions should be stated when implementing them; "LVQ" is a family rather than one universal update rule.
9.6. Penalized and Extended Variants
Historical penalized or modified LVQ forms aim to reduce prototype domination, improve boundary representation or handle different data structures. Their names are less standardized than core LVQ1/LVQ2, so implementations should document their exact rule.
9.7. Strengths and Weaknesses
LVQ is interpretable in terms of prototypes and computationally light for low-dimensional engineered features. It is sensitive to feature scaling and metric choice and does not learn hierarchical representations from raw high-dimensional signals in the manner of deep networks.
9.8. LVQ Quality-Control Application
9.9. Statistical quality-control Example
A process can be represented by feature vectors derived from measured signals or summary statistics. LVQ prototypes then represent known normal/fault classes.
The engineering sequence is:
- define measurable states/classes,
- collect representative examples,
- normalize features,
- initialize class prototypes,
- train on labeled examples,
- evaluate on independent data.
Evaluation should use a confusion matrix and class-sensitive metrics, particularly when faults are rare.
9.10. Later Perspective
For low-dimensional engineered features, LVQ remains a useful simple baseline. For high-dimensional image, audio or long sensor sequences, later CNN, recurrent or Transformer-based models can learn representations directly, but they introduce greater data and compute requirements.
9.11. Distance, Margin, and Ambiguity in a Prototype Classifier
Every LVQ prototype carries a class label and classification selects a winner under a defined distance metric. Features with incomparable scales can dominate Euclidean distance unless normalization or a justified metric is applied. Updating a correct–incorrect prototype pair near a class boundary can sharpen separation, but its margin or window hyperparameters must be selected using validation observations only.
For one-dimensional prototypes of classes A and B at 0 and 4, a query x=1.5 is assigned to A because distances are 1.5 and 2.5. At x=2, a tie occurs and the tie-breaking policy must be stated. Overall accuracy should be accompanied by boundary cases and inspection of regions represented by each prototype.
Unit 10: Adaptive Resonance Theory and Group Technology
10.1. Stability-plasticity Problem
An adaptive system should learn new patterns without catastrophically destroying previously learned categories. ART architectures were designed around this stability-plasticity tension.
10.2. Basic ART Mechanism
ART uses competitive category selection followed by a similarity/vigilance test. If the candidate category sufficiently matches the input, resonance allows learning. Otherwise the category is reset and another candidate is tried or a new category is created.
10.3. F1 and F2 Layers
In the traditional description, F1 represents the input/comparison field and F2 represents category units. Bidirectional weights participate in category choice and match checking.
10.4. Vigilance
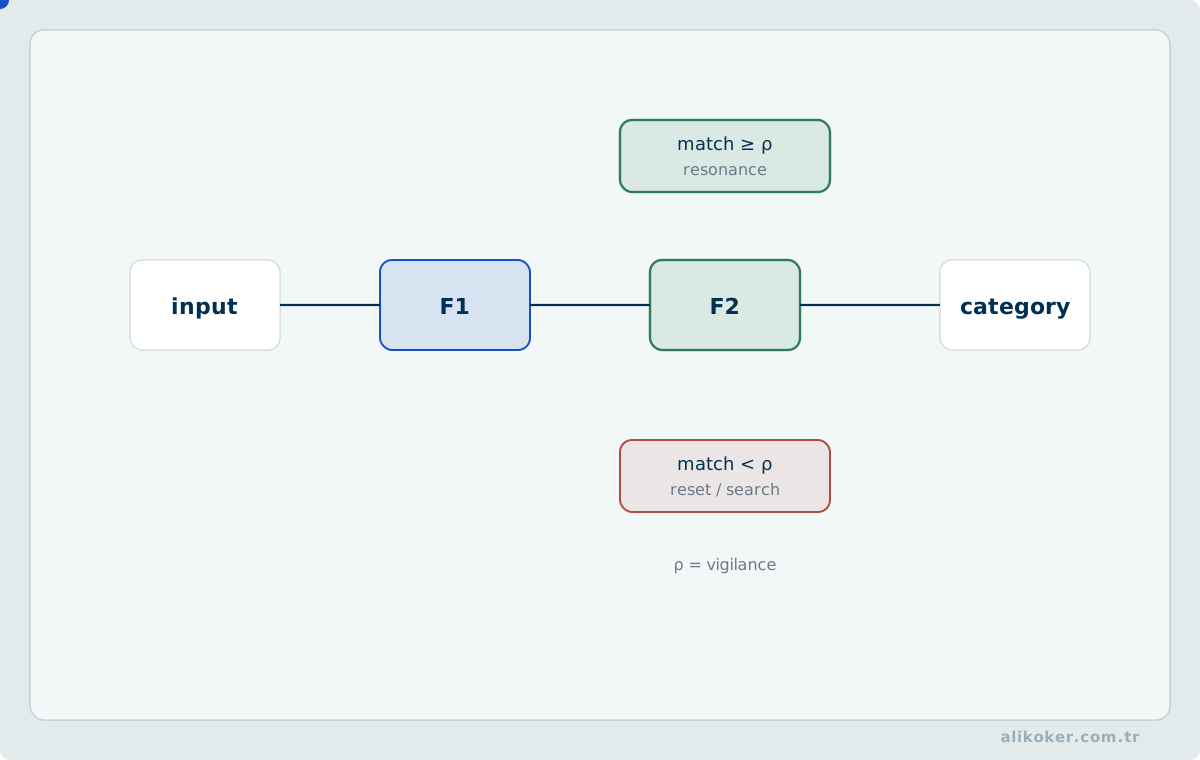
The vigilance parameter controls category granularity. Higher vigilance demands a closer match and tends to create more categories; lower vigilance allows broader categories.
10.5. ART1 and ART2
ART1 is designed for binary input patterns. ART2 extends the idea to continuous-valued inputs. These are historical model families; later clustering methods use different objectives and optimization formulations.
10.6. ART1 Group-Technology Application
10.7. Group Technology
Group technology in manufacturing groups parts with similar design/manufacturing characteristics so processes can be organized into families/cells.
Binary feature vectors can describe properties such as machine requirements or part characteristics. ART1 can cluster such vectors adaptively.
10.8. Iterative Operation
Each input selects a candidate category, is tested against vigilance, then either updates that category or causes reset/search. Results depend on vigilance, input order and preprocessing; the clustering is therefore not a unique ground truth.
10.9. Engineering Interpretation
ART1 is valuable here as an example of incremental unsupervised categorization with an explicit similarity threshold. Modern clustering should still be compared against simpler and more robust baselines for the actual data distribution.
10.10. Sequence Memory, Truncation, and recurrent-state Stability
A recurrent network carries state across sequence positions, so training couples parameters through time. Backpropagation through time unfolds the recurrence and accumulates gradients over that chain.
Long sequences increase memory cost and can worsen vanishing or exploding gradients. Truncated BPTT limits the number of unfolded steps and trades long-range credit assignment for bounded computation.
LSTM and GRU architectures introduce gates that make state retention and update more controllable, but they do not remove the need for sequence masking, state-reset policy, gradient clipping, and evaluation under distribution shift.
10.11. Stability–Plasticity and observation-order Dependence
An ART network accepts an observation into an existing category according to its match function and vigilance threshold. Excessive vigilance may proliferate categories, while insufficient vigilance may merge genuinely distinct patterns. Category formation can depend on input order and noise. Binary-input ART1 and variants for continuous signals require different representation and normalization assumptions.
In a group-technology classification task, a measurement error that creates a new category should prompt inspection of the input and match threshold rather than an unquestioned permanent category assignment. ART is a historically important solution to particular online clustering requirements, not a general substitute for modern deep representation learning.
Unit 11: Sequence Learning: Elman, LSTM, and GRU
This unit explains how hidden state is carried through time and how shared parameters model sequential dependencies.
x(t-1) -> h(t-1) -> y(t-1)
            |
            v
x(t)   ->  h(t)   -> y(t)
            |
            v
x(t+1) -> h(t+1) -> y(t+1)

time unrolling with shared parameters
11.1. Recurrent-network Concept
A recurrent network feeds information from previous states back into later computation. A simple state equation is:
h_t = phi(W_x x_t + W_h h_(t-1) + b)The hidden state creates temporal memory.
11.2. Elman Network
An Elman network uses a hidden layer whose previous activation is copied to context units and provided as additional input at the next time step.
Conceptually:
x_t + context(h_(t-1)) -> hidden -> outputThis allows the network to represent sequence dependencies beyond a memoryless feed-forward model.
11.3. Backpropagation Through Time
A recurrent network can be unfolded through time and differentiated as a deeper computational graph. Backpropagation through time accumulates gradients across temporal steps.
Long sequences can produce vanishing or exploding gradients, making long-range dependency learning difficult for simple recurrent units.
11.4. LSTM, GRU, Attention, and Transformers
LSTM/GRU, attention, and Transformer-based sequence modeling are developed further in Unit 11.
11.5. LSTM and GRU
Gated recurrent networks control state updates with learned gates, improving optimization of longer sequences compared with simple RNNs. They were major sequence-modeling tools before Transformers and remain relevant in streaming and resource-constrained scenarios.
11.6. Gradient Flow Through Time and Streaming Inference
A recurrent layer h_t = f(W_x x_t + W_h h_(t-1) + b) has long-range derivatives involving products of successive Jacobians. Their norms may decay or grow with sequence length. Truncated backpropagation through time limits graph size by cutting derivatives across predetermined boundaries, at the cost of ignoring some long-range gradient contributions. LSTM and GRU gates assist information retention but do not eliminate all long-dependency difficulties.
The training sequence boundary and the inference-state lifecycle must be defined independently. Accidentally carrying a hidden state between different people or device sessions can leak information across samples. Event timestamps, reordered inputs, missing observations, and state-reset rules are part of a deployable recurrent model's specification.
Unit 12: Associative, Energy-Based, and Radial Networks
Model families differ in memory mechanisms, connectivity, learning objectives, and representation capacity.
12.1. Hopfield Network
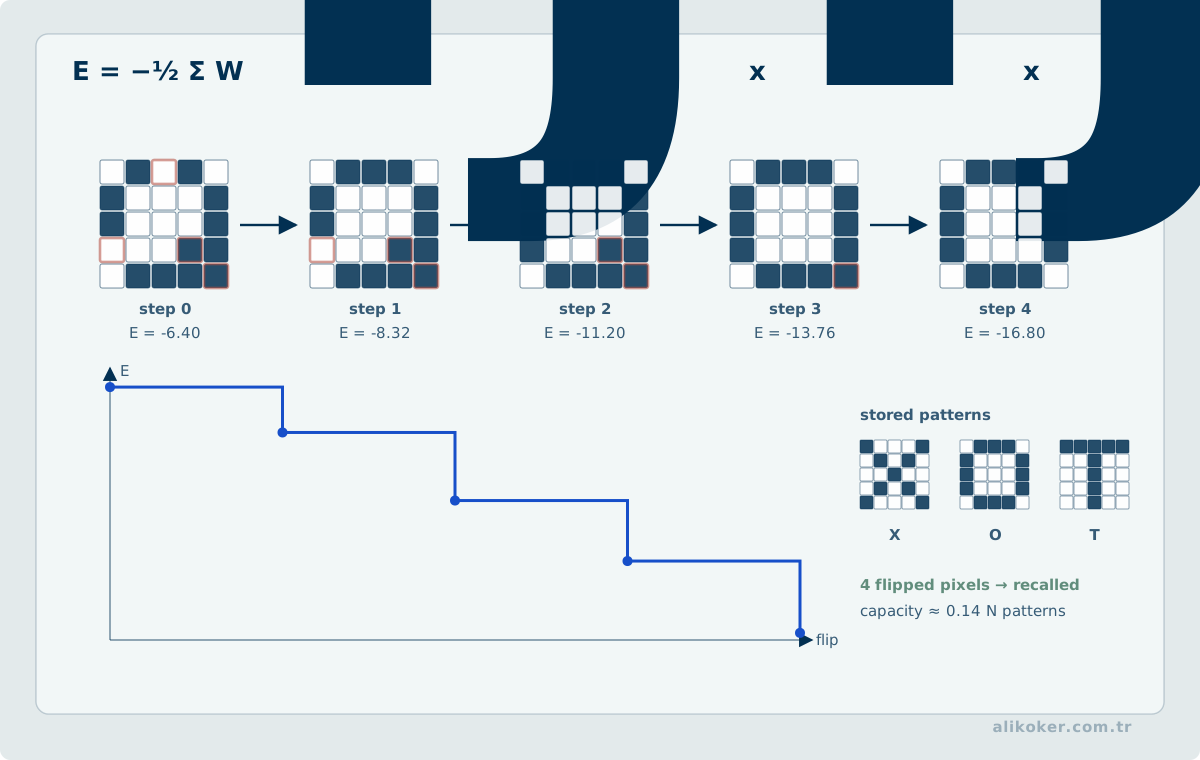
A Hopfield network is a recurrent associative-memory model with an energy function under the standard symmetric-weight formulation. Updating units reduces or preserves energy until an attractor/local minimum is reached.
Stored patterns are not retrieved as an exact database lookup; capacity and spurious attractors limit behavior.
12.2. Counterpropagation
Counterpropagation combines competitive representation with supervised association, historically linking Kohonen-style clustering and Grossberg-style output learning.
12.3. Cognitron and Neocognitron
Fukushima's neocognitron introduced hierarchical local receptive fields and shift-tolerant feature extraction, making it an important conceptual predecessor of convolutional neural networks.
12.4. Self-Organizing Map
A SOM maps high-dimensional samples to a usually low-dimensional grid. The winner and its neighborhood are moved toward an input, preserving topology approximately:
w_i <- w_i + alpha h_ci (x - w_i)It is useful for visualization and exploratory clustering, not as a probabilistic guarantee of class structure.
12.5. Radial-basis-function Networks
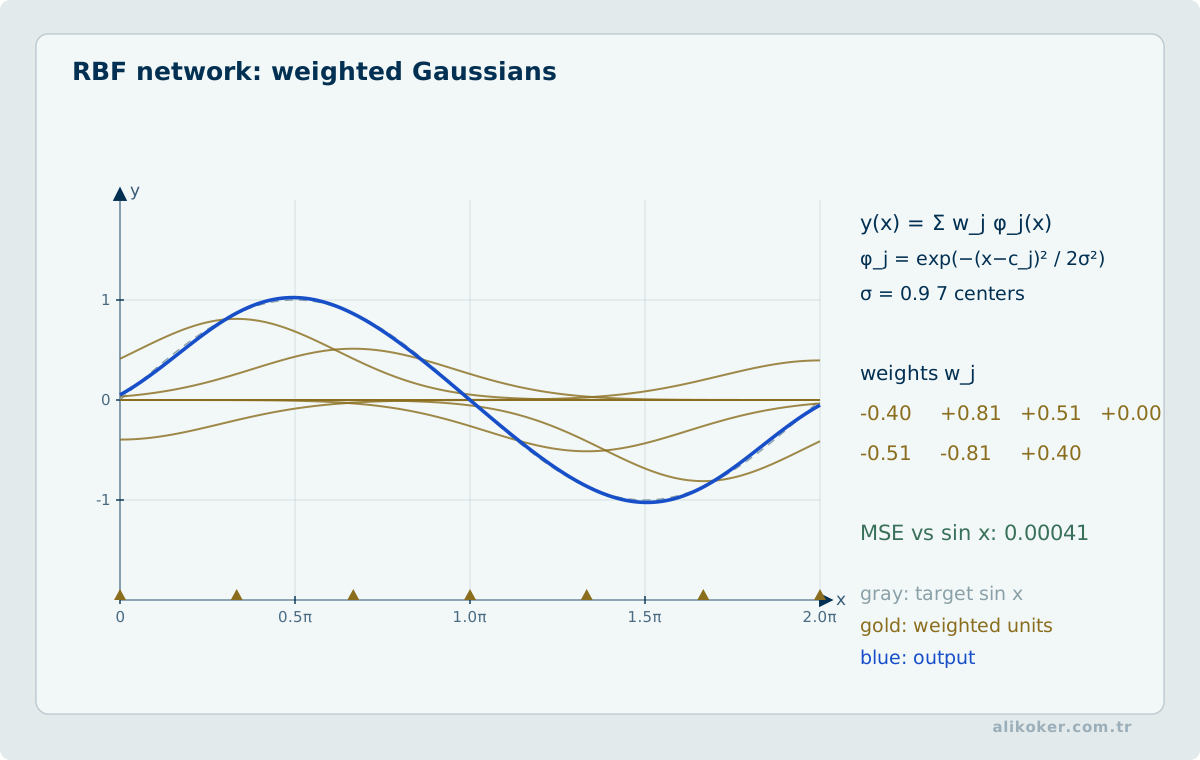
RBF networks use localized basis functions, commonly Gaussian-like responses around centers:
phi_j(x) = exp(-||x-c_j||^2 / (2 sigma_j^2))A linear output combines these features. Center and width selection determine behavior.
12.6. Probabilistic Neural Networks
PNN-style models estimate class likelihood/density from examples with kernel-like functions. They can train quickly but inference/storage grow with retained examples.
12.7. Boltzmann Machines
Boltzmann machines are stochastic energy-based networks. Restricted Boltzmann Machines simplify connectivity to enable more practical learning and were important in the history of deep generative pretraining.
Unit 13: Convolutional Networks and Visual Representation
13.1. Convolutional Neural Networks
CNNs exploit local connectivity and shared kernels:
feature_map = convolution(input, kernel)This inductive bias is efficient for spatially local patterns. Modern CNNs use many architectural refinements, but convolution, nonlinear activation and hierarchical features remain the core idea.
Layer count alone is a poor estimate of neural-network size. A conventional 3×3 convolution with eight input channels and sixteen output channels has 3×3×8×16=1,152 weights, plus sixteen optional biases. Its spatial operation count, however, grows with output height and width. Parameter memory and computational cost are therefore distinct quantities. Depthwise-separable convolution can reduce arithmetic work, but observed execution time also depends on memory traffic, kernel launch overhead, and hardware support.
13.2. Convolution Shapes, Weight Sharing, and Computational Cost
For input shape H×W×C_in, a k_h×k_w kernel, stride s, padding p, unit dilation, and C_out output channels, output height is floor((H+2p-k_h)/s)+1, with an analogous width formula. With biases the parameter count is (k_h*k_w*C_in + 1)*C_out, independent of the number of image locations. A 32×32×3 image passed through a 3×3 convolution of stride one, padding one, and 16 output channels produces 32×32×16 features and (27+1)*16 = 448 trainable parameters.
Local receptive fields and kernel sharing encode a spatial inductive bias rather than guaranteed invariance to all transformations. Padding, data augmentation, effective receptive field, sampling frequency, and the localization properties of labels require task-specific validation. Image-classification performance cannot simply be assumed to carry over to small-object detection or dense segmentation.
13.3. Feature Transfer and Layer Adaptation
A pretrained visual representation can be adapted to a new dataset in two distinct ways. In feature extraction, backbone weights remain frozen while the task head is trained. In fine-tuning, selected backbone layers are also updated using target-domain data. For a small labeled dataset, training the head first and then selectively unfreezing upper layers with a lower learning rate may reduce overfitting; it is not inherently superior for every task.
Input color space, channel normalization, and resolution should be compatible with the assumptions of pretraining. Augmentation must preserve the target label: random rotations or spatial transformations may invalidate labels when orientation or location carries meaning. The unfreezing schedule is assessed through learning curves and an independent validation split.
13.4. Output Spaces of Visual Tasks
Classification assigns one or more labels to an image. Object detection produces labels and bounding boxes. Semantic segmentation assigns a class to each pixel without distinguishing instances of the same class. Instance segmentation provides separate masks for individual objects. Panoptic segmentation combines countable object instances and background regions into one consistent pixel labeling.
A classification loss alone is insufficient for object detection. Detection combines class and localization objectives; segmentation uses pixel-level and potentially region-overlap objectives. With small foreground areas or sparse targets, pixel accuracy can be misleading because background pixels dominate. Class weighting, sampling, and loss selection must be evaluated against the actual label distribution.
13.5. Evaluation of Detection and Segmentation
The intersection-over-union of two regions is IoU = |A ∩ B| / |A ∪ B|. Another overlap measure for segmentation is 2|A ∩ B| / (|A| + |B|). Both require a predefined convention when the reference and prediction are empty.
Detection matching uses an IoU threshold together with the predicted class. Precision is the fraction of positive predictions matched to reference objects; recall is the fraction of reference objects found. Average precision summarizes the precision–recall curve over confidence thresholds. When results are averaged across IoU thresholds, the threshold set must be reported. Pixel- or class-level segmentation IoU cannot be substituted for box-level detection performance.
Unit 14: Attention, Transformers, and Self-Supervised Learning
Transformers are not separate from artificial neural networks. Attention, linear projections, normalization, and feed-forward blocks form a trainable neural architecture.
Large language models are therefore large-scale Transformer-based neural networks rather than a replacement for neural networks as a paradigm.
14.1. Attention and Transformer
Attention computes content-dependent weighted combinations. A standard scaled dot-product attention is:
Attention(Q,K,V) = softmax(QK^T / sqrt(d_k)) VA Transformer stacks attention and feed-forward blocks with residual paths and normalization. Positional information is required because pure self-attention does not inherently encode sequence order.
The original Transformer architecture appeared in 2017 and established self-attention as the central sequence-mixing mechanism of the model.
14.2. Self-supervised Representation Learning
Self-supervised methods derive prediction targets from the data itself, allowing large unlabeled corpora to train representations that can later be adapted to downstream tasks.
14.3. Attention Complexity and Architectural Selection
Full self-attention forms an n×n attention matrix per head over n tokens. Beyond its projection layers, computation is approximately O(n²d) and explicit attention weights can require O(n²) memory. Windowed attention, streamed state summaries, blockwise execution, and approximations address this cost by changing the information-access pattern; each brings an accuracy–memory–latency trade-off.
Architecture choice should follow the structure of the problem. CNNs offer local shared processing on regular grids, recurrent networks maintain a compact evolving state, and Transformers flexibly connect sequence elements. Parameter count alone cannot establish superiority without latency and memory measurements on the intended processor.
Unit 15: Generative Learning: Autoencoders, GANs, and Diffusion
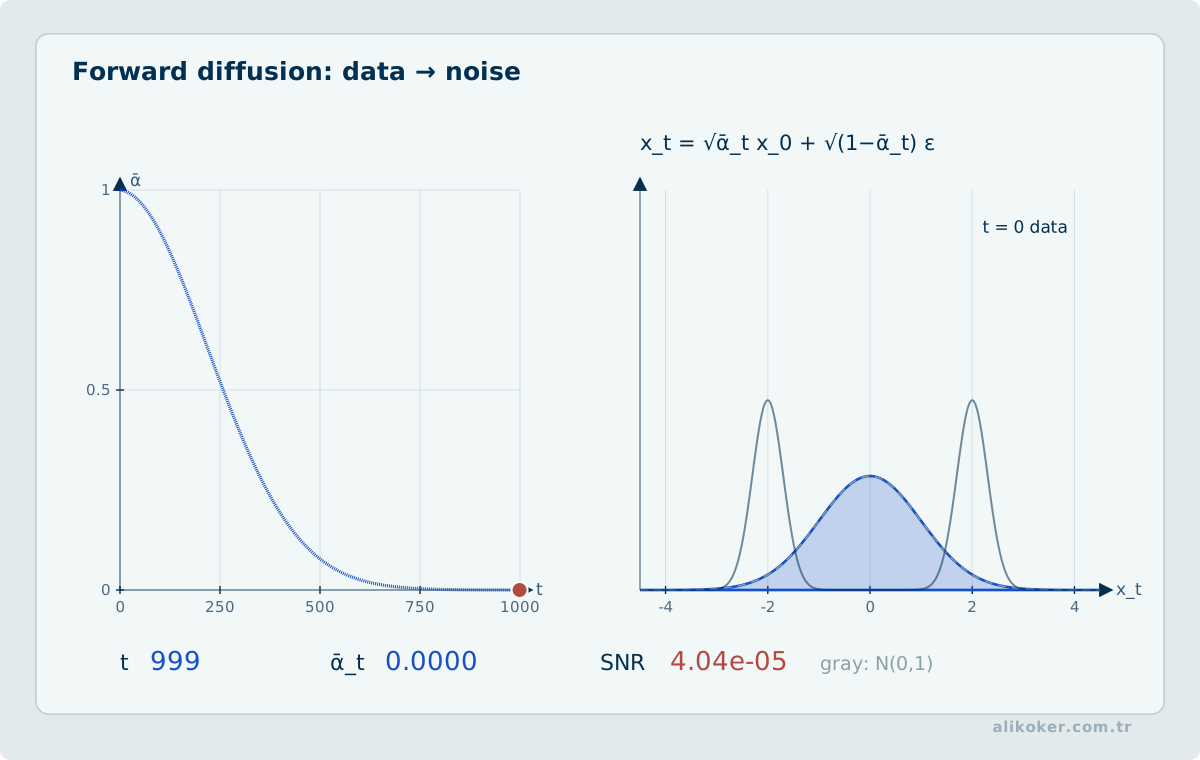
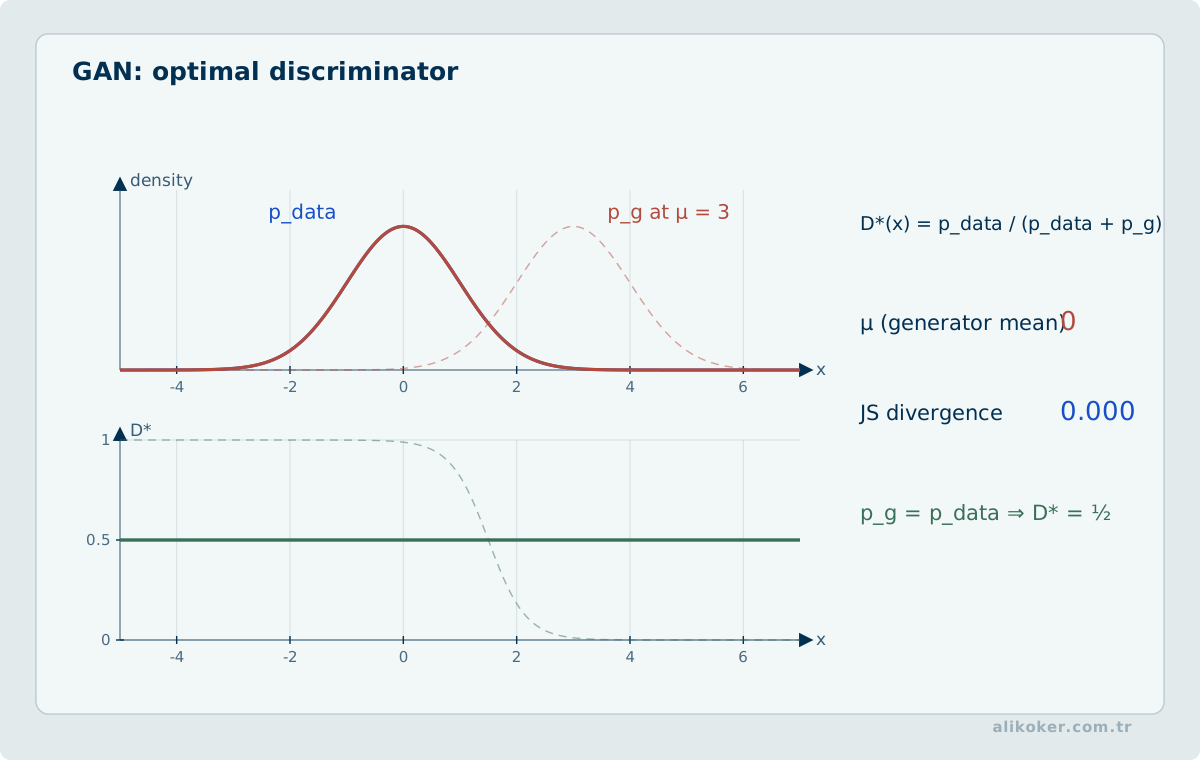
Generative AI includes several neural model families rather than only large language models.
15.1. Variational Autoencoders
A VAE maps observations into a probabilistic latent space and samples from that space.
x
 |
Encoder
 |
q(z|x)
 |
 z
 |
Decoder
 |
x'
Its objective combines reconstruction with regularization of the latent distribution.
15.2. Generative Adversarial Networks
GANs train a generator against a discriminator.
noise -> Generator -> fake sample
                       |
real sample ------------+--> Discriminator
This competitive objective can produce high-quality samples but can also suffer from instability and mode collapse.
15.3. Diffusion Models
Diffusion models define a forward noise process and learn a reverse denoising process.
data -> noise -> noise -> ...
                    |
                    v
              learned reverse
                    |
                  sample
Generation often requires multiple denoising steps.
15.4. Autoregressive Transformers
Language generation proceeds sequentially:
x1 -> x2 -> x3 -> x4 ...These families share the broad label “generative models” while differing in objectives, sampling cost, modalities, and failure modes.
15.5. Autoencoders
An autoencoder learns:
x -> encoder -> z -> decoder -> x_hatwith a reconstruction objective. Bottleneck, sparsity, denoising or variational constraints determine what representation is learned.
15.6. Generative Adversarial Networks
GANs were introduced in 2014. A generator and discriminator play an adversarial optimization game: the generator produces candidate samples while the discriminator provides a learned signal for distinguishing generated samples from training data. Training instability, mode collapse and evaluation difficulty are practical concerns.
15.7. Diffusion Models
Diffusion generative models learn to reverse a progressive noising process and have become a major family for high-dimensional generation. Training spans multiple noise levels, while generation applies a sequence of denoising steps that progressively maps a noisy state toward the learned data distribution.
15.8. Generative Objectives and Measured Sample Quality
A variational autoencoder balances a reconstruction term with a regularizer relating an approximate posterior to its prior; that balance changes the latent representation and sample diversity. GAN training involves alternating updates of a generator and discriminator rather than minimizing a single fixed loss for both; mode collapse describes failure to cover parts of the data distribution. Diffusion models learn reverse transitions across noise levels, often incurring a multi-step sampling cost.
A few visually convincing outputs are not sufficient evidence of quality. Coverage and diversity, reproduction of training examples, sampling latency, energy consumption, and application metrics must be considered on consistent evaluation splits. Producing a close copy of a training sample is not proof of generalization.
Unit 16: Graph Neural Networks, Tensor Networks, and Quantum-Inspired Representations
16.1. Message Passing and Neighborhood Normalization in Graph Networks
For relational data, one layer may be represented as h_v^(l+1) = σ(W_self h_v^l + AGG_{u∈N(v)} W_msg h_u^l). Sum, mean, and learned-weight aggregations behave differently under unequal node degrees. In the four-node graph with edges 1–2, 1–3, 3–4 and scalar initial features (1,0,0,1), self-inclusive neighborhood averaging yields (1+0+0)/3 = 1/3 at node 1 and (0+1+1)/3 = 2/3 at node 3. This nonparametric calculation illustrates relational signal flow rather than constituting a complete classifier.
With many propagation layers, node representations within connected components can become increasingly similar (over-smoothing). Exposing test edges during training can also invalidate link-prediction evaluation. Node-, edge-, and graph-level tasks require different splitting units, baselines, and outcome metrics.
16.2. Tensor Decompositions and quantum-inspired Classical Learning
A dense 4×4×4×4 tensor stores 256 scalars. A tensor-train factorization with internal ranks all equal to 2 has cores of shape 1×4×2, 2×4×2, 2×4×2, and 2×4×1, totaling 8+16+16+8=48 scalars. This storage reduction assumes a sufficiently accurate low-rank approximation; contraction overhead and memory access determine whether runtime improves.
A quantum-inspired neural representation may run entirely on classical hardware while borrowing mathematical ideas from quantum information. It does not require physical qubits, quantum measurement, or demonstrated quantum speedup. Hardware-based variational quantum circuits, by contrast, incur circuit and measurement costs. Claims about either family require matched data-access assumptions, strong classical baselines, and end-to-end resource accounting. Physical quantum computation is treated separately in Quantum Computers.
Unit 17: Compression, Software, and Deployment
Production constraints include memory, latency, and energy as well as predictive quality.
Pruning removes low-value parameters or structures.
Distillation transfers useful behavior from a larger teacher to a smaller student.
Quantization reduces numeric precision.
Model
 |
 +--> pruning
 +--> distillation
 +--> quantization
 |
 v
deployment trade-off
The techniques can be combined but are conceptually different.
Very low-bit research such as 1-bit/1.58-bit architectures should not be confused with ordinary post-training quantization of arbitrary models.
Compression should be measured across quality, latency, throughput, memory, energy, and hardware support.
17.1. Weight Compression Through Tensor Decomposition
The weights of a fully connected layer form a matrix, whereas a convolutional layer is commonly represented by a four-way tensor with output-channel, input-channel and kernel dimensions. Instead of storing this object as one dense parameter array, CP or Tucker decompositions can express it through smaller factors. Tucker decomposition combines a core tensor with lower-dimensional factor matrices along each mode; separate rank choices control approximation capacity across modes. CP decomposition uses a sum of rank-one tensors.
A low-rank representation may reduce parameter count, but theoretical compression does not imply proportional runtime speedup. Kernel launch overhead, intermediate buffers, memory traffic and available hardware primitives influence the total latency of a sequence of smaller convolutions. Fine-tuning after decomposition may be needed. Compression must be validated by task accuracy and end-to-end resource consumption, not simply by a small Frobenius-norm difference between weights.
Pruning, quantization and low-rank factorization introduce different error mechanisms: pruning removes connections, quantization restricts numerical representation, and factorization reduces the subspace available to the weights. If they are combined, accuracy losses should not be assumed to add linearly; the complete model must be measured again after composition.
17.2. From neural-network Simulators to Learning Frameworks
Older neural-network study often used specialized simulators. Modern frameworks represent differentiable computational graphs, automatic differentiation, accelerator execution and distributed training.
The abstraction changed, but the same engineering questions remain: define the data contract, loss, model, optimization, evaluation and deployment constraints explicitly.
17.3. Four Separate Outcomes for Compressed Models
Pruning, low-rank approximation, quantization, and distillation are distinct interventions. After a change, report (1) storage footprint, (2) actual peak memory use, (3) end-to-end latency or energy on the target hardware, and (4) task quality. A low-rank factorization can reduce nominal arithmetic but lose speed through many small kernels or intermediate data copies. Quantization requires measured weight and activation ranges, calibration data, and overflow behavior.
Report quality differences on the same held-out data with experimental variability, not only a headline metric. Latency figures without warm-up policy, batch size, input length, and CPU/GPU environment do not allow meaningful comparison.
17.4. End-to-end Latency in Visual Inference Pipelines
Live image processing extends beyond the network forward pass: T_total = T_capture + T_preprocess + T_transfer + T_model + T_postprocess + T_render. Data transfers, box suppression, mask resizing, and rendering can exceed model computation time. If stages overlap, this sum is a sequential per-frame accounting model; pipeline throughput must be measured separately.
Processed frames per second measure throughput, not the latency of an individual frame. Queue growth, dropped-frame ratio, p95/p99 latency, input resolution, and batch size must be recorded together. The benefit of quantization or pruning is validated against end-to-end results under the same input and quality constraints.
Unit 18: System Identification, Time Series, and Neuroevolution
Neural networks are not limited to classification or static regression. They can also learn dynamical behavior from past system inputs and outputs.
This connects neural networks directly to system identification.
18.1. The system-identification Problem
System identification builds a predictive or explanatory model from observed input-output data.
Conceptually:
u(t) ----> [ unknown system ] ----> y(t)
             |
             v
        observed data
             |
             v
        estimated model
A model can use lagged outputs and inputs:
y_hat(t) = F(
    y(t-1), y(t-2), ...,
    u(t), u(t-1), ...
)
The key distinction is:
static regression:
features from one example -> target for that example

dynamic model:
history / state -> future behavior
That distinction changes both data preparation and validation.
18.2. Begin with a Parametric Baseline
Neural networks do not make classical time-series or linear-system models obsolete.
AR, MA, ARMA/ARIMA, and input-aware ARX-like models can provide fewer parameters, greater interpretability, cheaper fitting, and clearer model-order analysis.
A neural network earns its extra complexity when validated nonlinear or dynamical behavior requires it.
A disciplined experiment can progress through:
naive baseline
     ↓
linear / autoregressive baseline
     ↓
MLP / RBF / recurrent model
     ↓
more complex architecture if justified
18.3. Model Order and Lag Selection
The amount of history supplied to the model is not a cosmetic hyperparameter. It defines capacity and assumptions about available information.
Too little history can miss relevant dynamics.
Too much history can introduce unnecessary parameters, harder optimization, spurious correlations, and greater overfitting risk.
Classical model-order criteria such as AIC or prediction-error-based criteria express the same underlying trade-off between fit and complexity.
18.4. Random Splits Are Dangerous for Time Series
Randomly mixing temporal observations across train and test sets can leak future structure into training.
A chronological split is often safer:
past
|------ train ------|--- validation ---|--- test ---|
                                                   future
Rolling-origin or walk-forward evaluation can measure behavior across time.
A learned representation differs from a manually engineered feature because the model estimates which information to retain from training data; it does not automatically eliminate measurement error. Adjacent windows from the same machine may look like separate dataset rows while sharing nearly identical physical conditions. Generalization to unseen machines requires machine-held-out evaluation, whereas forecasting future behavior requires temporal separation. With class imbalance and changing operating conditions, a single error rate is inadequate. Performance by group and period, probability calibration and safe fallback conditions must be evaluated together.
18.5. Cover the Operating Region
A neural model does not provide a reliable guarantee of extrapolation outside its training region.
System-identification data should cover relevant operating points, transitions, typical loads, and sufficient excitation of the inputs.
A model trained only during steady operation should not be assumed to predict abrupt operating changes correctly.
18.6. One-step Prediction Is Different from free-run Prediction
In one-step prediction, each estimate can receive the real previous output.
In recursive or free-run prediction, the model consumes its own previous estimate.
y_hat(t-1)
    ↓
model
    ↓
y_hat(t)
    ↓
y_hat(t+1)
Errors can therefore accumulate.
A model that is excellent on one-step metrics can drift or become unstable over a longer recursive horizon.
Evaluation must match deployment behavior.
18.7. MLP, RBF, and Recurrent Structures
Different neural families encode different inductive biases.
An MLP can map a fixed lag window through a nonlinear function.
An RBF network can approximate behavior around learned local centers.
A recurrent model carries history through hidden state.
LSTM, GRU, and Transformer sequence models can process longer context, but additional complexity is not automatically useful for smaller identification problems.
Architecture choice should consider dynamics, data volume, latency, stability, and interpretability.
18.8. Residual Analysis Goes Beyond RMSE
Define residual error as:
e(t) = y(t) - y_hat(t)Then ask more than how large it is:
- Is there persistent bias?
- Is a periodic pattern left unexplained?
- Do residuals remain autocorrelated?
- Are residuals still correlated with past inputs?
- Does error rise only in specific operating regimes?
Structured residuals can indicate that the model has not captured all available system information.
18.9. Neuroevolution Is More Than Evolving Weights
Neuroevolution combines evolutionary search with neural-network design.
Evolution can target:
weights
topology
activation / connectivity choices
hyperparameters
learning-rule parameters
It can be useful when the objective is non-differentiable, architecture contains discrete choices, or fitness comes directly from simulation.
The trade-off is potentially large evaluation cost.
18.10. Evolving Topology
Searching weights in a fixed topology is different from evolving the network structure itself.
Approaches such as NEAT combine ideas such as starting from small structures, structural mutation, alignment of differing topologies, and speciation that temporarily protects structural innovations.
This is not a universal replacement for gradient descent. It is most natural when topology is itself part of the search problem or fitness is obtained from an environment/simulator.
18.11. Hybrid Training
Evolutionary and gradient optimization can play complementary roles.
evolutionary search
    ↓
good initialization / topology / hyperparameters
    ↓
gradient-based fine tuning
is one possible design.
Global exploration and local numerical refinement solve different optimization subproblems.
18.12. Reproducible Neuroevolution
A stochastic evolutionary experiment should not report only its best run.
Record:
random seed
population size
selection pressure
mutation / crossover parameters
evaluation budget
fitness definition
independent-run count
mean / median / variance
best-so-far curve
System identification and neuroevolution therefore share one engineering rule:
Complex models are useful only when they beat simpler baselines under correct validation and reproducible experiments.
18.13. Measuring Error Accumulation in Learned Dynamics
In one-step prediction, a network uses the true current observation to compute x̂[k+1] = F(x[k],u[k]). In free-running prediction, it instead uses its own state estimate: x̂[k+1] = F(x̂[k],u[k]). Previous errors then enter future predictions. A low average one-step error does not establish long-horizon accuracy or stability. If predicted velocity is consistently 0.02 m/s too high, straightforward position integration over one hundred 0.1 s steps accumulates 0.2 m of error when other sources are neglected.
Evaluation should separate one-step loss, free-running error, and physical constraint violations. Starting from matched initial conditions, tests can vary load, friction, and supply within defined bounds, reporting deterioration outside the training domain. A neural model may predict dynamics accurately while failing to preserve energy-sign constraints, saturation behavior, or mechanical limits. Any model coupled to a physical controller needs independent validation over its authorized operating region and, when necessary, explicit constraints imposed by a physical model.
18.14. UKF State Estimation versus Neural Parameter Learning
Given a transition model x_t = f(x_(t-1),u_t)+q_t and observation model z_t = h(x_t)+r_t, an unscented Kalman filter propagates selected sigma points through nonlinear mappings. A standard scaled unscented transform uses 2n+1 sigma points for state dimension n; weights and covariance propagation depend on its parameters. A UKF intended to estimate physical state is a different construction from augmenting the state with neural-network weights for sequential parameter learning. The latter increases dimension, covariance costs, and observability requirements.
RLS applies to appropriately linearly parameterized models under excitation assumptions, while the UKF models nonlinear state or measurement transformations. Validation should use physical operating ranges and time blocks rather than arbitrary row splits. Report both one-step residuals and accumulated errors under free-running predictions.
Unit 19: Applications, Model Selection, and Operational Limits
19.1. APPLICATION AREAS
Because a neural network can extract regularities from examples, its application space is not confined to one engineering discipline. Before deciding to use a network, the representation of the input, the measurable target, the cost of errors, and the availability of representative data should be defined.
The main application areas of neural networks can be grouped by engineering context as follows:
- Digital forensics and cybersecurity: digital forensics, cybersecurity, image and data comparison, and pattern-oriented forensic analysis.
- Imaging and biometrics: image processing, handwriting recognition, fingerprint recognition, licence-plate recognition, and face matching.
- Audio, language, and signals: speech recognition, word recognition, language translation, electrical-signal recognition, and signal processing.
- Biomedical and engineering analysis: biomedicine, durability analysis, system modelling, quality control, and cost analysis.
- Control, robotics, and transportation: control systems, robotics, automated vehicle control, autopilot applications, path following, and flight simulation.
- Forecasting and production: weather forecasting, finance, and manufacturing-process control.
These tasks do not use one interchangeable architecture. Images, time series, text, and tabular data require different preprocessing, loss functions, validation strategies, and computational budgets.
19.2. ADVANTAGES AND LIMITATIONS
The central strength of a neural network is its ability to learn a parameterized mapping from examples without requiring a complete hand-written rule set. The same property creates a central risk: model quality can depend heavily on the data distribution, training procedure, validation discipline, and operating conditions. The main advantages and limitations follow from this dependence on learned parameters and data.
19.2.1. Advantages
- A trained network can generalize to unseen samples drawn from a sufficiently similar distribution.
- Nonlinear units allow it to represent relationships that linear models cannot capture directly.
- Distributed representations mean that, in some architectures, loss of one unit or connection does not imply loss of all learned information.
- It can learn decision boundaries from examples and respond to related cases that were not explicitly programmed.
- Its error profile can differ from that of conventional methods, which can be valuable in hybrid or redundant designs.
- Information can be distributed across many parameters instead of being stored in a single cell or rule.
- High accuracy is possible when training data is sufficiently large, clean, diverse, and representative of the problem space.
- Architectures can be trained to remain useful under missing or noisy inputs, although this robustness is not automatic.
- An explicit closed-form physical model is not always required; an approximate mapping can be learned from observations.
- Redundancy and distributed representation can improve fault tolerance in selected architectures.
- Learned feature representations are useful in perception tasks.
- Neural networks can operate directly as pattern-recognition systems.
- They can achieve high accuracy in classification when the data and evaluation protocol support that claim.
- Unsupervised and self-supervised methods can discover structure without a target label for every sample.
- With suitable hardware and batching, inference can be faster than some conventional processing pipelines.
- The same broad optimization machinery can be reused across different data types and model families.
19.2.2. Limitations
- There is no universal stability analysis for arbitrary neural networks comparable to classical results for specific control systems; formal guarantees apply only under defined architectures and assumptions.
- The reason for a single prediction can be difficult to trace in high-dimensional models, so interpretability must be designed and evaluated separately.
- Images, audio, text, and sensor observations must be converted into consistent numerical representations; errors in digitization or preprocessing propagate into the model.
- Hyperparameters such as depth, learning rate, regularization, and initialization may behave differently on another domain or dataset.
- No single rule determines when every training process should stop; validation loss, early stopping, convergence criteria, and resource budgets are typically combined.
- Training large models, and sometimes running them, can require substantial parallel computation, memory bandwidth, or accelerator hardware.
- Large and representative datasets may be a dominant requirement.
- Distribution shift can invalidate performance measured on development data.
- Adversarial inputs, data/model bias, calibration, and uncertainty require explicit treatment.
- For large models, memory bandwidth and energy consumption can become system limits in addition to compute.
19.3. From Learning Models to Production Inference
Model quality alone does not define production performance for AI systems. Batch size, memory bandwidth, placement of model state, activations and KV cache, prefill and decode phases, queueing, parallelism, and communication costs jointly determine the latency-throughput curve. A model-level optimization therefore needs to be validated against end-to-end service latency and output per unit of resource.
- Keep training metrics separate from production-serving metrics.
- Measure batching gains together with queue delay and memory consumption.
- Report compression or quantization together with both speedup and quality loss.
19.4. Model Selection Across Domains
Model-evaluation criteria vary by application domain. Accuracy should be considered together with latency, error cost, calibration, distribution shift, resource budget, and reliability. Application areas, strengths, and limitations should be considered together with the foundational framework introduced earlier.
19.5. Application Selection
Before using an Artificial Neural Network, determine whether the problem genuinely benefits from a learning-based solution. Nonlinear relationships, high-dimensional data, many examples, hard-to-write rules, and complex patterns can justify ANN use; a simple problem with a clear and verified algorithmic solution may not.
19.6. Industrial Systems
In industrial systems, accuracy is only one requirement. Latency, deterministic behavior, distribution drift, and safe behavior under failure can be equally important.
19.7. Financial Systems
Historical performance does not guarantee future performance. Regime change, data leakage, and selection bias are critical evaluation risks.
19.8. Military and Security Systems
False-positive and false-negative costs are usually asymmetric. Evaluation should reflect operational conditions, distribution shift, and adversarial effects.
19.9. Healthcare Systems
Clinical use requires more than accuracy. Data-representation fairness, calibration, external validation, and human oversight must be considered together.
19.10. Data Type and Model Choice
Image, audio, text, and time-series data have different structural properties. A model family should not be chosen mechanically by modality; representation structure, latency, memory, compute budget, error cost, and validation requirements should be evaluated together.
The best engineering model is not the largest model. It is the model that meets the requirement with sufficient reliability at the lowest total cost.
19.11. Outliers and Distribution Shift in Learning
Robust statistics asks how much an estimator degrades under small departures from an idealized model. In neural-network experiments, the median and MAD can reveal whether label noise or extreme samples are driving the error distribution; influence functions and breakdown points provide a more formal view of how the chosen estimator reacts as that contamination increases. In heavy-tailed or contaminated data, decisions based only on the mean and standard deviation can be misleading.
- Examine sensitivity of the loss function to outlying samples.
- Track train/test distribution shift through calibration as well as accuracy.
- Compare robust scaling with classical standardization on contaminated data.
19.12. Evaluate Domain Applications Through Operational Decisions
Suitability for diagnosis, industrial quality monitoring, or security detection is not determined by accuracy alone. Class prevalence, false-alarm workload, missed-event cost, human oversight, data provenance, and distribution shift determine the operational decision threshold. Two models with similar ROC-AUC can create very different workloads if their probability calibration differs.
For learned physical dynamics, agreement between predicted and observed outputs does not by itself establish safe control behavior. Physical constraints, uncertainty bands, out-of-distribution states, and fallback rules must be specified. Neural-network benefits should be tested against appropriate statistical, linear, or physics-based alternatives.
Unit 20: Experimental Design, Measurement, Uncertainty, and Scientific Evidence
An experiment begins by fixing the comparison hypothesis and primary metric. Partition data so that dependence across people, devices, or time does not leak into evaluation, and record random seeds and model-selection rules. Results used for hyperparameter selection must not be presented as final test performance. Repeated trials and analysis of poorly performing subgroups reveal how much evidence a single high score actually provides.
20.1. Experimental Design, Uncertainty, and Distribution Shift
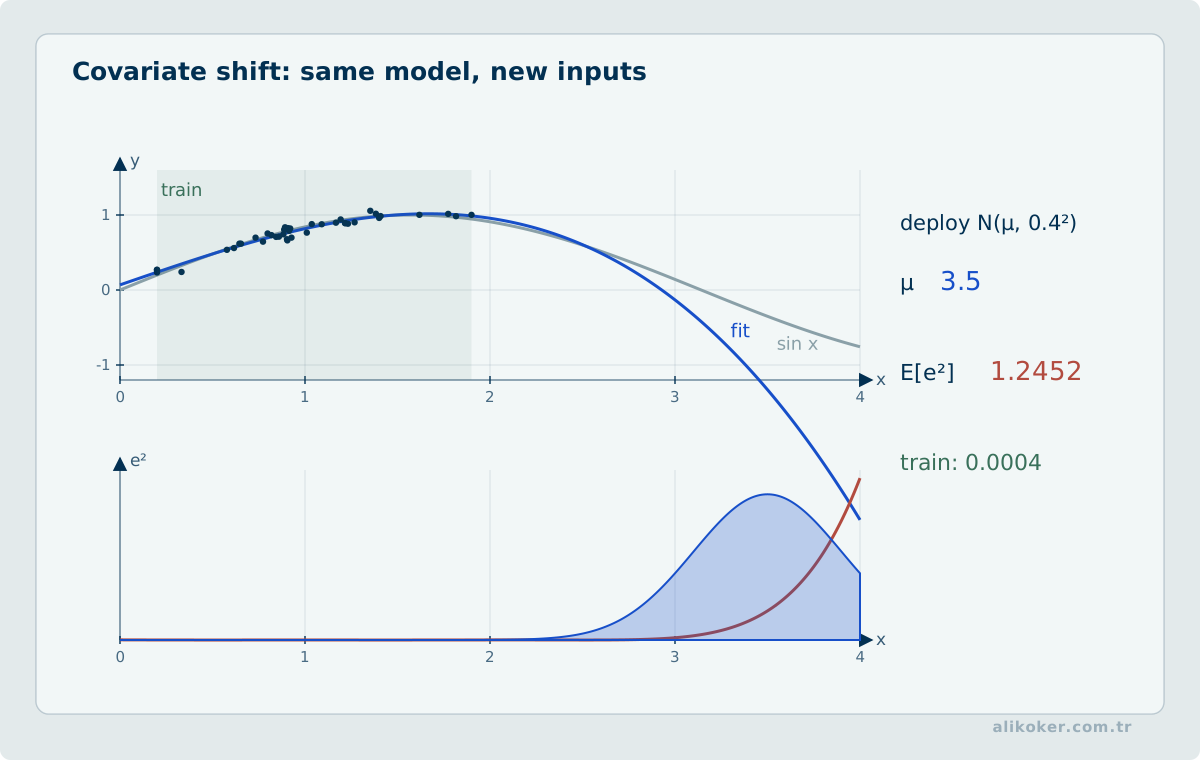
A falling training loss does not imply reliable real-world behavior. Training, validation, and test data must be separated carefully so that samples from the same person, device, session, or time series do not leak across splits.
Classification should be evaluated with metrics appropriate to class balance, while probabilistic outputs should also be checked for calibration. A system that can express uncertainty is often safer than one that assigns high confidence to every input.
Production distributions drift. Sensors, user behavior, devices, and collection policies change over time, so evaluation should include slice analysis, threshold behavior, drift monitoring, and explicit retraining criteria rather than a single offline score.
20.2. Connecting Model Output to Evidence
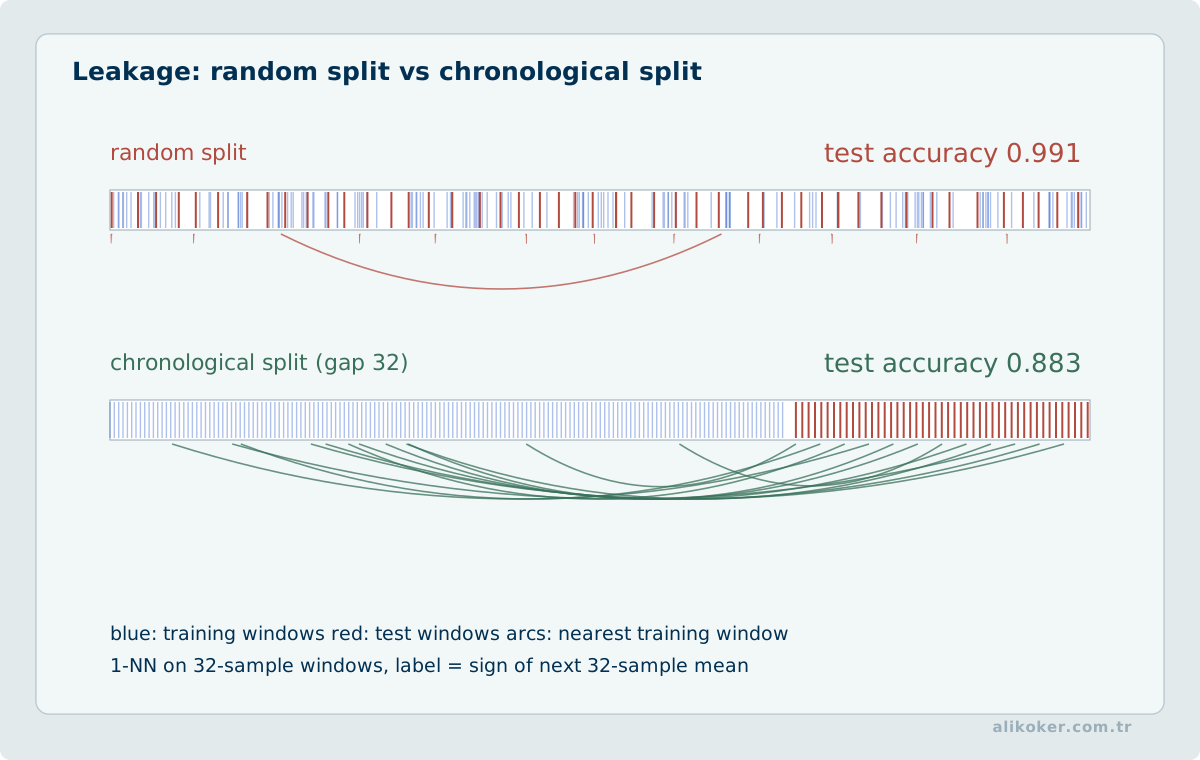
A model should not be judged by a single accuracy figure. Results are reproducible only when the data source, split strategy, class distribution, and evaluation metrics are explicit. Leakage across people, devices, sessions, or time windows can make image, audio, and time-series evaluations overly optimistic.
Decision thresholds depend on the operating context. When false positives and false negatives have different costs, there is no universally optimal threshold. Confusion matrices, class-wise precision/recall, calibration, and error slices should be considered together.
Deployment scope should be stated explicitly: which distribution was validated, which inputs are out of scope, how uncertainty is handled, and when human review is required. These conditions define how much confidence can be placed in a prediction.
20.3. Current Engineering Principles
For production neural systems:
- separate train/validation/test correctly,
- prevent data leakage,
- version preprocessing together with the model,
- measure latency and memory on target hardware,
- monitor distribution shift,
- calibrate or threshold outputs according to risk,
- retain reproducible model/data metadata,
- treat external validation as distinct from training success.
Historical neural models are valuable not because every one remains state of the art, but because they expose the core ideas of linear separability, error-driven learning, prototypes, competition, recurrence, and representation that later architectures build upon.
Reliability boundaries also include adversarial inputs, data poisoning, privacy constraints, and the role of human oversight in high-risk use. Progress is therefore better evaluated as an algorithm + data + hardware + validation + operations problem than as a catalogue of newly named architectures.
20.4. Experiment Tracking, Ablation, and Production Observation
Recording only the final metric does not record an experiment. Reproducible comparison requires the baseline, data version, preprocessing, model configuration, hyperparameters, evaluation set, and metric definition to remain traceable together.
baseline
→ one controlled change
→ same evaluation protocol
→ result
→ interpretation
This produces stronger evidence than changing many components at once and then being unable to identify which change produced the gain.
20.4.1. Hyperparameter Search and Evaluation Discipline
Grid search, random search, and probabilistic optimization generate different candidate configurations. A sophisticated search algorithm does not repair a weak evaluation protocol. Hyperparameter selection should use validation data; the final test set should not become part of the repeated selection loop.
When many experiments are run, simply choosing the highest score can also be misleading. Runs should use comparable splits, preprocessing, and metrics, and sources of variation should be inspected where they matter.
20.4.2. Ablation Studies
An ablation study removes a model component or feature/data group and compares the result under a controlled protocol.
Model A
Model A - component X
Model A - feature group Y
Model A - augmentation Z
Ablation is not a replacement for ordinary software testing. A test can ask whether required behavior holds; ablation asks how much a component contributes to observed performance. The two forms of evidence answer different questions.
20.4.3. Error Slices and Explainability
A single average score can hide where a model fails. Error rates can be inspected across meaningful slices such as class, time, source, device, or signal quality. Residual plots and systematic residual patterns serve a similar purpose in regression, while confusion matrices and class-specific measures help in classification.
Explainability methods such as SHAP can help inspect feature contributions to a model decision, but feature attribution is not causal proof. The explanation method itself is another analytical layer with assumptions and approximations.
20.4.4. Production Observation and Drift
Success on a validation set does not guarantee unchanged production behavior. Input distributions, class proportions, sensors, or client behavior can drift. System behavior such as latency, memory use, and failure rate also remains part of model quality.
offline evaluation
→ controlled rollout
→ data and model observation
→ drift / error-slice analysis
→ retrain or rollback decision
Online or incremental learning may adapt more quickly, but it introduces risks from bad labels, abrupt distribution change, irreversible updates, backward-compatibility failures, and catastrophic forgetting. Update criteria, data-quality checks, model versioning, and rollback must therefore be explicit.
Configuration and release management are developed further in Software Engineering, while evidence and validation scope are covered in Software Test Engineering.
20.5. Related Topics
The philosophical and theoretical dimensions of artificial intelligence beyond network modeling are addressed in Artificial Intelligence: Philosophy, Theory and Practice.
20.6. Calibration, Thresholds, and Error Slices
Ranking quality and probability quality are different. A classifier can have good AUC while being poorly calibrated; a score of 0.9 may not correspond to an event rate near 90 percent. Calibration curves and Brier score help expose the difference.
Decision thresholds should follow business costs and operating constraints rather than defaulting to 0.5.
Aggregate metrics can hide systematic failures. Errors should be sliced by meaningful factors such as device, source, noise level, region, or time, with uncertainty reported for small samples.
20.7. Building a Reproducible Learning Experiment
Architecture alone does not define an experiment. Dataset version, normalization, augmentation, random seed, optimizer, learning rate, batch size, early stopping, and model-selection criteria should be recorded with the result.
Train/validation/test roles should be fixed before model selection. Repeatedly tuning against the test set removes its independence. On small datasets, repeated cross-validation or confidence intervals can be more informative than one split.
Failure cases are also results. Error slices by class, source, noise, device, lighting, or another relevant dimension can reveal weaknesses hidden by aggregate metrics.
20.8. Separate the Learning Result from the Model
In a neural-network problem, architecture, training objective, and evaluation metric belong to different layers. An activation function introduces the layer's nonlinearity, a loss function defines what training attempts to minimise, and a metric reports performance. A classifier can, for example, be trained with cross-entropy while accuracy is reported separately.
Backpropagation is not a prediction method; it is a way to compute gradients by repeated application of the chain rule. The optimiser determines how those gradients change the parameters. A learning rate that is too large can create unstable updates, while one that is too small can make progress impractically slow.
Training, validation, and test sets have different roles. Training data changes model parameters. Validation data supports model and hyperparameter selection. A test set estimates generalisation only to the extent that it remains outside that selection loop. Repeatedly changing a design after inspecting test results effectively turns the test set into another validation set.
Overfitting is not merely low training error; it is the gap between training behaviour and performance on unseen data. Regularisation, data augmentation, early stopping, and appropriate model capacity can reduce that gap. High training error can instead indicate under-capacity, optimisation failure, poor data, or unsuitable feature scaling.
A high classifier score is not automatically a calibrated probability. If cases reported near 0.9 are correct only half the time, the model may rank examples well and still be poorly calibrated. Accuracy, calibration, and the decision threshold should therefore be evaluated separately, especially with imbalanced classes.
20.9. Matched-data and matched-budget Benchmarking
Start an experiment with a single falsifiable hypothesis, such as whether Levenberg–Marquardt reaches a smaller residual within a specified budget on a tractable nonlinear least-squares problem. Use identical train/validation/test splits, preprocessing and primary metrics. Repeat stochastic runs with recorded independent seeds. Optimizer comparisons should account for wall-clock time, memory, and loss or Jacobian evaluations, not merely epochs.
Do not publish the single best run as the expected outcome: report central tendency, variability, failed runs, meaningful data slices, and uncertainty intervals. Giving one method a much larger hyperparameter search budget compares resources rather than algorithms. For efficiency claims, preprocessing, data transfers, and inference must also be included in end-to-end costs.
20.10. Evaluation Protocols That Prevent Data Leakage
Using the same test set for model selection, threshold tuning, and final evaluation produces optimistic estimates. Sample-level splitting may be insufficient: records from the same speaker, session, device, or data source can leak across splits. The grouping unit must reflect the intended generalization target.
Accuracy or F1 alone cannot characterize class imbalance or calibration. Confusion matrices, per-class precision and recall, calibration measures where relevant, and a prespecified operating threshold should be reported together. Model comparisons require identical partitions, preprocessing boundaries, and computational budgets.
References
- Alex Krizhevsky; Ilya Sutskever; Geoffrey E. Hinton. (2012). ImageNet Classification with Deep Convolutional Neural Networks. Advances in Neural Information Processing Systems 25. NeurIPS
- Ashish Vaswani; Noam Shazeer; Niki Parmar; Jakob Uszkoreit; Llion Jones; Aidan N. Gomez; Łukasz Kaiser; Illia Polosukhin. (2017). Attention Is All You Need. Advances in Neural Information Processing Systems 30. NeurIPS
- Brendan Gregg. Systems Performance: Enterprise and the Cloud. Pearson Education, 2014.
- Chris Fregly. AI Systems Performance Engineering. O’Reilly Media, 2025.
- David E. Rumelhart; Geoffrey E. Hinton; Ronald J. Williams. (1986). Learning representations by back-propagating errors. Nature, 323, 533-536. doi:10.1038/323533a0
- David H. Ackley; Geoffrey E. Hinton; Terrence J. Sejnowski. (1985). A Learning Algorithm for Boltzmann Machines. Cognitive Science, 9(1), 147-169. doi:10.1207/s15516709cog0901_7
- Frank Rosenblatt. (1958). The Perceptron: A Probabilistic Model for Information Storage and Organization in the Brain. Psychological Review, 65(6), 386-408. doi:10.1037/h0042519
- Hinton, G.; Vinyals, O.; Dean, J. “Distilling the Knowledge in a Neural Network.” 2015. https://arxiv.org/abs/1503.02531
- Ho, J.; Jain, A.; Abbeel, P. “Denoising Diffusion Probabilistic Models.” NeurIPS, 2020. https://arxiv.org/abs/2006.11239
- John J. Hopfield. (1982). Neural networks and physical systems with emergent collective computational abilities. Proceedings of the National Academy of Sciences, 79(8), 2554-2558. doi:10.1073/pnas.79.8.2554
- Kingma, D. P.; Welling, M. “Auto-Encoding Variational Bayes.” 2013. https://arxiv.org/abs/1312.6114
- Mor Harchol-Balter. Performance Modeling and Design of Computer Systems: Queueing Theory in Action. Cambridge University Press, 2013.
- Narendra, Kumpati S.; Parthasarathy, Kannan. “Identification and Control of Dynamical Systems Using Neural Networks.” IEEE Transactions on Neural Networks, 1(1), 4–27, 1990. DOI: https://doi.org/10.1109/72.80202
- Naveenkumar, P.; Sharma, V.; Devarajan, G.; Abdullah, A.; Elngar, A. A. (eds.). Handbook of AI-Based Mechatronics Systems and Smart Solutions in Industrial Automation. CRC Press, 2026. DOI: https://doi.org/10.1201/9781032615790.
- Paul J. Werbos. (1974). Beyond Regression: New Tools for Prediction and Analysis in the Behavioral Sciences. Harvard University doctoral dissertation.
- Peter J. Huber; Elvezio M. Ronchetti. Robust Statistics. 2nd ed. Wiley, 2009.
- Sepp Hochreiter; Jürgen Schmidhuber. (1997). Long Short-Term Memory. Neural Computation, 9(8), 1735-1780. doi:10.1162/neco.1997.9.8.1735
- Stanley, Kenneth O.; Miikkulainen, Risto. “Evolving Neural Networks through Augmenting Topologies.” Evolutionary Computation, 10(2), 99–127, 2002. DOI: https://doi.org/10.1162/106365602320169811
- Teuvo Kohonen. (1982). Self-organized formation of topologically correct feature maps. Biological Cybernetics, 43, 59-69. doi:10.1007/BF00337288
- Walter W. Piegorsch, Richard A. Levine, Hao Helen Zhang, Thomas C. M. Lee (eds.). Computational Statistics in Data Science. Wiley, 2022. ISBN 9781119561071.
- Warren S. McCulloch; Walter Pitts. (1943). A Logical Calculus of the Ideas Immanent in Nervous Activity. Bulletin of Mathematical Biophysics, 5, 115-133. doi:10.1007/BF02478259
- Yann LeCun; Léon Bottou; Yoshua Bengio; Patrick Haffner. (1998). Gradient-Based Learning Applied to Document Recognition. Proceedings of the IEEE, 86(11), 2278-2324. doi:10.1109/5.726791
- Chunwei Zhang, Tianpeng Li, Ying Dai, Li Sun, and Ardashir Mohammadzadeh. Practical Neural Networks in Python and MATLAB. Springer Nature, 2026. DOI: https://doi.org/10.1007/978-3-032-14746-2.
- Cybellium Ltd. Mastering Neural Networks. Cybellium, undated electronic edition (supplied copy).
- Moolchand Sharma, Nebojsa Bacanin, and Tarik Ahmed Rashid (eds.). Quantum-Inspired Neural Networks: Future Perspectives and Challenges. CRC Press, DOI: https://doi.org/10.1201/9781003682950 (supplied copyright page ©2027).