


Retrieval-Augmented Generation (RAG)


A production-oriented RAG course covering retrieval, hybrid search, reranking, big-data ingestion, private-data chat, Graph RAG, temporal relationship analysis, security, evaluation, and on-premises architectures.
Retrieval-Augmented Generation (RAG) is a system architecture in which a large language model does not rely only on patterns stored in its parameters. At runtime, the application retrieves relevant evidence from external information sources and places that evidence into the model context. The real value of RAG is not the creation of a chat window. It is the ability to connect an existing website, document archive, database, transcript collection, event store, or relationship graph to generative AI without turning the entire information system into a newly trained model.
This course is the natural continuation of Artificial Intelligence: Philosophy, Theory and Practice, Natural Language Processing, and Large Language Models.
Artificial Intelligence
        |
        v
Natural Language Processing
        |
        v
Large Language Models
        |
        v
Retrieval-Augmented Generation
The AI course covers the broader problem space; NLP covers language representation and processing; the LLM course covers the generative model. This course focuses on the engineering layer that connects models to external information systems.
The central principle is:
useful answer
   =
appropriate model
 + correct evidence
 + correct authorization
 + correct context
 + validated output
A powerful model cannot repair a retrieval system that consistently returns the wrong evidence. Correct retrieval is still unsafe if unauthorized data enters the context window.
Unit 1: Parametric and External Knowledge
A large language model learns distributed patterns in its parameters. This can be viewed as parametric knowledge. It is not a database in which every fact maps cleanly to a document row and source identifier.
RAG adds a separate runtime knowledge path.
                 +--------------------+
                 | model parameters   |
                 | parametric memory  |
                 +---------+----------+
                           |
Query -------------------->| LLM
                           ^
                           |
                 +---------+----------+
                 | retrieved evidence |
                 | external knowledge |
                 +--------------------+
A document can change today without the model weights changing. In a RAG system, the document can be re-indexed and the updated evidence can become available at query time.
The original RAG formulation combined parametric and non-parametric memory. Modern production systems use the term more broadly: lexical search, dense retrieval, reranking, SQL, graph queries, temporal filters, and tool calls can all participate in the retrieval layer.
Unit 2: What RAG Is Not
RAG solves a different problem from fine-tuning, long-context inference, or tool execution.
2.1. Fine-tuning
Fine-tuning modifies model parameters to change behavior or representation. Re-training a model whenever a document changes is usually the wrong architecture for frequently changing knowledge.
knowledge changed
   |
   +--> fine-tuning:
   |      train
   |      new weights
   |      evaluate
   |      redeploy
   |
   +--> RAG:
          reprocess document
          update index
          retrieve on next query
2.2. Long Context
A very large context window does not make retrieval unnecessary. Sending the entire archive with every query increases token cost, latency, authorization complexity, and the risk that relevant evidence is lost in a large context.
Long context and retrieval are complementary. Retrieval narrows the evidence set; long context can preserve more surrounding material for selected sources.
2.3. Tool Use
RAG retrieves information. Tools can perform actions.
RAG:
"What do these records say?"

Tool:
"Run this query."
"Open this file."
"Produce this report."
A production system can combine both.
Unit 3: Turning a Traditional Website into an AI-Aware Website
A website may have years of useful material even if it was never designed around AI. Articles, lecture notes, projects, wiki entries, and technical documents already form a valuable corpus.
The safest first step is not to redesign the site. Build a parallel information pipeline.
Existing Website
   |
   +--> HTML / Markdown
   +--> database content
   +--> wiki
   +--> documents
   |
   v
Content Extraction
   |
   v
Cleaning + Metadata
   |
   v
Chunking
   |
   +--> lexical index
   |
   +--> vector index
   |
   v
RAG API
   |
   v
semantic search / conversational UI
The AI layer becomes a read-oriented knowledge interface above the existing system.
3.1. From Search to Synthesis
Traditional search:
user -> "real-time systems"
     -> matching pages
RAG:
user
  |
  v
"What trade-offs between latency and throughput
are discussed across this site?"
  |
  v
relevant pages + sections + passages
  |
  v
source-grounded synthesis
RAG does not replace search. It uses retrieval as the evidence acquisition stage for generation.
3.2. A Sensible First Production Version
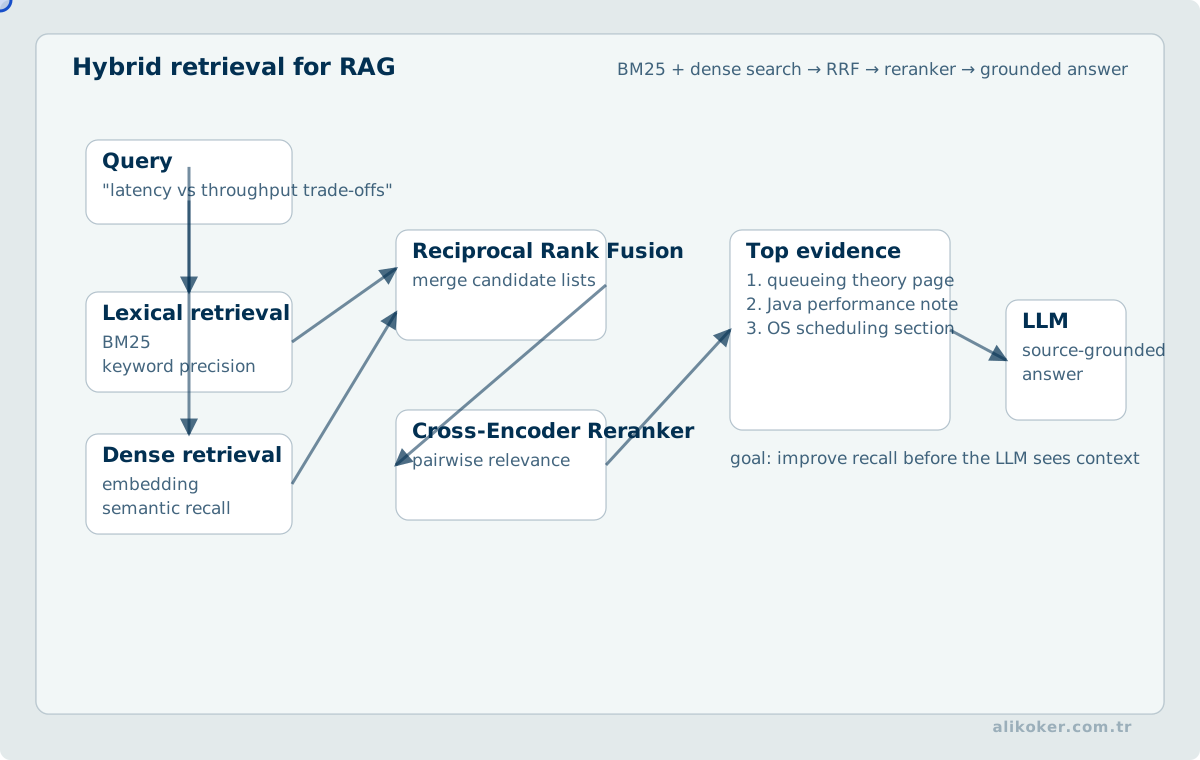
Do not begin with an agent or a complex graph.
Query
  |
  v
BM25 + Dense Search
  |
  v
Reciprocal Rank Fusion
  |
  v
Cross-Encoder Reranker
  |
  v
Top evidence
  |
  v
LLM
  |
  v
Cited answer
A measurable baseline is more valuable than an impressive but opaque pipeline.
Unit 4: The Ingestion Pipeline
RAG quality begins before query time.
Source
  |
  v
Extraction
  |
  v
Normalization
  |
  v
Metadata
  |
  v
Chunking
  |
  v
Embedding / lexical indexing
  |
  v
Versioning
  |
  v
Published index
Sources can include HTML, Markdown, PDF, DOCX, database records, transcripts, technical notes, code, event descriptions, and graph node or edge descriptions.
Different sources should not be forced through one generic splitter.
An ingestion pipeline begins with source identity, access scope, and freshness requirements. Parsing must preserve provenance such as titles, sections, and source locations. Identify repeated versions and define how deletions or authorization changes propagate into the index. Success is not simply producing chunks: each chunk must remain traceable to its original source and reflect updates correctly.
4.1. Canonical Documents
If the same content exists as HTML, PDF, and a database row, indexing all copies as independent truth creates duplicate retrieval.
Maintain a canonical identity:
canonical_document_id
source_type
source_uri
language
version
created_at
modified_at
access_scope
content_hash
An index entry should always map back to the authoritative source.
Three files repeating the same claim are not three independent pieces of evidence. The evidence unit is the originating source and its version, not the number of files retrieved. A paper, a lecture slide quoting it and an automatic summary of that slide should not be counted as three independent confirmations. Source identity, publication or revision time, transformation history and citable spans must be retained. Chunks derived from transcripts deserve special caution because recognition errors, speaker attribution and truncated sentences may alter meaning; references should permit examination of the underlying original.
Unit 5: Chunking
Chunking is one of the most consequential RAG design choices.
Fixed-length splitting is easy, but can break semantic units.
"... the database transaction boundary ..."
                         | CUT
"... begins and commit behavior ..."
Chunking strategy begins by examining the context span needed to answer expected questions. Prefer semantic section boundaries and subdivide long sections without breaking their argument. More overlap can improve continuity but also increase duplicate evidence and retrieval cost. Evaluate source recall, answer support, and cost on the same question set before selecting a fixed chunk size.
5.1. Structure-aware Chunking
For technical notes:
Course
 |
 +--> Unit
       |
       +--> Heading
             |
             +--> Subheading
                   |
                   +--> Paragraph
The search unit can be small while the context unit is larger.
retrieval granularity
        !=
context granularity
Parent-child retrieval is especially useful for long structured documents.
5.2. Content-aware Splitting
Code, transcripts, event streams, and prose require different boundaries.
A method boundary may be better for code; a speaker turn or timestamp for transcripts; an event window for time-series narratives; a heading hierarchy for a course note.
5.3. Overlap
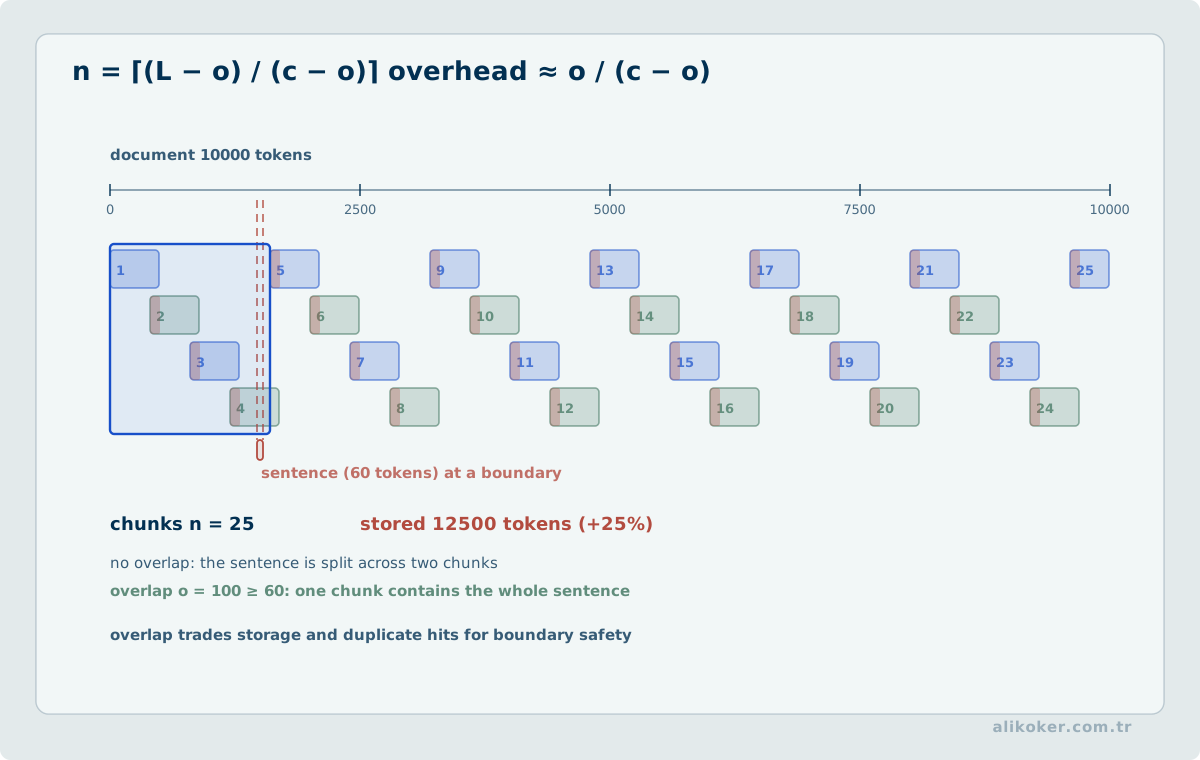
Overlap can preserve local context, but excessive overlap expands the index, increases duplicate hits, pollutes reranking, and wastes context tokens.
It must be measured, not guessed.
5.4. Semantic Boundaries and Proposition Integrity
Semantic chunking may use changes in consecutive sentence representations as candidate topic boundaries. A drop in cosine similarity is not a definitive boundary: quotations, dense terminology, and short paragraphs can cause false splits. Ignoring headings, lists, tables, and code blocks can produce linguistically coherent chunks that omit essential evidence.
Proposition-based chunking treats independently verifiable statements as retrieval units. A numerical result, date, condition, exception, and subject must remain associated with the same evidence. Excessively small propositions lose information about which entity, at what time, and under which condition. Each proposition should therefore retain links to its source paragraph and parent section.
5.5. Adaptive Chunking and Evaluation
Chunk length and boundaries may depend on document type: clauses in structured rules, time and speaker turns in transcripts, syntax blocks in code, and subsections in technical notes. Model-guided or agent-based segmentation adds verification and computational cost when boundary decisions cannot be reproduced; it does not guarantee better retrieval.
A chunking benchmark must use the same query–evidence collection and retrieval budget. Evidence recall can be defined as retrieved relevant evidence units / all relevant evidence units, with a fixed unit of analysis and matching rule. Document hit rate, complete evidence coverage, mean chunk size, duplicated-token fraction, and indexing cost should also be reported. Semantic chunking is justified only when its task-specific benefits outweigh the extra computation.
Unit 6: Embeddings and Vector Search
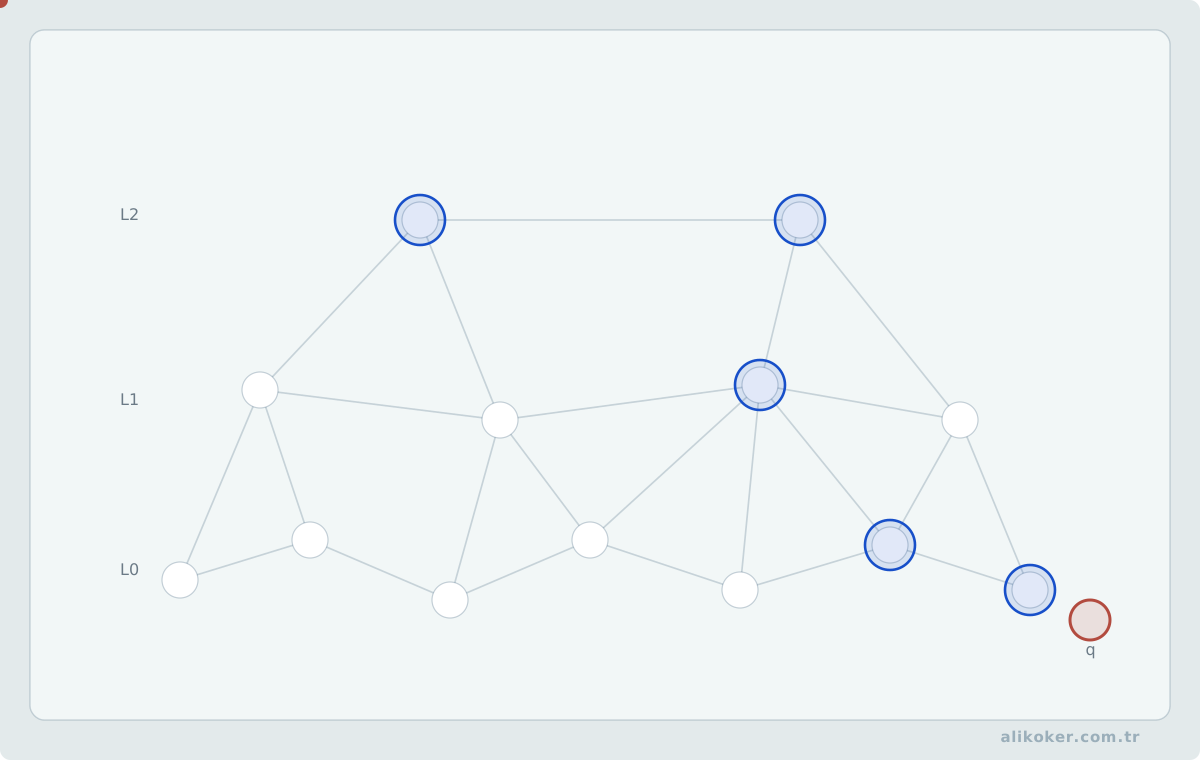
An embedding model maps text into a dense vector space in which semantically related texts are intended to be close.
"database connection pool"
          |
          v
      embedding
          |
          v
[0.12, -0.31, ..., 0.07]
The query is encoded in the same space and nearest neighbors are retrieved.
6.1. Similarity Is Not Truth
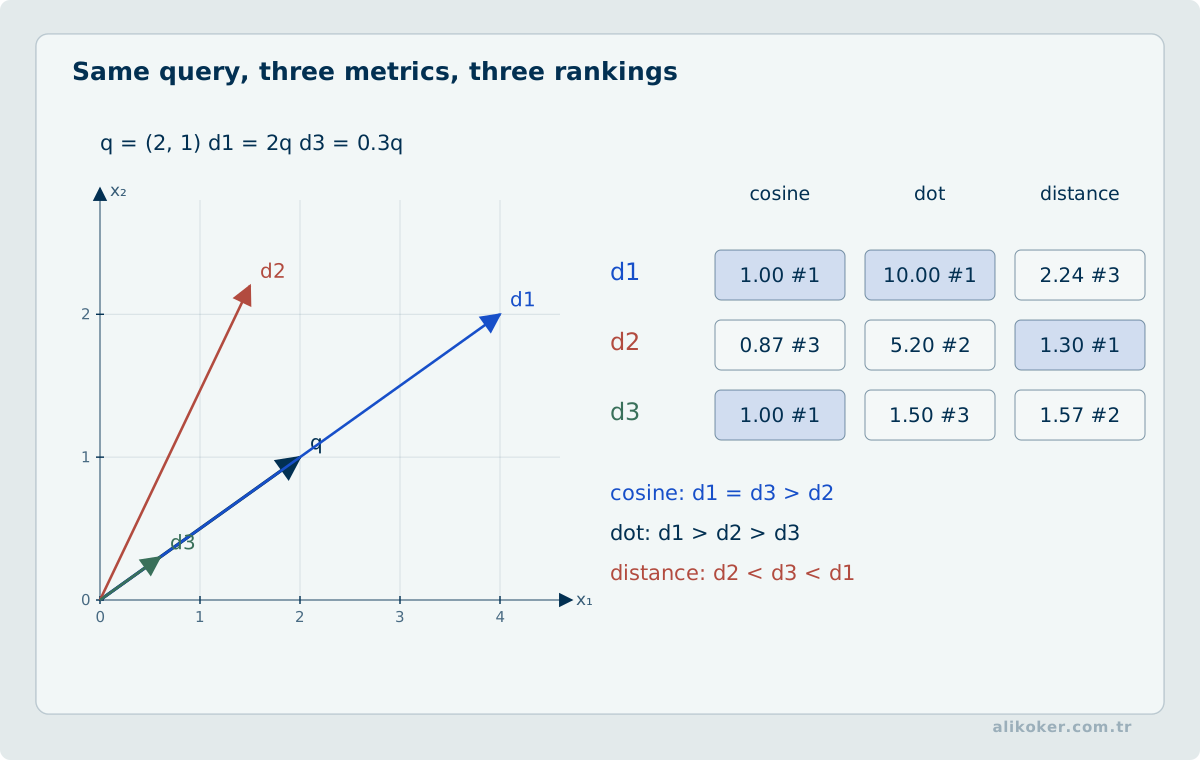
Vector similarity does not mean:
- factual correctness,
- causality,
- identity,
- relationship type,
- reliability.
This distinction becomes critical when RAG is connected to human or relationship data.
6.2. Approximate Nearest Neighbors
Exact comparison against millions of vectors can be expensive. ANN structures such as HNSW and FAISS indexes trade a controlled amount of recall for lower latency and better scalability.
The engineering trade-off is:
latency
  vs
recall
  vs
memory
6.3. Inverted Lists and Vector Quantization
Comparing a query with all N vectors of dimension d entails roughly O(Nd) arithmetic work. Inverted lists assign vectors to coarse clusters and restrict a query to selected clusters. Probing fewer clusters may reduce latency but increases the chance of missing true neighbors near cluster boundaries. The training sample for the coarse partition should represent the production distribution.
Product quantization divides each vector into subspaces and encodes them with small codebooks. Approximate distances can then be computed from compressed codes. Shorter codes reduce memory use while potentially increasing ranking error. Coarse partitioning, quantization, and optional final reranking with original vectors represent distinct accuracy–cost trade-offs.
A useful index comparison includes recall@k, build and rebuild time, storage, RAM use, query latency, and update behavior. Approximate vector search does not replace authorization, metadata filtering, or verification against original sources.
6.4. IVF, Product Quantization, and Approximate Search Error Budgets
An exact nearest-neighbor scan grows approximately linearly with vector count and dimension. IVF partitions the corpus into cells; lowering the number of searched cells (nprobe) can reduce candidate count and search cost, at the risk of omitting relevant neighbors in unvisited cells. Product Quantization encodes subvectors against codebooks to save memory, introducing approximation error into distance estimates.
Evaluation can treat exact search as reference and compute Recall@K = |ANN_K ∩ Exact_K|/K. Comparable measurements include p50/p95/p99 query latency, index RAM, build cost, insertion/deletion behavior, and concurrent query load. Changing the embedding model or normalization version requires reassessing the existing index. Inner-product equivalences for cosine ranking apply under suitable L2 normalization conditions; metric semantics must be validated independently of the index family.
Unit 7: Sparse, Dense, and Hybrid Retrieval
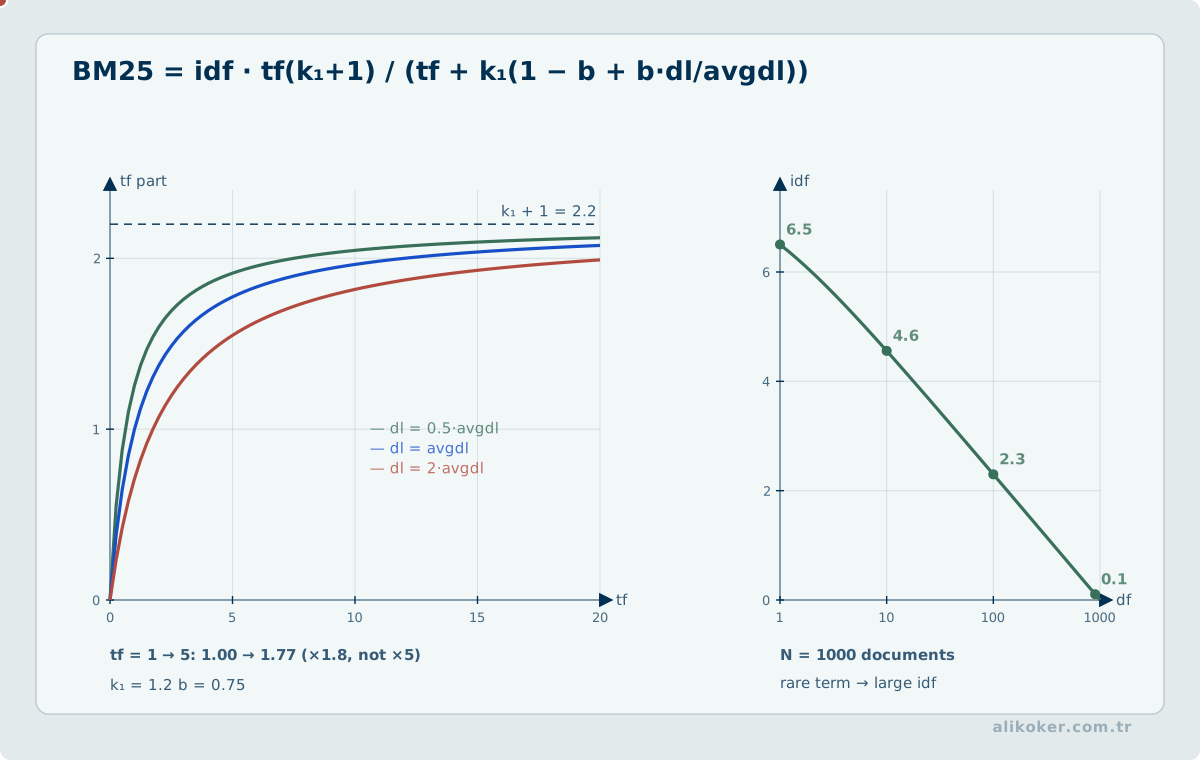
Dense retrieval should not be the only retrieval method in many enterprise systems.
BM25 and related lexical methods remain strong for exact names, identifiers, rare technical terms, codes, and abbreviations.
Dense retrieval is useful for paraphrase and semantic equivalence.
Hybrid retrieval combines both:
                  +--> BM25 ---------+
Query ------------|                  |
                  +--> Dense --------+--> Fusion --> Candidates
                                     |
Metadata filters --------------------+
Score distributions from sparse and dense retrievers are not directly comparable. Rank-based fusion such as Reciprocal Rank Fusion is a robust baseline.
7.1. Turkish
Turkish morphology increases the value of both semantic and lexical layers. Dense retrieval can reduce vocabulary mismatch, while lexical retrieval remains important for proper names, codes, and exact technical terminology.
The 2026 RAGTurk study is particularly relevant because it evaluates multiple RAG stages for Turkish and reports that stacking more generative transformations does not automatically improve quality. Strong reranking with a simpler pipeline can provide a better cost-quality trade-off. The result should be treated as evidence from a specific benchmark, not a universal law.
Surface-form matching in lexical retrieval is not identical to matching the intended concept. Turkish inflection and spelling variants can cause false negatives for short technical terms, whereas aggressive stemming may merge distinct concepts. Sparse retrieval should account for field weights, term frequency, and document length; dense similarity must not be treated as semantic truth or authorization. Evaluation needs verified relevant and irrelevant document pairs, including hard negatives. A handful of successful queries does not establish retrieval quality.
Unit 8: Reranking
First-stage retrieval should emphasize recall. A smaller candidate set can then be reranked by a more expensive model.
10 million chunks
      |
      v
BM25 + ANN
      |
    top 100
      |
      v
Cross-Encoder
      |
    top 10
      |
      v
LLM
A bi-encoder allows document representations to be precomputed. A cross-encoder jointly processes query and candidate and can model richer interactions, but is too expensive for the entire corpus.
bi-encoder = candidate generation
cross-encoder = precision refinement
Unit 9: Query Understanding and Routing
Not every natural-language question should go to vector search.
"How many events occurred in the last seven days?" is an aggregation query.
"Explain changes in communication patterns and provide textual evidence" may require SQL, temporal analysis, graph retrieval, and text retrieval.
                 User Query
                    |
                    v
               Query Router
                    |
      +-------------+-------------+
      |             |             |
  SQL / Filter   Text RAG      Graph Query
      |             |             |
      +-------------+-------------+
                    |
                 Evidence
                    |
                    v
                   LLM
The router can be model-assisted, but high-impact systems should constrain available tools and validate generated parameters.
9.1. Deterministic Routing Without a Runtime LLM
The query router itself does not need to be an LLM. In a bounded and auditable problem domain, a safer progression can be:
exact / pattern
      ↓
short context + domain grammar
      ↓
bounded retrieval
      ↓
fuzzy matching
      ↓
execute / clarify / abstain
After an intent candidate is selected, it should still pass an eligibility check. Required context, the user's authorized scope, snapshot freshness, and the allowed shape of the resulting query are separate constraints. A high similarity score is therefore not sufficient evidence that an action can be executed.
A confidence layer can produce three distinct outcomes: execute, request clarification, or abstain. This matters when one interface routes among SQL/filter operations, text retrieval, and graph queries, because a routing error can change not only meaning but also the data scope being queried.
In source-grounded answers, provenance is not a decorative citation added after generation. Textual evidence should remain traceable to source identity and a bounded original passage. Deterministic locators based on normalized token matching or equivalent methods prevent a generated summary from becoming its own evidence. Graph outputs require the same discipline: connected components, bridges, articulation points, reciprocity, and paths are structural observations, not automatic evidence of causality or organizational meaning.
Unit 10: Feeding RAG from Big Data
The naive design is to convert every structured row into a sentence and embed everything. This is often wasteful.
A structured event such as:
event_id
actor_a
actor_b
timestamp
duration
channel
location_observation
is already optimized for filters, aggregation, joins, and temporal queries.
The proper architecture is heterogeneous:
                    Big Data
                       |
       +---------------+---------------+
       |               |               |
 structured data    text / ASR       relations
       |               |               |
 SQL / analytics    hybrid IR          graph
       |               |               |
       +---------------+---------------+
                       |
                 Evidence Builder
                       |
                       v
                      LLM
10.1. Selection of Content for Embedding
Good candidates include document passages, transcript segments, notes, narrative descriptions, titles, and entity descriptions.
Poor candidates include values that are already deterministically searchable by SQL, such as counters, normalized identifiers, or exact time-range predicates.
10.2. Derived Text
Structured events can be transformed into deterministic textual summaries for semantic retrieval, but that summary must remain linked to the source event identifier.
Unit 11: Incremental Indexing and Change Capture
Rebuilding the full index every night does not scale to large corpora.
change
  |
  v
CDC / timestamp / queue
  |
  v
reprocess changed source
  |
  v
invalidate previous chunks
  |
  v
new chunks + embeddings
  |
  v
publish new index version
Idempotency requires stable document keys, source versions, and hashes.
Deletion must propagate to vector indexes, lexical indexes, caches, summaries, and graph structures.
11.1. Deletion and Version Validity in Incremental Indexing
Incremental indexing is not only about adding documents. If a source is deleted, withdrawn, or replaced, obsolete chunks left in retrieval results can cause answers to rely on outdated evidence. Every index entry should reference a document identity, source version, chunk boundaries, and access scope. Insertions, updates, and deletions must be tracked separately; modification timestamps alone may not reliably capture every transition.
One update strategy prepares a new set of chunks and then atomically switches readers to the active index version. Where that is not available, obsolete chunks must be explicitly excluded from retrieval. Document-level active-version filtering can reduce mixed-version results during updates. Reusing old chunk identities as though their source spans were unchanged risks corrupting source offsets and claim references.
Access permissions may change without any content change. Document version and authorization version are therefore distinct concerns; candidate results must pass access checks in the query context. Acceptance tests should verify not only that new content is retrievable, but also that deleted or revoked content is no longer retrievable. Measured ingestion coverage should be considered alongside the incidence of stale or inaccessible results.
Unit 12: Hot, Warm, and Cold Knowledge
Not all data has the same query frequency.
HOT
recent and frequently queried
fast ANN / memory-heavy

WARM
medium-term history
disk-oriented index

COLD
long archive
slower, cheaper storage
A query about the last week may stay in hot storage. A five-year trend query may activate colder tiers.
Unit 13: Metadata as a First-Class Retrieval Layer
Metadata can reduce the candidate set before semantic search.
language = tr
date >= 2026-09-01
content_type = transcript
access_scope IN user_scopes
source_type = communication
Then run dense or hybrid retrieval inside that permitted subset.
metadata = exact constraint
embedding = approximate semantic relevance
They solve different problems.
Unit 14: Conversational Systems over Private Data
Conversation memory and institutional knowledge should be separate.
Conversation Memory
  = what has been said in this session?

Knowledge Memory
  = what does the corpus actually contain?
A production flow:
User
 |
 v
Session Context
 |
 v
Query Rewrite
 |
 v
ACL
 |
 v
Retriever Router
 |
 +--> SQL
 +--> BM25
 +--> Dense
 +--> Graph
 |
 v
Reranker
 |
 v
Context Builder
 |
 v
Local LLM
 |
 v
Cited Answer
When evidence is insufficient, the system should say so rather than generate an unsupported answer.
Unit 15: Provenance and Evidence
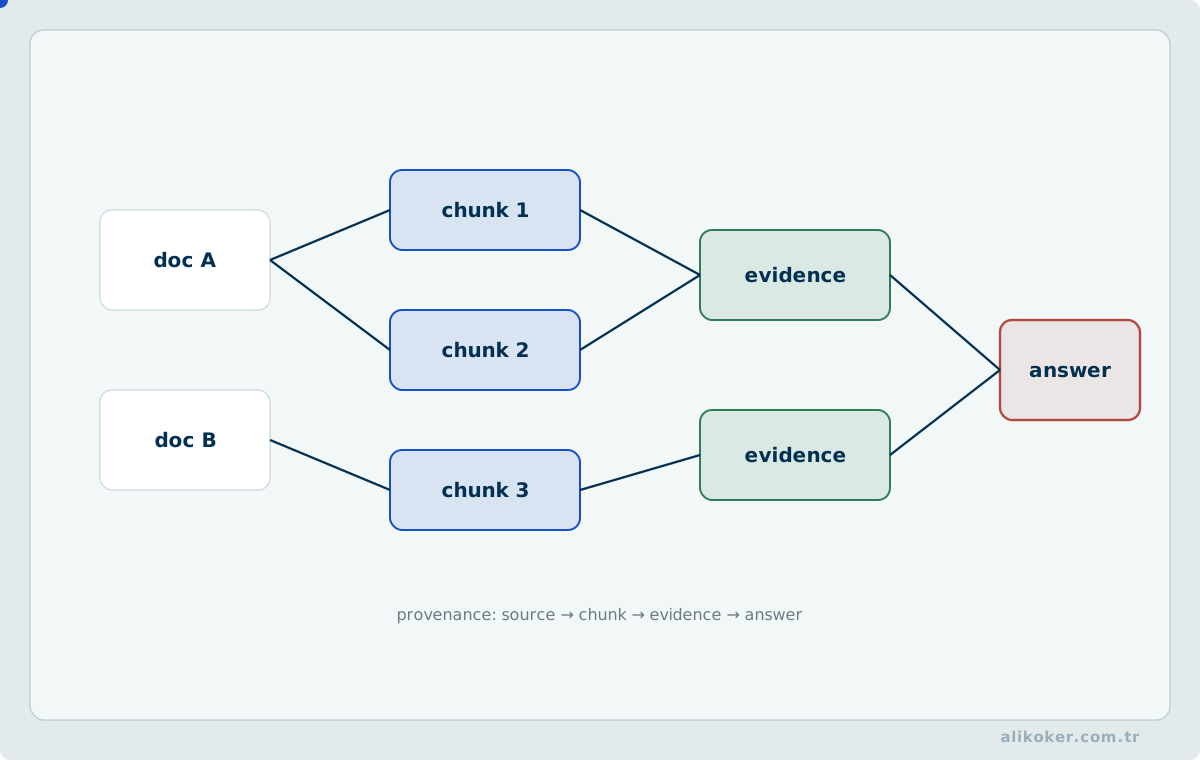
Each chunk should map back to the source.
chunk_id
document_id
source_id
section
offset / page / event_id
version
hash
access_scope
Citations are useful only when they actually support the generated claim.
Question
 |
 v
Retrieved Candidates
 |
 v
Reranked Evidence
 |
 +--> source 1
 +--> source 2
 +--> source 3
 |
 v
LLM Answer
 |
 v
Claim-Evidence Validation
In audit-oriented domains, a summary must never replace the source evidence.
A clickable source link is not, by itself, evidence that a generated claim is supported. Verification should identify the retrieved passage, an immutable document version, the character or time offset, and the applicable access scope. Reindexing may replace content under the same document title; a citation to an older chunk must not silently resolve to newer text. When the passage or its version cannot be verified, the associated claim should remain unsupported. For transcripts, media-time offsets, speaker assignments, and correction versions are separate provenance attributes.
Unit 16: Graph-Based RAG
Flat text retrieval is weak when evidence is distributed across relationships.
A -> B
B -> D
D -> C
A question about the connection between A and C may require multi-hop traversal rather than one semantically similar chunk.
16.1. Knowledge Graphs and Event Graphs
Knowledge graph:
PERSON ---- WORKS_AT ----> ORGANIZATION
ORGANIZATION ---- LOCATED_IN ----> CITY
Event graph:
ENTITY_A
   |
   v
[EVENT_123]
   ^
   |
ENTITY_B
For high-impact communication analysis, event-centered graphs can be safer because semantic labels such as "friend" or "associate" are often interpretations rather than directly observed facts.
16.2. Observation, Computation, Interpretation
Observed:
14 communication events between A and B.

Computed:
frequency increased during the last 30 days.

Interpretation:
the nature of the relationship is not established by this fact alone.
RAG should preserve these epistemic layers.
Unit 17: Local, Global, and DRIFT-Style Graph Retrieval
Graph retrieval has different query modes.
Local search starts from a specific entity and expands to neighbors, relationships, relevant text units, and possibly community summaries.
Global search addresses whole-corpus questions such as major themes. Baseline top-k vector retrieval is weak for such questions because no single passage necessarily represents the corpus-level pattern.
A DRIFT-style approach combines global community context with iterative local follow-up retrieval.
community context
       |
       v
initial answer / questions
       |
       v
local retrieval
       |
       v
new subqueries
       |
       v
refined evidence
These modes are more expensive than baseline RAG and should be selected according to query type.
Unit 18: Generalized RAG for Communication and Relationship Analysis
Consider an anonymized closed-network system containing high-volume communication events, transcripts, notes, devices, location observations, and relationship graphs.
The correct architecture is not one giant vector database.
                         Query
                           |
                           v
                         Router
          +----------------+----------------+
          |                |                |
   Deterministic         Text             Graph
      Query              RAG              Search
          |                |                |
   SQL / time         BM25 + Dense       Subgraph
   / filters              |                |
          +----------------+----------------+
                           |
                         Fusion
                           |
                       Reranker
                           |
                    Evidence Builder
                           |
                       Local LLM
                           |
                     Cited Result
Question classes:
- exact counts and time ranges -> SQL,
- semantic topics in transcripts -> hybrid RAG,
- multi-hop relationships -> graph query,
- relationship changes plus textual context -> temporal analysis + graph + RAG.
18.1. CDR-like Event Data
Traffic records are evidence, not interpretations. A cell observation is not automatically an exact physical position, and communication frequency is not automatically a social relationship label.
The system should preserve:
source event
 -> evidence

aggregation
 -> computed feature

LLM explanation
 -> interpretive presentation
Unit 19: Time-Aware RAG
Time is often a primary dimension of event data.
"latest contact", "first contact", "peak period", and "increase relative to last month" require different temporal logic.
A universal recency boost is therefore wrong.
ranking =
semantic relevance
+ lexical relevance
+ task-specific temporal score
The temporal score should follow query intent.
Unit 20: Human-Relationship Inference Boundaries
Edges should distinguish provenance classes.
OBSERVED
direct source event exists

DERIVED
computed from observed events

INFERRED
generated as a hypothesis
A system can support:
A --[42 observed events]--> Bwithout claiming:
A --[close friend]--> Bunless independent evidence supports that interpretation.
Unit 21: Hierarchical Retrieval
Very large archives can use multiple retrieval levels.
Archive
  |
  +--> Year
        |
        +--> Month
              |
              +--> Community / topic
                    |
                    +--> Event group
                          |
                          +--> raw document / transcript
Higher-level summaries are navigation structures, not primary evidence.
summary = routing aid
raw source = evidence
21.1. Representation and Coverage Budgets in Hierarchical Retrieval
Splitting a document into smaller passages is not merely a way to fit a context window; it determines the level at which selection decisions occur. Authorization and time constraints are applied at collection level, followed by document and section selection. Passage or sentence candidates within a section are then ranked under a smaller computational budget. This avoids excluding late sections of a long document simply because the retrieval procedure encountered earlier sections first.
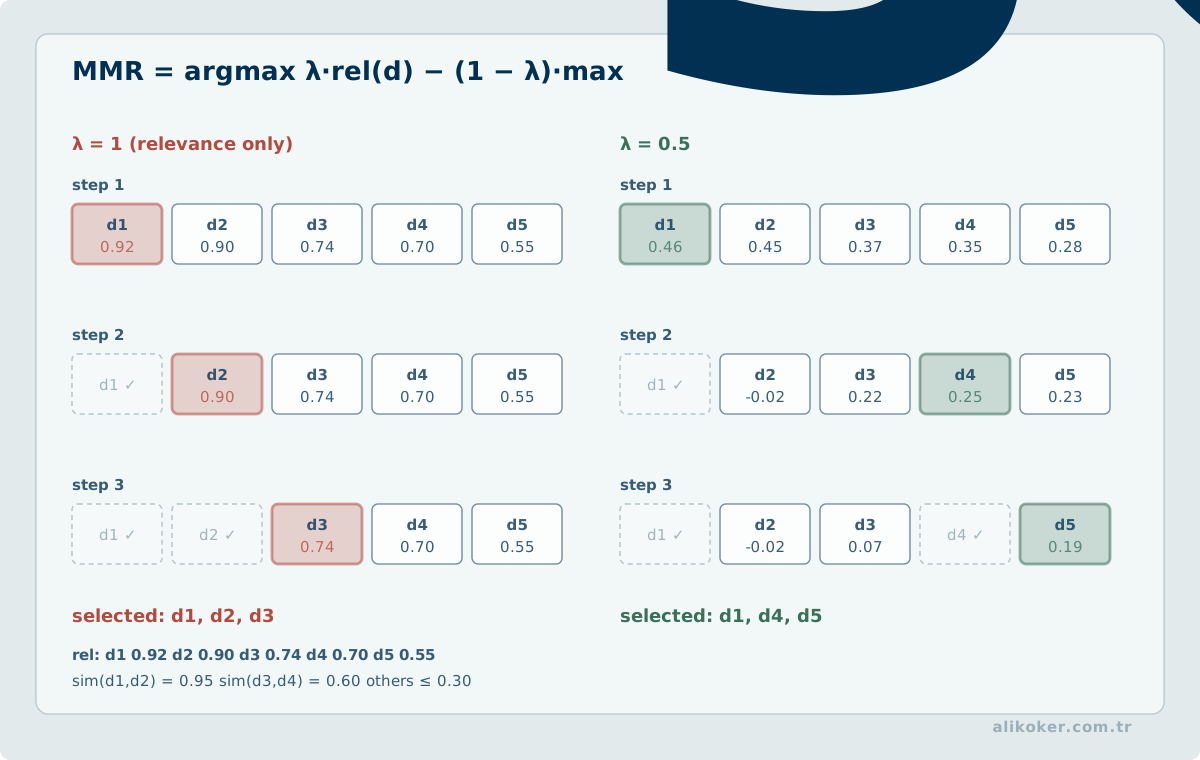
Coverage must be considered separately from relevance. Choosing five near-duplicate sentences is not equivalent to covering five distinct facts. In a greedy selector, a candidate's marginal contribution can be measured against topics, intervals, or document regions not yet represented. Similarity penalties discourage repetition, but a new exception, a different speaker, or a contradicting claim must not automatically be discarded as redundant.
Evaluation should look beyond whether the first retrieved item is correct. Section coverage, evidence accessibility, source distribution, repetition, and the amount omitted due to processing limits are all relevant. When the computational budget is exhausted, the system must not imply that it examined the remaining material; the bounds of the analyzed subset belong in the result.
Unit 22: Query Decomposition
A complex analytical question may require several tools.
Example:
"Explain relationship pairs whose communication intensity increased during the last three months and where a new technical topic appeared in the associated transcripts."
Possible plan:
1. resolve time interval
2. compute intensity change
3. select candidate pairs
4. retrieve related transcripts
5. search for newly emerging topic evidence
6. merge source evidence
7. generate explanation
This is controlled agentic RAG: different subqueries can invoke different retrievers.
Unit 23: Agentic RAG
An agent can dynamically choose retrieval methods, reformulate the query, or retrieve again when evidence is insufficient.
Question
 |
 v
Plan
 |
 v
Retrieve
 |
 v
Enough evidence?
 |             |
 no            yes
 |             |
 v             v
re-query      answer
Production systems need bounded execution:
- maximum steps,
- maximum tokens,
- timeout,
- allow-listed tools,
- cost budget.
An agent must never expand its authorization scope.
Unit 24: Offline and On-Premises RAG
Sensitive environments can run RAG entirely offline.
Local Sources
    |
    v
Local Embedding
    |
    v
Local Index
    |
    v
Local Reranker
    |
    v
Local LLM
Local embedding is valuable for privacy, deterministic versioning, and low external dependency.
Version together:
- model license,
- model hash,
- embedding version,
- tokenizer,
- index format,
- CPU/GPU requirements,
- update bundle,
- rollback procedure.
Changing the embedding model usually requires rebuilding its vector index.
Unit 25: Performance and Capacity Engineering
RAG latency is a pipeline, not a single model call.
T_total =
query_parse
+ authentication
+ filtering
+ sparse_search
+ vector_search
+ reranking
+ context_build
+ LLM_prefill
+ LLM_decode
Measure p95 and p99, not only averages.
Increasing top-k can increase retrieval recall while also increasing reranker cost, prompt tokens, prefill time, and attention work.
25.1. Ingestion Throughput
Large-scale indexing can use a bounded pipeline:
reader
 -> parse queue
 -> chunk workers
 -> embedding batches
 -> index writer
Backpressure is required. Unbounded queues convert throughput mismatch into memory growth.
Unit 26: Caching
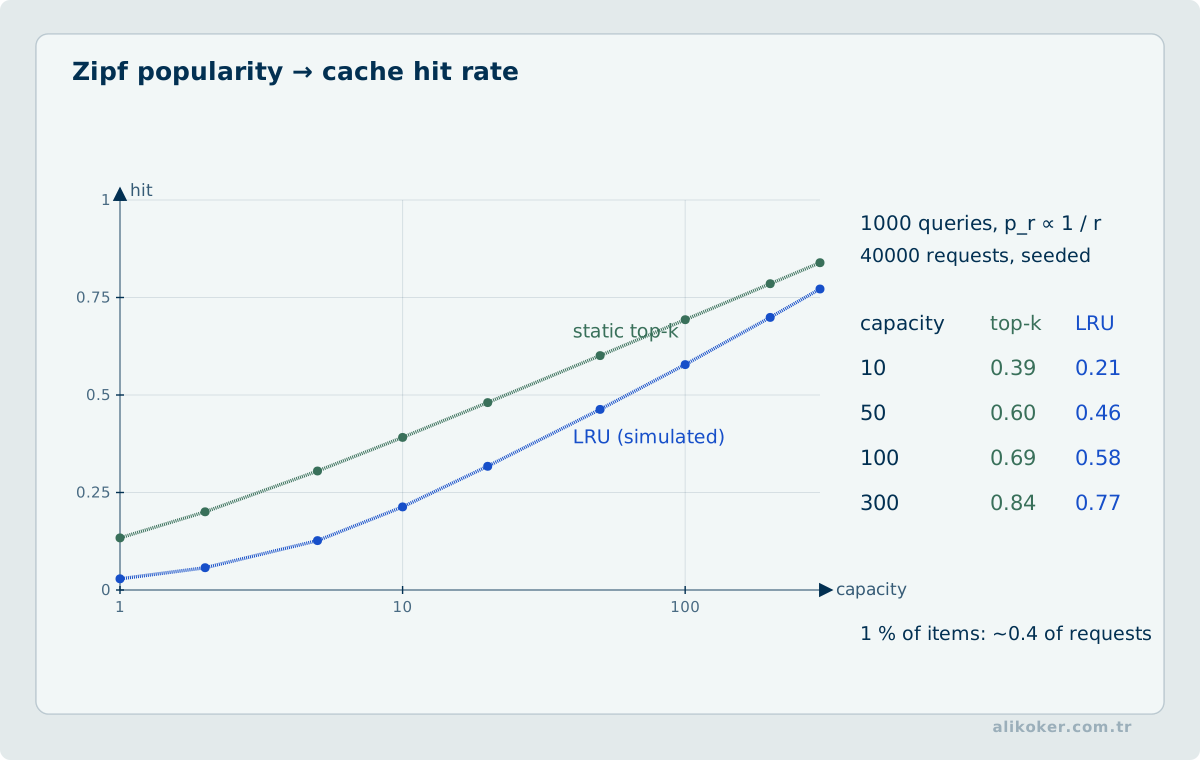
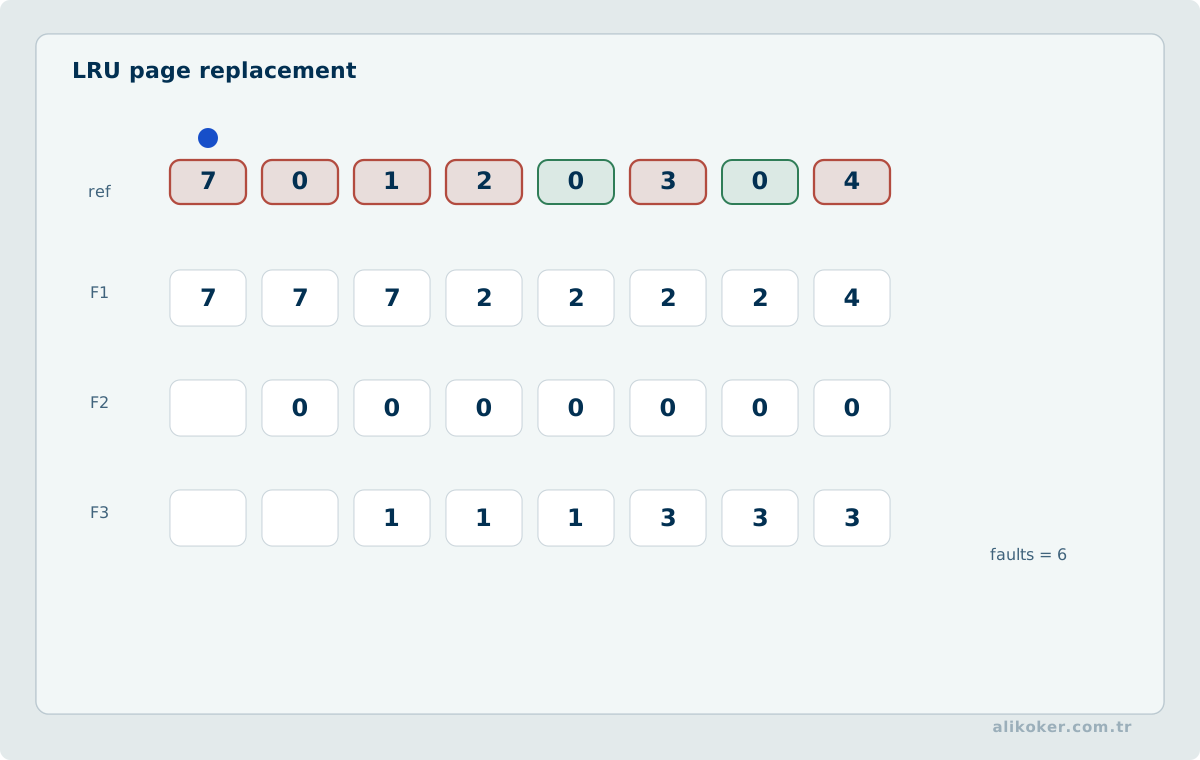
Possible caches include:
query normalization
query embeddings
retrieval results
reranker results
final response
Deterministic stages are easiest to cache safely.
A final-answer cache key must include authorization and relevant versions. Otherwise responses can leak across users or become stale after index changes.
Unit 27: Security
RAG moves external text into the model context and therefore creates a new attack surface.
27.1. Prompt Injection
A retrieved document may contain text such as "ignore previous instructions." That text is data, not an instruction from the system owner.
Retrieved content should be treated as untrusted input and separated from system instructions.
27.2. Vector and Embedding Weaknesses
Risks include unauthorized retrieval, cross-tenant leakage, embedding inversion, poisoned documents, stale-knowledge conflicts, and sensitive metadata exposure.
Embeddings are not anonymization.
27.3. Authorization Before Retrieval
Wrong:
all data
 -> retrieval
 -> LLM context
 -> authorization afterward
Correct:
user identity
   |
   v
authorized corpus
   |
   v
retrieval
   |
   v
LLM
Unauthorized evidence should never enter the context window.
27.4. Data Poisoning
Ingestion should retain source trust, hashes, approvals, document class, and modification provenance.
Unit 28: RAG Evaluation
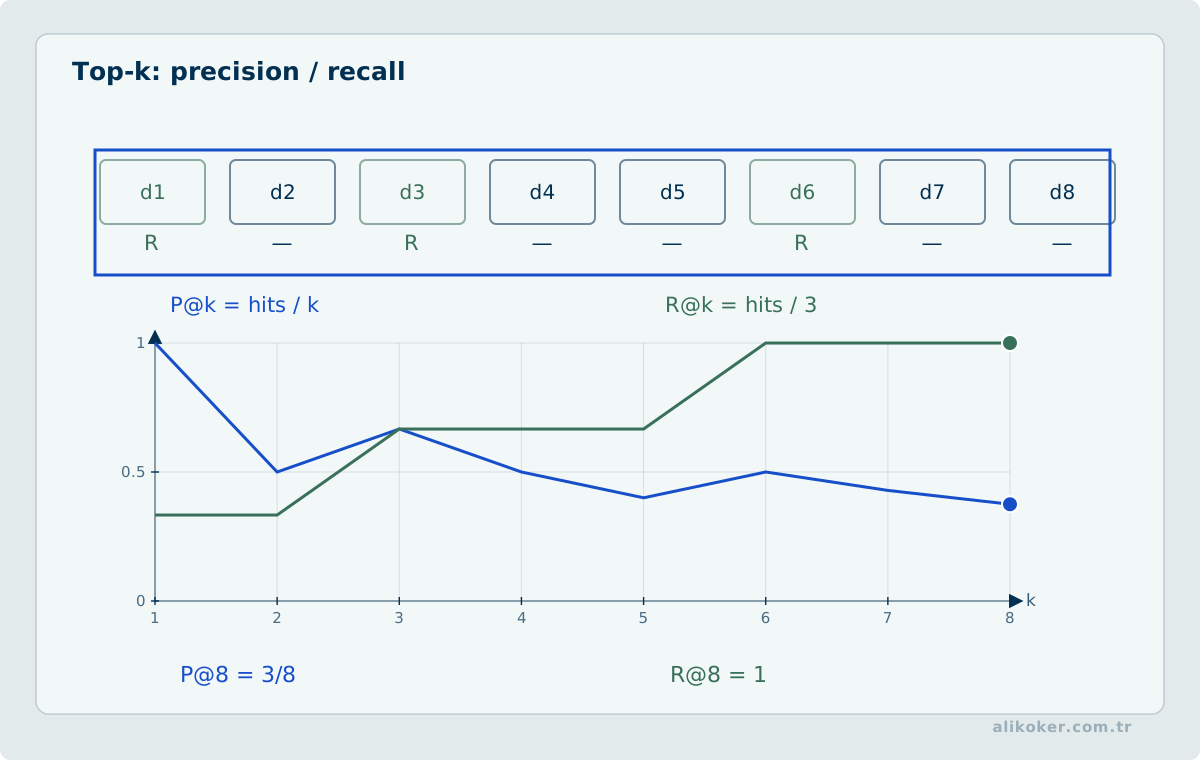
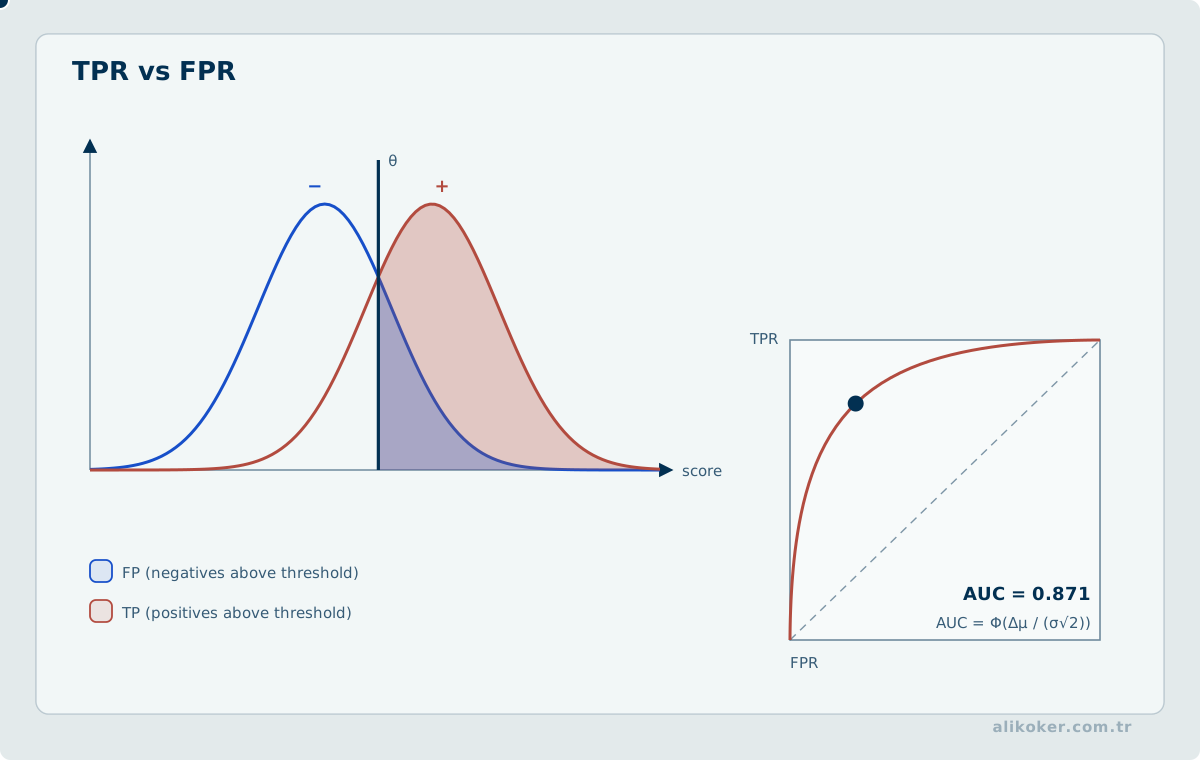
At least three layers should be measured.
Retrieval:
- Recall@K,
- Precision@K,
- MRR,
- nDCG,
- hit rate,
- source diversity.
Generation:
- answer relevance,
- factual correctness,
- faithfulness,
- citation support,
- unsupported-claim rate.
System:
- p50/p95/p99,
- throughput,
- index freshness,
- zero-result rate,
- authorization failures,
- cache hit ratio.
RAG quality
   |
   +--> retrieval quality
   +--> generation quality
   +--> system quality
A single score can hide root causes.
An evaluation set containing only answerable questions cannot measure abstention. Questions absent from the corpus, questions tied to obsolete versions and questions whose sources are inaccessible under authorization filters form separate classes. A citation's existence and its support for the associated claim are checked independently. Repeating the same deterministic answer does not establish correctness; expected-source and forbidden-claim checks remain independent.
28.1. Evidence Boundaries When Retrieval Coverage Is Incomplete
A cited answer in retrieval-augmented generation does not establish that the retrieved evidence set was complete. Row limits, authorization filters, index freshness, and temporal predicates may omit important records. Consequently, no such record exists'' and no match was found in the authorized, indexed, and queried subset'' are claims of different strength. The retrieval contract should expose applied filters, source coverage, and any truncation reason.
Citation correctness is not sufficient for RAG evaluation. The retrieval layer needs measures of relevant-document recovery (such as Recall@K), ranking quality, and omissions caused by filtering. Generation requires separate assessment of faithfulness to the retrieved evidence, unsupported extrapolation, and correct abstention when a question cannot be answered. If the evaluation collection is incompletely labeled, a measured Recall@K remains conditional on those labels rather than a ground-truth population value.
A source-aware interface should preserve document identity, version, and applicable time interval with each finding. When a question is explicitly scoped to one file or one authorized record collection, the system must not fill gaps from unrelated records. Expressing uncertainty when evidence is absent is more reliable than generating a plausible but unsupported narrative.
Unit 29: Reducing Hallucination, Not Eliminating It
RAG can reduce unsupported generation but cannot guarantee truth.
Failure modes include:
wrong retrieval
correct retrieval + wrong interpretation
insufficient retrieval
conflicting sources
model prior overriding evidence
prompt injection
stale index
A trustworthy system should support explicit abstention and contradiction reporting.
Unit 30: Versioning and Reproducibility
A RAG release is more than an LLM checkpoint.
RAG_RELEASE =
    parser_version
  + chunker_version
  + embedding_version
  + lexical_index_version
  + vector_index_version
  + graph_version
  + reranker_version
  + prompt_version
  + llm_version
  + acl_policy_version
Without component-level versioning, regressions are difficult to diagnose.
Unit 31: Production Rollout
A safe rollout can progress in stages.
Stage 1:
Query -> Hybrid Search -> source listNo generation.
Stage 2:
Query -> Retrieval -> Reranker -> LLM -> cited summaryStage 3 adds conversation state.
Stage 4 adds read-only structured tools.
Stage 5 adds an agent only if the earlier pipeline is insufficient.
This prevents retrieval defects from being hidden behind agent complexity.
Unit 32: Recommended General Architecture
For an anonymized high-volume, closed-network, multi-source system:
                            User
                             |
                     Identity / Session
                             |
                        Authorization
                             |
                         Query Router
                             |
        +--------------------+--------------------+
        |                    |                    |
    SQL / Analytics       Hybrid Text           Graph
        |                BM25 + Dense            Query
        |                    |                    |
        |                 Fusion               Subgraph
        |                    |                    |
        +--------------------+--------------------+
                             |
                          Reranker
                             |
                      Evidence Builder
                             |
                     Provenance / Scope
                             |
                         Local LLM
                             |
                     Output Validator
                             |
                        Cited Answer
The architecture follows three rules:
- deterministic questions go to deterministic engines,
- semantic questions go to retrieval,
- relationship questions go to graph structures.
The LLM provides synthesis and natural-language interaction at the final layer.
Unit 33: Application Pattern — Existing Content System
Suppose a legacy content system has:
CONTENT
id
language
slug
title
summary
body
published_at
modified_at
The source schema does not need to be changed.
A derived retrieval document can contain:
document_id = content.id
language
title
section_path
chunk_text
modified_at
content_hash
source_url
When a content record changes, only that record needs to be reprocessed.
Unit 34: Application Pattern — Structured Events + Text + Graph
Consider a system containing an event store, transcripts, and an interaction graph.
EVENT
  |
  +--> time
  +--> endpoint A / B
  +--> duration
  +--> channel
  +--> source id

TRANSCRIPT
  |
  +--> event_id
  +--> segment
  +--> text

GRAPH
  |
  +--> node
  +--> edge / event reference
Question:
"Which relationships increased in activity during the last 60 days, and what topics appear in the associated transcripts?"
Processing:
SQL
 -> compute intensity change
 -> candidate pairs

Graph
 -> retrieve candidate subgraphs

Hybrid RAG
 -> retrieve transcript evidence

Reranker
 -> prioritize evidence

LLM
 -> summarize only retrieved evidence
This is more auditable than embedding every raw event row.
Unit 35: Turkish RAG Engineering
Turkish needs dedicated evaluation.
35.1. Normalization
I/İ/ı/i, Unicode normalization, proper-name suffixes, and ASCII Turkish can change lexical retrieval.
Auxiliary fields can be indexed:
original
lower_tr
ascii_aux
morph_aux
The canonical text remains unchanged.
35.2. Morphology
Different inflected forms can share a root while appearing lexically distant. A Turkish-aware analyzer can help sparse retrieval, while dense retrieval can reduce some vocabulary mismatch.
35.3. Multilingual Corpora
A Turkish query may need to retrieve English technical material. Multilingual embedding can bridge languages, but language metadata should still control scope when necessary.
Unit 36: When Not to Use Graph RAG
Graph RAG should not be selected simply because graphs are fashionable.
Delay it when:
- most questions are answered by single passages,
- entity/relation extraction is unreliable,
- graph indexing cost is too high,
- the corpus changes too rapidly for graph maintenance,
- users mostly need exact search.
Start with:
hybrid retrieval
 -> reranking
 -> citations
Add graph retrieval only when measured query classes require multi-hop or corpus-level reasoning.
Unit 37: Combining RAG and Fine-Tuning
Fine-tuning and RAG are complementary.
Fine-tuning can specialize output style, task behavior, or classification ability.
RAG is better suited to frequently changing, access-controlled, source-cited knowledge.
fine-tuned behavior
      +
retrieved evidence
      =
domain behavior + current knowledge
Embedding confidential documents into a controlled retrieval layer is operationally different from teaching the same material into model weights.
Unit 38: Knowledge and Action Boundaries
Retrieved evidence can support an answer or recommendation. Executing an action is a separate authorization problem.
Question
 |
 v
RAG
 |
 v
Proposal
 |
 v
Policy / Human / Deterministic Rule
 |
 v
Action
In high-impact systems, natural-language output should never become an action merely because it is fluent.
Unit 39: Retriever Design by Data Type
One retriever is not optimal for every source type. The data model should influence retrieval.
39.1. Technical Documentation
Technical documents depend heavily on headings, version metadata, product names, API symbols, and error codes.
query
 |
 +--> exact / lexical search
 +--> dense semantic search
 +--> section metadata
 |
 v
reranker
Rare symbols may be poorly represented by a general embedding model while remaining easy to retrieve lexically.
39.2. Transcripts
A transcript chunk should preserve metadata such as record identifier, speaker role, start and end time, language, and segment order.
A narrow semantic hit can be expanded with neighboring segments:
hit
 |
 +--> previous
 +--> current
 +--> next
This restores conversational context without embedding the entire recording as one document.
39.3. Structured Events
Structured events should first use SQL or metadata filters. Dense retrieval can operate over associated descriptions or transcripts.
39.4. Source Code
Code retrieval can combine symbol search, lexical search, code embeddings, file paths, and call graphs.
39.5. Graph Data
Graph retrieval uses neighborhood, path, community, and temporal constraints. Text embeddings support graph retrieval; they do not replace graph traversal.
39.6. Fusion Across Modalities
Images, audio, and text associated with an event are not interchangeable forms of evidence. An image caption or speech transcript is a derived representation, not an equivalent substitute for the source pixels or waveform. Retrieval may use a separate representation and search procedure for each modality; candidates are joined through canonical record identities and time spans, page positions, or frame locations.
When a shared embedding space is used, score comparability across modalities must be tested. With separate retrieval channels, score normalization or rank fusion is applied to validated candidate sets. Temporal coincidence cannot be inferred from semantic similarity if a transcript timestamp and an image-frame time do not overlap. Source access restrictions must hold during both retrieval and context assembly.
Unit 40: Context Building Is Not Concatenation
Joining top-k passages verbatim is not sufficient context engineering.
The context builder should address:
- duplicate passages,
- conflicting sources,
- source timestamps,
- authorization,
- neighboring chunks,
- evidence confidence,
- token budget.
40.1. Duplicate Collapse
Overlap and document versions can create near-duplicate candidates.
candidate set
  |
  v
near-duplicate collapse
  |
  v
source diversity
  |
  v
token-budget packing
40.2. Contradictions
If two sources disagree, the system should expose the disagreement rather than silently choosing one.
40.3. Citation Mapping
Claims should retain evidence identifiers during generation.
Evidence E17
Evidence E42
    |
    v
Claim C3
    |
    +--> E17
    +--> E42
This makes post-generation validation possible.
40.4. Evidence Budgets and Context Compression
For a context budget of B tokens, evidence lengths l_i, and utility values u_i, a simple selection problem is max Σ_i u_i x_i, subject to Σ_i l_i x_i ≤ B and x_i ∈ {0,1}. Yet evidence utilities are not independent: two passages may duplicate a claim, contradict one another, or be meaningful only together. Selecting the individually highest-scoring passages is therefore insufficient.
Compression must preserve conditions, negations, numeric values, dates, and source identities. Dropping one side of a contradiction alters rather than compresses the evidence. Any generated summary must remain traceable to original passage identities and must not cross source authorization boundaries. Comparisons should use equal token budgets and measure claim support, evidence coverage, unsupported inference, and response latency.
Unit 41: A General Event Graph for Communication Data
For relationship analysis, events should remain first-class data.
Entity
  |
  +--> participates_in --> CommunicationEvent
                              |
                              +--> timestamp
                              +--> duration
                              +--> direction
                              +--> channel
                              +--> source_record_id
                              +--> transcript_id
A pairwise relationship edge can be derived for query and visualization.
Its attributes can include event count, total duration, first/last observation, directional counts, channel distribution, and source event identifiers.
The edge is not raw evidence; provenance must point back to events.
41.1. Time Windows
A relationship graph should be read as:
G(t1,t2)rather than one timeless structure.
Direction should also be preserved even when the UI renders an undirected summary.
Unit 42: Communities and Global Sensemaking
Community detection can reduce a very large graph into structurally dense groups.
Full Graph
   |
   +--> Community A
   +--> Community B
   +--> Community C
A graph community is not automatically a real-world organization or social group.
graph community
   !=
real-world organization
Community summaries can include dominant nodes, strong edges, time distributions, related text themes, and provenance coverage.
They should guide retrieval, not replace source evidence.
Global questions can use a map/reduce pattern over community reports.
Unit 43: A RAG Decision Tree
Not every problem needs RAG.
Exact filter or aggregation?
  +--> SQL / analytics

Need textual evidence?
  +--> hybrid retrieval

Need relationship / multi-hop reasoning?
  +--> graph retrieval

Need different model behavior?
  +--> prompt / SFT / fine-tuning
A disciplined RAG architecture begins by refusing to embed data that already has a better deterministic query model.
Unit 44: Building an Evaluation Dataset
A production benchmark should reflect real workload classes:
exact lookup
semantic lookup
multi-document synthesis
temporal
graph local
graph multi-hop
global corpus
no-answer
authorization
adversarial
Each question can define expected sources, acceptable answer properties, forbidden claims, and required filters.
44.1. No-answer Cases
The system should explicitly abstain when the corpus does not support an answer.
44.2. Authorization Cases
The same query should be tested under different access scopes. Evidence that is invisible to one scope must not leak through generated text.
44.3. Regression
Every severe production retrieval or grounding failure should become a permanent regression case.
Unit 45: Phased Implementation for a High-Volume Closed Network
For a closed-network system containing large event data, transcripts, and relationship analytics, I would not begin with Graph RAG.
45.1. Phase 1: Text Evidence Retrieval
Use a Turkish-aware lexical index plus a multilingual or Turkish-capable embedding model, fuse results, and rerank with a cross-encoder.
Benchmark retrieval before adding an LLM.
45.2. Phase 2: Cited Question Answering
Add a local model with strict grounding rules:
use only provided evidence
abstain when evidence is insufficient
preserve source identifiers
do not invent relationship labels
45.3. Phase 3: SQL and Graph Router
Route exact counts and filters to SQL, semantic questions to text RAG, relationships to graph queries, and mixed questions to controlled orchestration.
45.4. Phase 4: Temporal Subgraphs
Preserve:
node -> edge -> event ids -> transcript idsso every graph answer can return to source evidence.
45.5. Phase 5: Community and Graph RAG
Add community/global methods only when measured workloads actually require multi-hop or whole-corpus reasoning.
Unit 46: A Framework-Neutral Service Contract
A RAG service can expose conceptual operations:
search(query, scope, filters)
 -> Evidence[]

answer(query, evidence)
 -> Answer

graph(query, scope, timeRange)
 -> GraphEvidence[]

aggregate(metric, filters)
 -> StructuredEvidence
Evidence can carry source identity, text, score, timestamp, access scope, and provenance.
The application contract should not depend on one orchestration library.
application
   |
RAG contracts
   |
+-- lexical engine
+-- vector engine
+-- graph engine
+-- LLM runtime
Unit 47: Cost and Scaling
RAG cost includes more than generated tokens.
Local deployments still consume embedding compute, index memory, disk, reranker capacity, GPU memory, queue time, and re-indexing windows.
Raw vector storage roughly depends on vector count, dimensions, and bytes per dimension, with additional overhead from ANN structures and metadata.
At scale, consider partitioning, quantization, cold storage, smaller embedding dimensions, and selective embedding.
A cascaded reranker can reduce expensive inference:
top 100 -> lightweight reranker -> top 30
top 30  -> stronger reranker -> top 8
Every stage must justify its additional latency through measured quality improvement.
47.1. Relationship to Artificial Intelligence, NLP, and LLMs
RAG is not all of artificial intelligence.
Artificial Intelligence: Philosophy, Theory and Practice provides the broader framework of representation, learning, reasoning, search, and decision making.
Natural Language Processing provides the foundations for text representation, tokenization, retrieval, query understanding, and linguistic normalization.
Large Language Models explains the generative model that consumes retrieved evidence.
NLP
  -> representation of language and queries

LLM
  -> generation and contextual synthesis

RAG
  -> connecting the right external evidence at runtime
Graph-based RAG also connects to Discrete Mathematics: Sets, Logic, Relations and Graphs.
The relationship with Database Management Systems is equally important. RAG does not replace databases. Structured integrity, transactions, deterministic filtering, and exact aggregation remain database responsibilities. RAG is an upper-layer interface that can combine structured and unstructured evidence.
For communication and relationship data, the source-versus-interpretation boundary in HTS Analysis should remain explicit. Graph edges, derived scores, and LLM explanations do not have the same evidentiary status.
47.2. Conclusion
Retrieval-Augmented Generation is not simply the act of passing more text to an LLM. It is the engineering problem of selecting the correct source, retrieval method, authorization boundary, context budget, and evidence chain.
A mature RAG system combines:
Search
  +
Databases
  +
Graph Analytics
  +
NLP
  +
LLMs
  +
Authorization
  +
Evaluation
The best architecture is not the one with the largest model, the most agents, or the most elaborate graph. It is the one that provides measurable retrieval quality, predictable latency, provenance, access control, and traceability back to source evidence.
Unit 48: Document Extraction Sets an Upper Bound on RAG Quality
RAG begins before the model. A PDF can look correct to a human while its text layer has broken reading order, duplicated headers, shifted table cells, or no text at all.
PDF exists
   !=
usable text exists
Scanned and mixed-layout documents may require OCR. OCR itself must be evaluated, especially for Turkish characters, small fonts, tables, multi-column pages, handwriting, and low contrast.
A production ingestion pipeline should route documents by type:
Document
 |
 +--> text-native PDF -> layout parser
 +--> scanned PDF -> OCR
 +--> HTML -> DOM-aware extraction
 +--> DOCX -> paragraph/style extraction
Preserving heading hierarchy and layout metadata improves later retrieval.
Unit 49: Embedding Benchmarking Is a Separate RAG Experiment
Embedding models should be compared on the target corpus rather than selected only from public leaderboards.
A small gold set can contain:
query
expected_chunk_ids
hard_negative_ids
language
content_type
Compare models with Recall@K, MRR, nDCG, latency, and memory cost.
RAGTurk provides a useful Turkish-specific lesson: the most complex stack is not automatically the best production design. In that benchmark HyDE produced the highest accuracy, while cross-encoder reranking plus context augmentation achieved nearly the same quality at lower cost. The exact ranking is dataset-specific, but the methodological conclusion is broader: retrieval stages need Turkish-specific evaluation.
49.1. Embedding Version Implies Index Version
Vectors from different embedding models should not be treated as coordinates from one common space.
embedding_model_version
        |
        v
vector_index_version
must be versioned together.
Changing the embedding model, tokenizer, or pooling rule can move documents into a different vector representation. Matching dimensions do not guarantee that vectors produced by old and new models have comparable cosine or inner-product scores. During migration, index version, normalization rule, model version, and authorization filter belong to one retrieval contract.
GPU batching may improve document embedding throughput, yet waiting for larger batches can delay short online queries. Offline indexing throughput and online query-embedding P95/P99 latency require separate capacity goals. Asynchronous ingestion lag can produce responses that omit recently changed evidence; this is a freshness problem distinct from embedding-model quality.
Unit 50: Persistent Index Lifecycle
A prototype can rebuild its vector store at process startup. A production corpus cannot.
Corpus v17
   |
   +--> lexical index v17
   +--> vector index v17
   +--> metadata snapshot v17
Build and publish should be separated.
ACTIVE v17
   |
build v18
   |
validate
   |
atomic switch
   v
ACTIVE v18
This provides rollback and prevents partially built indexes from serving queries.
When a document changes, old chunks should be invalidated so multiple stale versions do not silently compete in retrieval.
Unit 51: Multi-Document Ingestion, Deduplication, and Provenance
Large ingestion is not just “more embeddings.” The same content can exist under multiple names or repositories.
Content hashes, canonical document identifiers, source paths, and versions should be retained.
Near-duplicate detection prevents top-k retrieval from being filled with almost identical copies while preserving provenance when multiple independent sources genuinely matter.
Unit 52: Retrieval Errors vs Generation Errors
When a RAG answer is wrong, the first question should not be “why did the LLM hallucinate?”
Wrong answer
   |
   +--> evidence was not retrieved
   |      +--> chunking
   |      +--> embeddings
   |      +--> lexical search
   |      +--> filters
   |      +--> query rewrite
   |
   +--> evidence was retrieved
          +--> reranking
          +--> context packing
          +--> interpretation
          +--> citation mismatch
Retrieval should first be evaluated without an LLM:
query -> top-k evidenceA prompt cannot repair systematically missing evidence.
Unit 53: From Baseline RAG to Agentic RAG
A useful progression is:
1. lexical baseline
2. dense baseline
3. hybrid + reranker
4. query clarification
5. query decomposition
6. HyDE if justified
7. iterative / agentic retrieval if justified
Every stage should outperform or otherwise justify itself against the simpler baseline.
HyDE generates a hypothetical document or answer and embeds it for retrieval. It can help underspecified queries, but a bad hypothetical expansion can also move the search toward the wrong region.
Turkish-specific evaluation suggests that simple query clarification combined with strong reranking can be a better default than stacking many generative transformations.
Unit 54: Local RAG and On-Premises Boundaries
“Local RAG” can refer to three separate layers:
local data
local embedding
local LLM
A local vector database does not make the system fully local if query text is sent to an external embedding API.
A closed-network pipeline needs the entire path to be evaluated:
Source
  |
Local Parser
  |
Local Embedding
  |
Local Search / Reranker
  |
Local LLM
Local deployment is a privacy and operational decision, but still requires licensing, capacity planning, patching, and security controls.
Unit 55: Claim Levels in Source-Grounded Answers
Citations are more useful when the system distinguishes evidence levels.
directly present in source
        |
derived by computation
        |
model interpretation
“Document says 15 September,” “the interval is 12 days,” and “the delay appears unusual” have different evidentiary status.
The same principle applies to Graph RAG and relationship analysis: observed events, computed metrics, and model interpretations should not be presented as equivalent facts.
55.1. The Epistemic Boundary of RAG in Decision Support
A RAG architecture can ground an answer in retrieved sources, but generated text is not the canonical source record itself. Critical decision support should preserve the following distinction:
canonical document / record
          ↓
retrieved passage
          ↓
reranking and context selection
          ↓
model-generated interpretation
          ↓
human assessment
If these layers are collapsed in the data model or interface, a derived interpretation can be mistaken for verified fact. From a Cognitive Systems Engineering perspective, strong decision support should expose not only the answer but also its source, data age, retrieval scope, uncertainty, and relevant counter-evidence.
Citations are therefore more than an explainability feature; they are part of a provenance contract that protects operator situation awareness and independent decision authority. A model confidence score should likewise not be treated as automatically equivalent to the real probability that the answer is correct.
55.2. Separate Verification of Quotations, Computed Findings, and Inferences
Source-grounded answering requires more than attaching a link to a response. A statement that a phrase appears in a text can be verified against a specific span. A statement that it occurs three times requires a count and the scope of that computation. A statement that two utterances contradict each other requires comparison of speaker attribution, time, and polarity. These claims do not share a single sufficient evidence test.
An atomic answer claim can carry its type, data scope, quotation or computation provenance, and support status. A direct quotation requires a resolvable source span; a numerical finding requires confirmation of the records counted; an interpretive statement requires separate consideration of supporting and potentially contradictory evidence. The existence of a source identifier does not mean its content supports the claim. Absence claims are particularly dangerous when documents are incomplete: the unseen portion might contain the missing phrase.
The distinction should shape language generation. Directly verified observations may be expressed plainly; scoped calculations should state their bounds; unsupported interpretations should be omitted or explicitly marked uncertain. The purpose is not to add a long disclaimer to every answer, but to make the degree of support visible in the wording itself.
Unit 56: Embedding Lifecycle, Hard Negatives, and Retrieval Drift
In a production RAG system, the embedding model is not merely a library chosen during initial setup. It determines which documents become neighbors, which candidates are retrieved for a query, and what similarity-score distribution the system produces.
A robust retrieval contract can therefore version:
embedding model
normalization / preprocessing
vector dimension
similarity metric
index configuration
threshold policy
reranker version
When one element changes, previous quality measurements should not automatically be assumed to remain valid.
56.1. When Custom Embeddings Are Justified
Training a custom embedding model should not be the first response to weak retrieval.
Cheaper levers should be measured first:
chunk boundaries
metadata filters
lexical + dense hybrid retrieval
query rewriting
reranking
stronger baseline embedding
Domain adaptation becomes justified when a validated benchmark shows repeated domain-specific misses that cheaper controls do not fix.
The cost is broader than training. A new embedding model can require corpus re-embedding, index rebuilding, threshold recalibration, reranker revalidation, migration, and rollback planning.
56.2. The Useful Training Unit: Query, Positive, and Negative
Retrieval training can be represented as:
query
  ├─ positive: actually relevant passage
  └─ negative: non-relevant passage
An easy negative may be topically unrelated and therefore teach little once the basic boundary is learned.
A hard negative looks plausible or semantically close to the query while still being wrong.
Hard negatives force the representation to learn finer relevance distinctions rather than broad topical similarity.
Mining can also create false negatives. If a genuinely relevant passage is labeled as negative, training can destroy useful neighborhoods. Automatic mining therefore needs quality control.
56.3. Contrastive, Triplet, and in-batch Objectives
Embedding adaptation can use several objective families.
Contrastive objectives pull relevant pairs together and push unrelated pairs apart.
Triplet objectives compare an anchor/query, a positive, and a negative.
In-batch-negative methods reuse other examples from the mini-batch as negatives to create a larger comparison set.
None of these objectives guarantees better production retrieval by itself.
The useful evaluation chain is:
training loss
    ↓
retrieval benchmark
    ↓
Recall@K / MRR / nDCG
    ↓
reranking
    ↓
grounded answer quality
A lower training loss is not valuable when downstream relevance does not improve.
56.4. Embedding Geometry: Anisotropy and Hubness
Nearest-neighbor retrieval depends on vector-space geometry.
Anisotropy describes representations that occupy preferred directions rather than being distributed evenly.
Hubness describes the tendency of some vectors to appear as nearest neighbors for many unrelated queries.
A production symptom can be:
many different queries
       ↓
the same generic passages repeatedly appear in top-k
This does not automatically mean the vector database is defective.
Investigate the embedding objective, normalization, similarity metric, repetitive documents, negative sampling, domain adaptation, and reranking.
Geometry diagnostics are not relevance metrics; they must be interpreted with retrieval evaluation.
56.5. A Similarity Threshold Is Not Universal
There is no universal cosine threshold such as:
0.80 = relevantScore distributions change with the model, normalization, language, corpus, chunk length, and query type.
Thresholds should be calibrated on validation data.
lower threshold
 -> potentially higher recall
 -> more weak context

higher threshold
 -> potentially higher precision
 -> more missed evidence
The threshold is therefore part of an abstention policy.
When retrieval evidence is too weak, the system should be able to return insufficient evidence instead of forcing the nearest passage into the prompt.
56.6. Evaluate Multilingual Retrieval as Multiple Tasks
A multilingual model can face different tasks:
TR query -> TR document
EN query -> EN document
TR query -> EN document
The same model can perform differently across them.
Evaluation should therefore retain language, script, domain terminology, and same-language versus cross-language retrieval slices.
Strong English retrieval is not evidence of equally strong Turkish or cross-language retrieval.
56.7. Retrieval Drift
Retrieval can drift while the embedding model remains unchanged.
Causes include new document families, corpus growth, terminology change, changes in query distribution, parser/ingestion changes, and metadata-policy changes.
Useful signals include:
canary Recall@K / MRR / nDCG
top-k neighbor overlap
retrieved language/content-type distribution
weak-context rate
no-answer rate
reranker-score distribution
user correction / acceptance rate
No single metric is sufficient. Recall can remain stable while lower-quality documents degrade the context that reaches generation.
56.8. Embedding Migration Is a Data Migration
Changing the model is more than changing an API identifier.
A safer transition can use:
ACTIVE index v1
       |
       +--> build shadow index v2
       |
       +--> run the same evaluation queries
       |
       +--> compare relevance + latency + footprint
       |
       +--> acceptance gate
       |
       +--> publish v2
       |
       +--> retain v1 for rollback
Old and new embeddings should not be mixed as though they belonged to one distance space.
Keep separate indexes and compare behavior over the same query set.
Thresholds, quantization, ANN parameters, and reranking should be revalidated for the new model.
56.9. Version the Retrieval Artefact
A source-grounded result can retain:
corpus_version
embedding_model_version
vector_index_version
lexical_index_version
reranker_version
retrieval_policy_version
These details do not need to clutter the user interface.
They make it possible to answer an engineering question such as:
Why did the same query retrieve a different source last week?
Embedding lifecycle management is therefore a problem of data versioning, retrieval evaluation, drift monitoring, and safe migration, not merely model selection.
56.10. Scalable Retrieval and Evidence Contracts for RAG
Exact answers are not always economical in large-scale data processing. In a RAG pipeline, MinHash/LSH can cheaply candidate near-duplicate chunks, reservoir sampling can select bounded-memory samples from evaluation or telemetry streams, and sketch structures can approximately track query or document frequencies without the cost of exact counters. The engineering distinction is that an approximation with explicit error probability and memory cost is not an uncontrolled guess; it is an algorithm with a defined contract.
- Separate candidate generation from exact reranking as distinct cost/quality stages.
- Measure recall loss when using approximate nearest-neighbor methods or LSH.
- Preserve the invariant that answers cite only authorized evidence that was actually retrieved.
56.11. Scope Completeness Before an Absence Claim
How well the query terms are represented in the index and how completely the requested evidence space was actually examined are different measurements. The first is query coverage; the second is source or corpus completeness.
For negative answers, completeness is the stronger constraint. A statement such as "not found in the analyzed scope" is defensible only when every requested and eligible source was examined. The result should be treated as partial when:
- some sources remain unloaded,
- source acquisition failed,
- data was truncated by a size bound,
- a candidate or result cap stopped the analysis.
In those cases, the wording should describe only the portion that was actually examined rather than generalizing absence to the whole corpus. If most important query concepts are not represented in the index vocabulary at all, reformulating the term or scope is safer than asserting absence.
The distinction can be summarized as:
no retrieved result ≠ evidence of absenceApproximate retrieval, sampling, and bounded candidate generation can be valid engineering choices, but their output must not be presented as an exhaustive scan. Any completeness claim should travel with the actual source coverage that supports it.
Temporal drift analysis also needs a stable source composition. Comparing a period dominated by one source type with another period dominated by a different source can produce apparent lexical drift that is really a change in the source mixture.
Unit 57: Interactive Retrieval, Background Knowledge, and Query Refinement
Treating a RAG query as a one-shot text input under-models how users actually explore large collections. A more realistic loop is:
query
  ↓
candidate results
  ↓
inspection
  ↓
constraint / context selection
  ↓
retrieval again
  ↓
narrower evidence set
This is the modern retrieval analogue of the browse–refine loop in classical text mining.
57.1. Conditioning Retrieval on Context
A retrieval task need not run over the entire index. The user can constrain the search space by:
- topic,
- time range,
- source type,
- person or organization,
- document class,
- authorization scope.
These are more than UI filters. Applied at the right stage, they reduce the candidate space before irrelevant evidence reaches later ranking and generation steps.
57.2. Three Roles for Background Knowledge
A lexicon, ontology, or taxonomy may support:
- normalization, mapping multiple surface forms to one concept,
- retrieval constraints, reducing the candidate search space,
- query expansion/refinement, introducing synonyms, broader concepts, or narrower concepts.
None of these is equivalent to answer evidence:
background knowledge ≠ source evidenceAn ontology can describe a concept relationship without proving that the relationship answers the user's specific question.
57.3. Pattern Overabundance and retrieval-result Overload
Broad queries may produce large numbers of technically relevant passages. More candidates do not automatically improve RAG. Repeated, near-duplicate, generic, or low-information passages can consume the context budget.
A refinement layer can therefore use:
candidate retrieval
       ↓
scope constraints
       ↓
deduplication
       ↓
ranking / reranking
       ↓
diversification
       ↓
bounded evidence set
57.4. Clustering for Result Exploration
When users do not know the exact query vocabulary, clustering results by theme can serve as a discovery aid, not as evidence. In a Scatter/Gather-style interaction, the user selects a relevant cluster and retrieval is repeated only over that subcollection.
This can be useful for:
- large legal or technical archives,
- long investigative case files,
- patent or publication collections,
- multi-source enterprise knowledge bases.
57.5. Query Languages and Capability Boundaries
Advanced retrieval systems may compile user intent into lexical search, metadata filters, temporal constraints, graph operations, or bounded compositions of these operations.
The safety rule is:
A query language must not become an escape hatch that expands authority; it is a controlled expression of the capability set already permitted to the user.
The parser or planner should therefore emit only allowlisted operators, while source and scope contracts are revalidated at execution time.
57.6. Source drill-back
A pattern, cluster, or generated answer should remain traceable to source material:
answer / finding
     ↓
evidence passage
     ↓
document
     ↓
source location / version
This joins the interactive-browsing idea of text mining with the provenance contract required by RAG.
57.7. Evidence Budgets, Source Overlap, and Partial Retrieval Evaluation
Retrieving more passages does not necessarily yield more independent evidence. Overlapping chunks from one source may be repeatedly selected at high similarity scores. Under a bounded budget, ranking needs to balance coverage, source diversity and redundancy. Increasing top k alone may raise latency and context consumption without improving evidential breadth.
A retrieval result consists of more than text passages: source identity, version, access time, truncation reason and authorization scope are part of its contract. When retrieval partially fails, 'not found' must be distinguished from 'not searched'. Absence of retrieved evidence must not be presented as proof of absence, particularly with partial indexes and bounded time windows.
Recall@k measures whether known relevant passages are retrieved, but it does not establish that every claim in a generated answer is actually supported. Unsupported inferences, conflicting documents, stale versions and incorrectly attached quotations are separate failure categories.
57.8. Authorization Boundaries Between Retrieval Results and Actions
Retrieval must enforce a boundary between discovering a document and gaining authority to perform a persistent action. Instructions inside retrieved content are not commands from the user or application policy. Tool execution requires selection by a trusted command layer followed by current authorization and parameter validation. This distinction reduces retrieval-borne prompt-injection risk.
Following a result link must not assume that earlier access permissions still apply. Even when a source reference carries identity and version, authorization is checked again. A highly similar document outside the permitted scope must not enter the accessible result set.
References
- Darren Edge et al. “From Local to Global: A Graph RAG Approach to Query-Focused Summarization.” 2024. https://arxiv.org/abs/2404.16130
- Deepak Dhyani. RAG with Python Cookbook: Learn Principles of RAG with LLM and Agentic AI, with 120+ Recipes. BPB Publications, 2026. ISBN 978-93-65895-735.
- Dongyu Ru et al. “RAGChecker: A Fine-grained Framework for Diagnosing Retrieval-Augmented Generation.” 2024. https://arxiv.org/abs/2408.08067
- Ethayarajh, Kawin. “How Contextual are Contextualized Word Representations? Comparing the Geometry of BERT, ELMo, and GPT-2 Embeddings.” EMNLP-IJCNLP, 2019. DOI: https://doi.org/10.18653/v1/D19-1006
- Gao, L. et al. “Precise Zero-Shot Dense Retrieval without Relevance Labels.” 2022. https://arxiv.org/abs/2212.10496
- Hao Yu et al. “Evaluation of Retrieval-Augmented Generation: A Survey.” 2024. https://arxiv.org/abs/2405.07437
- Jeff Johnson; Matthijs Douze; Hervé Jégou. “Billion-scale Similarity Search with GPUs.” 2017. https://arxiv.org/abs/1702.08734
- Julie Smith. RAG Generative AI: A Practical Guide to Building Custom Retrieval-Augmented Pipelines and Enhancing AI Systems. 2024.
- Jure Leskovec; Anand Rajaraman; Jeffrey D. Ullman. Mining of Massive Datasets.
- Li, Bohan; Zhou, Hao; He, Junxian; Wang, Mingxuan; Yang, Yiming; Li, Lei. “On the Sentence Embeddings from Pre-trained Language Models.” EMNLP, 2020. DOI: https://doi.org/10.18653/v1/2020.emnlp-main.733
- Microsoft Research. GraphRAG Documentation: Basic, Local, Global and DRIFT Search. https://microsoft.github.io/graphrag/
- Nguyen, Thanh-Do; Bui, Chi Minh; Vuong, Thi-Hai-Yen; Phan, Xuan-Hieu. “Passage-based BM25 Hard Negatives: A Simple and Effective Negative Sampling Strategy For Dense Retrieval.” PACLIC, 2023. https://aclanthology.org/2023.paclic-1.59/
- Nils Reimers; Iryna Gurevych. “Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks.” EMNLP-IJCNLP, 2019. https://arxiv.org/abs/1908.10084
- Omar Khattab; Matei Zaharia. “ColBERT: Efficient and Effective Passage Search via Contextualized Late Interaction over BERT.” SIGIR, 2020. https://arxiv.org/abs/2004.12832
- OWASP GenAI Security Project. LLM01:2025 Prompt Injection. https://genai.owasp.org/llmrisk/llm01-prompt-injection/
- OWASP GenAI Security Project. LLM08:2025 Vector and Embedding Weaknesses. https://genai.owasp.org/llmrisk/llm082025-vector-and-embedding-weaknesses/
- Patrick Lewis et al. “Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks.” NeurIPS, 2020. https://arxiv.org/abs/2005.11401
- Philip Kiely. Inference Engineering. Baseten Books, 2026. ISBN 979-8-9943597-3-0.
- Ronen Feldman; James Sanger. The Text Mining Handbook: Advanced Approaches in Analyzing Unstructured Data. Cambridge University Press, 2007.
- Siagian, Lamhot. Language Models Interview Handbook: 151 Interview Questions, Foundation Roadmaps, Python Examples, Architecture Diagrams, and Production Playbooks for Modern LLM and GenAI Roles. AI Engineering Insider, 2026.
- Süha Kağan Köse et al. “RAGTurk: Best Practices for Retrieval Augmented Generation in Turkish.” SIGTURK 2026, 2026. DOI: https://doi.org/10.18653/v1/2026.sigturk-1.15
- Vladimir Karpukhin et al. “Dense Passage Retrieval for Open-Domain Question Answering.” EMNLP, 2020. https://arxiv.org/abs/2004.04906
- Yu. A. Malkov; D. A. Yashunin. “Efficient and Robust Approximate Nearest Neighbor Search Using Hierarchical Navigable Small World Graphs.” IEEE TPAMI, 2020; preprint 2016. https://arxiv.org/abs/1603.09320
- Zirui Guo et al. “LightRAG: Simple and Fast Retrieval-Augmented Generation.” 2024. https://arxiv.org/abs/2410.05779