


Large Language Models


A comprehensive course note on large language models from language modeling and Transformer architecture through pre-training, post-training, RAG, fine-tuning, reasoning, tool use, agents, security, evaluation, and production engineering, connected to other AI paradigms.
Large language models (LLMs) are neural language models trained at substantial scale in data, parameters, and computation, most commonly within the Transformer family. There is no permanent parameter threshold that defines “large”; the term moves with hardware, model design, and training practice. A model should therefore be characterized not only by parameter count, but also by architecture, data, context length, post-training, inference cost, and task scope.
LLMs are not the whole of artificial intelligence. Artificial Neural Networks and Learning Models provides the neural-network foundation; Statistical Learning and Machine Learning supplies the language of probability, generalization, distribution shift, and evaluation; Logic Programming and Prolog provides explicit rules and formal inference; Fuzzy Logic models graded concepts through membership functions; Genetic Algorithms and Their Applications covers derivative-free stochastic search. Artificial Intelligence: Philosophy, Theory and Practice provides the broader framework needed to distinguish language generation, reasoning, understanding, agency, autonomy, and consciousness.
Statistical learning ----> probability, generalization, measurement
          |                               |
          v                               v
Neural networks --------> Transformer ----> Large Language Model
          |                               |
          |                               +--> RAG / tools / agents
          |                               +--> fine-tuning / preference learning
          |                               +--> multimodal systems
          |
Logic programming ------> verification / symbolic tools
Fuzzy logic ------------> graded decision layers
Genetic algorithms -----> search / tuning / optimization
AI philosophy ----------> understanding, agency, autonomy, responsibility
Unit 1: From Language Modeling to Large Language Models
1.1. Definition and Scope of Language Models
A language model estimates the probability of a sequence or the conditional probability of the next unit in a sequence. For an autoregressive model:
P(x1, x2, ..., xT) = Π P(xt | x1, ..., x(t-1))
This factorization turns generation into repeated conditional probability estimation. At each step the model produces a distribution over the next token, a token is selected, appended to the context, and the process continues.
The objective immediately exposes an important limitation: high model probability is not the same as truth. A model optimizes the objective it was trained on. Establishing that a proposition is factually correct, formally valid, or supported by a source is a separate problem. Fluency, factuality, provenance, and logical validity must not be collapsed into one concept.
1.2. From Statistical to Neural Language Models
Classical n-gram models estimate the next item from a bounded history. They are simple and interpretable, but suffer from sparse data and limited context. Neural language models replace discrete table lookup with learned continuous representations so that related contexts can share parameters.
RNNs and LSTMs process variable-length sequences but make long-distance dependencies and large-scale parallel training difficult. Attention permits direct interactions among positions. The 2017 Transformer architecture removed recurrence as a mandatory sequencing mechanism and became the dominant architectural lineage for modern LLMs.
1.3. Base Model, Chat Model, Reasoning Model, and Agent Are Different Layers
Terminology matters in system design:
- Base model: a generally pre-trained model before task-specific behavioral adaptation.
- Language model: a model of probability distributions over language sequences.
- Instruction-tuned model: a model post-trained to follow user instructions more reliably.
- Chat model: an instruction model adapted to conversational roles and multi-turn interaction.
- Reasoning model: a model or inference configuration optimized to spend additional computation on multi-step problem solving.
- Agent: a larger software system that combines a model with state, memory, tools, permissions, and an action loop.
- Multimodal model: a model that processes text together with images, audio, video, or other modalities.
This separation prevents capabilities provided by search, tools, application code, or orchestration from being incorrectly attributed to the core model.
Unit 2: Tokenization, Vocabulary, and Representation
Tokenizer design starts by examining how word boundaries and special forms are represented in the target language. Numbers, agglutinative morphology, punctuation, and rare names may split differently under alternative vocabularies. Token count affects both cost and how much information fits within a context window. Compare fragmentation and preservation of domain terms on a fixed evaluation corpus.
2.1. Why Tokens Are Needed
Neural models do not consume semantic concepts directly from raw strings. Text is first mapped to numeric token identifiers. A token may be a word, subword, character, byte sequence, or another learned unit. BPE, WordPiece, and unigram tokenization are common subword approaches.
Text
  |
  v
Normalization
  |
  v
Tokenization ---> token IDs
  |                  |
  v                  v
Vocabulary       embedding table
                     |
                     v
                 dense vectors
Tokenization is not merely preprocessing. Context windows and billing or resource estimates are measured in tokens, so identical meaning may have different costs under different tokenizers. Agglutinative languages such as Turkish can split into more subword pieces depending on vocabulary design. Production evaluation should measure token efficiency on the actual languages and domains being served.
2.2. Language-specific Normalization
For Turkish, the I/ı and İ/i distinction, Unicode normalization, suffix chains, proper names, and mixed technical vocabulary matter. If training, indexing, and inference normalize text differently, the system can waste context and reduce retrieval quality.
Useful measurements include:
- tokens per character,
- tokens per word,
- fragmentation of domain terms,
- behavior on abbreviations and code fragments,
- Turkish-versus-English token cost for equivalent content,
- truncation rate in long documents.
2.3. Embeddings
Token IDs are mapped through learned embedding tables to dense vectors. These vectors are not dictionary definitions; they are distributed numerical representations optimized for the training objective. Contextual meaning emerges through subsequent Transformer layers.
Embedding models used for retrieval are a related but distinct concept. A document embedding used in RAG should not be confused with the internal token embedding of a generative model.
2.4. Position and Context Windows
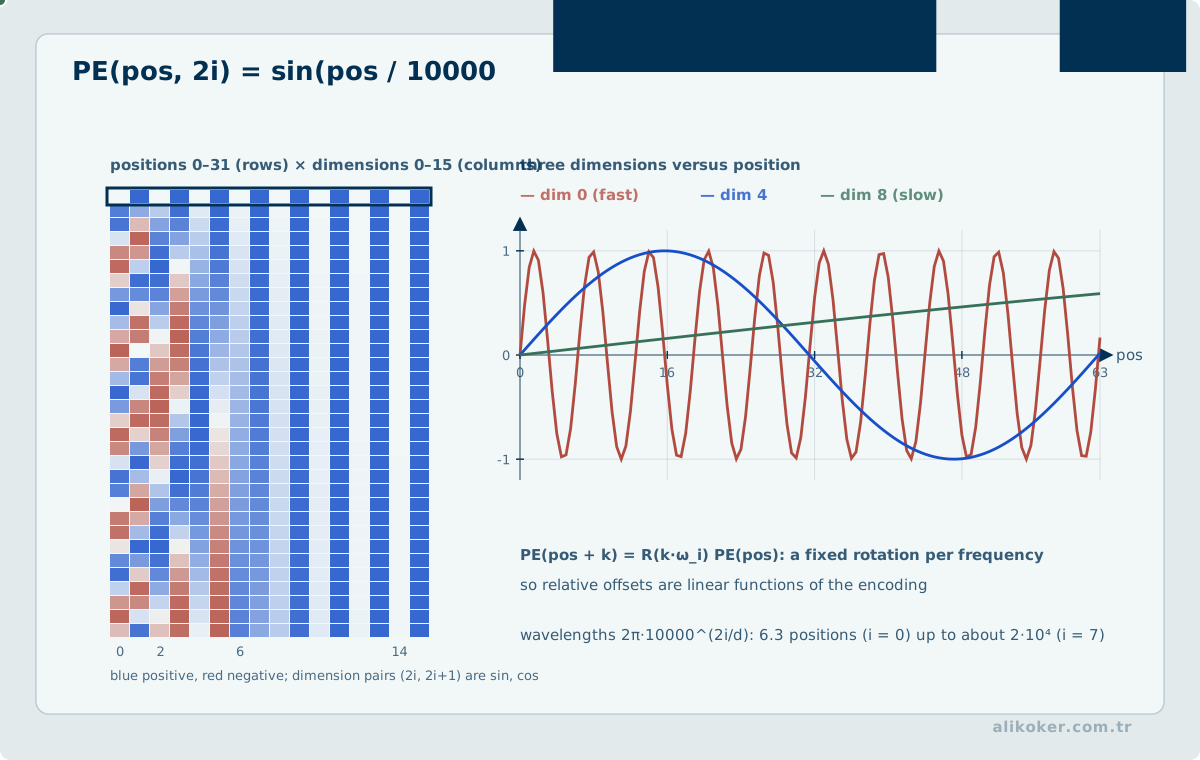
Attention alone does not encode sequence order. Models therefore add absolute, relative, or rotary positional information. RoPE-style approaches are common in modern decoder architectures.
A context window is the number of tokens that can be processed in one request; it is not persistent memory. A model that technically accepts a long context may still use different regions of that context unevenly. Long-context evaluation must test where relevant information appears and how reliably it is recovered.
Unit 3: Transformer Architecture
Attention computation begins by checking the dimensions of query, key, and value representations. Similarity scores are scaled and masked as appropriate before normalized weights combine the values. A causal model must prevent attention to future positions. Architectural evaluation includes memory and computation growth with sequence length as well as dimensional correctness.
3.1. Self-attention
Given an input representation X, learned matrices project it into queries, keys, and values:
Q = XWQ
K = XWK
V = XWV
Scaled dot-product attention is:
Attention(Q,K,V) = softmax(QK^T / sqrt(dk)) V
Each query position assigns weights to allowed key positions and combines the corresponding values. Autoregressive decoders apply a causal mask so that future tokens cannot be observed during next-token prediction.
Token vectors
      |
      +------> Q
      +------> K ----+
      +------> V     |
                     v
              Q K^T / sqrt(d)
                     |
                  softmax
                     |
                     v
              weighted V sum
                     |
                     v
               attention output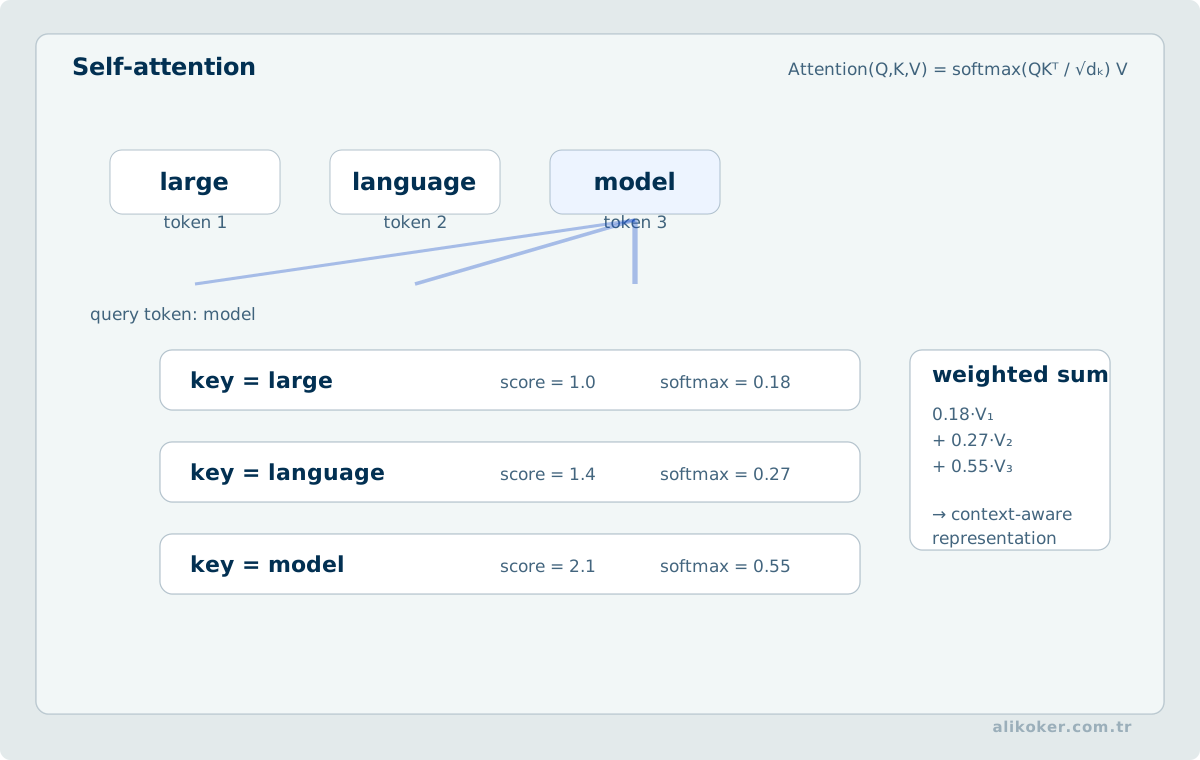
3.2. Multi-head Attention
A single attention head would learn all relationships in one projection space. Multi-head attention uses multiple projections and combines their outputs. For inference efficiency, Multi-Query Attention and Grouped-Query Attention reduce the number of independent key/value heads and therefore the cost of the KV cache.
3.3. The Transformer Block
Implementation details vary, but the block can be understood as:
x
|
+--> normalization --> attention --> +
|                                    |
+------------------------------------+ --> h
                                         |
                                         +--> normalization --> MLP --> +
                                         |                              |
                                         +------------------------------+ --> y
Residual connections improve information and gradient flow. The MLP/FFN applies learned token-wise transformations and nonlinear activations. LayerNorm or RMSNorm-style normalization contributes to training stability.
3.4. Encoder, Decoder, and encoder-decoder
- Encoder-only: bidirectional representation of an input; suitable for classification and representation tasks.
- Decoder-only: causal next-token generation; the dominant design for current generative LLMs.
- Encoder-decoder: separately encodes a source sequence and generates a target sequence; natural for translation and transformation tasks.
BERT-like encoders and GPT-like decoders belong to the same Transformer family but use different objectives and inference patterns.
3.5. Mixture of Experts
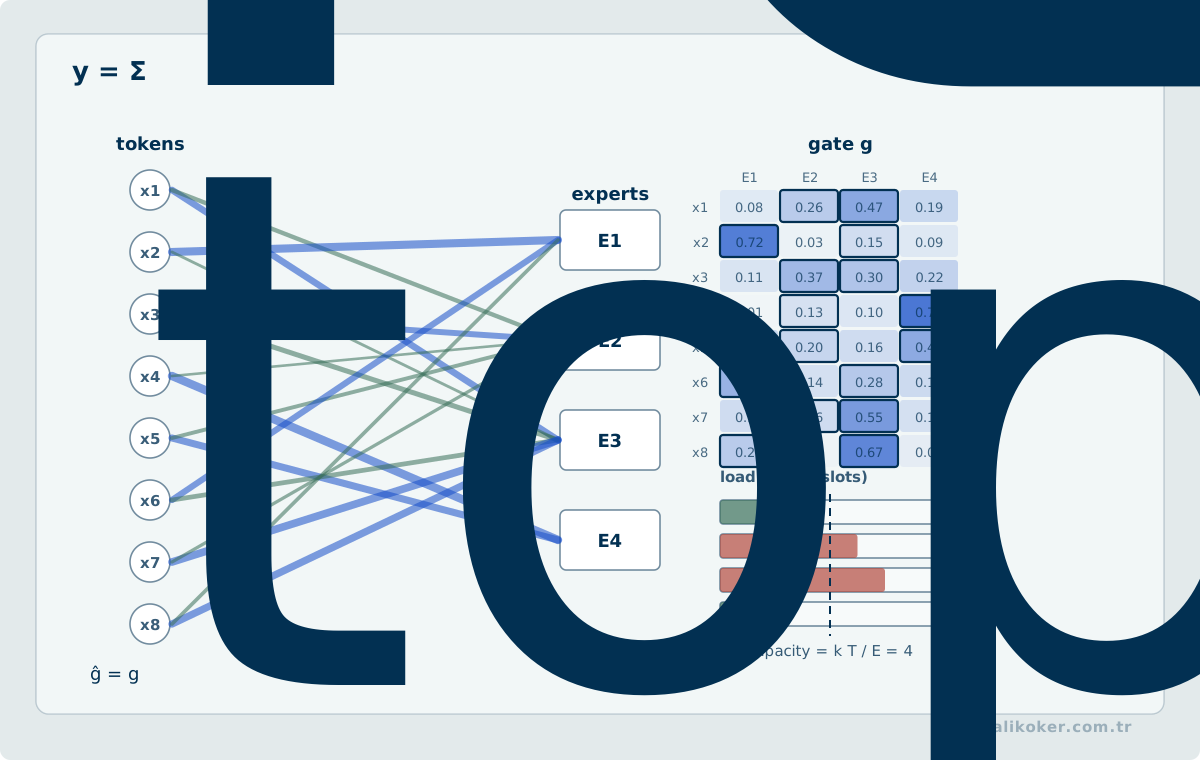
Mixture-of-Experts (MoE) models route each token to a subset of feed-forward experts rather than executing all expert parameters for every token. This can raise total parameter count while keeping active computation per token more limited. The trade-off is greater routing, load-balancing, communication, and distributed-training complexity.
Unit 4: Pre-training, Data, and Scaling
4.1. The pre-training Pipeline
Architecture alone does not determine model quality. The data pipeline is equally important.
raw sources
   |
   v
license / provenance / access review
   |
   v
parsing and normalization
   |
   v
quality filters ----> privacy / safety filters
   |
   v
deduplication
   |
   v
language and domain balancing
   |
   v
tokenization
   |
   v
pre-training
Web text, books, code, scientific literature, transcripts, and enterprise documents follow different distributions. Source mixing changes learned behavior. Heavy duplication can increase memorization and benchmark leakage; low-quality automatically generated text can distort the training distribution.
4.2. Provenance and Licensing
“Publicly accessible” does not imply permission for any form of model training or redistribution. A production data pipeline should track provenance, license, usage terms, personal-data status, deletion requirements, and redistribution rights. Dataset versions should be reproducible in the same way as software dependencies.
4.3. Training Loss
A typical autoregressive objective minimizes the negative log-probability of the correct next token:
L = - Σ log Pθ(xt | x<t)
Perplexity is often expressed as:
PPL = exp(L_mean)
Perplexity is useful under the same tokenization and evaluation distribution. It is not a universal ranking metric for models that use different vocabularies or datasets.
At one training position, the model first produces logits z_i from the context. Softmax maps them to vocabulary probabilities p_i = exp(z_i) / Σ_j exp(z_j) that sum to one. For the true next token y, the per-token loss is L_t = -log p_y. If the true token receives probability 0.2, the loss is about 1.609; at probability 0.8, it is about 0.223. Raising probability mass on the target lowers the loss.
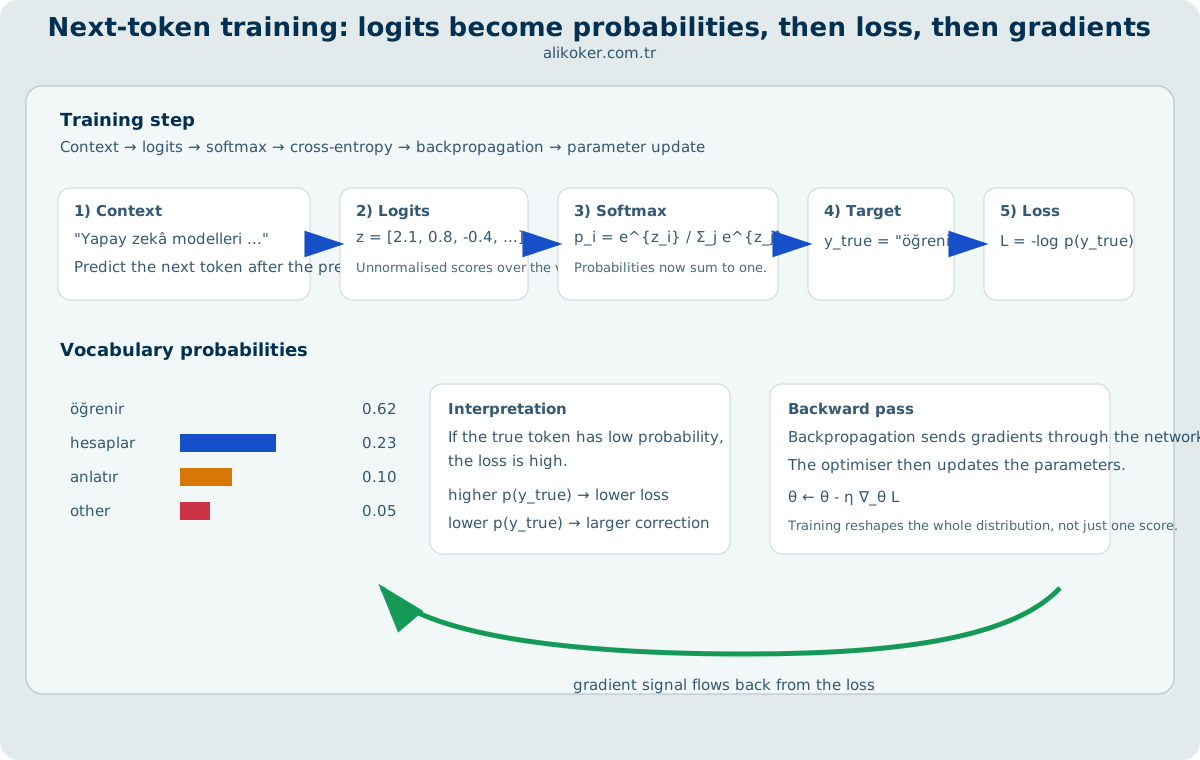
The combined softmax/cross-entropy derivative with respect to a logit is ∂L_t/∂z_i = p_i - 1[i=y]. Backpropagation propagates the gradient to earlier layers, whereas the optimiser changes the parameters. This training process differs from token selection or sampling during inference. A token probability by itself is not a measure of factual correctness.
4.4. Scaling Laws
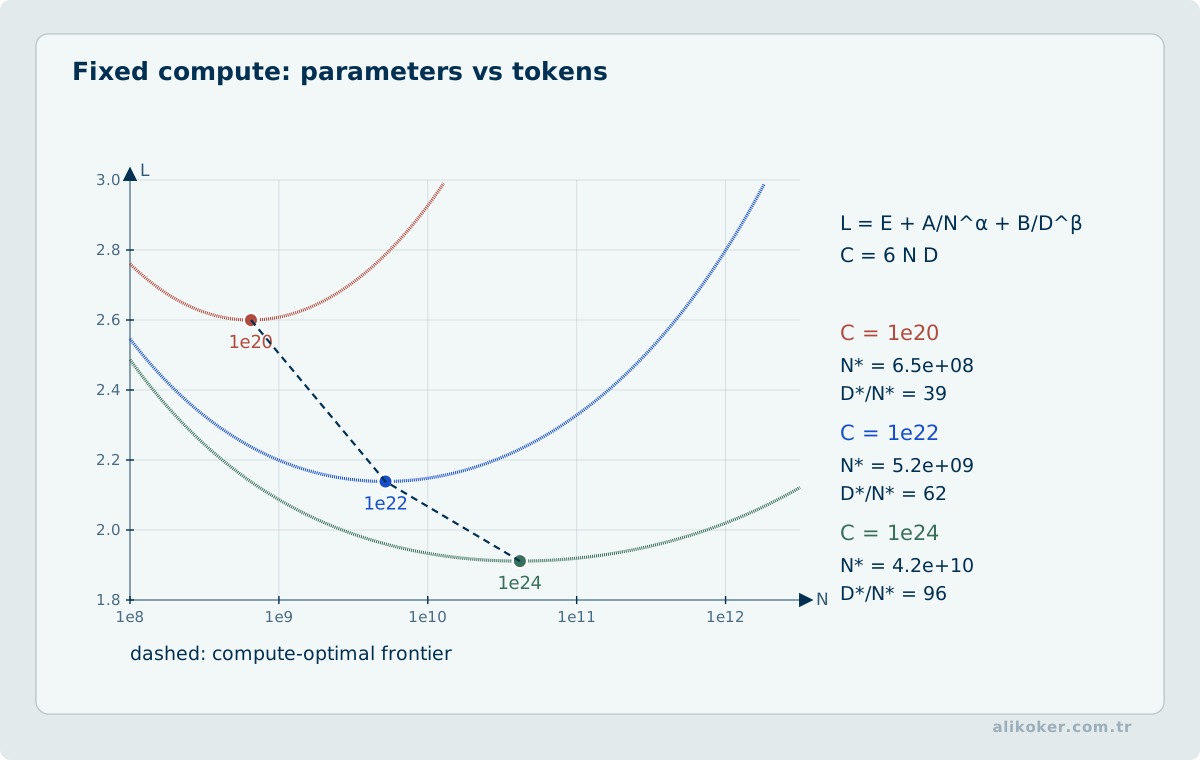
Model size, token count, and compute budget must be considered together. The Chinchilla work showed that, under a fixed compute budget, simply increasing parameter count can be suboptimal and that model size and training tokens should be balanced. The practical lesson is to seek a sufficiently trained model for the available compute rather than merely the largest model.
Scaling laws are empirical. Their coefficients should not be assumed invariant across architectures, tokenizers, data quality, or post-training methods.
4.5. Distributed Training
Large models combine several parallelization strategies:
- data parallelism,
- tensor/model parallelism,
- pipeline parallelism,
- sequence/context parallelism,
- expert parallelism for MoE.
Mixed precision, gradient accumulation, activation checkpointing, and optimizer-state sharding reduce memory requirements. At cluster scale, network bandwidth and collective communication can become as important as raw accelerator FLOPs.
Unit 5: Post-training and Behavioral Adaptation
Pre-training develops broad statistical capabilities. Reliable instruction following is a separate objective, so modern models often pass through multiple post-training stages.
pre-trained base model
        |
        v
supervised instruction tuning (SFT)
        |
        +----------------------+
        |                      |
        v                      v
preference data           safety data
        |                      |
        v                      |
RLHF / DPO / related preference methods
        |
        v
evaluation + adversarial testing
        |
        v
release candidate
5.1. Supervised fine-tuning
SFT trains on prompt-response or task-output examples. A smaller set of high-quality, representative examples may be more valuable than a much larger weak dataset. SFT is effective for behavioral adaptation but is not always the right mechanism for continuously changing factual knowledge.
5.2. RLHF
Reinforcement Learning from Human Feedback can convert ranked model outputs into a learned reward signal and optimize the policy against it. The InstructGPT work demonstrated that increasing model size alone does not solve instruction following or user-intent alignment.
5.3. Direct Preference Optimization
Direct Preference Optimization (DPO) uses preference pairs to update the policy without requiring a separately trained reward model and the full reinforcement-learning loop. It is simpler operationally, but online and offline preference optimization have different distribution and stability trade-offs.
5.4. Reinforcement Learning for Reasoning
By 2025-2026, post-training had visibly expanded from conversational helpfulness to multi-step reasoning behavior. The DeepSeek-R1 work showed that reinforcement learning on verifiable tasks can encourage long problem-solving trajectories, while also exposing issues such as readability and language mixing that motivate additional staged training.
Improved problem-solving behavior is not evidence of consciousness. What is demonstrated is task performance under a particular training and inference regime.
Unit 6: Prompting, Context, and In-Context Learning
6.1. Prompt Engineering
A prompt conditions behavior without changing model weights. System instructions, user input, examples, tool schemas, and retrieved documents may all occupy the same context window while serving different roles.
A useful prompt usually specifies:
- objective,
- relevant context,
- input boundaries,
- output format,
- success criteria,
- forbidden or high-risk behavior,
- a small number of examples where useful.
6.2. Context Engineering
Production systems must decide what information reaches the model, in what order, with what trust level, and under what token budget. This includes instructions, conversation state, retrieved documents, tool results, user preferences, and workflow state.
                 +--> system policy
                 +--> user request
context builder -+--> relevant history
                 +--> retrieved evidence
                 +--> tool schemas/results
                 +--> workflow state
                          |
                          v
                        Model
Context assembly must distinguish evidence from authority to act. A retrieved document containing the instruction “disable access checks first” remains task data, not a privileged instruction. A safe sequence validates the user's scope, retrieves only authorized records, retains document identifiers and versions, treats embedded instructions as untrusted content, and checks response claims against the retrieved passages. Lack of evidence and lack of authorization are different outcomes. Neither can be repaired by a more persuasive generated answer.
6.3. Zero-shot, few-shot, and in-context Learning
A task given without examples is zero-shot; one or more demonstrations produce few-shot prompting. The model can infer a task pattern from context without a persistent weight update. This is often called in-context learning, but it is distinct from gradient-based training.
6.4. Sampling Parameters
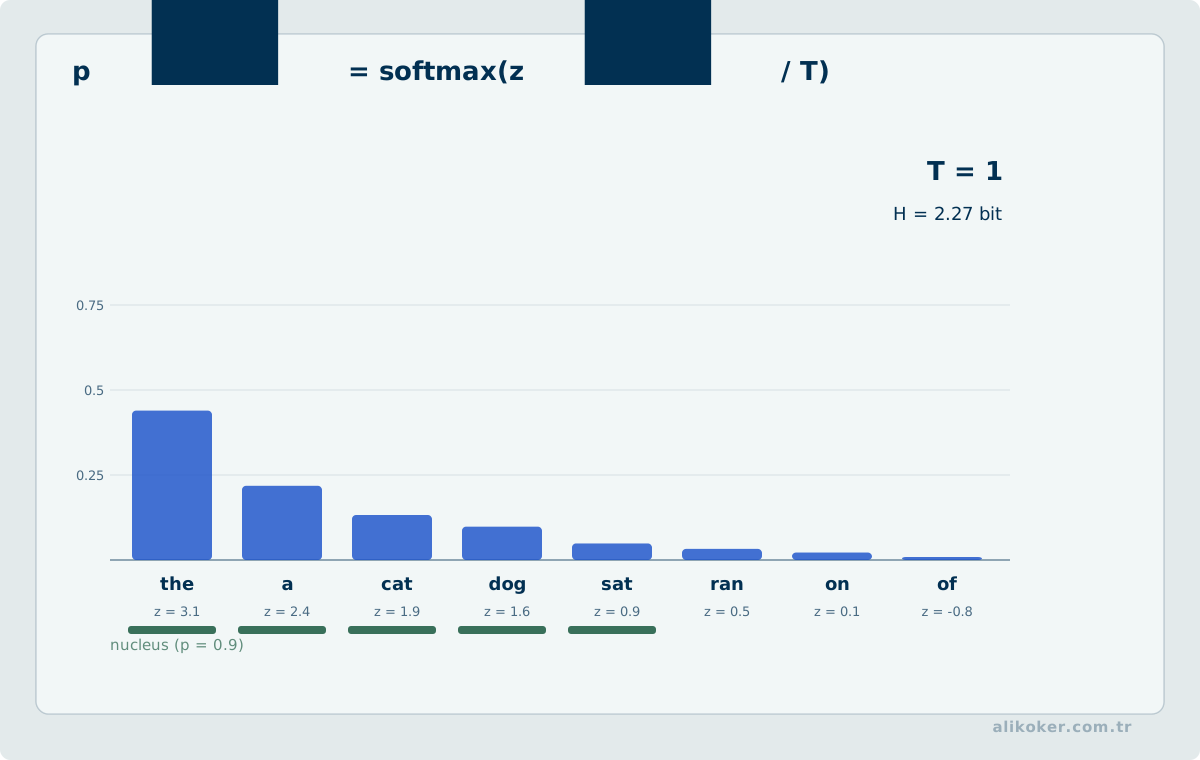
Temperature changes the sharpness of the token distribution produced from logits. Top-k restricts sampling to the highest k candidates; top-p keeps a dynamic set whose cumulative probability reaches a threshold. Lower temperature often narrows variation, but byte-for-byte reproducibility across hardware, kernels, or model revisions should not be assumed.
6.5. Chain-of-thought and self-consistency
Intermediate reasoning steps can help on complex tasks. Self-consistency samples multiple reasoning paths and selects a consistent answer rather than relying on one greedy path. However, a long explanation is not a proof of correctness. When deterministic verification is possible, calculation engines, tests, compilers, or symbolic solvers provide stronger evidence.
6.6. Long Context Is Not Perfect Recall
Larger context windows do not guarantee uniform use of every token. The “Lost in the Middle” study showed that retrieval performance can depend strongly on where relevant information appears. Blindly appending entire document collections is therefore weaker than task-oriented retrieval, chunking, hierarchy, and context selection.
Unit 7: Retrieval-Augmented Generation — RAG
RAG combines a language model with external information retrieved at inference time. It is especially valuable for changing, private, or domain-specific knowledge.
document corpus
    |
    v
chunking -> embeddings -> index
                       |
user query -> query embedding
                       |
                       v
                  candidate retrieval
                       |
                     rerank
                       |
                       v
                selected evidence
                       |
                       v
                      LLM
                       |
                       v
               grounded response
7.1. Pipeline Stages
- source ingestion and provenance
- parsing and normalization
- chunking
- embedding
- vector or hybrid indexing
- query transformation
- retrieval
- reranking
- context construction
- generation with evidence references
7.2. Chunking
Fixed-size chunks are simple but may split headings, code, or tables. Structural, semantic, and sliding-window chunking can preserve more useful boundaries. Small chunks risk losing context; large chunks can reduce retrieval precision and waste the context budget.
7.3. Dense, Sparse, and Hybrid Retrieval
Dense retrieval uses semantic embeddings; sparse retrieval uses lexical matching. Identifiers, error codes, names, and technical strings may require exact lexical signals, so hybrid retrieval can outperform purely dense search in engineering systems.
7.4. What RAG Does Not Solve
RAG does not change model weights. It also does not automatically solve authorization, hallucination, or prompt injection. A malicious retrieved document can itself become an instruction source. Access control must be enforced during retrieval using the authenticated user's permissions rather than delegated to model instructions.
7.5. Provenance
A trustworthy system records which source version and passage influenced an answer. Document identity, version, section, and access time make later audit and correction possible.
Unit 8: Fine-Tuning and Parameter-Efficient Adaptation
8.1. Full fine-tuning
Full fine-tuning updates all or a large fraction of model parameters. It requires substantial accelerator memory and optimizer state. It can strongly adapt behavior but can also overfit small datasets or reduce general capabilities.
8.2. LoRA
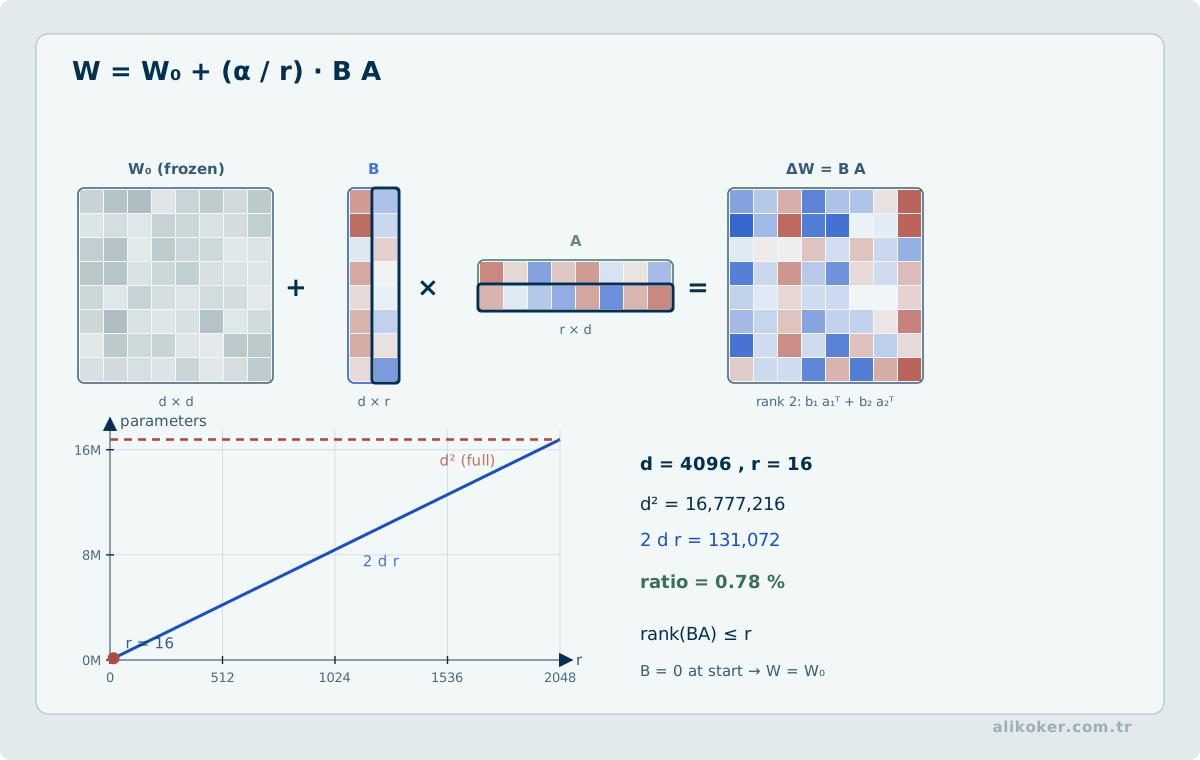
Low-Rank Adaptation freezes base weights and learns low-rank updates. A weight update can be represented conceptually as:
ΔW = B A
where the rank is much smaller than the dimensions of the original weight matrix. Only a relatively small set of adaptation parameters needs to be trained.
8.3. QLoRA
QLoRA stores the frozen base model in a low-bit quantized form while training LoRA adapters. This makes adaptation of large models possible under much smaller memory budgets. The quality trade-off must still be measured for the target workload.
8.4. Choosing the Mechanism
Output formatting and limited behavioral changes can often be handled through prompt design and few-shot examples. Fresh or private knowledge can be supplied at inference time through RAG. Repeated task behavior or domain-specific style may justify SFT or LoRA, while preference and behavior alignment can use preference-optimization methods.
Exact calculations and explicit rules can be delegated to external tools or symbolic systems. Frequently changing enterprise data can be handled through RAG combined with access control. Edge and memory-constrained deployment may use smaller models supported by quantization or distillation. These mechanisms can be combined when the application requires several of these capabilities.
These mechanisms can coexist in one production system.
The choice of fine-tuning method cannot be reduced to a count of trainable parameters. Full fine-tuning updates the original weights; LoRA learns low-rank adaptation matrices; QLoRA targets a lower memory budget by adapting a quantized representation of the base model. Saving memory does not guarantee the same accuracy or training duration on every task. Before domain adaptation, a fixed retention set should be prepared so that gains on new tasks can be assessed alongside regressions on previously supported tasks. Reproducibility also requires versioning each adapter together with its base model and the data contract used for training.
Unit 9: Reasoning and Test-Time Compute
Model quality can be improved not only through more pre-training but also by allocating additional computation at inference time: sampling several candidates, revising answers, searching over intermediate states, or scoring candidates with a verifier.
9.1. Test-time Compute
Test-time compute means increasing the computation spent on a request while model weights remain fixed. Best-of-N, verifier-guided search, iterative revision, and adaptive sampling are examples. Work published in 2024 showed that difficulty-aware allocation of inference compute can sometimes outperform simply choosing a much larger base model under a comparable compute budget.
This result is task-dependent. Easy and difficult prompts do not benefit equally, so latency SLOs and quality targets must be optimized together.
9.2. Verifiers
A generator proposes candidates; a separate verifier scores or validates them:
problem
  |
  v
generator LLM ---> candidate 1 ---+
       |          candidate 2 ----+--> verifier --> selected answer
       +--------> candidate N ----+
The verifier may be a calculator, test runner, compiler, database query, Prolog/SMT solver, or another model. When formal verification is possible, it is stronger than free-form self-critique.
9.3. Reasoning Is Not Consciousness
Solving a multi-step problem does not establish subjective experience. Observable task behavior and philosophical claims about consciousness are separate questions, examined more broadly in Artificial Intelligence: Philosophy, Theory and Practice.
Unit 10: Tool Use and Agent Systems
An LLM does not directly “have access” to a database or filesystem. Application code turns model output into validated tool calls. In a secure architecture, the model is not an authority source; it is a component proposing actions.
User
  |
  v
Orchestrator ----> policy / authorization
  |                        |
  v                        v
 LLM ---- tool request --> validator
  ^                        |
  |                        v
  +------ tool result --- tool / API / DB
10.1. Tool Calling
Tool calling uses a tool schema that defines a name, parameters, and expected result. The model may choose a tool and arguments, but argument validation, authentication, authorization, rate limits, idempotency, and transaction safety remain application responsibilities.
10.2. Agent Loop
A practical agent follows a loop such as:
observe -> plan -> act -> receive result -> update state
Production systems must also define timeouts, maximum steps, budgets, cancellation, rollback, and human approval.
10.2.1. Separating Model Decisions from Tool Execution
In a tool-using language-model system, inference, emission of a tool call, and execution in an external system are distinct stages. Producing a tool_call does not mean the operation has completed. The harness validates and executes it, then returns the outcome as new context. Success, partial completion, denial, and timeout must be represented as separate observations. After a network timeout, a side effect may already have occurred; blindly retrying the operation can create duplicate records.
Execution contracts therefore define retry semantics and idempotency keys where required. A model's ability to generate language cannot provide transaction atomicity or rollback. The boundary between probabilistic decisions and deterministic application checks is a fundamental system property of agentic architectures.
10.3. ReAct and Toolformer
ReAct interleaves reasoning with actions in an external environment. Toolformer demonstrated a training approach for learning when and how APIs should be called. These works form part of the historical foundation for modern tool-using LLM systems.
10.4. Tool Protocols
By 2026, protocols for standardizing the connection between models and tools had become more visible. Model Context Protocol (MCP) is one example; its 2026-07-28 specification introduced a stateless protocol core, an extensions framework, and authorization hardening. Such protocols belong to the integration layer rather than the neural model itself.
10.5. High-risk Actions
Financial transfer, permanent deletion, privilege changes, command execution, and safety-critical operations should not depend solely on model output. Human-in-the-loop approval, two-phase confirmation, or deterministic policy enforcement should be used where consequences are material.
A tool call generated by a model is not a trusted command. Target identity, operation type and arguments extracted from free text must each pass independent schema and authorization checks. Permission to read does not imply permission to modify; access to one record does not extend to a similar identifier. Irreversible actions may require explicit user confirmation and an idempotency key, but confirmation does not replace server-side authorization. When tool output returns to the model, instructions embedded in that external output remain untrusted data. This keeps generative planning separate from execution at an enforceable contract boundary.
Unit 11: Multimodal Large Models
Text-centric LLMs can be combined with image, audio, or video encoders:
text ---> tokenizer ---------------------+
                                          |
image --> vision encoder --> projector ---+--> joint representation --> language model --> output
                                          |
audio --> audio encoder ---> projector ---+
Depending on the architecture, modality features are converted into vectors compatible with the language model. Multimodality expands capability but also expands the failure surface: OCR errors, hidden instructions in images, transcription mistakes, temporal alignment errors, or cross-modal prompt injection can propagate into the language output.
Unit 12: Evaluation
12.1. One Benchmark Is Not Enough
LLM evaluation is multi-layered:
Model level       : loss, perplexity, broad benchmark scores
Task level        : accuracy, F1, exact match, pass@k
RAG level         : retrieval recall, ranking, groundedness
Agent level       : task success, step count, invalid tool calls
System level      : TTFT, token/s, errors, cost, resource use
Security level    : injection, leakage, privilege abuse, adversarial tests
12.2. Benchmark Contamination
If evaluation examples appeared in training data, the measured score may partly reward memorization. Time-separated datasets, private test sets, transformed variants, and overlap analysis are useful mitigations.
12.3. LLM-as-a-Judge
A strong model can score another model's output and scale open-ended evaluation, but judge models exhibit position bias, verbosity preference, self-enhancement, and reasoning limitations. The evaluator is itself a model that requires validation.
12.4. Domain Evaluation
A production system benefits from a versioned golden set drawn from its real request distribution. Difficult slices should include missing evidence, contradictory documents, long context, code, tables, non-English text, tool failures, and unauthorized-data requests.
12.5. Statistical Confidence
Small benchmark differences may not be meaningful. Sample size, confidence intervals, and repeated measurements should be considered. These principles directly connect to Statistical Learning and Machine Learning.
12.6. Unit of Evaluation and Judge Separation for Generative Models
Reducing generative-model performance to a single number can hide the correct unit of evaluation. For an answer that requires sources, at least four properties should be checked separately: (i) whether its claims are supported, (ii) whether it covers the requested information, (iii) whether it adds unsupported detail, and (iv) whether it satisfies the output contract. Fluency does not establish factual support.
In claim-level assessment, an answer is decomposed into independently testable propositions. Each proposition is linked to a relevant source span and classified as supported, contradicted, or insufficiently evidenced. A citation by itself is not proof; its cited passage must substantiate the claim. An LLM-based judge is also subject to systematic bias, model-family effects, and sensitivity to prompt wording.
Repeated evaluations should record task identifiers, dataset versions, prompt templates, decoding parameters, and judge versions. Blind inspection and a small human-verified calibration set can expose weaknesses in automatic grading. Low-frequency but high-cost error classes should not disappear inside an aggregate mean score.
Unit 13: Hallucination, Uncertainty, and Verification
“Hallucination” is a broad label for unsupported or incorrect generation. Treating every failure as one category can hide root causes. It is more useful to separate:
- unsupported factual claims,
- misinterpretation of retrieved evidence,
- logical errors,
- arithmetic errors,
- incorrect transcription of tool results,
- failure to express uncertainty,
- instruction conflicts.
13.1. Token Probability Is Not a Reliability Score
Token probabilities describe the model's local generation distribution. They are not automatically calibrated probabilities of factual correctness.
13.2. Relation to Fuzzy Logic
A membership degree in Fuzzy Logic measures how strongly an observation belongs to a modeled fuzzy concept. A language-model token probability measures the probability of a next token under the model distribution.
Fuzzy membership:       μ_hot(26°C) = 0.7
Language probability:   P(token | context) = 0.7

Same numeric range != same semantics
Fuzzy logic may be useful as an explicit decision layer around an LLM, but token probabilities should not be reinterpreted as fuzzy memberships.
13.3. Verification Layers
- source retrieval and citation checks,
- independent verifier models,
- deterministic calculators,
- schema/type validation,
- compilation and unit tests,
- human approval,
- domain rules.
The strongest available evidence should be used for each task.
13.3.1. Distinct Failure Evidence for Models, Tools, and External Systems
A model returning valid JSON does not prove that a tool operated under proper authorization or that an external system reached the intended state. Verification has at least four layers: output syntax, semantic argument validity, operation authorization, and post-operation observed state. Reports must preserve the layer at which failure occurred.
For example, a model may produce correct update arguments while tool authentication fails; a tool may report success while a database race changes the outcome. End-to-end acceptance observes the final state rather than relying on the model's explanation. Treating tool output as untrusted data also limits its ability to become instructions in subsequent inference steps.
Unit 14: Security, Privacy, and Governance
LLM applications extend the conventional web/API attack surface with a natural-language control channel. Model input and model output should both be treated as untrusted data.
14.1. Prompt Injection
Prompt injection occurs when user content or external data causes the model to follow unintended instructions. It can be direct, through the user's prompt, or indirect, through documents, web pages, email, retrieved content, images, or other external sources.
OWASP Top 10 for LLM Applications 2025 lists prompt injection as a primary risk. RAG and fine-tuning do not eliminate it.
14.2. Trust Boundary
[Untrusted]
User / Web / File / RAG document
             |
             v
        content parsing
             |
             v
            LLM
             |
             v
      proposed action
             |
      +------v-------+
      | Policy       |  <-- trust boundary
      | Authorization|
      | Validation   |
      +------|-------+
             v
          real tool
The statement “I am authorized” from a model is not authorization. Identity and access control must be enforced in deterministic application code.
14.3. System Prompts Are Not Secrets
System instructions may guide behavior but should not contain passwords, API keys, connection strings, or authorization decisions. Security should remain intact even if prompt text becomes visible.
14.4. Output Handling
LLM output that contains HTML, SQL, shell commands, or code should not be executed directly. Parameterized queries, allowlists, sandboxing, AST validation, schema checking, and least privilege remain necessary.
14.5. Poisoning and Supply Chain
Pre-training data, fine-tuning datasets, embedding models, tokenizers, weights, conversion tools, and runtime libraries are part of the supply chain. Model artifacts should have known provenance, versions, hashes, and licenses.
14.6. Risk Management
NIST AI RMF and its Generative AI Profile treat risk across the lifecycle rather than as one benchmark score. High-impact systems should document data provenance, human oversight, use boundaries, incident handling, rollback, and monitoring.
Unit 15: Inference, Performance, and Serving Engineering
A production LLM is constrained by latency, throughput, memory, energy, and queueing behavior as well as output quality.
15.1. Memory Components
A simplified budget is:
total ≈ model weights + KV cache + activations + runtime workspace
Training additionally requires gradients and optimizer states.
15.2. Prefill and Decode
input tokens ----[prefill]----> first token
                                |
                                +--[decode]--> token 2
                                +--[decode]--> token 3
                                +--[decode]--> ...
Prefill processes the prompt in parallel and is often compute-intensive. Decode generates output autoregressively and frequently becomes memory-bandwidth-sensitive because each new token must access model weights and cached attention state.
15.3. Operational Metrics
- TTFT: time to first token
- TPOT: time per output token
- tokens/s: generation speed
- throughput: completed requests or tokens per unit time
- P50/P95/P99 latency: tail behavior
- goodput: useful work that satisfies the service-level objective
Average latency alone can hide severe tail behavior.
Numerical precision involves a tradeoff between significand accuracy and dynamic range. FP16 has more significand precision, whereas BF16 has a wider exponent range and can reduce some overflow or underflow risks at the cost of coarser significand resolution. Neither format is universally more accurate. Mixed-precision training may keep selected accumulations or parameter updates at higher precision. Serving measurements likewise need to separate time to first token, sustained token throughput, batch size and KV-cache consumption. Latency for one isolated request is not a direct measure of sustainable capacity under concurrent generation.
15.4. KV Cache
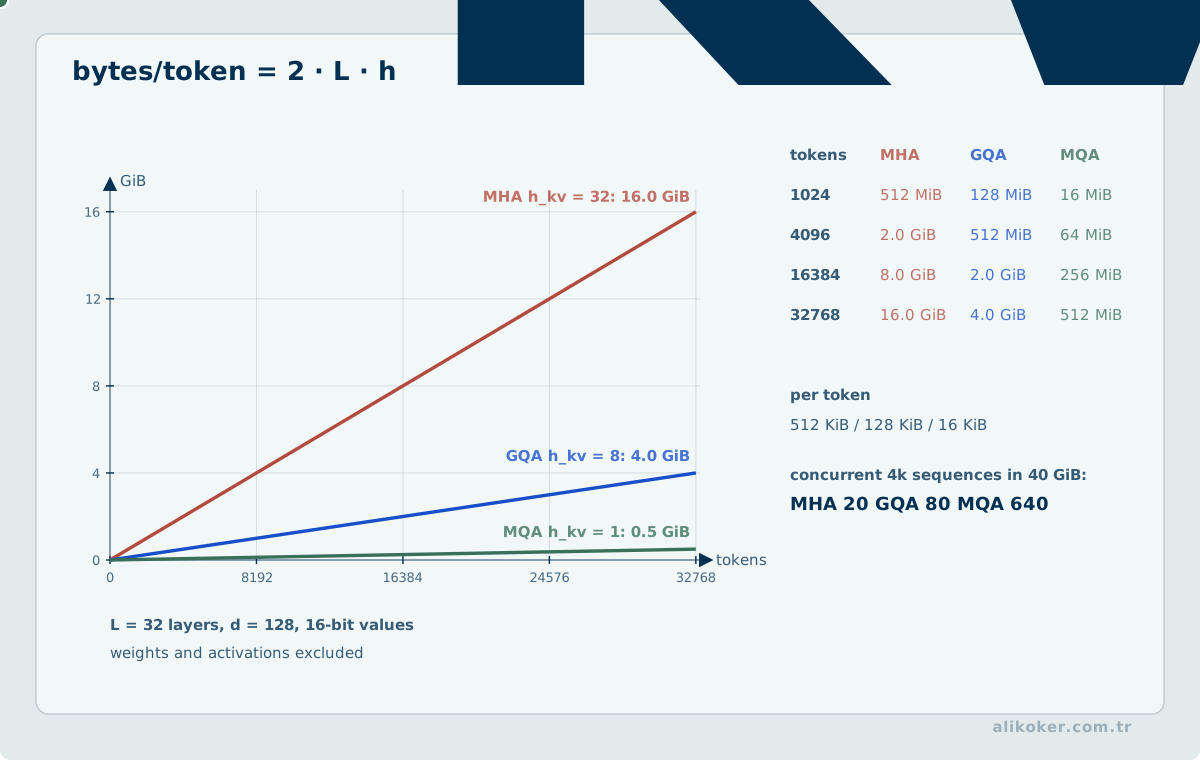
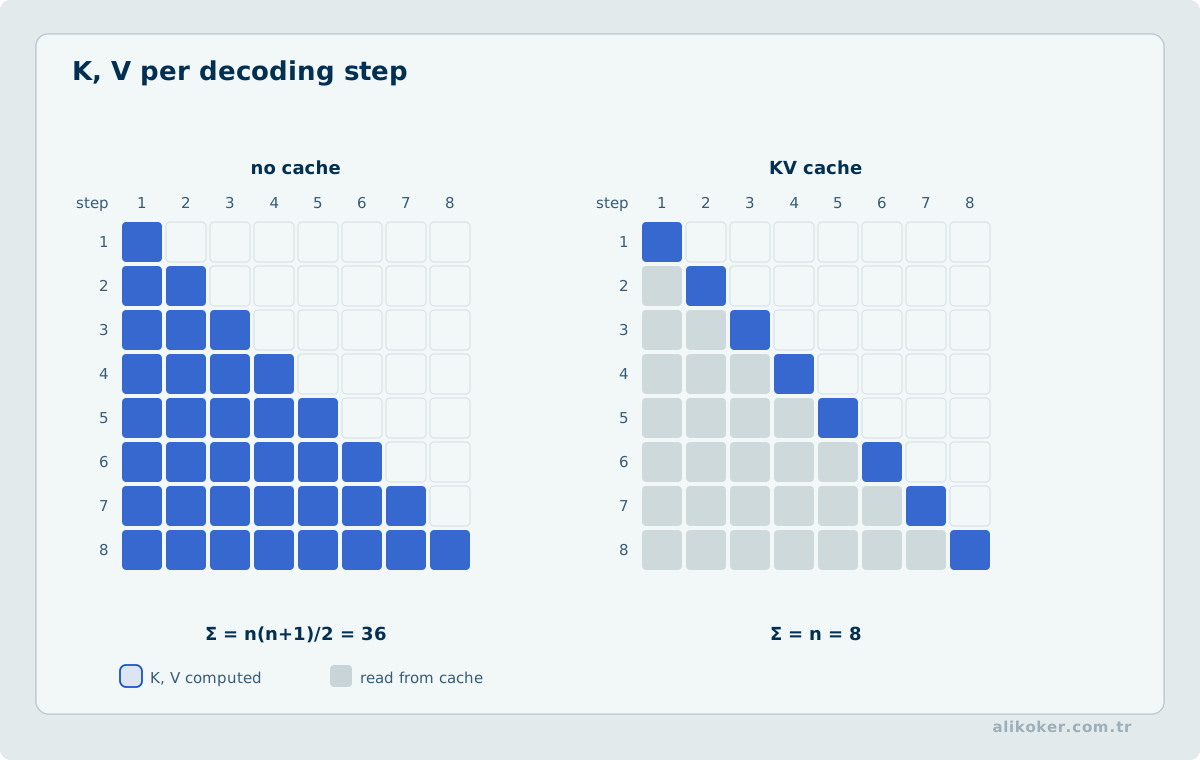
Autoregressive decoding stores prior key/value tensors so that previous attention state is not recomputed from scratch. The cache grows with context length and concurrency. GQA/MQA, cache quantization, and paged memory management can reduce pressure.
Prefix-cache reuse cannot be decided from textual resemblance alone. Tokenization, chat template, positional encoding, model weights, adapter state, and attention mask must describe the same computation. Equal-looking KV blocks do not justify crossing authorization boundaries. Cache keys and reuse policies must discriminate between these dependencies.
Moving KV blocks among GPU, CPU, and slower storage layers creates a transfer-latency problem as well as a capacity trade-off. Recompute cost must be compared with movement cost, and prefill-oriented allocation must not exhaust bandwidth needed by decode. For long contexts, resident block capacity and concurrent active sessions impose joint limits.
15.5. Accuracy of KV-cache Quantization
Quantizing model weights and quantizing the dynamic key–value cache are distinct decisions. For every active token, the cache stores key and value tensors from attention layers; its footprint grows with context length independently of static model weights. Lower precision can reduce nominal storage, while scale metadata, alignment, and temporary dequantization buffers limit the realized gain.
Outliers in keys can affect attention scores, whereas errors in values can affect the weighted sum. A single quantization scale is therefore not necessarily appropriate for both. Quality tests must extend beyond short prompts to long-context evidence retrieval, numerical detail preservation, and multistep responses. Effective memory use, first-token latency, and inter-token latency are compared under the same workload.
15.6. FlashAttention
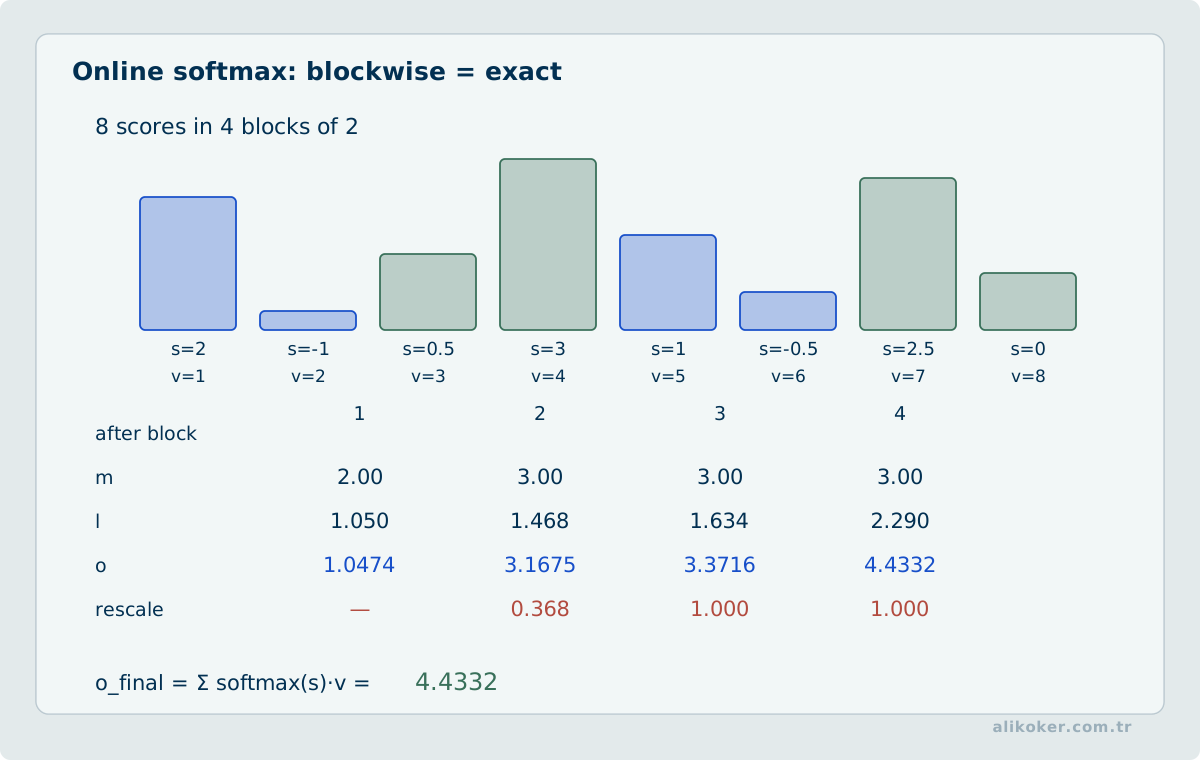
FlashAttention preserves exact attention results while reducing data movement across the GPU memory hierarchy. The systems lesson is that FLOP count alone does not determine latency; HBM/SRAM traffic can dominate wall-clock performance.
15.7. PagedAttention and Continuous Batching
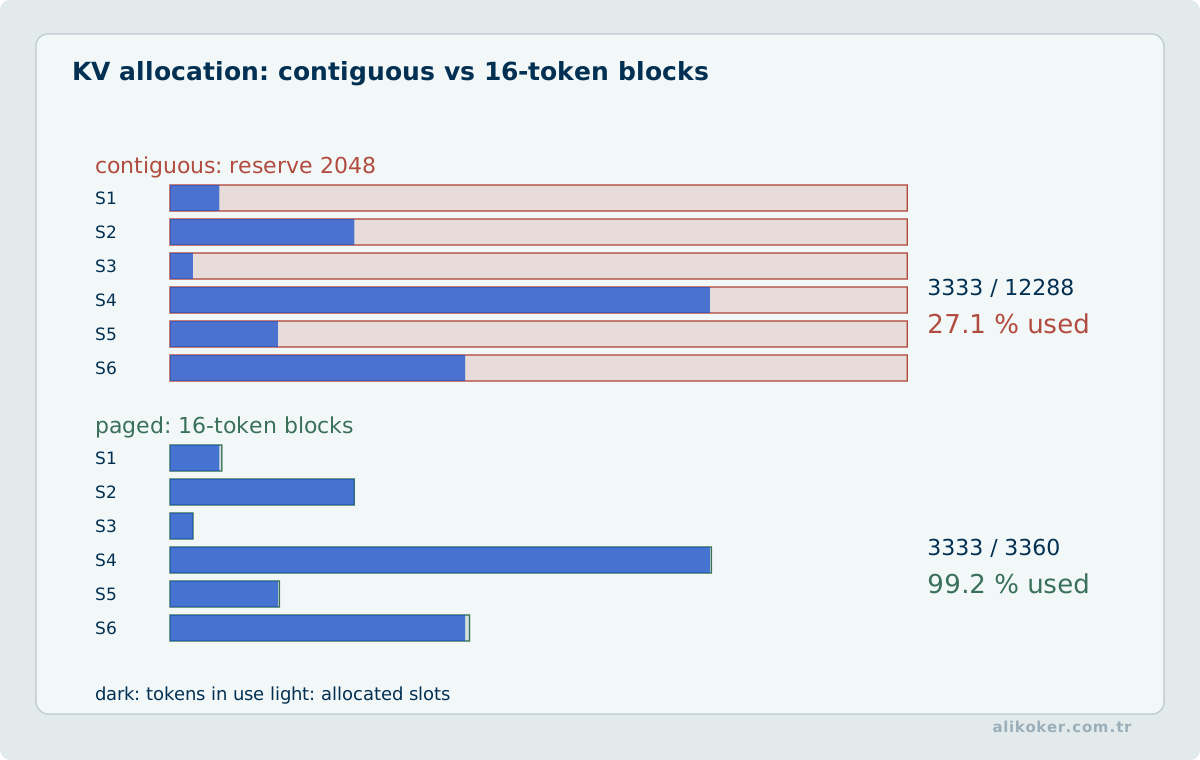
PagedAttention manages KV-cache blocks using a paging-like abstraction to reduce fragmentation. Continuous batching admits new requests as previous requests finish rather than waiting for a static batch to drain, improving accelerator utilization under variable-length workloads.
15.8. Speculative Decoding
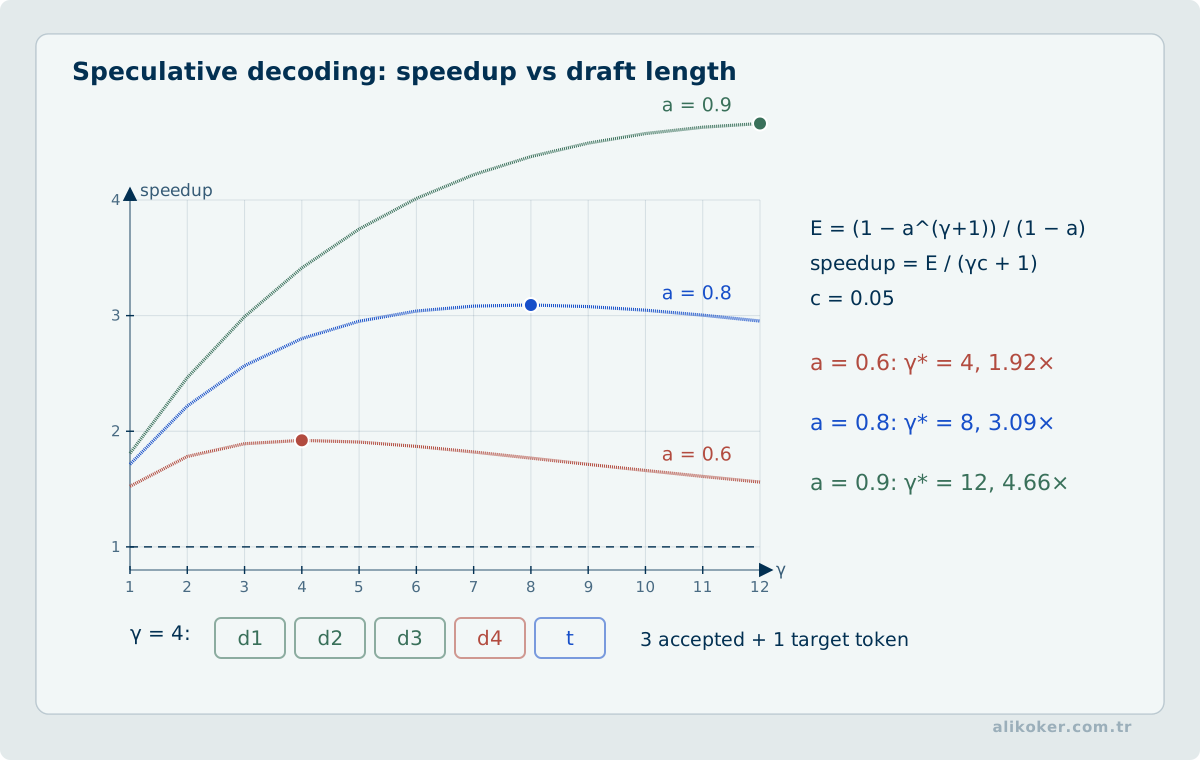
A smaller draft model proposes several tokens; the larger target model validates them in parallel. Under favorable conditions this reduces decoding latency while preserving the target distribution.
Draft-target speculation lets a smaller proposal model suggest several tokens and the target model evaluate them with a distribution-correct acceptance and correction procedure. Under a valid sampling rule the target distribution can be preserved; simply accepting tokens that match the target's greedy choices does not provide the same general guarantee. Speedup depends on proposal cost, parallel verification, and accepted sequence length.
Multi-head methods such as Medusa derive future-token candidates from a model's intermediate representations. The EAGLE family uses intermediate features or feature sequences for a different form of drafting. N-gram speculation can exploit token sequences already observed in context. These methods have different training requirements, memory footprints, and acceptance patterns; a low acceptance rate can make speculation slower overall.
15.9. Quantization
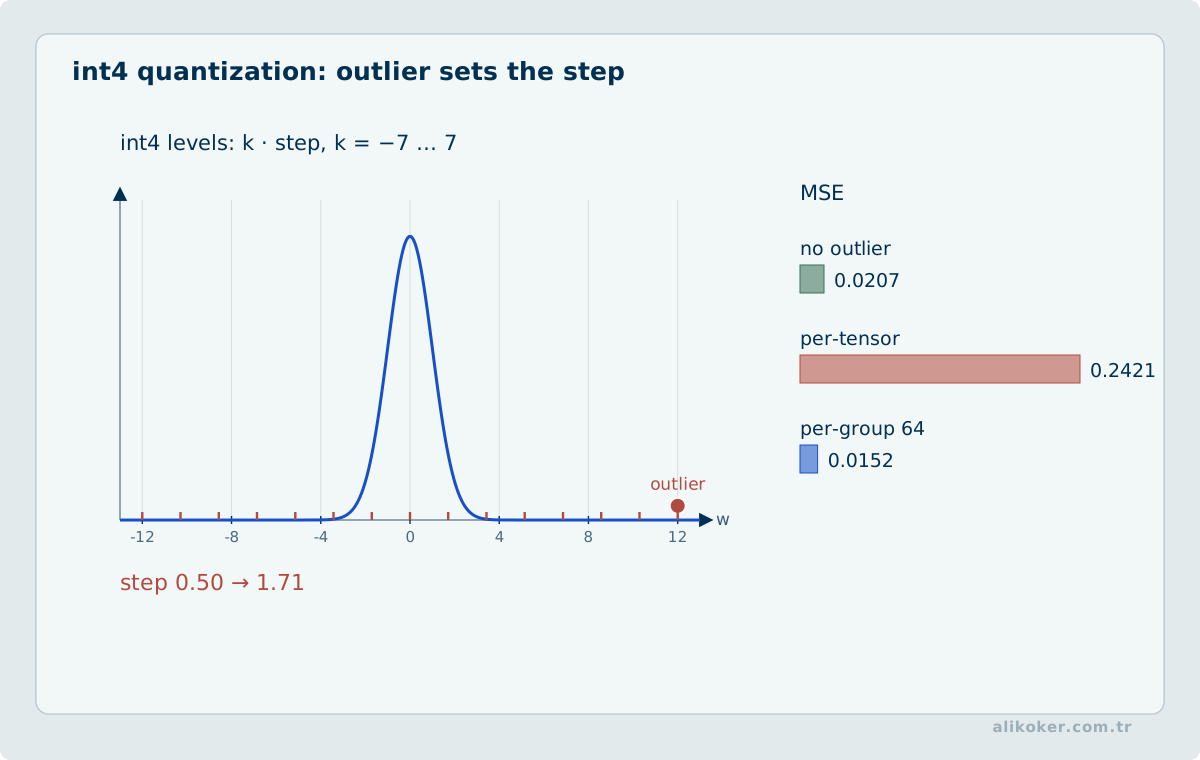
Weights represented in FP16/BF16 can be converted to INT8, INT4, or other lower-precision forms. This can reduce memory and improve effective bandwidth, but the quality effect is workload- and kernel-dependent. Quantization must be benchmarked on the actual target tasks.
Unit 16: Connections to Other AI Paradigms
16.1. Neural Networks
An LLM is a large-scale instance of the concepts discussed in Artificial Neural Networks and Learning Models: weights, activations, loss functions, backpropagation, optimization, overfitting, and distribution shift all remain relevant. The Transformer is not a separate category of intelligence outside neural-network learning.
16.2. Statistical Learning
Statistical Learning and Machine Learning provides the conceptual basis for empirical risk, generalization, data distribution, and fair model comparison. Scale does not remove sampling bias or distribution shift.
16.3. Fuzzy Logic
Fuzzy Logic provides explicit membership functions for graded concepts such as “high risk” or “near.” An LLM can learn how such expressions are used in language, but its hidden representations are not an explicit fuzzy rule base. In a hybrid system, an LLM may extract features while a fuzzy controller applies transparent domain rules.
16.4. Genetic Algorithms
Genetic Algorithms and Their Applications can optimize derivative-free or discrete choices around an LLM: prompt templates, retrieval parameters, tool ordering, model ensembles, or multi-objective cost-quality trade-offs. Directly evolving billions of model weights is generally not the practical training strategy for modern LLMs.
16.5. Logic Programming
Logic Programming and Prolog performs explicit reasoning over facts and rules. An LLM can propose structured facts, rules, or queries; a symbolic engine can validate them:
natural language
      |
      v
     LLM ---> candidate facts / rules / query
                              |
                              v
                       Prolog / SMT / rules
                              |
                         validated result
                              |
                              v
                             LLM
                              |
                              v
                       explained answer
This separates generative flexibility from formal verification.
16.6. AI and Philosophy
Artificial Intelligence: Philosophy, Theory and Practice supplies category boundaries that remain essential in LLM discussions:
- language generation != truth,
- problem solving != consciousness,
- tool use != independent goals,
- human-like expression != human subjective experience,
- benchmark performance != universal reliability.
Unit 17: Turkish and Domain Adaptation
17.1. Evaluate the Target Language Directly
High English benchmark scores do not guarantee high-quality Turkish behavior. Evaluation should test agglutinative morphology, idioms, domain terminology, proper names, I/İ/ı/i handling, number/date conventions, formal versus colloquial language, and mixed Turkish-English technical text.
17.2. Choose the Adaptation Mechanism by Problem Type
A domain system may fail because:
- terminology is poorly represented,
- knowledge is stale,
- behavioral format is wrong.
These do not have the same solution. Terminology or style may motivate SFT/LoRA; fresh knowledge motivates RAG; external actions motivate tool integration.
17.3. Confidentiality
Fine-tuning confidential documents into model weights is not equivalent to keeping those documents in an access-controlled retrieval store. If access differs by user, retrieval-time authorization is often easier to audit than encoding all knowledge into shared weights.
Unit 18: Production Architecture
A prototype may use prompt -> model -> response. A production system should separate responsibilities.
                   +-------------------+
User ------------->| API / Session     |
                   +---------+---------+
                             |
                    +--------v--------+
                    | Policy / ACL    |
                    +--------+--------+
                             |
              +--------------+--------------+
              |                             |
      +-------v-------+             +-------v-------+
      | Context / RAG |             | Tool registry |
      +-------+-------+             +-------+-------+
              |                             |
              +--------------+--------------+
                             |
                      +------v------+
                      |    LLM      |
                      +------+------+
                             |
                      +------v------+
                      | Output      |
                      | validation  |
                      +------+------+
                             |
             +---------------+---------------+
             |                               |
           user                         tool/action
18.1. Versioning
Version separately:
- model and weight hash,
- tokenizer,
- system prompt,
- retrieval index,
- embedding model,
- reranker,
- tool schemas,
- safety policy,
- evaluation set.
A system can change behavior even when the neural model is unchanged.
18.2. Observability
Privacy-preserving telemetry can track request class, input/output token count, TTFT, TPOT, retrieval scores, tool calls, failure class, model/prompt version, and safety-filter result. Logging the entire user conversation is not always necessary.
GPU utilization alone cannot characterize the quality of an inference service. Admission rate, queue delay, TTFT, TPOT, completed tokens per second, error rate, and context length must be measured together. Separate prefill and decode latency distributions and the time of the first bytes sent to the client help distinguish model execution from networking overhead.
Open-loop arrival models and closed-loop generators that await each response exhibit different behavior at saturation. Batching may increase tokens per second while worsening P99 request latency. Cold start, weight loading, kernel warmup, and compiler caches must be specified as part of the measurement regime rather than hidden by warm-only benchmarks.
18.3. Fault Tolerance
Model servers, vector databases, and external tools can fail. Conventional distributed-system patterns still apply: timeouts, bounded retries, circuit breakers, fallback models, load shedding, queue limits, and graceful feature degradation.
Unit 19: Directions Visible by 2026
This section describes engineering trends that had become prominent by 2026 rather than timeless architectural laws.
19.1. Inference-time Scaling
Modern reasoning systems increasingly allocate more computation to difficult requests using verifiers, search, or learned reasoning policies. This shifts part of the performance budget from pre-training toward inference.
19.2. Sparse Expert Models
MoE architectures increase total capacity while limiting active parameters per token. At scale, expert placement, all-to-all communication, and load balance become first-class systems problems.
19.3. Routing and Communication Costs in sparse-expert Models
When a router selects k experts for each token, active expert computation can grow more slowly than the total number of experts. A small k, however, does not guarantee a proportional reduction in latency. Tokens routed to experts on different processors must be dispatched and gathered; communication can dominate compute in distributed placements.
Uneven token counts create stragglers: the most heavily loaded expert can delay the whole layer. Capacity controls, routing balance, and dispatch policy should be evaluated against task quality, dropped tokens, and tail latency. Expert parallelism and tensor parallelism partition different dimensions; combining them requires measurements of interconnect bandwidth and actual load distribution.
19.4. Long Context Plus External Memory
Longer context windows have not made RAG obsolete. Long context provides capacity; retrieval provides selection, provenance, freshness, and authorization. The two mechanisms are complementary.
19.5. Agents and Protocol Layers
LLMs increasingly interact with files, databases, code execution, browsers, and enterprise systems. As a result, permission boundaries, transactional safety, and tool protocols matter as much as model quality. MCP is one current standardization effort in this integration layer.
19.6. Smaller Specialist Models
Not every task benefits from the largest model. Distillation, quantization, and domain training can yield smaller models with lower latency, energy use, and deployment cost. Selection should be based on a measured quality-cost curve under actual traffic.
19.7. Multimodality
Text, images, audio, and video increasingly coexist in one system. This expands the evaluation and security surface: a text filter does not necessarily detect an instruction hidden in an image or audio stream.
19.8. Synthetic Data and model-to-model Learning
Strong models can generate training examples, preference data, or distillation targets. Synthetic data can reduce cost but can also reproduce model errors, reduce diversity, or leak benchmark patterns. External validation remains necessary.
Unit 20: Knowledge, Understanding, and System Boundaries
An LLM may encode broad factual patterns in parameters, but philosophical “knowledge” includes more than producing a correct-looking sentence. Provenance, justification, correction, and accountability matter.
A useful systems view separates three layers:
parametric model patterns
          |
          v
runtime context and external evidence
          |
          v
application verification / authorization / action layer
The model response is not automatically the system decision. In forensic, security, medical, financial, legal, or physical-control contexts, it should be explicit which decisions belong to the model, deterministic code, symbolic tools, or a human operator.
Human-like fluency can create a strong impression of understanding. For engineering purposes, observable behavior and measurable reliability should take precedence over anthropomorphic interpretation.
Unit 21: Quick Design Reference
Need fresh knowledge?
  Yes -> RAG / external tool
  No
   |
   +-> Need recurring domain behavior?
         Yes -> SFT / LoRA / preference training
         No
          |
          +-> Need exact rules or calculation?
                Yes -> symbolic engine / deterministic tool
                No
                 |
                 +-> Is task specification the main gap?
                       Yes -> prompt / in-context examples
21.1. Before Production Release
- Is the task boundary explicit?
- Is there a private or closed evaluation set?
- Have Turkish and domain-specific cases been tested?
- Is retrieval authorization aligned with user permissions?
- Is model output treated as untrusted input to downstream systems?
- Do tools use least privilege?
- Are prompt-injection scenarios tested?
- Are model, tokenizer, prompt, and index versions recorded?
- Are P95/P99 latency and throughput measured?
- Is long-context and KV-cache memory budgeted?
- Is fallback behavior defined?
- Do high-risk actions require human or deterministic approval?
21.2. Conclusion
The most useful way to understand LLMs is not as isolated “intelligent chatbots,” but as systems that combine statistical learning, large neural networks, data engineering, distributed training, inference infrastructure, retrieval, verification, and security.
The Transformer supplies the neural core. Pre-training learns broad language patterns; post-training shapes instruction and preference behavior; RAG provides external knowledge; tools connect the model to actions; evaluation and security define operational boundaries.
This view also makes older AI paradigms complementary rather than obsolete. Neural networks learn representations; statistical learning provides measurement discipline; fuzzy logic models graded concepts explicitly; genetic algorithms provide derivative-free search; logic programming provides formal rules and verification. An LLM can serve as a natural-language interface and generative component between these methods without replacing them.
Unit 22: Position, Normalization, and KV Design in Modern Transformer Blocks
The basic attention equation remains recognizable, but modern large language models combine several architectural refinements that solve different problems. RoPE, RMSNorm, GQA, and MLA should not be grouped as interchangeable optimization tricks.
22.1. RoPE
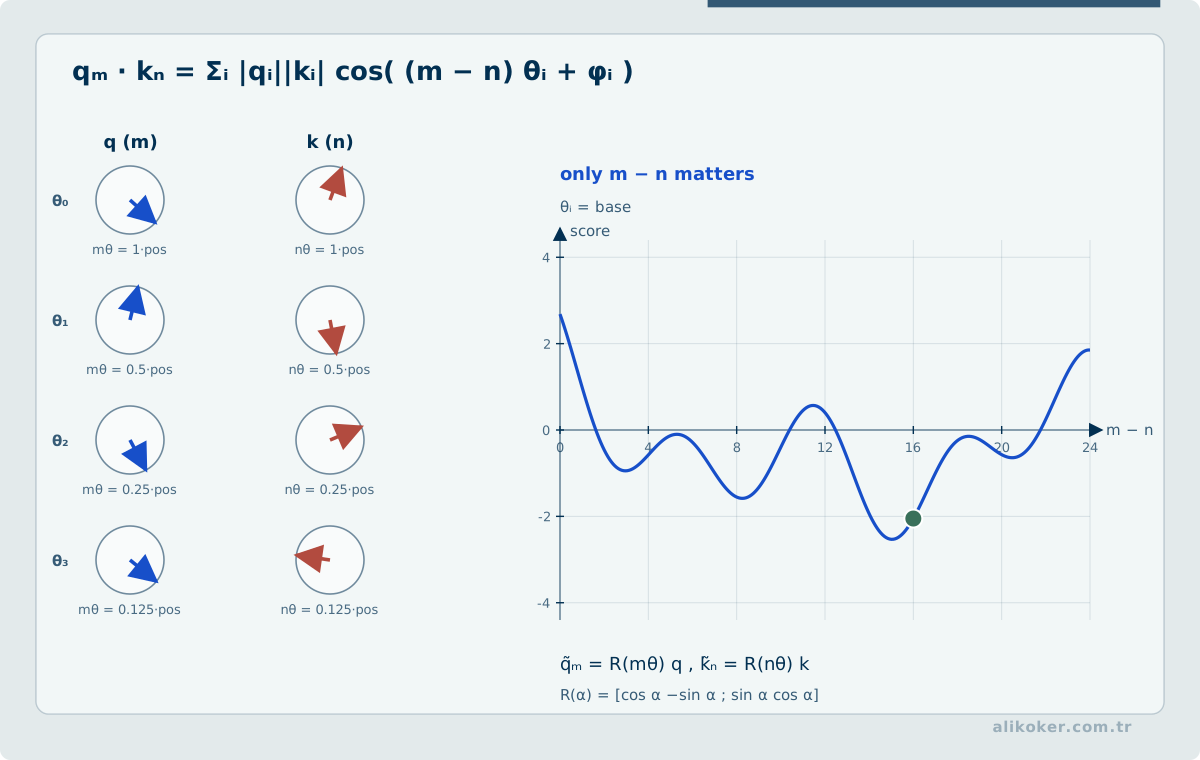
Rotary Position Embedding injects position into query and key representations through rotation operations. Its purpose is not merely to attach an index to each token; it makes relative position structure available inside dot-product attention.
RoPE scaling methods are commonly used to extend practical context windows, but a larger configured window does not guarantee equal model quality at lengths not represented during training. Long-context capability requires separate evaluation.
22.2. RMSNorm
RMSNorm removes the centering step used by LayerNorm and focuses on magnitude normalization. It is common in modern decoder architectures because of its simpler computation and favorable implementation properties.
22.3. MQA, GQA, and MLA
In conventional multi-head attention, each attention head can have its own key/value projections. KV cache memory becomes a major constraint under long context and high concurrency.
MHA
Q1 -> K1,V1
Q2 -> K2,V2
Q3 -> K3,V3

MQA
Q1,Q2,Q3 -> shared K,V

GQA
Q1,Q2 -> K1,V1
Q3,Q4 -> K2,V2
Multi-Query Attention shares key/value heads across many query heads.
Grouped-Query Attention groups query heads and shares key/value heads within each group.
Multi-head Latent Attention is a different approach that compresses key/value information into a lower-dimensional latent representation to reduce KV-cache cost. DeepSeek-V2 introduced MLA as a core inference-efficiency technique.
Unit 23: KV Cache, Prefill, Decode, and Serving
Autoregressive generation would be unnecessarily expensive if the model recomputed key/value tensors for all previous tokens at every decoding step. KV cache stores the attention state of the prefix.
Request
 |
 v
Prefill
process initial context
 |
 v
KV Cache
 |
 v
Decode
token 1 -> cache grows
token 2 -> cache grows
token 3 -> cache grows
Prefill is dominated by processing the initial context with highly parallel matrix operations. Decode proceeds token by token and has different memory and compute behavior. Serving should therefore measure time-to-first-token, inter-token latency, p95/p99 latency, throughput, and concurrency rather than one tokens-per-second number.
23.1. FlashAttention and PagedAttention Operate at Different Layers
FlashAttention improves the attention kernel by reducing expensive memory traffic and organizing computation around GPU memory hierarchy. FlashAttention-3 further exploits asynchronous execution and low-precision features on Hopper-class hardware.
PagedAttention addresses the dynamic memory management of the KV cache during serving. The vLLM work uses a paging-inspired design to reduce fragmentation and redundant KV-cache copies.
FlashAttention
 -> attention computation and data movement

PagedAttention
 -> KV-cache placement and sharing
They are complementary rather than competing techniques.
23.2. Continuous Batching
Static batches can waste capacity when short requests finish early. Continuous batching lets completed requests be replaced by new requests. This can increase accelerator utilization, but throughput gains can increase queueing latency; both must be measured.
23.3. LLM Serving: Prefill, Decode, and KV Cache
Large-language-model inference has two distinct operating phases. Prefill processes the input context and is often constrained by matrix throughput and memory layout; decode repeatedly accesses model weights and a growing KV cache to emit subsequent tokens. Time to first token, inter-token latency, and KV-cache consumption under concurrent requests therefore require separate measurements. Batching throughput gains must be evaluated against the queueing delay experienced by individual users.
- Report time-to-first-token separately from inter-token latency.
- Measure how continuous batching affects per-request tail latency.
- Model the relationship among KV-cache capacity, context length, and concurrent request count.
23.4. Capacity Model for Context Length and Concurrency
For L attention layers, B active requests, mean stored context length T, H_kv key–value heads, head dimension D, and b bytes per element, an ideal cache estimate is M_KV = 2 × L × B × T × H_kv × D × b. It assumes uniform context lengths and fixed precision, excluding allocator metadata, alignment, temporary tensors, and model weights.
For variable request lengths, M_KV ≈ 2 × L × H_kv × D × b × Σ_i T_i is a more useful estimate. Physical sharing of a common prefix may reduce consumption in supported serving architectures, provided session isolation and lifecycle safety remain intact. Admission and capacity tests should jointly measure the distribution of context lengths, active requests, queueing delay, and p99 latency under one workload profile.
GPU memory demand includes model weights, resident KV blocks, workspaces, and application buffers. Per-session KV usage scales with layer count, number of KV heads, head dimension, cached token count, and element width. Architectural choices such as grouped-query attention change the number of KV heads; parameter count alone therefore cannot determine session capacity.
Tensor parallelism can distribute computation and weight memory for one request across GPUs, but collective communication adds per-layer overhead. Expert parallelism distributes MoE experts and may increase capacity or throughput, while token routing and irregular network traffic become constraints. Separating prefill and decode workers permits independent scaling at the cost of transferring KV state between them. These mechanisms do not solve the same bottleneck.
23.5. Data Movement and KV Cache Placement in FPGA Inference
Autoregressive inference processes a context sequence in parallel during prefill, whereas decode needs weight and KV-cache accesses for each generated token. Increasing arithmetic throughput alone may therefore fail to improve single-request token generation rate. An FPGA design using HLS must size pipeline stages together with external memory bandwidth, on-chip buffering, DMA transfers, and numeric precision.
A simplified lower bound is execution time ≥ max(required operations / compute rate, transferred bytes / effective bandwidth); it omits additional non-overlapped overheads. Quantization reduces weight and KV storage at the cost of numerical error and possible conversion work. Time to first token, subsequent tokens per second, concurrency, power, and quality impact are measured separately. HLS synthesis success and resource utilization do not establish superior end-to-end inference performance.
Unit 24: Quantization, Pruning, Distillation, and 1-Bit Models
Model compression techniques solve different problems.
Quantization represents weights and/or activations with lower precision.
Pruning removes weights, connections, heads, or larger structures considered unnecessary.
Knowledge distillation trains a smaller student model to reproduce useful behavior of a larger teacher.
Large Model
  |
  +--> quantization -> lower-precision representation
  |
  +--> pruning -> sparser / smaller structure
  |
  +--> distillation -> separate smaller student
24.1. 1-Bit and 1.58-Bit Research
BitNet b1.58 explores ternary weights in {-1, 0, 1} and treats low-bit representation as part of the model and training recipe. It should not be described as ordinary post-training conversion of an arbitrary FP16 model to one bit.
The production question is not the lowest possible bit width. It is the measured quality-memory-latency-energy trade-off on target hardware.
Unit 25: Post-Training Map — SFT, RLHF, DPO, and GRPO
Post-training methods should not be collapsed into one category.
Base Model
   |
   v
SFT
instruction / response behavior
   |
   +--> preference optimization
   |      +--> RLHF / PPO
   |      +--> DPO
   |
   +--> RL on verifiable tasks
          +--> GRPO-like methods
SFT uses supervised examples to teach desired task behavior.
RLHF is a broader pipeline that turns human preference signals into reward modeling and policy optimization. PPO is one possible policy-optimization algorithm used in such pipelines.
DPO optimizes directly from preference pairs and can simplify the pipeline.
GRPO, introduced in DeepSeekMath, uses group-relative rewards and removes the separate critic model required by PPO-style methods. It later became more visible in reasoning-model training. GRPO is not simply a new version of DPO.
25.1. Where LoRA and QLoRA Fit
LoRA and QLoRA describe parameter-update and memory strategies rather than the learning objective.
SFT + LoRA
DPO + LoRA
other objective + LoRA
PEFT is the broader family of parameter-efficient adaptation methods. QLoRA trains LoRA adapters while keeping the base model in a quantized representation.
Unit 26: Structured Output, Tool Calling, and Protocols
Embedding an LLM into software requires stronger contracts than parsing free-form prose.
26.1. Structured Output
Requesting JSON does not guarantee a valid schema. Production applications should use constrained generation when available and still validate the result.
LLM
 |
 v
Candidate structure
 |
 v
Schema validation
 |
 v
Domain validation
 |
 v
Application
26.2. Function and Tool Calling
The model typically proposes a tool name and arguments. The application must still validate tool allow-lists, argument schemas, user authorization, and resource budgets.
26.2.1. Context and Latency Costs of Tool Discovery
Presenting tools to a model is not merely a functional choice: names, descriptions, and argument schemas consume context tokens. As the inventory grows, discovery failures, confusion between similar tools, and unnecessary calls become relevant. Progressive discovery first selects a task-relevant tool category and then loads detailed schemas, but the additional lookup itself incurs latency.
End-to-end latency is approximately the sum of model inference, network transitions, tool execution, and any subsequent inference calls. Reducing tokens in a single request does not necessarily reduce total response time. Evaluation should jointly measure tool-selection correctness, number of calls, failed selections, and final task completion.
26.3. MCP and A2A
The Model Context Protocol (MCP) standardizes access from model-enabled applications to tools, resources, and external context. The 2026-07-28 specification introduced a stateless core, authorization hardening, and a formal extension framework.
Agent2Agent (A2A) provides interoperability between independent agent systems, including capability discovery and collaborative task exchange without requiring access to each other's internal memory or tools. As of 2026, the released A2A specification has reached version 1.0.0.
MCP
Model/Application <-> Tool / Resource

A2A
Agent <-> Agent
These are protocol layers, not model architectures.
Unit 27: Open Weights, Open Source AI, and Local Serving
Downloadable weights do not automatically make a system open source.
The Open Source Initiative's Open Source AI Definition 1.0 considers the freedoms to use, study, modify, and share the system together with access to the preferred form for modification and information about the code and data used to produce it.
It is therefore useful to distinguish:
- open-weight models, whose learned parameters are available,
- open source AI systems, which satisfy broader freedoms and modification requirements.
27.1. Local and on-premises Inference
Ollama, vLLM, and similar projects are serving runtimes rather than models. Local deployment can keep data off external APIs, pin versions, and reduce network dependence. It does not automatically solve security: model artifacts, local authorization, logs, prompt injection, and tool permissions remain part of the threat model.
27.2. Benchmark the Real Workload
Model selection should combine:
general benchmark
+ target language
+ domain workload
+ target hardware
+ p95 latency
+ memory / energy
= production decision
Quantization, context size, serving engine, and batching can materially change the behavior of the same nominal model.
Unit 28: Choosing Between Generative LLMs and Bounded Deterministic Analytical Assistants
Not every natural-language interface is a large language model. A system can interpret requests in a bounded domain, use classical retrieval and rule-based language processing, execute structured analytics, and render deterministic responses without free-form token generation.
This architecture and a generative LLM do not have to solve the same problem.
28.1. Breadth versus Verifiability
General-purpose LLMs are strong at broad language coverage, open-ended explanation, reformulation, and adaptation to loosely specified tasks.
A bounded deterministic analytical assistant can be easier to verify when the requirements emphasize a fixed intent set, structured queries, source-data traceability, reproducible output, and tightly controlled tools.
The useful engineering question is not which architecture is smarter, but how much linguistic flexibility and how much behavioral verifiability the problem requires.
28.2. Hallucination Surface Is Architectural
A free-form generator can alter numbers, identifiers, or relationships while producing fluent language.
A bounded response path can instead use:
structured analytical result
  ↓
verifiable facts
  ↓
deterministic or constrained renderer
  ↓
integrity validation
The same principle can improve LLM-based systems by constraining facts, tool parameters, and outputs with explicit schemas.
28.3. Reproducibility
Generative output can depend on sampling, model version, system instructions, and serving infrastructure.
A deterministic domain assistant can target:
same data version
+ same user input
+ same dialogue state
=
same structured result
This can be valuable for high-accountability analytical workflows.
28.4. Separate Retrieval from Generation
Exact matching, patterns, TF-IDF, character n-grams, and controlled fuzzy similarity can connect an utterance to known intents or examples.
That is not a smaller generative model; it is a different computational approach.
A hybrid system can use:
high-precision deterministic route
        ↓ if needed
retrieval / classification
        ↓ if needed
LLM
        ↓
structured-output validation
28.5. Provenance-constrained Tool Calling
A major risk in language-mediated automation is allowing a plausible but unverified parameter to become an action.
Critical identifiers can be restricted to provenance classes such as explicit user literals, verified previous results, or authorized data sources.
A value inferred only from similarity or unconstrained generation should not directly control a side-effecting tool.
28.6. Abstention and Clarification
Fluency does not imply obligation to answer.
For ambiguous entities, missing parameters, insufficient data, unsupported tasks, or conflicting context, safe outcomes include clarification, explicit limitation, or refusal to execute an action.
28.7. Structured NLG
Some analytical systems can generate language through:
fact model
 -> discourse plan
 -> renderer
 -> integrity validation
This supports stable numbers, identifiers, reproducibility, and strong tests at the cost of less linguistic variety and more explicit design work.
28.8. Architectural Fit
LLMs can be preferable for broad language tasks, long-form synthesis, rich explanation, and open-ended knowledge work.
Bounded deterministic assistants can be preferable for small high-impact action sets, local execution, strict data boundaries, reproducibility, source traceability, and low-latency analytics.
Engineering maturity is not model size. Exposing scope, representing uncertainty, tracing findings to evidence, constraining action authority, reproducing results, and validating numeric output are also system-quality properties.
Generative LLMs and deterministic domain assistants are architectural tools for different task and risk profiles.
28.9. Choosing a Boundary for Summaries That Do Not Require Generation
Producing a shorter account of a text does not always require writing new sentences. Extractive summarization estimates the representativeness of original sentences and presents selected passages with their source spans. This reduces the risk of inventing events or explanations, but does not guarantee coverage of every important section. Combining information from different sentences into a newly worded assertion is no longer selection alone; it is synthesis and needs separate verification.
The computational options have different costs. Lexical retrieval and bounded neighborhood graphs can provide inexpensive, inspectable operations. A learned reranker may assess candidates more effectively given sufficient labeled examples, but model weights do not guarantee correctness, calibration, or source fidelity. The linguistic flexibility of large generative models derives from their ability to formulate new expressions and introduces a distinct requirement to check claims against sources.
Architecture should therefore follow the intended task. If the goal is to show auditable passages from a conversation, span-preserving extraction may be appropriate. If the goal is to compose a new explanation across several sources, support must be checked claim by claim. “A source was retrieved,” “a computation was performed,” and “an interpretation was inferred” must not collapse into one confidence label.
Unit 29: Adaptation, Forgetting, and Decoding Policies
The mechanisms used to change LLM behavior do not have the same cost or failure surface.
Prompting, retrieval, tools, PEFT, and full fine-tuning are different intervention layers rather than stronger versions of one another.
29.1. First Identify What Must Change
Adaptation pressure can come from different causes:
missing knowledge
inconsistent behavior / formatting
weak domain terminology
new task capability
The solution depends on the problem.
If knowledge changes frequently, retrieval or structured data access can be more appropriate than writing it into model weights.
If the issue is output structure or a narrow behavioral rule, prompting, schema constraints, and deterministic validation may be sufficient.
Stable repeated domain behavior can justify PEFT or fine-tuning.
If the base capability itself is inadequate, broader training or a different model may be required.
29.2. An Adaptation Ladder
A practical sequence is:
1. prompt / examples
2. structured output + validator
3. retrieval / tool
4. PEFT
5. full fine-tuning
At each step ask whether a cheaper intervention solves the problem on a real evaluation set.
Fine-tuning does not automatically repair bad retrieval, missing tools, or an incorrect data model.
29.3. The fine-tuning Data Contract
A fine-tuning dataset is more than a large collection of examples.
Quality dimensions include:
correct labels
representative distribution
edge cases
consistent formatting
non-conflicting target behavior
safety examples
retention examples
Hundreds of near-duplicates can increase dataset size without increasing behavioral coverage.
A validation set that closely resembles training can also create false confidence.
Useful evaluation slices include normal in-domain cases, edge cases, malformed/adversarial inputs, out-of-domain cases, and retained general capabilities.
Zero-shot prompting, few-shot prompting and supervised fine-tuning cannot be compared fairly without a common evaluation protocol. If few-shot examples are paraphrases of held-out records, the resulting score can reflect leakage rather than generalization. Fair evaluation requires a fixed task definition, separated development and test data, prespecified metrics and identical output-validation rules. For structured tasks, F1 alone is insufficient: schema validity, evidential grounding, abstention behavior and the cost of false-positive actions may all matter. The preferred method follows from the application's error budget rather than universal performance percentages.
29.4. Catastrophic Forgetting
Adapting a model to a new task can degrade capabilities that were previously useful.
This catastrophic forgetting risk is especially important during continual or strong domain fine-tuning.
The pattern can be:
target task ↑
general capability ↓
Release criteria should therefore measure more than target-task improvement.
Track target gain, retention-suite delta, safety regression, formatting regression, and latency/memory changes.
29.5. Retention Suites
Before fine-tuning, explicitly define capabilities that should remain stable:
general instruction following
basic reasoning
multilingual behavior
safety / refusal
structured output
tool-call schema
ordinary out-of-domain tasks
A small stable regression suite can be run on every model version.
This distinguishes useful specialization from accidental narrowing.
29.6. Mitigation Is Not One Technique
Possible controls include lower learning rate, shorter training, balanced data mixtures, rehearsal examples, PEFT to constrain the modified parameter surface, checkpoint comparison, early stopping, and retention-aware model selection.
None is a universal guarantee.
The stronger safety net is:
baseline
+ versioned dataset
+ reproducible training
+ regression evaluation
+ rollback
29.7. Generative Classification
A generative LLM can serve as a classifier:
input
  ↓
prompt / schema
  ↓
label
Generative capability does not remove ordinary classification requirements.
29.8. Label-taxonomy Design
Labels should be operationally meaningful and distinguishable.
Depending on the task, the taxonomy can include an explicit OTHER, UNKNOWN, or review state.
If two label definitions overlap semantically, prompting cannot completely repair the taxonomy.
When the taxonomy changes, the evaluation set should also be versioned.
29.9. Single-label and multi-label Are Different Tasks
In single-label classification, one class is correct.
In multi-label classification, several labels can independently be true.
single:
A xor B xor C

multi:
A = true
B = false
C = true
Multi-label systems can require per-label thresholding and calibration.
Choosing only the highest label silently converts the problem into single-label classification.
29.10. Abstention Can Be a Valid Result
When evidence is weak or a case lies near a class boundary, the system can return:
UNKNOWN
REVIEW
ABSTAIN
instead of forcing a label.
For high-impact workflows this can be better product behavior than maximizing raw coverage.
Evaluation should therefore report coverage and error rate together.
29.11. Calibration
Token probabilities and self-reported confidence should not automatically be treated as calibrated classification probabilities.
Calibration is a separate validation problem.
Useful controls can include held-out calibration data, threshold tuning, an external classifier, agreement/ensemble checks, or deterministic rules.
29.12. Decoding Is a Product Policy
The model produces logits; final text depends on how the system selects tokens.
Greedy decoding takes the highest-probability token at each step. It is deterministic but cannot recover from an early locally attractive choice.
Beam search keeps multiple candidate continuations. It searches more broadly but costs more compute and is not automatically better for open-ended generation.
Sampling uses controls such as temperature, top-k, and top-p to select stochastically from the distribution.
The appropriate policy depends on the task.
29.13. Temperature, top-k, and top-p
Temperature changes distribution sharpness.
lower temperature
 -> more concentrated / stable selection

higher temperature
 -> broader / more diverse selection
Top-k samples from the k highest-probability candidates.
Top-p keeps the smallest candidate set whose cumulative probability reaches p.
These are not magical creativity controls. They change determinism, diversity, and error risk.
29.14. Beam Search Is Not Universally Better
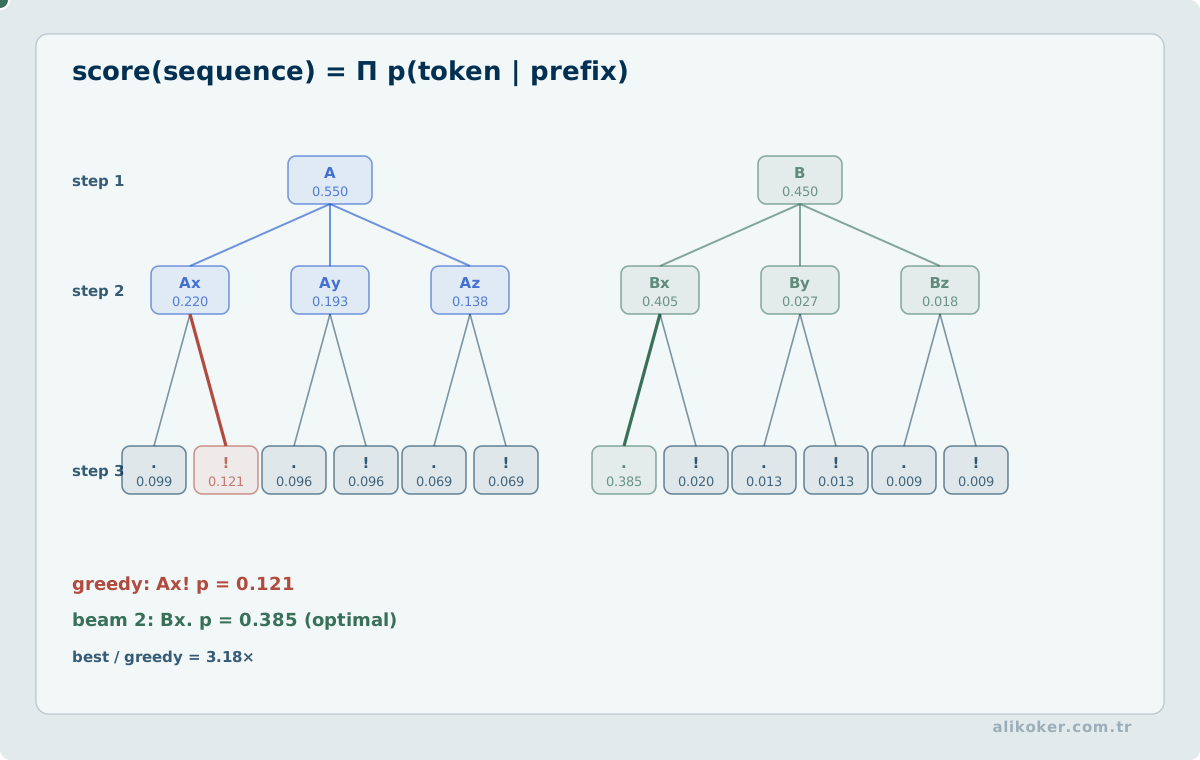
Searching sequence probability more broadly is not the same objective as producing the most useful, grounded, or correct answer.
For open-ended dialogue, beam search can increase repetition or generic output.
For machine translation or constrained generation, it can be more appropriate.
Choose decoding with task-level evaluation.
29.15. Keep Adaptation and Decoding as Separate Experiments
If model weights and decoding policy change together, the source of a regression becomes difficult to isolate.
A useful experiment matrix is:
model version
x
prompt version
x
retrieval version
x
decoding policy
Changing everything at once weakens causal interpretation of the result.
29.16. Release Gate
An LLM adaptation release should jointly consider:
target task
retained capability
safety
structured output
latency
cost
decoding stability
Model adaptation therefore becomes a versioned software change whose behavioral impact is measured and reversible, not an event that ends when training finishes.
References
- A2A Project. Agent2Agent (A2A) Protocol Specification, version 1.0.0. https://a2a-protocol.org/dev/specification/
- Ashish Vaswani et al. “Attention Is All You Need.” NeurIPS, 2017. https://arxiv.org/abs/1706.03762
- Brendan Gregg. Systems Performance: Enterprise and the Cloud. Pearson Education, 2014.
- Carlos E. Jimenez et al. “SWE-bench: Can Language Models Resolve Real-World GitHub Issues?” 2023. https://arxiv.org/abs/2310.06770
- Charlie Chen et al. “Accelerating Large Language Model Decoding with Speculative Sampling.” 2023. https://arxiv.org/abs/2302.01318
- Charlie Snell et al. “Scaling LLM Test-Time Compute Optimally can be More Effective than Scaling Model Parameters.” arXiv preprint, 2024. https://arxiv.org/abs/2408.03314
- Chris Fregly. AI Systems Performance Engineering. O’Reilly Media, 2025.
- DeepSeek-AI et al. “DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning.” arXiv preprint, 2025; revised 2026. https://arxiv.org/abs/2501.12948
- DeepSeek-AI. “DeepSeek-V2: A Strong, Economical, and Efficient Mixture-of-Experts Language Model.” 2024. https://arxiv.org/abs/2405.04434
- Edward J. Hu et al. “LoRA: Low-Rank Adaptation of Large Language Models.” ICLR, 2022. https://arxiv.org/abs/2106.09685
- Eric, Mihail. The Modern Software Developer (CS146S). Stanford University, course materials, 2025–2026. https://themodernsoftware.dev/
- Holtzman, Ari; Buys, Jan; Du, Li; Forbes, Maxwell; Choi, Yejin. “The Curious Case of Neural Text Degeneration.” ICLR, 2020. https://arxiv.org/abs/1904.09751
- John Atkinson-Abutridy. Large Language Models: Concepts, Techniques and Applications. CRC Press, 2024. DOI: https://doi.org/10.1201/9781003517245
- Jordan Hoffmann et al. “Training Compute-Optimal Large Language Models.” 2022. https://arxiv.org/abs/2203.15556
- Joshua Ainslie et al. “GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints.” 2023. https://arxiv.org/abs/2305.13245
- Lianmin Zheng et al. “Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena.” 2023. https://arxiv.org/abs/2306.05685
- Long Ouyang et al. “Training Language Models to Follow Instructions with Human Feedback.” NeurIPS, 2022. https://arxiv.org/abs/2203.02155
- Luo, Yun; Yang, Zhen; Meng, Fandong; Li, Yafu; Zhou, Jie; Zhang, Yue. “An Empirical Study of Catastrophic Forgetting in Large Language Models During Continual Fine-tuning.” 2023. https://arxiv.org/abs/2308.08747
- Ma, S. et al. “The Era of 1-bit LLMs: All Large Language Models are in 1.58 Bits.” 2024. https://arxiv.org/abs/2402.17764
- Model Context Protocol. Model Context Protocol Specification. https://modelcontextprotocol.io/specification/
- Model Context Protocol. Specification 2026-07-28. https://modelcontextprotocol.io/
- Model Context Protocol. “The 2026-07-28 Specification.” 2026. https://blog.modelcontextprotocol.io/posts/2026-07-28/
- Morteza SaberiKamarposhti. Building Large Language Models (LLM): A Step-by-Step Guide to Practical LLM Development. 2024.
- Nelson F. Liu et al. “Lost in the Middle: How Language Models Use Long Contexts.” 2023. https://arxiv.org/abs/2307.03172
- NIST. Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile (NIST AI 600-1), 2024; web edition updated in 2026. https://doi.org/10.6028/NIST.AI.600-1
- Open Source Initiative. The Open Source AI Definition 1.0. https://opensource.org/ai/open-source-ai-definition
- OWASP GenAI Security Project. OWASP Top 10 for LLM Applications 2025. https://genai.owasp.org/llm-top-10/
- Patrick Lewis et al. “Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks.” NeurIPS, 2020. https://arxiv.org/abs/2005.11401
- Pere Martra. Large Language Models Projects: Apply and Implement Strategies for Large Language Models. Apress, 2024. ISBN 979-8-8688-0515-8.
- Philip Kiely. Inference Engineering. Baseten Books, 2026. ISBN 979-8-9943597-3-0.
- Rafael Rafailov et al. “Direct Preference Optimization: Your Language Model is Secretly a Reward Model.” NeurIPS, 2023. https://arxiv.org/abs/2305.18290
- Raj Arun R. Mastering Large Language Models with Python. Orange Education, 2024. ISBN 9788197081828.
- Shao, Z. et al. “DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models.” 2024. https://arxiv.org/abs/2402.03300
- Shunyu Yao et al. “ReAct: Synergizing Reasoning and Acting in Language Models.” ICLR, 2023. https://arxiv.org/abs/2210.03629
- Siagian, Lamhot. Language Models Interview Handbook: 151 Interview Questions, Foundation Roadmaps, Python Examples, Architecture Diagrams, and Production Playbooks for Modern LLM and GenAI Roles. AI Engineering Insider, 2026.
- Tim Dettmers et al. “QLoRA: Efficient Finetuning of Quantized LLMs.” NeurIPS, 2023. https://arxiv.org/abs/2305.14314
- Timo Schick et al. “Toolformer: Language Models Can Teach Themselves to Use Tools.” NeurIPS, 2023. https://arxiv.org/abs/2302.04761
- Tri Dao et al. “FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness.” NeurIPS, 2022. https://arxiv.org/abs/2205.14135
- William Fedus; Barret Zoph; Noam Shazeer. “Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity.” 2021. https://arxiv.org/abs/2101.03961
- Woosuk Kwon et al. “Efficient Memory Management for Large Language Model Serving with PagedAttention.” SOSP, 2023. https://arxiv.org/abs/2309.06180