


Avionics Systems and Unmanned Aerial Vehicles

Academic lecture notes covering flight physics, IMU/GNSS, sensor fusion, flight control, ground control, avionics data buses, real-time software, fault tolerance, MISRA C, DO-178C, and verification from a systems-engineering perspective.
Avionics combines sensing, state estimation, navigation, communications, flight control, mission management, and fault management within a common timing and reliability model. This coupling is especially visible in unmanned aircraft: sensor semantics, communication delay, control-loop stability, software execution time, and the state presented to the operator belong to the same flight-safety chain.
These notes begin with fixed-wing flight physics and basic control, then move through IMU/GNSS, coordinate frames, Kalman filtering, and sensor fusion. The later units cover ground control, telemetry, avionics data buses, real-time behavior, fault tolerance, static analysis, software assurance, and system integration. The objective is not to promote a particular aircraft product but to explain engineering principles that remain applicable across platforms.
In avionics, a numerical measurement is incomplete without provenance and timing. The originating sensor, coordinate frame, timestamp, validity state, uncertainty bounds, and processing version can all affect the meaning of the value. The same distinction applies to commands: “issued,” “accepted,” “executing,” and “physically verified” are different states.
Standards and assurance practices are therefore treated as engineering mechanisms rather than as a compliance checklist. ARINC 429, ARINC 653, MIL-STD-1553, MISRA C, and DO-178C are discussed within their proper scopes; no architecture or certification claim is made for a specific platform unless it is supported by an appropriate public source.
The historical application record for the author's 2015 work on embedded networking, telemetry, static analysis, and avionics debugging is kept separately on the Baykar internship page. General technical claims in this course are grounded in the academic and technical references listed below.
Unit 1: Flight Physics and Core Avionics Concepts
1.1. Definition of an Avionics System
The word avionics combines aviation and electronics. It covers the electronic, sensing, computing, communication, and control functions that support flight.
An aircraft avionics system is more than a cockpit display or a flight computer. A modern avionics architecture typically brings together functions such as:
- measuring aircraft state,
- computing position and attitude,
- receiving commands from a pilot or operator,
- controlling flight surfaces and other actuators,
- managing the mission and flight plan,
- operating external-world sensors and payloads,
- providing communications,
- monitoring system health,
- detecting and, where possible, isolating faults,
- preventing the loss of critical functions after a single failure.
In a crewed aircraft, the pilot is physically present in the aircraft and remains a central decision maker. In an unmanned aircraft, removing the pilot from the airframe does not reduce avionics requirements. State estimation, communications, automatic flight, and fault management instead become even more decisive because the aircraft must continue to understand and control itself across a remote link.
An airframe and an engine are not enough to make a UAV operational. Flight must be measured, interpreted, and controlled.
1.2. Physical Basis of Flight
The shortest path to understanding a fixed-wing aircraft begins with four fundamental forces:
- lift,
- weight,
- thrust,
- drag.
In an idealized straight-and-level condition, lift balances weight and thrust balances drag. Real flight continuously departs from that balance because speed, altitude, wind, maneuvering, and control inputs change.
1.2.1. Dynamic Pressure
A large part of aerodynamic force is associated with dynamic pressure:
q = ½ρV²
where:
q: dynamic pressure,ρ: air density,V: airspeed relative to the surrounding air.
Because dynamic pressure varies with the square of velocity, the same control-surface deflection does not create the same effect at low and high airspeed. A flight-control system must therefore consider not only a commanded deflection but also the operating point of the aircraft.
1.2.2. Lift and Drag
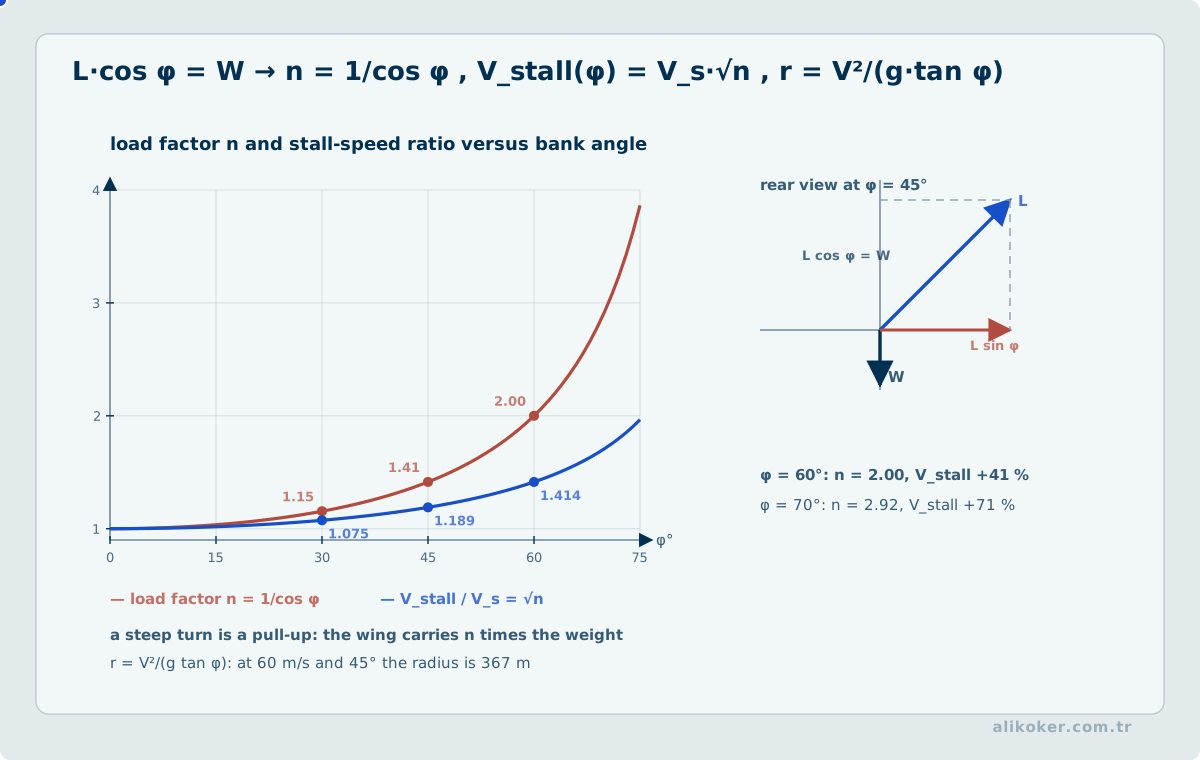
Lift can be approximated as:
L = ½ρV²SC_L
and drag as:
D = ½ρV²SC_D
Here S is wing area, C_L is the lift coefficient, and C_D is the drag coefficient.
These equations demonstrate an important engineering fact: flight cannot be explained from mechanical geometry alone. Air density, speed, angle of attack, airfoil characteristics, and aircraft configuration must be considered together.
1.2.3. Angle of Attack
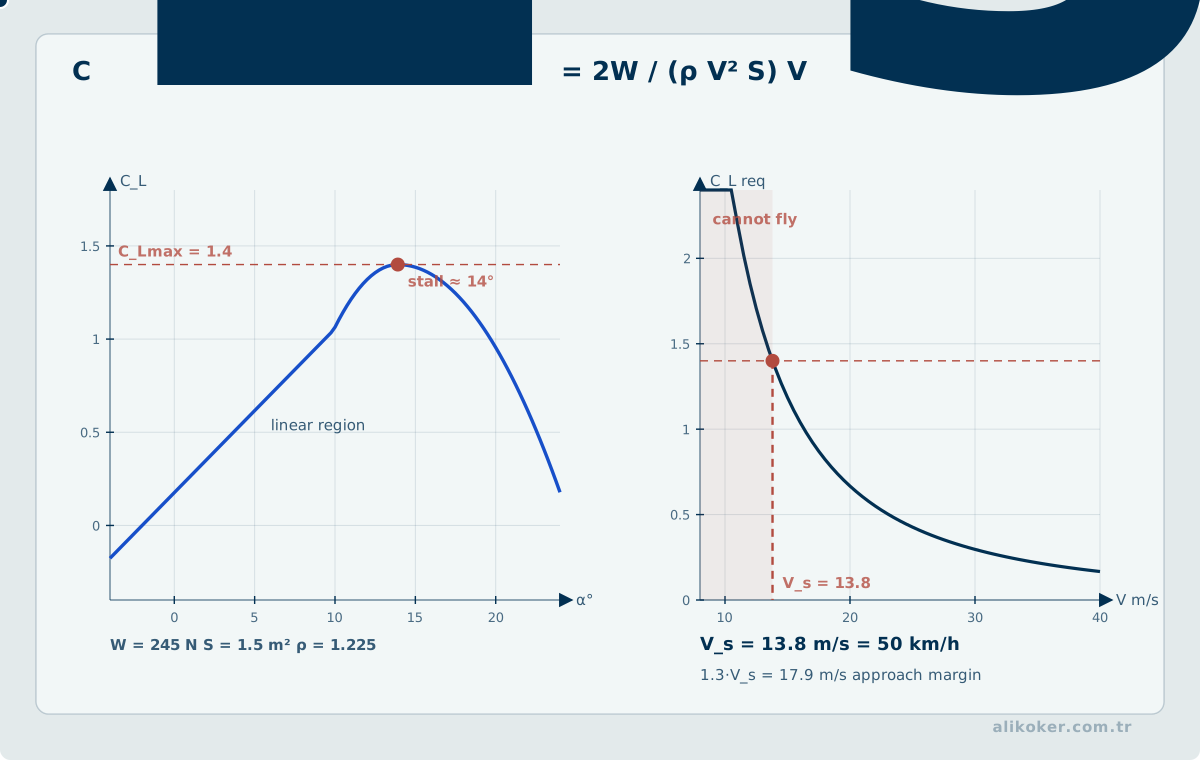
Angle of attack is the angle between an airfoil reference line and the relative airflow.
Within a normal operating range, increasing angle of attack generally increases lift coefficient. Once the flow begins to separate strongly from the wing, however, lift degrades rapidly and the wing can stall.
A stall is not simply an event that happens because an aircraft becomes “too slow.” The governing quantity is angle of attack. Airspeed, load factor, turns, and maneuvering determine how close the aircraft comes to the critical angle.
Reliable automatic flight is therefore not only a route-following problem. Keeping the aircraft inside a safe flight envelope is also part of the control problem.
1.3. Aircraft Axes and Motion
An aircraft has six degrees of freedom: three translational and three rotational.
A body-fixed coordinate frame commonly uses:
- forward axis
x, - lateral axis
y, - vertical axis
z.
Rotations about these axes are commonly called:
- roll,
- pitch,
- yaw.
Angular rates are often represented as:
p: roll rate,q: pitch rate,r: yaw rate.
Because inertial sensors are physically mounted to the airframe, the body frame is also natural from the avionics perspective. Sensors first measure quantities in body coordinates; navigation and control software then transforms those measurements into the reference frames required by the application.
This is one of the points where software enters directly into physics. A sign error in a coordinate transformation, an incorrect unit, a missing timestamp, or a wrong axis convention can turn a small software defect into an incorrect estimate of aircraft state.
1.4. Stability, Control, and Feedback
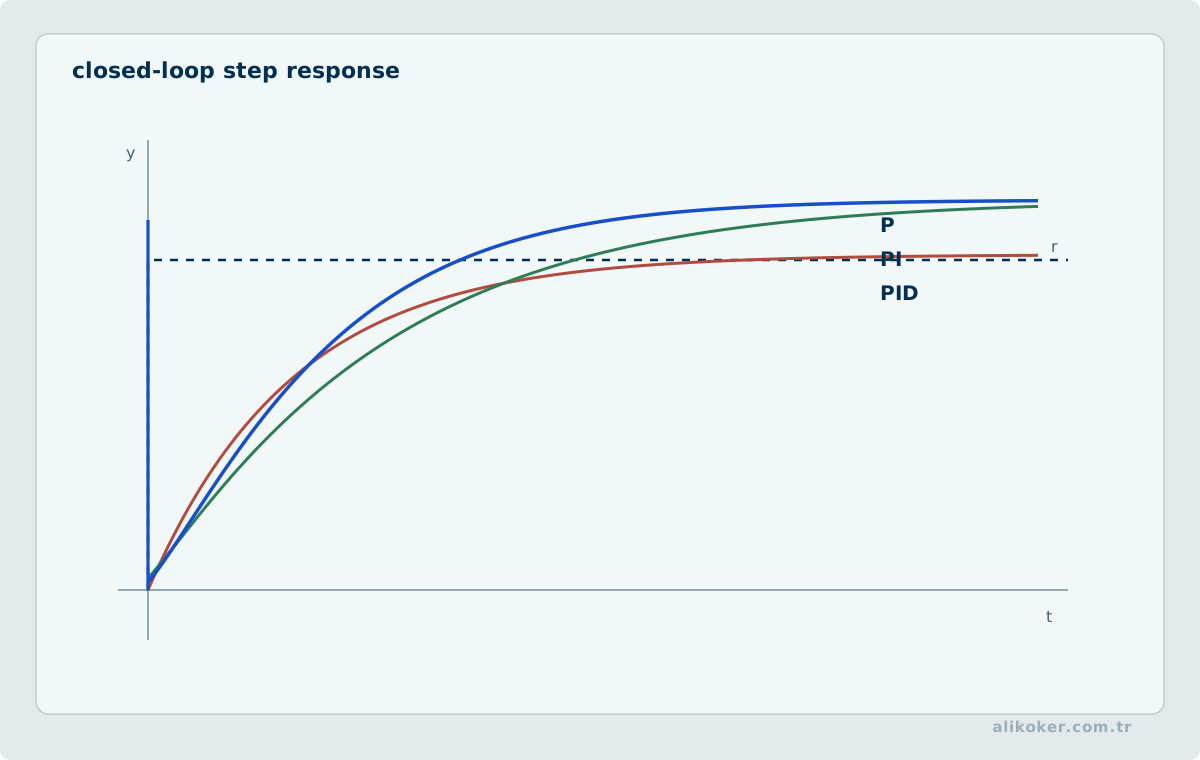
A stable system tends to return toward an equilibrium after a small disturbance. In an unstable system, small deviations can grow with time.
Aerodynamic stability must be considered together with performance. Some aircraft configurations deliberately reduce natural stability to improve drag or maneuvering characteristics. The cost is a stronger dependence on active control.
Flight control therefore becomes a classical feedback problem:
e(t) = r(t) - y(t)
where:
r(t): desired state,y(t): measured or estimated state,e(t): control error.
A controller uses this error to generate actuator commands.
To achieve a desired bank angle, for example, a controller does not merely move an aileron to one fixed deflection. It observes measured bank angle and angular rate, evaluates the dynamic response of the aircraft, and continuously corrects the command in a closed loop.
An autopilot is therefore not software that simply replays a list of predefined motions. It is a real-time system in which sensing, state estimation, control laws, actuators, and feedback operate together.
1.5. Fly-by-wire and Digital Flight Control
In a fly-by-wire system, control commands are processed electrically and digitally rather than being transmitted solely through direct mechanical linkages.
A simplified loop is:
command → flight computer → control law → actuator → aircraft → sensor → feedback
This architecture is natural for a UAV because the remote operator has no physical mechanical linkage to the aircraft. Flight computers, sensors, and actuators are intrinsic parts of the control path.
Digital flight control provides capabilities such as:
- gain scheduling across operating points,
- complex control laws,
- processing multiple sensor sources,
- comparing redundant channels,
- fault detection,
- built-in testing,
- flight-data recording,
- functional updates through software.
The trade-off is that software faults become part of the flight-safety problem. “It runs” is not a sufficient engineering statement for flight-critical software. Timing, data validity, failure behavior, memory behavior, input bounds, and fault propagation are also part of the design.
Unit 2: Sensors, Navigation, and Flight Control
This unit treats sensing, state estimation, guidance, control, and actuator response as one closed-loop chain from physical flight state to commanded motion.
            +-----------------------------+
            |                             |
            v                             |
physical flight -> sensors -> state estimate -> guidance -> control -> actuators
      ^                                                             |
      +-------------------------------------------------------------+
                         feedback
Navigation estimation begins by mapping position, velocity, and attitude to available sensors. Measurements at different rates require a common time basis, and coordinate frames must be defined before transformation. During filtering, compare model prediction with the measurement innovation. An unusually large innovation must prompt checks for sensor error, delay, and model mismatch rather than being attributed automatically to vehicle motion.
2.1. Air-data Systems
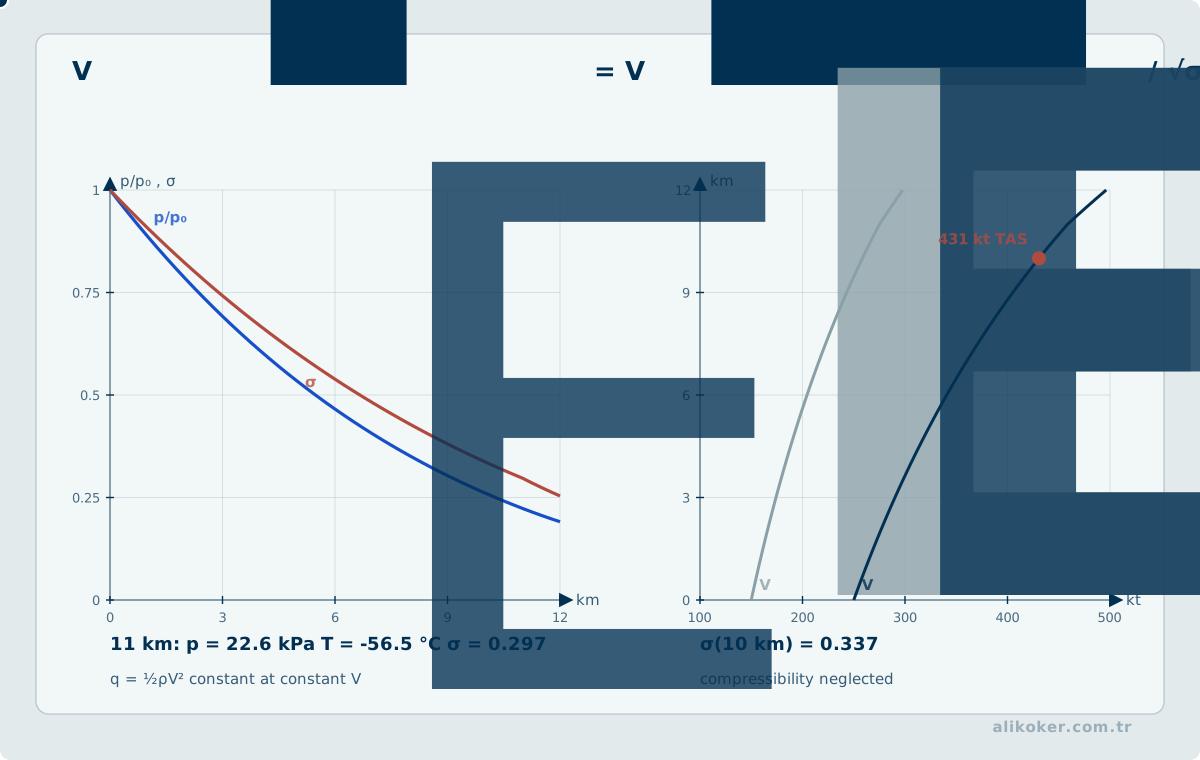
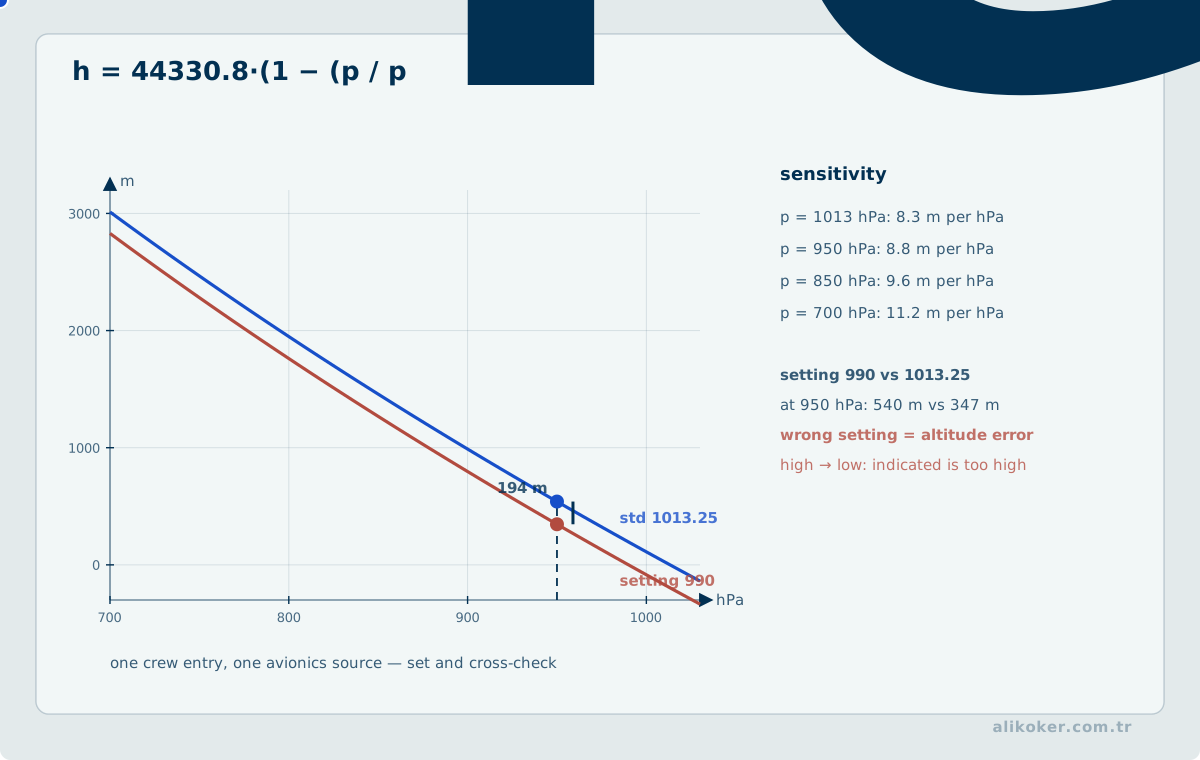
An aircraft needs to know not only where it is but also how it is moving through the atmosphere.
An air-data system may provide or contribute to values such as:
- static pressure,
- total pressure,
- pressure altitude,
- calibrated airspeed,
- true airspeed,
- Mach number,
- air temperature,
- vertical speed,
- angle of attack.
Pressure altitude and airspeed are fundamental control states. Because a given control-surface deflection produces different aerodynamic moments at different speeds, flight-control gains may be scheduled according to air-data conditions.
For a UAV, air data is especially important for three groups of functions:
- Flight envelope: protecting against stall and overspeed conditions.
- Autopilot: running altitude, speed, climb, and descent modes.
- Navigation: combining airspeed and barometric altitude with other sensors.
A sensor value is never the whole physical truth. Calibration, installation effects, pressure error, temperature, sampling time, and data validity are part of the measurement as well.
2.2. IMU, Gyroscopes, and Accelerometers
One of the central building blocks of modern avionics is the inertial measurement unit.
A typical IMU measures three-axis:
- angular rate with gyroscopes,
- specific force with accelerometers.
In a strap-down architecture the sensors are fixed to the airframe, and attitude, velocity, and position are computed numerically rather than by mechanically stabilized platforms.
In an idealized system, integrating acceleration gives velocity and integrating velocity gives position. Real sensors, however, contain:
- bias,
- scale-factor error,
- axis misalignment,
- temperature sensitivity,
- noise,
- drift.
Integration causes many of these errors to accumulate. That is one of the fundamental limitations of inertial navigation.
The engineering conclusion is that robust navigation is not simply a matter of choosing a “good GPS” or a “good IMU.” Sensors with different error characteristics must be combined correctly.
2.3. Attitude and State Estimation
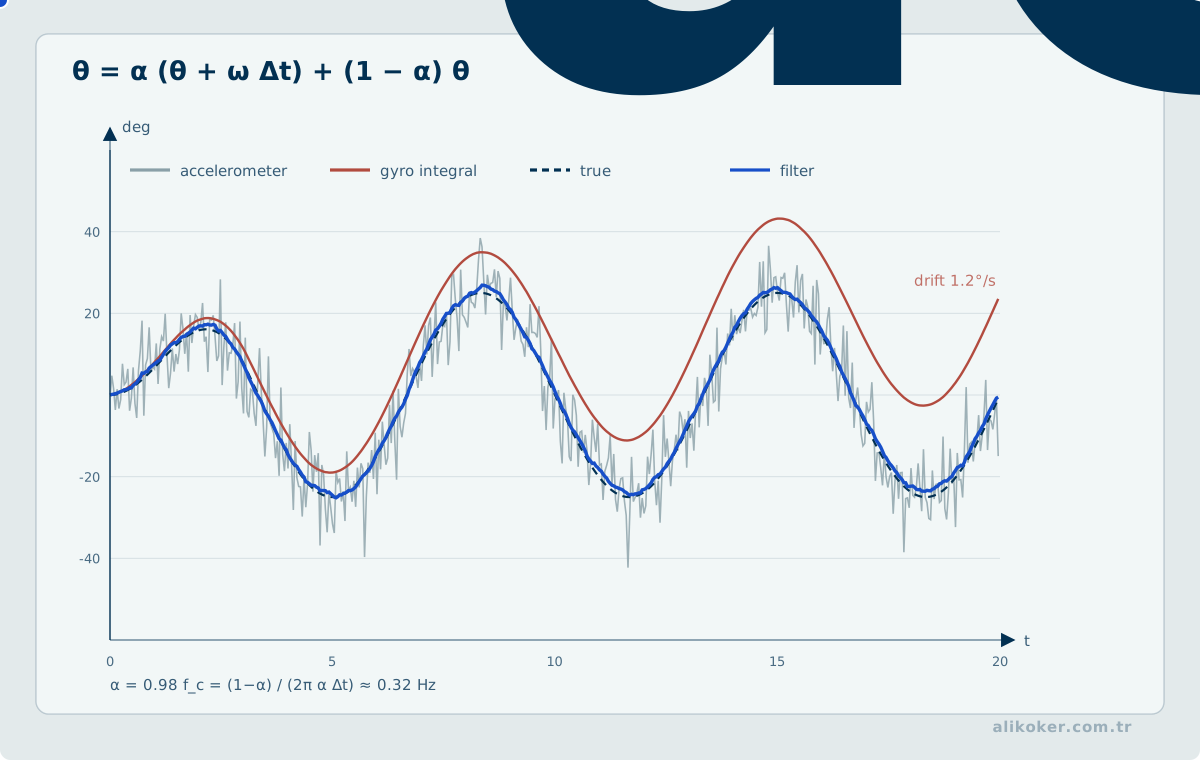
One of the flight computer’s fundamental questions is:
Where is the aircraft, how is it oriented, and how is it moving now?
A state vector depends on the application, but an example can be represented as:
x = [position, velocity, attitude, angular rate, sensor biases]
Attitude can be expressed through Euler angles, while computation often uses quaternions or other representations to avoid singularities and improve numerical behavior.
State estimation combines multiple sensors inside a common physical model. Instead of trusting one measurement source blindly, the estimator can reason about consistency among measurements and model predictions.
That is why sensor fusion is central to UAV reliability.
2.4. GPS/GNSS, INS, and Sensor Fusion
Satellite navigation provides long-term absolute position information. Inertial navigation provides high-rate, smooth short-term motion information.
Their error characteristics complement each other:
- GNSS provides absolute position but can suffer latency, outages, degradation, or interference.
- INS can continue without external radio navigation but its errors grow over time.
Combining GNSS and INS is therefore a natural solution.
2.4.1. Kalman Filtering
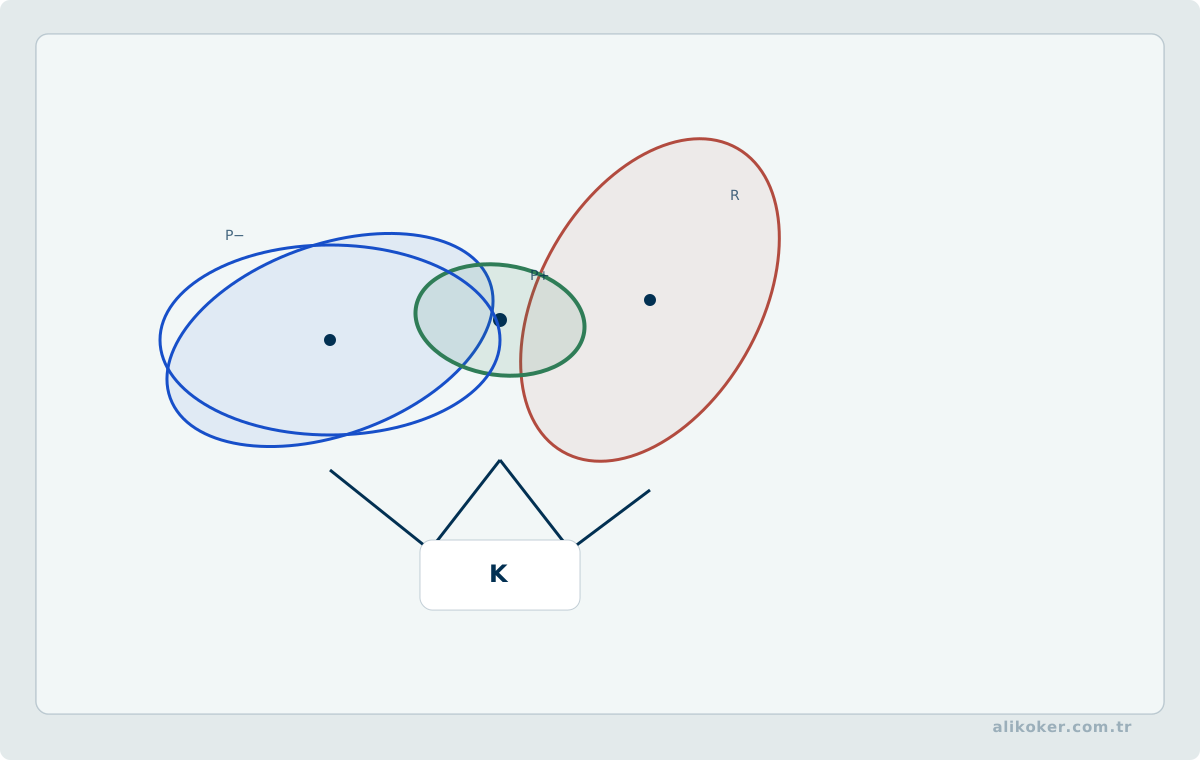
At a high level, a Kalman filter alternates between two operations:
- predict the state using a system model,
- correct the prediction when a new measurement arrives.
A simplified prediction can be written as x̂⁻ₖ = F x̂ₖ₋₁.
When a measurement becomes available, the correction can be represented as x̂ₖ = x̂⁻ₖ + K(zₖ - Hx̂⁻ₖ).
The innovation term zₖ - Hx̂⁻ₖ is the difference between the actual measurement and the measurement expected from the predicted state.
The same framework can estimate quantities such as gyroscope bias and accelerometer bias, not only position.
For a UAV, sensor fusion is effectively part of the control system’s perception. No control law can compensate for consistently incorrect state information.
2.4.2. Coordinate Frames and Time Alignment
Combining sensor values is not enough. The values must represent the same physical quantity in compatible coordinate frames and on a compatible time basis. GNSS position normally arrives in a geodetic reference system, whereas IMU measurements originate in body axes. The navigation solution must transform data among earth, local-navigation, and body frames as required by the system.
WGS 84 is a widely used global geodetic reference. Flight-control algorithms often work in local navigation frames such as north-east-down together with body coordinates. A sign error, axis-order mistake, or unit mismatch in these transformations can convert correct sensor data into an incorrect physical interpretation.
Time alignment is equally important. A 100 Hz IMU and a slower GNSS receiver cannot be fused correctly merely according to packet arrival order. The estimator must know when each measurement was taken, the transport and processing latency, and how to propagate the state to a common estimation instant. Sensor fusion is therefore a problem of coordinate consistency and temporal consistency as well as statistical estimation.
2.5. Autopilot and Flight Management
Autopilot and flight management are not the same function.
An autopilot closes control loops around specific targets such as:
- bank-angle hold,
- heading hold,
- altitude hold,
- speed hold,
- climb or descent,
- route tracking.
Flight management operates at a higher level and may deal with:
- flight plans,
- waypoint sequences,
- mission routes,
- speed and altitude profiles,
- mission phases,
- route changes,
- performance prediction.
The distinction becomes especially clear in unmanned aircraft.
A ground operator normally does not command “move the aileron three degrees to the right.” A higher-level intent is given instead:
fly to this waypoint
To execute that intent, the system must:
- determine current position,
- compute the required path,
- derive heading and bank targets,
- run lower-level flight-control loops,
- compensate for wind and disturbances.
As autonomy increases, operator commands move to a higher level of abstraction. The lower-level feedback loops do not disappear; more responsibility is delegated to them.
Unit 3: UAV Architecture, Ground Control, Telemetry, and Real-Time Communications
This unit treats the air vehicle and ground control station as one distributed system connected through telemetry, commands, operator interaction, and recording.
+-----------------+      data link       +-------------------+
| air vehicle     | <------------------> | ground control    |
|                 |                      | station            |
| sensors         | -- telemetry ------> | visualization     |
| flight computer | <--- command --------| operator          |
| actuators       |                      | logging / analysis|
+-----------------+                      +-------------------+
A UAV communication link begins by classifying safety-critical versus diagnostic information. Assign message rate, packet size, loss tolerance, and freshness deadline separately for each class. Architectural decisions, such as keeping the control loop independent of a delayed ground link, should follow a safety analysis. Define and test expected vehicle-state transitions when communication is lost.
3.1. UAV System Architecture
A UAV should not be viewed only as a flying platform. An operational system generally contains:
- the aircraft,
- flight-control system,
- mission computer,
- sensors,
- payloads,
- data link,
- ground control station,
- operator interface,
- mission-planning and recording infrastructure,
- maintenance and test equipment.
A UAV architecture is not limited to the air vehicle. A continuous information path connects the airborne platform and the ground segment for telemetry, commands, recording, debugging, and operator interaction. From a computer-engineering perspective, much of system behavior becomes observable at these interfaces.
3.2. Ground Control Stations
In a crewed aircraft, many flight and system indications are presented directly in the cockpit. In a UAV, much of that information moves to the ground control station.
A ground-control interface may display:
- position,
- altitude,
- airspeed and groundspeed,
- heading,
- pitch and roll,
- route and waypoints,
- engine and power-system status,
- flight mode,
- data-link status,
- sensor and payload status,
- video or electro-optical imagery,
- warnings and faults.
The user interface is not cosmetic in this setting.
If the operator selects the wrong flight mode, treats stale telemetry as current, or misses a critical alarm, the problem becomes a system-level failure. Information density, prioritization, mode awareness, and error visibility must therefore be handled as engineering requirements rather than decoration.
3.3. Telemetry: from Numbers to System State
Telemetry is more than displaying values received from the aircraft.
For every telemetry value, questions such as these matter:
- What is the source of the value?
- When was it measured?
- What unit does it use?
- When was it last updated?
- Is it valid?
- Is it inside an expected range?
- At what sampling rate is it produced?
- Were packets lost?
- Were sequence numbers skipped?
- Is the value a raw sensor measurement, an estimate, or a command?
- Can an old value remain on screen and appear current?
In a ground station, altitude = 5000 is not a complete data model.
A more useful representation is closer to:
value + unit + source + measurement time + validity + quality + sequence
Working on ground-control telemetry in 2015 made the difference between theoretical networking and a live real-time system very tangible. Latency, link interruption, or malformed data were no longer laboratory examples; they directly affected whether the system state was understood correctly.
3.4. Embedded Networking and Data Flow
UAV communication can be considered at two different scales:
- communication inside the aircraft among avionics components,
- the data link between the aircraft and the ground system.
Internal buses allow sensors, computers, and actuators to exchange information. The air-ground link may carry commands, telemetry, mission data, and payload data.
Bandwidth is only one engineering constraint. Other relevant properties include:
- latency,
- latency variation,
- packet loss,
- ordering,
- data integrity,
- error detection,
- time alignment,
- prioritization,
- behavior after link loss.
Losing a packet in a video stream and losing a flight-mode command do not belong to the same consequence class. Critical-system traffic must be classified by semantics and risk, not just by byte rate.
An embedded network stack is more than a TCP/IP programming topic. It forms part of the boundary among processor timing, buffer management, fault behavior, and the physical system. Packet loss, retransmission, latency, and link interruption can directly affect higher-level state estimation and the operator view.
3.4.1. Avionics Data Buses: Different Requirements, Different Designs
Not every avionics data path needs to be Ethernet- or IP-based. Different aircraft generations and system architectures use buses selected for their reliability, wiring, bandwidth, determinism, and environmental constraints.
ARINC 429 is a long-established civil-avionics data-transfer standard with a deliberately simple and predictable model. MIL-STD-1553 defines a different command/response architecture in which a bus controller manages communication on the multiplex data bus. Studying them together is useful not for inferring the internal architecture of a particular platform, but for comparing design trade-offs among bandwidth, determinism, topology, fault containment, and verifiability.
The broader engineering lesson is that a data bus should not be selected by bit rate alone. Fault model, topology, bounded latency, timing predictability, electromagnetic environment, maintainability, and interface lifecycle all matter.
3.5. Real-time Behavior and Latency
A real-time system is not simply a system that runs very fast.
The essential requirement is:
Producing the result at the correct time is part of producing the correct result.
If a control-loop value must arrive within 10 ms and instead arrives after 500 ms, numerical correctness alone is insufficient.
Avionics software therefore treats concepts such as these as part of functional correctness:
- worst-case execution time (WCET),
- sampling period,
- deadline,
- jitter,
- queueing delay,
- timeout,
- stale data.
The human operator works on a much slower time scale than an inner flight-control loop. Even so, telemetry latency and freshness must remain visible. The operator must be able to distinguish “current state” from “state several seconds ago.”
3.5.1. Data Age and Time Synchronization
Packet reception time and measurement time are not the same thing. A telemetry packet may have arrived just now while carrying a sensor value sampled significantly earlier. For critical data, it is not enough to attach an arbitrary timestamp; the meaning of that timestamp must be explicit.
In multisensor systems, clock drift, timestamp resolution, buffering, queue delay, and different sampling rates can all affect state estimation. The same numerical value can imply a different physical state when associated with the wrong instant. Data age and time synchronization are therefore part of functional correctness rather than secondary performance metrics.
In position telemetry, measurement time, transmission time, and ground-station arrival time are distinct. A coordinate that has just appeared on the display may describe an older physical observation. If acquisition and processing take 80 ms, queueing takes 120 ms, and network transit takes 50 ms, the observation is already at least 250 ms old when consumed. A UAV status display should distinguish measurement age, confidence in clock synchronization, and the freshness threshold. Refreshing an interface with stale data does not make the control observation current.
3.6. Link Loss Is a Design State, Not an Exception
A data link in an unmanned system cannot be assumed to be permanently perfect.
Link loss should therefore not be treated as an unexpected exception.
It must be represented explicitly in system design.
Questions that need predefined answers include:
- Under what conditions is the link considered lost?
- Does the aircraft continue the current task?
- Does it navigate toward a predefined point?
- Is there a safe loiter behavior?
- How does the operator see the loss of link?
- How is state reconciled after communication is restored?
The point is not to describe a specific platform’s operational logic. The engineering principle is that failure behavior belongs inside the normal system state model, not outside it.
3.6.1. Modeling Link Loss with a State Machine
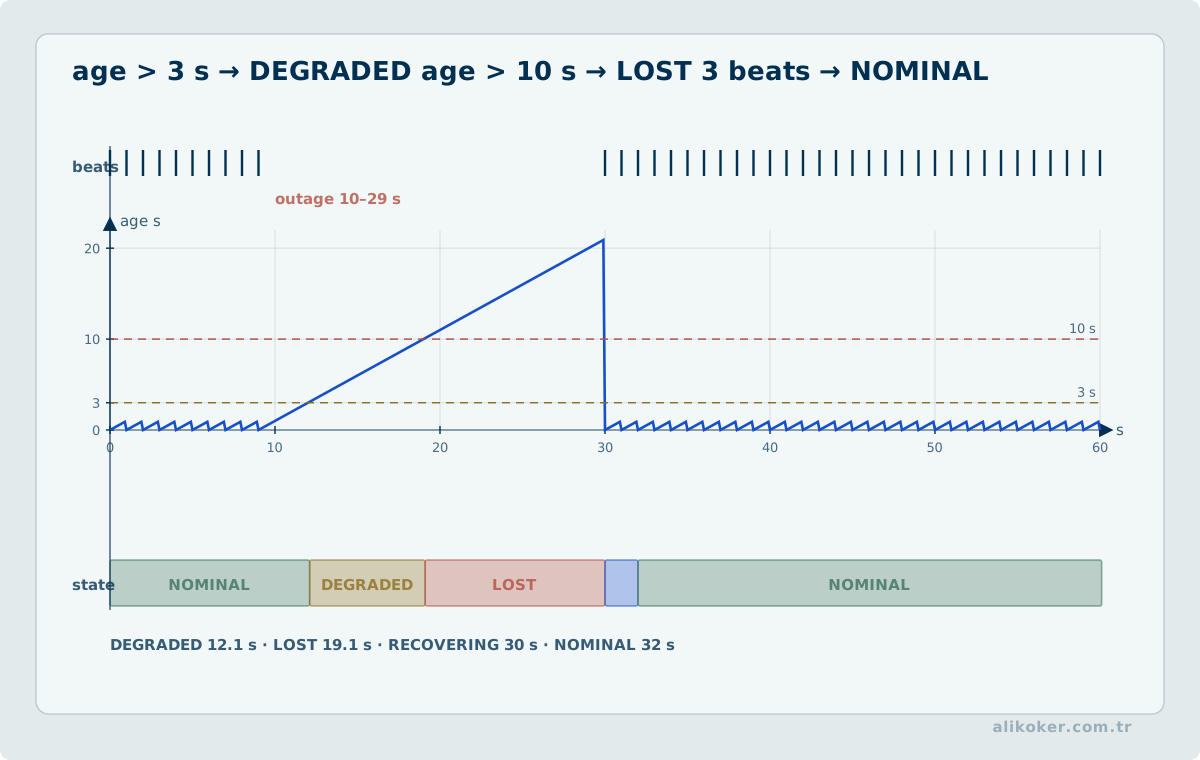
A robust design usually benefits from an explicit state model rather than one if statement for communication loss. A generic design may distinguish normal operation, degraded communication, lost link, safe behavior, reconnection, and state reconciliation. The transitions can depend on timeout, data quality, mission phase, and other context.
This does not claim to represent the real operational state machine of any particular UAV. It demonstrates why a critical communication failure should not be delegated to an exception handler. An explicit state model also provides a clearer basis for testing, fault injection, and review.
Unit 4: Reliability, Fault Tolerance, Static Analysis, and System Integration
This unit examines how faults in sensing and processing are detected, isolated, and converted into degraded or safe behavior while preserving system integrity.
sensor A --+
sensor B --+--> voter / estimator --> controller --> actuator
sensor C --+          |
                      +--> degraded operating mode
                      +--> safe state / recovery
4.1. Redundancy and Fault Tolerance
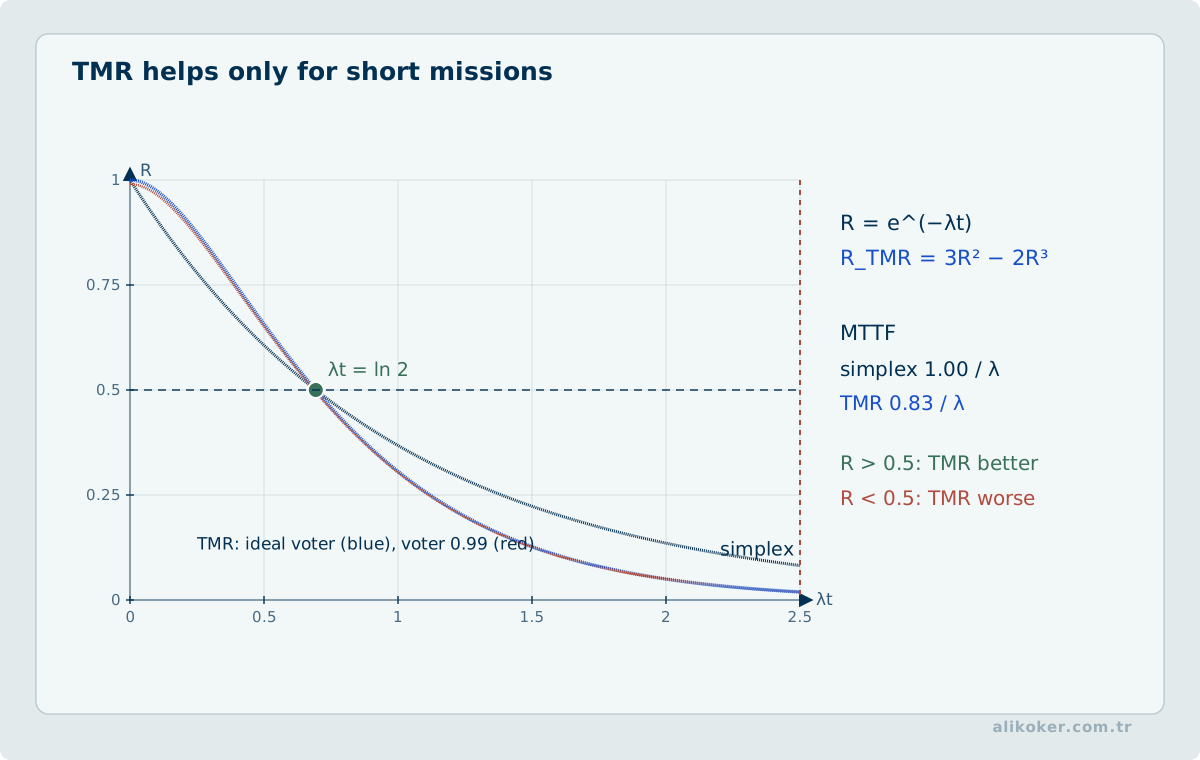
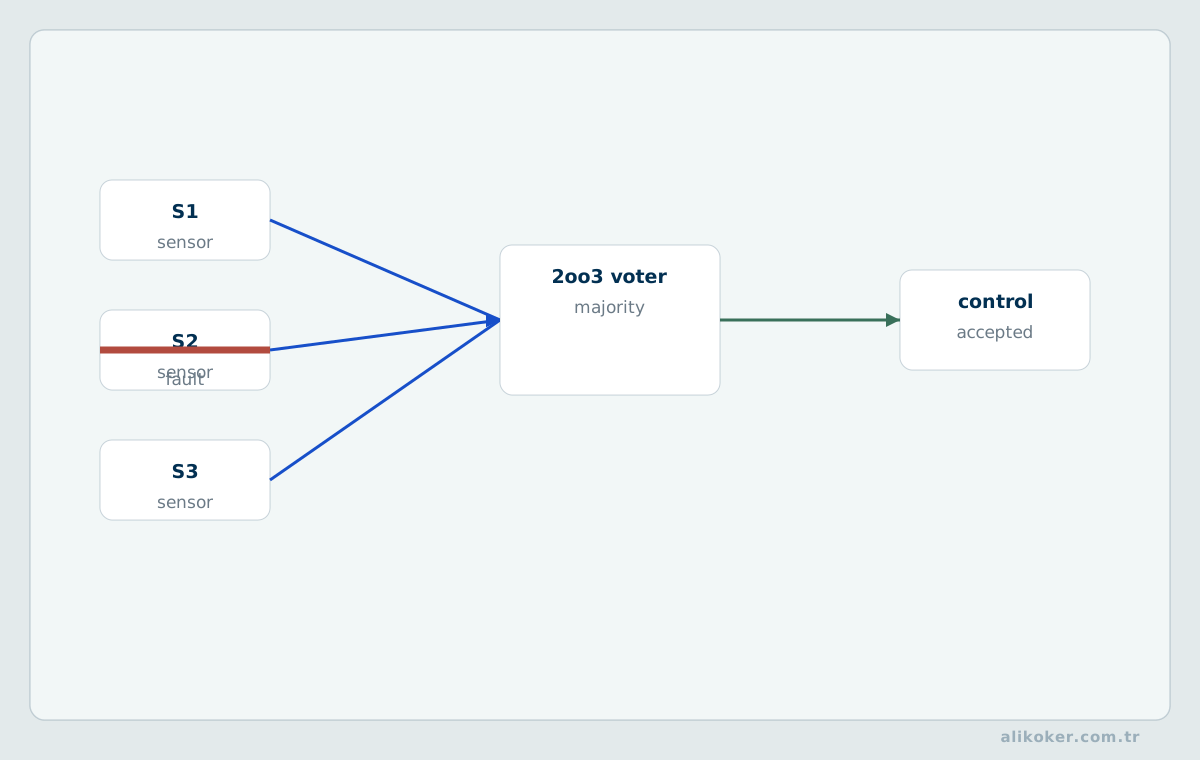
In flight-critical systems, the failure of a single component should not necessarily lead to complete loss of the system.
Redundancy can be applied at several levels:
- sensors,
- processors,
- power sources,
- data buses,
- actuators,
- communications,
- software or algorithms.
However, installing three sensors is not by itself fault tolerance.
A redundant system also needs mechanisms such as:
- cross-channel comparison,
- identification of an inconsistent channel,
- voting,
- fault isolation,
- reconfiguration,
- degraded modes,
- common-cause failure analysis.
If three channels depend on the same incorrect assumption, numerical redundancy does not remove the common-cause failure.
This is why critical avionics considers not only redundant hardware but also independence, diversity where appropriate, and containment of fault propagation.
4.2. FMEA and fault-oriented Thinking
Failure Modes and Effects Analysis (FMEA) provides a structured way to ask how a component can fail and what the system consequences will be.
The basic question is:
What happens if this component behaves incorrectly?
That leads to more specific questions:
- Can the failure be detected?
- Does the component produce incorrect data or stop producing data?
- Can the fault propagate to other channels?
- Can the system continue operating?
- Can it move to a safe mode?
- Can the operator understand what happened?
In critical-system engineering, a fault is not only a software event handled by a catch block. Sensors, power, networking, processors, timing, and human interaction have to be considered together.
4.2.1. Built-in Test and Health Monitoring
Fault tolerance is not only switching to a spare channel after a failure. The system must also be able to observe the health of its components, detect abnormal behavior as early as practical, and isolate the faulty source from healthy ones. Built-In Test (BIT) is one way avionics systems implement this idea.
Built-in test can operate at startup, continuously during operation, or on demand during maintenance. The goal is more than to output “pass” or “fail.” Health management may also need to determine which capability has been lost, what residual capability remains, and whether the system should enter a degraded mode.
This layer is directly connected to FMEA. FMEA identifies failure modes and consequences; built-in test and health monitoring provide mechanisms by which those failure modes may be observed during operation.
4.3. Static Analysis in Avionics Software
Static analysis in avionics software helps expose the difference between code that a compiler accepts and code that is acceptable under an engineering assurance process. The objective is not merely syntax checking, but finding classes of defects such as undefined behavior, data-flow anomalies, arithmetic boundary errors, resource misuse, and deviations from project coding rules before execution.
An effective static-analysis process starts by defining the applicable rule set and deviation policy rather than by selecting a tool. A project can then combine local checks and findings from multiple analysis engines in a common result model. Deduplication, severity, false-positive disposition, and linkage to the exact source revision are more useful than a raw warning count.
The durable value was not one particular analyzer. It was the chain from a documented rule, through repeatable automated checking where possible, to source-file and line-level traceability, together with the recognition that different analyzers provide different kinds of assurance for the same source code.
Static analysis can help expose classes of problems such as:
- unreachable code,
- null-pointer and pointer misuse,
- undefined behavior,
- out-of-bounds access,
- unsafe type conversions,
- resource leaks,
- unused states and values,
- overly complex control flow,
- some concurrency defects.
Static analysis does not replace testing or system-level verification.
A more realistic assurance chain is:
sound architecture + explicit requirements + static analysis + testing + integration verification + field evidence
No single tool produces reliability. Different methods are needed because they detect different defect classes and rely on different assumptions.
4.3.1. MISRA C: Separating the Rule Set from the Analyzer
MISRA C is not itself a static-analysis engine. It is a family of guidelines intended to make the use of C in critical systems more predictable and reviewable. A tool may automatically enforce some guidelines, while others can require code review, design evidence, or a controlled deviation process.
The version of a programming standard should be a configuration-controlled project input. Publication of a newer MISRA edition does not retroactively mean that an older code base was developed against it. Compliance also cannot be reduced to “the analyzer reports zero warnings”; applicable guidelines, justified deviations, and verification evidence require project-level control and traceability.
The subject is developed in greater depth in MISRA C and Static Code Analysis.
4.3.2. Airworthiness and Software Assurance
Airworthiness is not equivalent to compiling without errors or passing a software test suite. Evidence about the aircraft and its systems must be considered across system design, hardware, software, maintenance, configuration, and operational context.
For civil airborne software, RTCA DO-178C is one of the central reference documents for development and verification assurance. FAA AC 20-115D recognizes DO-178C together with DO-330 for software-tool qualification, DO-331 for model-based development and verification, DO-332 for object-oriented technology, and DO-333 for formal methods. These documents are discussed here to explain an assurance chain from requirements to evidence, not to assign a certification basis to any particular platform.
The broader engineering principle is an auditable evidence chain among requirements, design, code, verification results, configuration, and problem reports. That is the avionics counterpart of the traceability and verification concepts developed in Software Engineering and Software Test Engineering.
4.3.3. Requirements-based Verification and Structural Coverage
Structural coverage is evidence about which portions of the implementation were exercised. It does not by itself prove that the requirements were correct, complete, or properly verified. In critical systems, criteria such as statement coverage, decision coverage, and modified condition/decision coverage (MC/DC) become meaningful according to the applicable assurance objectives and risk.
The sound objective is not simply to maximize a coverage percentage. Verification scenarios are first derived from requirements; structural coverage analysis can then expose code that was not exercised, behavior without a clear requirements basis, or places where additional tests are needed. Coverage becomes a way to find verification gaps rather than a score to optimize in isolation.
4.4. Relationship Between Sensor Fusion and Fault Tolerance
Sensor fusion is often introduced as an accuracy problem. It can also be a reliability problem.
Consider three independent attitude sources.
Simply averaging them is not sufficient. If one source begins to diverge, the system may need to determine:
- which sensor is inconsistent,
- how long the inconsistency has persisted,
- whether the behavior is transient or persistent,
- how much confidence should remain in the resulting state estimate.
Sensor fusion therefore sits at the intersection of state estimation and health management.
A UAV must not only know its estimated state; it should also have an engineering basis for how much confidence can be placed in that estimate.
4.5. System Integration
An avionics architecture is not the sum of individually good components.
Integration includes decisions such as:
- which function runs on which computer,
- where sensors connect,
- which path carries each data item,
- latency budgets,
- power distribution,
- redundancy,
- software partitioning,
- maintenance and built-in test,
- reconfiguration after failures.
This is why the word interface is so important in system integration.
Two subsystems may each be correct in isolation and still behave incorrectly together.
Examples include:
- different coordinate systems,
- different endianness,
- different time references,
- different units,
- different sign conventions,
- different update rates.
Any one of these can produce an integration failure.
Avionics debugging therefore does not stop inside source code. The engineer may need to trace data end to end, from cable and protocol to sensor processing and the operator display.
4.5.1. Partitioning and ARINC 653
Integrated Modular Avionics allows multiple functions to share common computing resources, which in turn creates a requirement to prevent faults and timing interference from spreading across applications. ARINC 653 addresses this area by defining the APEX interface between application software and the avionics operating-system environment together with a partitioning model.
Spatial partitioning aims to contain memory and resource interference between partitions. Temporal partitioning aims to allocate processor time in predictable windows so that one application cannot arbitrarily consume another application's execution budget. This course keeps the topic at architecture level; the details are covered separately in ARINC 653 Temporal and Spatial Partitioning.
ARINC 653 Part 1 Supplement 6 was published at the end of 2024. Keeping standards references current matters: a supplement number copied from an older engineering note should not be assumed to remain the current revision indefinitely.
4.5.2. System-level Hazard Analysis: STPA as a Complement to FMEA
FMEA is a strong method for asking how a defined component failure mode can affect the rest of the system. Complex avionics systems, however, can also become hazardous while individual components continue to operate according to their local specifications. Interaction, timing, or an incorrect model of system state can be sufficient.
Component failure and system-level hazard are therefore not identical concepts:
component failure
-> analyze its effects

but also

components operating
+ unsafe interaction / timing / state model
-> hazardous system behavior
Nancy G. Leveson's STAMP approach treats safety not only as a collection of component failure probabilities but as a problem of enforcing appropriate constraints on system behavior. STPA turns this systems-theoretic view into structured questions for design and hazard analysis.
For a UAV, the analysis can begin by separating an unacceptable loss from the system state that could make that loss possible, and then deriving the constraint that should prevent that state:
loss / unacceptable outcome
↓
hazardous system state
↓
safety constraint
↓
control structure
↓
control action + feedback
↓
causal scenario
Here controller does not mean only the flight-control computer. An autopilot, ground-control application, human operator, mission-management function, or another supervisory element can constrain the same physical process.
A control action can be challenged from at least four directions:
- Could omitting a required action create the hazard?
- Could issuing the action under a particular system state create the hazard?
- Could the correct action become unsafe because it is too early, too late, or out of sequence?
- Could its duration or termination be unsafe?
For an abstract flight-mode transition, the engineering problem is therefore larger than the bit pattern of a MODE_CHANGE message. Safe behavior may depend on:
current flight mode
position / altitude / speed state
age of sensor information
autopilot process model
state shown to the operator
command ordering
feedback that the command was accepted and applied
Software can produce a syntactically valid command and still be wrong at system level when one of these contextual variables no longer matches physical reality.
4.5.2.1. Process-model Mismatch
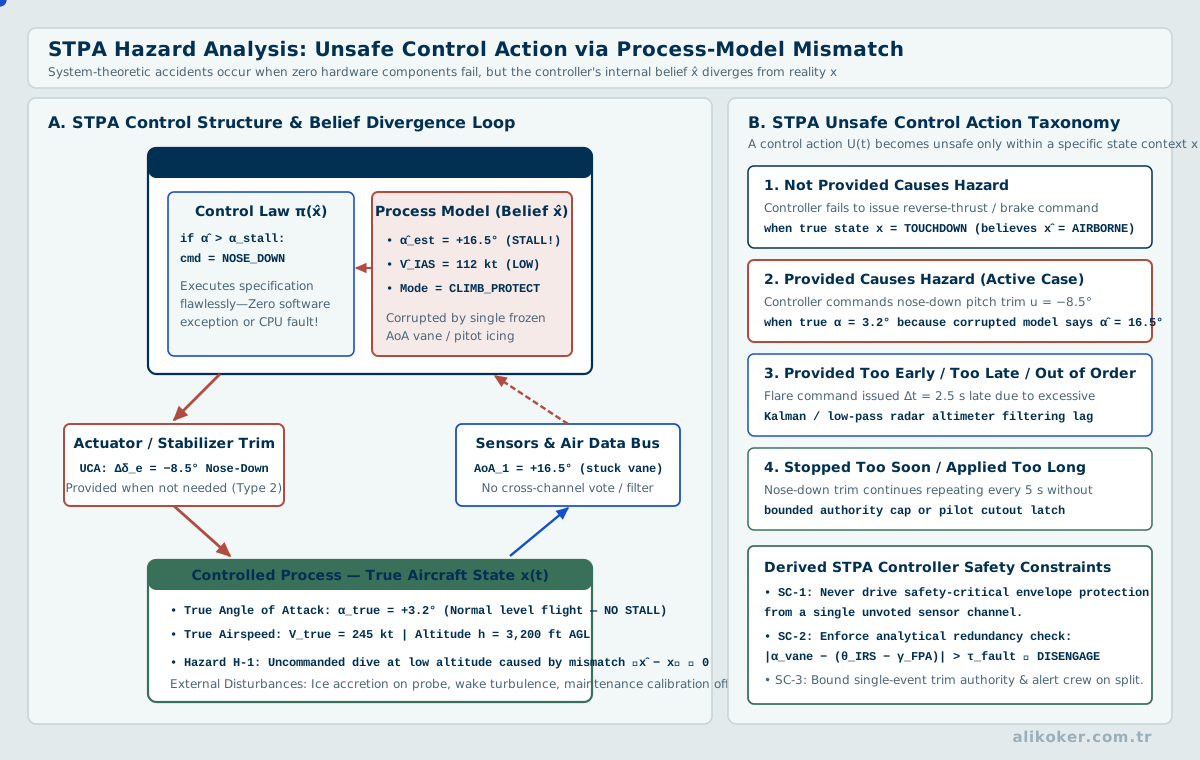
A controller does not act on physical reality directly. It makes decisions from an internal model assembled from sensors, feedback, and previous state. When that model lags behind reality, a correct algorithm operating on incorrect state can create unsafe behavior.
This idea is especially relevant to a ground-control chain:
physical flight state
↓
sensor / avionics data
↓
telemetry and communications
↓
ground-control process model
↓
operator's perceived state
↓
command
Delay, stale data, missing acknowledgement, or mode mismatch anywhere in the chain can change the meaning of the final control action. The data-age, alarm-priority, command-validation, and logging principles in Section 26 are therefore not merely interface preferences; they participate in the safety control structure.
4.5.2.2. FMEA and STPA Are Complementary Lenses
FMEA is particularly useful for exposing the consequences of physical and electronic component failure modes. STPA provides a different lens for software-intensive systems with people and multiple controllers, where inadequate control can arise without a component failure.
In practical terms:
FMEA -> how can a component fail, and what is the effect?
STPA -> what interaction or control action can make a hazardous system state possible?
Both questions can be useful in the same engineering process.
STPA/STAMP is not a replacement for FMEA; it is a complementary system-safety lens that considers hazards in terms of control structures, unsafe control actions, and inadequate feedback in addition to component failures. It is particularly useful for reasoning across human, software, sensor, network, and actuator interactions.
4.6. COTS Components and critical-system Use
Commercial off-the-shelf components can reduce development time and cost. Their use is especially natural in ground systems and supporting infrastructure.
The same convenience cannot automatically be assumed for a flight-critical function.
Evaluation may need to consider:
- product lifecycle,
- documentation,
- backward compatibility,
- deterministic behavior,
- environmental robustness,
- verifiability,
- supply continuity,
- software integrity.
“Widely used in the market” is not safety evidence.
It is also insufficient to evaluate only the feature list. The exact version, compiler or toolchain, configuration, known defects, update policy, and vendor lifecycle behavior may need to remain traceable. Two releases with the same product name can have different fault characteristics. In a critical system, reproducible configuration and known component provenance matter as much as technical capability.
4.7. End-to-End Timing Budgets and Fault Containment in Avionics
Real-time engineering considers end-to-end latency budgets, worst-case or high-percentile delay, jitter, resource saturation, and recovery behavior together rather than optimizing an average in isolation. In an avionics pipeline, sensor acquisition, bus transfer, filtering, decision logic, and actuator command each add service and queueing time; a fast microbenchmark for one algorithm does not prove that the worst-case end-to-end deadline or jitter bound is satisfied. Limits, overload behavior, and degradation modes need explicit definitions.
- Allocate latency budgets explicitly across sensing, computation, control, and actuation.
- Track jitter and deadline misses separately from mean cycle time.
- Design fault-containment regions and recovery behavior together with the communication architecture.
Calculating triple-redundancy reliability with its assumptions. Suppose three independent sensors each have probability p = 0.01 of producing an incorrect result during a specified mission interval, and a majority voter fails only if at least two sensors are wrong. The probability of an incorrect majority is P_fail = 3p²(1−p) + p³ = 0.000298, or about 0.0298%, apparently much lower than the 1% failure probability of a single sensor. This calculation depends on independence and a consistent definition of failure. A shared power fault, common calibration defect, or environmental disturbance may cause correlated errors and invalidate the optimistic estimate. Voting latency, outlier handling, and safe-mode transitions on invalid data must be engineered separately.
4.8. Common-Cause Failures in Redundant Sensors
Two sensors measuring the same physical quantity do not necessarily provide two independent failure sources. A shared power rail, clock, software conversion, or mounting geometry may cause both channels to fail in similar ways. Majority voting is effective only to the extent that independence assumptions are justified. Agreement between two sensors does not exclude a common reference error.
Disagreement should not be judged solely from \(\lvert y_1-y_2\rvert\); timestamp alignment, measurement uncertainty, and operating dynamics matter. Different filter delays, for example, can create large transient differences during rapid maneuvers without a physical fault. Monitoring should distinguish legitimate transients, frozen outputs, data age, and physically implausible rates of change.
The control mode following sensor isolation, reduced performance limits, and operator indications must be specified beforehand. Verification should cover loss of one channel as well as shared power failure, a faulty time reference, and channels that agree while sharing the same error. Having a redundant channel is not equivalent to demonstrating fault tolerance.
4.9. ARINC 653 Partitioning and Scheduling Contracts
ARINC 653-style temporal and spatial partitioning constrain applications from consuming one another's resources without limits. Partition execution can be assigned windows in a major time frame; task deadlines within partitions, interpartition communication latency, and failure transitions still require separate analysis. Isolation alone does not establish complete system functional safety.
Validation covers window overruns, communication buffers, task priorities, critical sections, watchdog responses, and worst-case execution-time assumptions. Static analysis and coding rules are complemented by timing measurement. Scheduling conclusions are not portable across platforms without specifying the target RTOS version and hardware properties.
4.10. Distinguishing Manoeuvres from Sensor Faults Through Innovations
A real abrupt manoeuvre produces large residuals in a constant-velocity estimator. Such a residual does not by itself establish GNSS or inertial-sensor failure. Alternative flight-dynamics models, timestamp alignment, independent channels and common-cause faults should be assessed together. Measurement rejection must not trap the system in an incorrect navigation estimate. NIS and robust multiple-model filtering are treated in Anomaly Detection.
Unit 5: Mission Management, Command Safety, and Operator Interfaces
5.1. Mission and Mode Management
Mission management in a UAV is more than ordering waypoints. Flight mode, navigation source, communication state, energy status, mission phase, and fault state interact. The same geographic objective may therefore be executed differently under different system conditions.
Mode transitions should be modeled explicitly. A simplified chain might be:
MANUAL
  ↓
ASSISTED
  ↓
AUTO_MISSION
  ↓
RETURN / HOLD / LAND
A real implementation also defines when a transition must be rejected, which fault causes which degraded or safe mode, and when operator intervention is accepted.
A mode selected in the user interface is not proof that the platform has entered that mode. The interface should distinguish a requested transition from verified system state.
5.2. Command Life Cycle
A ground-control command benefits from explicit states such as:
created
→ transmitted
→ received
→ validated
→ executing
→ completed / rejected / timed out
Transmission does not prove physical completion. Critical commands may require transaction identity, duplicate suppression, timeout handling, explicit acknowledgement, and confirmation of the resulting state.
A link interruption can leave the sender uncertain about whether a command was applied. Blind retry is unsafe in that situation. Idempotent operations, unique command identifiers, and explicit state-query mechanisms reduce ambiguity.
Command safety is also broader than authorization. An authorized operator can issue a syntactically valid command that is unsafe in the current flight phase. User permission and state validity should therefore be checked separately.
5.3. Alerts, Priority, and Situation Awareness
An operator interface should expose the state needed for decisions rather than simply maximize the amount of visible data. A large set of equally prominent warnings can hide the event that actually requires action.
An alert model can distinguish at least:
- severity,
- source subsystem,
- occurrence time,
- active or cleared state,
- acknowledgement state,
- repetition count,
- associated flight mode,
- recommended or automated response.
When the underlying condition disappears, retaining the alert life cycle is usually more useful than deleting the evidence, especially for post-flight analysis.
Situation awareness also depends on mode and automation intent. The operator should understand what the vehicle is doing, why it is doing it, and what behavior is expected next. Mode confusion or automation surprise can create operational risk even when every displayed number is individually correct.
5.4. Recording, Traceability, and post-flight Analysis
Real-time presentation and after-the-fact explainability are different requirements. The interface may summarize state, while investigation requires raw or sufficiently detailed records.
5.4.1. One Unambiguous Representation of State
The same variable should not silently appear with different units, rounding rules, or status encodings across screens. Presentation transformations should derive from a defined source.
5.4.2. Distinguishing Old Data from New Data
The most recently received value is not automatically a valid current value. Data age, timeout, or validity state should be represented where it affects decisions.
5.4.3. Alarm Priority
Critical alarms, informational events, and maintenance notices should not receive identical visual weight. Prioritization is part of reliability engineering, not merely graphic design.
5.4.4. Command Acknowledgement and Completion
For critical actions, sent and applied must remain distinct. A transport-layer acknowledgement does not prove physical actuation.
5.4.5. Recording and Traceability
A record becomes more useful when time, source, flight mode, software version, and related state variables can be correlated. Replay and timeline reconstruction support not only debugging but verification and maintenance.
The central principle of this unit is that the operator interface, command channel, and recording system should be different views of the same authoritative state model.
Unit 6: Human Factors, Autonomy, Reliable Software, and End-to-End Architecture
6.1. Human Factors in a UAV System
The pilot is not physically inside the aircraft, but human factors do not disappear.
The operator may have to:
- work with delayed video,
- monitor many system states at once,
- understand automatic-flight modes,
- manage communication outages,
- understand what the automation is doing and why.
As automation increases, a new class of problem becomes important: automation surprise.
The system may have made a technically correct transition, yet the operator's situation awareness can still degrade if the transition and its reason are not understandable.
A good interface should not merely display state. It should make system behavior interpretable.
6.2. Autonomy versus Remote Control
In a remotely controlled vehicle, the human continuously produces low-level commands.
In an autonomous system, the human gives a higher-level objective and the vehicle produces lower-level control decisions internally.
The distinction can be summarized as:
remote control: human → control surface
autonomous flight: human → mission objective → flight management → autopilot → control surface
Automatic taxi, takeoff, route following, and landing are general examples that illustrate the distinction between continuous low-level manual control and higher-level supervisory mission management. The engineering question is which decisions are produced onboard and under what conditions the human operator intervenes with which authority.
Autonomy does not mean “a system without humans.”
A more precise statement is:
Autonomy raises the level of abstraction between the human and the inner control loop.
6.3. Distinguishing Characteristics of UAV Software
UAV software differs from ordinary desktop or web software in several fundamental ways.
6.3.1. It Is Directly Coupled to the Physical World
An incorrect output may affect a physical system rather than only render an incorrect screen.
6.3.2. Time Matters
A correct answer delivered too late can be functionally wrong.
6.3.3. Hardware Is Imperfect
Sensor noise, packet loss, component drift, and power disturbances are part of the real environment.
6.3.4. Failure Conditions Are Normal Design Cases
Loss of communication, sensor disagreement, or failover to a redundant channel should be modeled before deployment.
6.3.5. Observability Is Necessary
Without logs, telemetry, and state records, reproducing a field problem becomes much harder.
6.3.6. System Boundaries Are Wide
The root cause of one visible error may lie anywhere from an embedded processor to the ground-control display.
These properties make it necessary to study UAV software together with systems engineering rather than as isolated application code.
The control side of this subject intersects directly with Automatic Control, measurement and sampling with Signals and Systems, processor and interrupt behavior with Microprocessors, scheduling and process behavior with Operating Systems, and data transport with Computer Networks. Ground-control human-machine interaction is complemented by UI/UX Engineering, while the verification chain connects naturally to Software Test Engineering.
6.4. Fundamental Software Principles for Reliability
Several principles apply broadly to avionics and similar real-time critical systems.
6.4.1. Avoid Ambiguous State
If data is invalid, “last known value” and “valid current value” should not be presented as the same state.
6.4.2. Avoid Silent Failure
Silently producing an incorrect answer can be more dangerous than explicitly reporting a failure.
6.4.3. Prefer Deterministic Behavior
Predictable timing and explicit state transitions are valuable when failure analysis and verification matter.
6.4.4. Limit Fault Propagation
A failure in one subsystem should not unnecessarily disable otherwise independent functions.
6.4.5. Bound Resource Use
Memory, CPU, queue growth, and other finite resources should have defined limits and failure behavior.
6.4.6. Preserve Observability
The system should retain enough state and event information to explain what happened after a problem.
These principles are not unique to aviation. The same reasoning appears in critical financial systems, public-safety systems, telecommunications, and industrial control.
6.5. The Connection Between Flight Physics and Software
One of the most instructive aspects of avionics engineering is that the boundary between software and physics becomes very thin.
A software variable named:
airspeed
is not merely a floating-point number.
Behind it may be:
- pitot/static sensing,
- calibration,
- an atmosphere model,
- filtering,
- sampling time,
- a data bus,
- flight-control gain scheduling,
- an operator display.
Likewise:
roll
is not merely an angle shown on the screen.
It can be the combined result of IMU measurements, coordinate transformation, state estimation, and control logic.
For this reason, avionics software must preserve a strong and explicit relationship between a program variable and the physical quantity it represents.
6.6. End-to-end Data Path from Sensor to Display
Consider one telemetry quantity:
altitude
It may originate through a path such as:
pressure sensor → ADC → air-data computation → flight computer → packetization → data link → ground station → parsing → UI
or:
GNSS → navigation solution → flight computer → data link → ground station
or:
INS + barometric data → fusion → estimated altitude → telemetry
An “altitude looks wrong” problem therefore cannot be assigned to one layer without evidence.
A good debugging process traces the value end to end:
- Is the source measurement correct?
- Is the conversion correct?
- Is the packet correct?
- Is the timestamp correct?
- Did the data reach the destination?
- Was it parsed correctly?
- Is the UI presenting the correct unit and scale?
This is one of the most durable engineering methods I learned while working around avionics debugging in 2015, and I have continued to use the same end-to-end reasoning in other critical systems.
6.7. Reading Architecture Through Redundancy Patterns
When examining a public avionics architecture, reliability patterns are more generalizable than product names. Redundant flight computers, multiple sensor channels, cross-linked communications, separated power paths, and independent actuator channels may all support reliability, but they address different fault models.
6.7.1. Computational Redundancy
Multiple processing channels can tolerate a single processor failure. They do not remove common-cause risk if every channel shares the same software defect, incorrect requirement, or power source.
6.7.2. Sensor Redundancy
Multiple IMUs or air-data sources are not used only for majority voting. Consistency checks, bias monitoring, failed-channel exclusion, and uncertainty management also matter.
6.7.3. Communication Redundancy
Two physical links do not automatically provide independent communication. Routing, fault detection, and switchover behavior must also respect the independence model. A shared software-state defect can defeat physically separate channels.
6.7.4. Power and Actuator Redundancy
Redundant power distribution, servo drives, and actuators should be analyzed together with shared wiring, regulators, mechanical coupling, and remaining single points of failure.
6.7.5. Autonomous Takeoff, Landing, and Navigation
As automation expands, the contracts among state estimation, mode management, fault management, and the human-machine interface become more demanding. Autonomy is less about adding a separate “intelligence module” than about extending the system's decision and recovery chain.
The purpose of architectural reading is not to collect feature lists but to determine which fault assumption is contained by which architectural mechanism.
6.8. Situation Awareness and Resilience in the Human-Machine Team
In avionics, automation, sensor fusion, and flight management are not only problems of technical correctness. Pilots, operators, and ground-control teams must be able to understand what the system knows, which automation mode is active, which data have become unreliable, and what current trends mean for flight objectives. This directly intersects with Cognitive Systems Engineering.
6.9. Mode Awareness and Automation Surprise
When automation mode is not visible or a transition violates the operator's expectation, the technical subsystem can behave as designed while the joint human-machine system behaves incorrectly. Critical automation should therefore make several properties explicit:
- active mode,
- the event that caused the transition,
- variables currently controlled by automation,
- actions available for human takeover,
- conditions that reduce sensor or model confidence,
- expected transient behavior after takeover.
6.10. Situation Awareness
Situation awareness is not simply seeing flight parameters. It includes perceiving relevant elements, comprehending their meaning in the flight context, and projecting trends into the near future. A strong cockpit or ground-control display therefore exposes operational relationships among energy, margins, route, threats, communication, and system health rather than merely multiplying raw values.
6.11. Resilience and Degraded Modes
A key avionics design problem is deciding which capabilities remain available after partial failure. Loss of a sensor, degraded communication, or failure of a secondary function does not necessarily require the entire system to behave identically. Preserving safe core functions and making new constraints intelligible to the human are complementary aspects of graceful degradation.
Degraded-mode verification should therefore test not only whether software outputs remain correct, but also what information the human receives during takeover and whether new operational margins remain understandable.
Unit 7: Verification, Degradation, and Engineering Principles
7.1. Laboratory Correctness versus Flight Reliability
An avionics function that behaves correctly in a laboratory does not automatically provide the same assurance in flight. Timing variability, sensor noise, wiring and power faults, temperature, vibration, communication loss, restart behavior, and unexpected mode transitions can all change system behavior.
Verification is therefore distributed across levels such as model-in-the-loop, software-in-the-loop, processor-in-the-loop, hardware-in-the-loop, and controlled flight testing. Each level exposes different fault classes, and assumptions not covered by that level should remain explicit.
7.2. Connecting Design Decisions to Requirements and Evidence
The important question in assurance is not merely “does this technique work?” but “which requirement does it satisfy, under which assumptions, and with what evidence?”
A traceability chain can be represented as:
system hazard
→ safety requirement
→ subsystem requirement
→ software/hardware design
→ verification scenario
→ test result / analysis evidence
A break in that chain weakens assurance even when the raw number of tests is high.
7.2.1. Physics Is Part of the Software Requirement
Aircraft dynamics, sensor limits, and actuator saturation are not external details when software controls the vehicle. Control and safety requirements must be written with physical bounds.
7.2.2. Measurement Is Not Reality
Every measurement carries error, latency, and validity semantics. Treating a value as exact truth makes state estimation and fault management brittle.
7.2.3. Network Failures Belong to Application Logic
Loss, reordering, duplication, delay, and disconnection are not only networking concerns. Mission and control logic need defined behavior for those states.
7.2.4. Redundancy Is an Architecture Problem
Two channels that share the same failure source are not two independent reliability channels. Common-cause analysis belongs to redundancy design.
7.2.5. The Interface Can Be a Critical Component
Correct lower-level computation may not be sufficient if the operator sees stale or misleading state. The human-machine interface belongs to the reliability chain.
7.2.6. Recording and Telemetry Are Not Afterthoughts
Data required for post-event explanation, maintenance, and verification should be designed from the start. Generic debug logging is not a substitute for structured event evidence.
7.2.7. Autonomy Increases System Responsibility
As autonomous authority expands, the limits of that authority, fallback behavior, operator intervention, and safe-state definition must become more explicit.
7.3. Fault Containment and Deterministic Degradation
When a subsystem fails, the capabilities to retain and the capabilities to abandon should be predetermined. Transition from full mission capability to a limited mode, hold, return behavior, or controlled landing should be an explicit state machine rather than an accidental exception chain.
Fault-containment regions clarify where a fault is expected to remain. Watchdogs, bus guardians, process isolation, and power switching provide value only when they are matched to a defined fault model.
7.4. Connecting Avionics Decisions to Requirements and Evidence
Timing and interface contracts should be measurable. Message period, maximum delay, timeout, units, coordinate frame, and validity interval must be explicit; otherwise two locally correct subsystems can interact incorrectly.
The same principle applies to configuration management. Software version, parameter set, calibration, and hardware revision need joint traceability so that the tested configuration and the flown configuration do not silently diverge.
7.5. The Role of Autonomy and AI in Avionics
Machine learning can support perception, classification, estimation, anomaly detection, or decision support. A learned-model output, however, should not become the only source of assurance in a critical chain.
At minimum, a model-based function should answer:
- how well training and validation data represent the operational domain,
- how out-of-distribution behavior is bounded,
- where confidence scores enter the decision chain,
- what safe fallback exists when the model fails,
- how data and model versions are traced,
- whether latency and resource use fit the worst-case budget.
In a critical architecture, an AI component cannot be designed independently from the surrounding state machine, timing budget, and fault-management strategy.
7.6. Conclusion
The central problem of avionics engineering is not making electronic components or software modules work in isolation. It is maintaining measurement, timing, computation, communication, control, operator interaction, and fault management within one coherent reliability model.
Flight physics defines control limits. Sensors observe the physical world imperfectly. State estimation turns those observations into an actionable model. Control laws generate actuator commands. Communications and ground control expose system state to the operator. Recording and verification mechanisms make later explanation possible.
If timing, validity, or state meaning is lost anywhere along that chain, local correctness of individual components is not enough to guarantee correct system behavior.
References
- Brendan Gregg. Systems Performance: Enterprise and the Cloud. Pearson Education, 2014.
- European Union Aviation Safety Agency. Artificial Intelligence Concept Paper Issue 2: Guidance for Level 1 & 2 Machine-Learning Applications. EASA, 2024.
- FAA AC 20-115D, Airborne Software Development Assurance Using EUROCAE ED-12( ) and RTCA DO-178( )
- MISRA C:2025 Addendum 6
- Heather Adkins; Betsy Beyer; Paul Blankinship; Piotr Lewandowski; Ana Oprea; Adam Stubblefield. Building Secure & Reliable Systems: Best Practices for Designing, Implementing, and Maintaining Systems. O’Reilly Media, 2020.
- Mor Harchol-Balter. Performance Modeling and Design of Computer Systems: Queueing Theory in Action. Cambridge University Press, 2013.
- Nancy G. Leveson. Engineering a Safer World: Systems Thinking Applied to Safety. MIT Press, 2011.
- R. P. G. Collinson. Introduction to Avionics Systems, 3rd ed. Springer, 2011.
- SAE, ARINC 429 Part 1 Supplement 19
- SAE, ARINC 653 Part 1 Supplement 6
- U.S. DoD ASSIST, MIL-STD-1553
- Simo Särkkä; Lennart Svensson. Bayesian Filtering and Smoothing, 2nd ed.. Cambridge University Press, 2023. https://doi.org/10.1017/9781108917407