


Cybersecurity Engineering


A systems-oriented cybersecurity course covering risk, governance, trust architecture, identity, networks, endpoints, applications, cryptography, threat modeling, vulnerability management, detection, incident response, and resilience.
Cybersecurity engineering is broader than operating individual security products. The central problem is to identify assets, trust boundaries, threats, and failure modes and then design, operate, and continuously validate a system that reduces risk to an acceptable level. Firewalls, endpoint protection, SIEM, IAM, penetration testing, and vulnerability scanners are tools inside that system; none of them is security by itself.
This course connects governance, architecture, identity, networks, platforms, applications, detection, incident response, and resilience. Application-level details are covered more deeply in Secure Software Engineering, while the evidence lifecycle belongs to Digital Forensics Engineering.
Unit 1: Cybersecurity as an Engineering Problem
1.1. Assets, Threats, Vulnerabilities, and Risk
asset + threat + vulnerability + impact context -> riskA vulnerability does not determine risk on its own. Exposure, exploit preconditions, business impact, data classification, existing controls, and recovery capability all matter.
The CIA triad remains useful:
- Confidentiality: preventing unauthorized disclosure,
- Integrity: preventing unauthorized or undetected modification,
- Availability: keeping required services usable when needed.
Engineering often adds authenticity, accountability, privacy, safety, and resilience. In cyber-physical systems, an incorrect command may matter more than disclosure of the command itself.
1.2. Cyberspace, Cyber Ecosystems, and Attack Surface
Cybersecurity is not limited to protecting computers connected to the public Internet. A useful distinction can be made among cyberspace, cyber ecosystems, and cyber terrain/topology. The distinction remains useful: cyberspace includes networks, devices, software, identities, data, and the physical infrastructure that supports them; the ecosystem also includes users, operators, suppliers, regulators, and adversaries.
An attack surface is therefore broader than exposed IP addresses. It includes at least:
- network services and protocols,
- user and service identities,
- administrative interfaces,
- client applications,
- import/export paths,
- supply-chain and update mechanisms,
- physical access,
- cloud and third-party integrations,
- human and operational processes.
A system can appear “closed” at the perimeter while remaining reachable through e-mail, removable media, software packages, or compromised credentials.
1.3. Distinguishing Cybercrime, Attack, Threat, and Risk
Cybercrime, cyberattack, threat, cyberwarfare, cyberespionage, cyberterrorism, and cyberextortion are separate concepts. They are not merely synonyms.
- A threat is a potential cause or actor capable of harming an asset.
- An attack is a concrete technical or operational action.
- A vulnerability is a weakness the attack may exploit.
- Risk combines threat, vulnerability, likelihood, and impact within a particular context.
- Cybercrime is a legal characterization and varies by jurisdiction.
- Cyberespionage emphasizes information acquisition, while cyberextortion uses coercion to obtain economic or other benefit.
- Cyberwarfare and cyberterrorism depend heavily on actor, purpose, context, and law rather than on any one technical method.
Engineering should begin with the technical question: which asset, behind which trust boundary, must resist which adversary capability and which unacceptable impact?
1.4. Threat-Actor Model
Calling every adversary a “hacker” produces weak designs. A threat-actor model should describe:
motivation
+ capability
+ access level
+ time / patience
+ resources
+ target knowledge
+ operational security
An insider, criminal group, supplier, automated opportunistic scanner, state-supported actor, and accidental misconfiguration do not call for the same controls. Rate limiting may be effective against Internet credential spraying, while a privileged insider requires separation of duties, strong audit, and independent approval.
1.5. Beyond Confidentiality, Integrity, and Availability
The CIA triad remains foundational:
- Confidentiality: preventing unauthorized disclosure.
- Integrity: preventing unauthorized or undetected modification.
- Availability: making services and data available when authorized users need them.
Modern systems often need explicit treatment of:
- authenticity,
- accountability,
- evidence supporting non-repudiation claims,
- privacy,
- safety,
- resilience.
An industrial controller may prioritize integrity and safety, a health system must protect both privacy and availability, and a financial transaction system strongly depends on integrity and accountability.
Unit 2: Governance, Risk, and Security Economics
Cyber-risk assessment begins by identifying protected functions and their sensitivity to interruption or data modification. Describe threats using actor capability, current controls, and credible impact. If likelihood and impact scores are uncertain, do not present their ranking as exact. Compare mitigation cost with expected risk reduction, assign residual-risk acceptance to the authorized decision maker, and reassess when conditions change.
2.1. Governance and Cyber Risk Management
NIST Cybersecurity Framework 2.0 organizes cybersecurity outcomes around six concurrent functions:
GOVERN
IDENTIFY
PROTECT
DETECT
RESPOND
RECOVER
The explicit Govern function is a major CSF 2.0 change. Risk appetite, accountability, supply-chain expectations, policy, and investment decisions belong to organizational governance rather than only to a security operations team.
A defensible program should answer:
- Which assets are critical?
- Which adversaries and failure modes are credible?
- Which risks are accepted, mitigated, transferred, or avoided?
- Who owns each control?
- Which measurement demonstrates that it works?
- Who has decision authority during an incident?
2.2. Security Metrics and Engineering Economics
Metrics should support decisions. Useful examples include:
- coverage of critical assets,
- patch latency,
- MFA coverage,
- time to close high-risk findings,
- MTTD and MTTR,
- restore-test success rate,
- telemetry coverage and delay,
- excessive-privilege counts,
- supply-chain verification coverage.
Averages may hide queueing and tail behavior. In critical systems, p95 or p99 detection and recovery times can be more informative.
2.3. Security-Investment Trade-Offs
Every control has costs: latency, CPU, operational complexity, user friction, licensing, and staffing. Security engineering seeks better risk reduction per unit of total cost without casually removing essential trust boundaries for performance.
Unit 3: Trust Boundaries, Security Architecture, and Threat Modeling
Trust-boundary analysis maps the identity and assumptions accompanying data across each component. Validation and authorization must occur at the boundary where they are required. Defense layers that secretly depend on one common control can share a failure mode. Test mitigation claims by identifying where an attack path is blocked and whether alternate paths still reach the same asset.
3.1. Trust Boundaries and Security Architecture
Security architecture should not assume that an “internal network” is inherently trustworthy. Every transition of data or authority can be modeled as a trust boundary.
user
  ↓ identity
client
  ↓ protocol
API / service
  ↓ authorization
data layer
  ↓
storage / external system
For each boundary, examine authentication, authorization, confidentiality, integrity, replay, failure behavior, and logging.
External documents, email messages, and search results processed through an AI assistant also cross a trust boundary. Instructions embedded in those materials do not carry the authority of an explicitly authorized user action. A command-like sentence inside a document cannot authorize deleting an index or exporting protected records. Tool permissions must be enforced independently of prompt text, with checks for data scope, operation type, target record, and side effects. Resistance to prompt injection depends on application-enforced authorization, not merely on filtering suspicious strings.
3.2. Least Privilege and Separation of Duties
A service should access only the resources and operations required for its function and preferably only for the necessary duration. Separating administration, operation, and audit roles limits the damage of one compromised identity.
3.3. Zero Trust
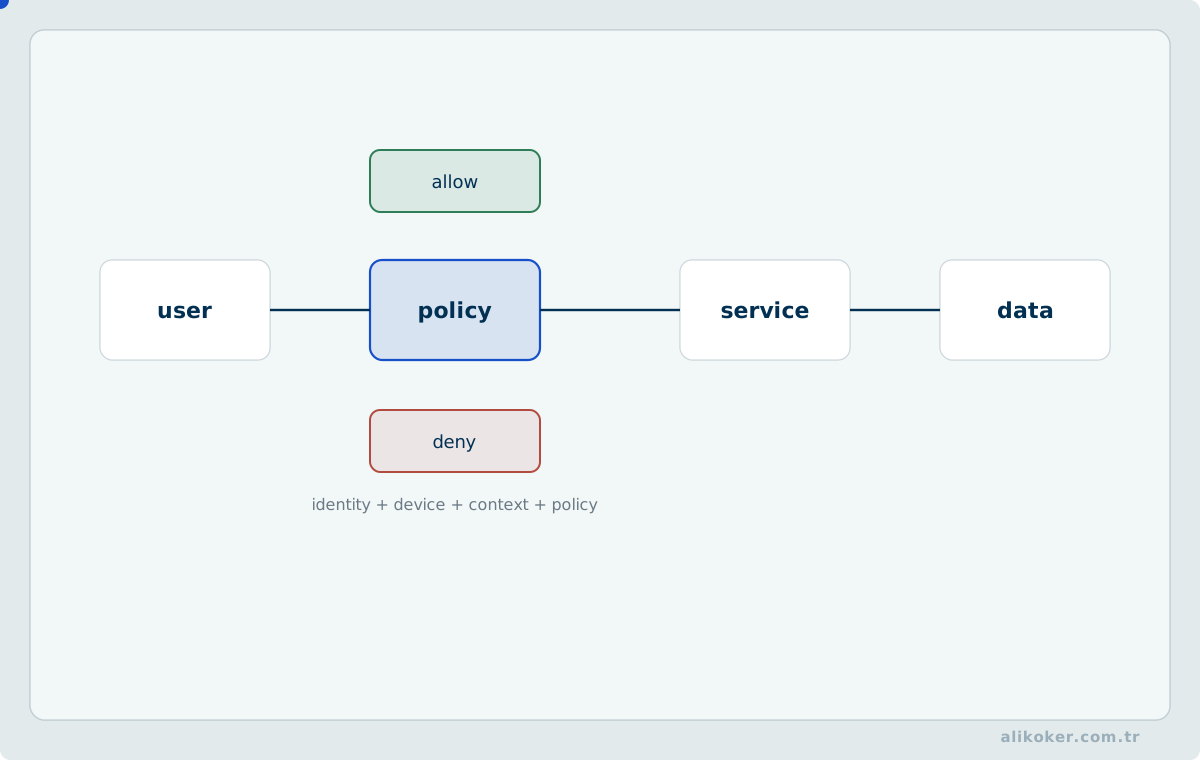
Zero Trust is an architectural principle rather than a product. NIST SP 800-207 emphasizes access decisions based on identity, device, policy, resource, and context instead of automatic trust derived from network location. A VPN alone is not a Zero Trust architecture.
3.4. Threat Modeling and Attack Surface
Threat modeling is a design activity, not only preparation for a final penetration test.
assets
 ↓
data flows
 ↓
trust boundaries
 ↓
threats
 ↓
controls
 ↓
verification scenarios
STRIDE, attack trees, and abuse cases structure reasoning. The objective is to close high-impact attack paths, not to maximize the length of a threat list.
Attack surface includes more than internet ports: APIs, administration consoles, file formats, update channels, identity providers, package registries, e-mail, human processes, and physical interfaces all contribute.
An analytical table without direct personal identifiers can still re-identify people through combinations of seemingly innocuous attributes. A small cell defined by age range, workplace and event date may uniquely identify a record. Data minimization is therefore more than deleting names: query permissions, small-cell suppression, repeated exports and linkage across published reports belong in the threat model. Summaries transmitted to external analytics or language-model services require the same scrutiny. Controls must apply at the access boundary of derived results as well as to masking of source rows.
3.5. Defense in Depth and Common-Mode Failure
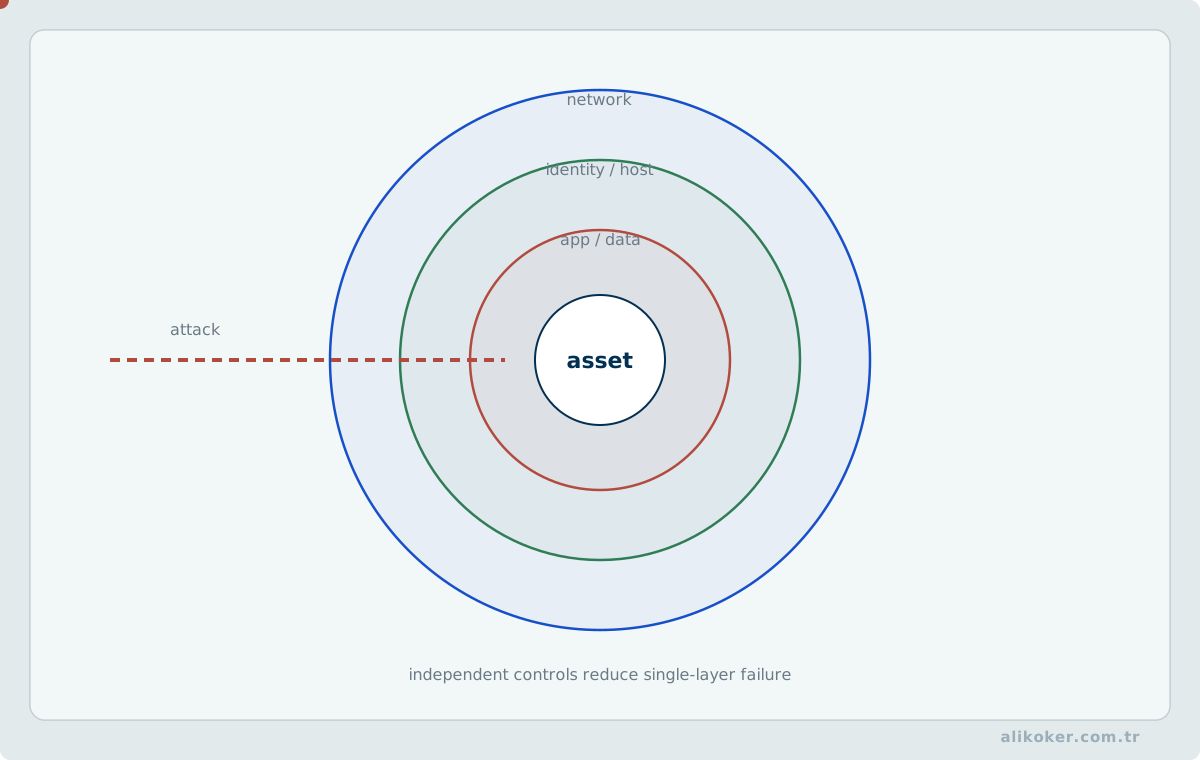
Multiple controls provide true defense in depth only when their failure modes are sufficiently independent. Three products that depend on the same identity provider, management plane, or privileged account can fail together.
MFA + PAM + SIEM
      |
shared privileged management identity
      |
common compromise -> multiple controls affected
Control dependencies belong in the architecture model.
3.6. Design Review and Threat Modeling
Before code exists, engineers can model assets, trust boundaries, attacker capabilities, and misuse paths. Authorization or isolation errors visible at design time are expensive to discover only through later fuzzing.
Deriving a trust boundary from data flow. When a user request passes through an application layer to authorization and database access, first identify the data's source, where identity is authenticated, and which authorization condition applies at each transition. For example, a client-supplied ownerId must not become an authoritative query scope. The server must independently derive the set of resources accessible to the authenticated principal. A negative test changes ownerId to another user's identifier; whether access is denied or the resource is hidden, the response must not expose the other user's record, its existence where sensitive, or protected attributes. A positive test ensures legitimate access still works. The security property is not merely input validation, but reconstructing authorization at each data-access boundary from trusted server-side context.
3.7. Electromagnetic Emissions and Physical Trust Boundaries
Information security is not limited to packets crossing a network. Electronic systems can emit electromagnetic energy through switching activity, clocks, and other data-dependent physical processes. Whether usable information can be recovered depends on source characteristics, distance, environmental noise, bandwidth, and the interpretability of captured signals; not every emission is an exploitable leak.
A threat model identifies protected information, possible physical observation surfaces, environmental boundaries, and adversarial observation capabilities. Authentication, network access control, and storage encryption do not automatically eliminate all physical side channels. Conversely, a Faraday cage does not replace cryptography; it provides a separate defense layer aimed at reducing electromagnetic coupling.
Assessing source emissions and the feasibility of information recovery are different validation problems. A favorable decibel measurement alone does not prove zero residual risk. These principles can be taught without publishing organization-specific facility or operational details.
Unit 4: Identity, Authentication, and Authorization
Identity systems are often central attack surfaces. Account takeover, token theft, weak recovery, and excessive privilege can bypass otherwise strong network controls.
4.1. Authentication
Password security includes storage algorithms, rate limiting, breached-password handling, MFA, and account-recovery design. Complexity rules in isolation are not a complete policy.
4.2. Authorization
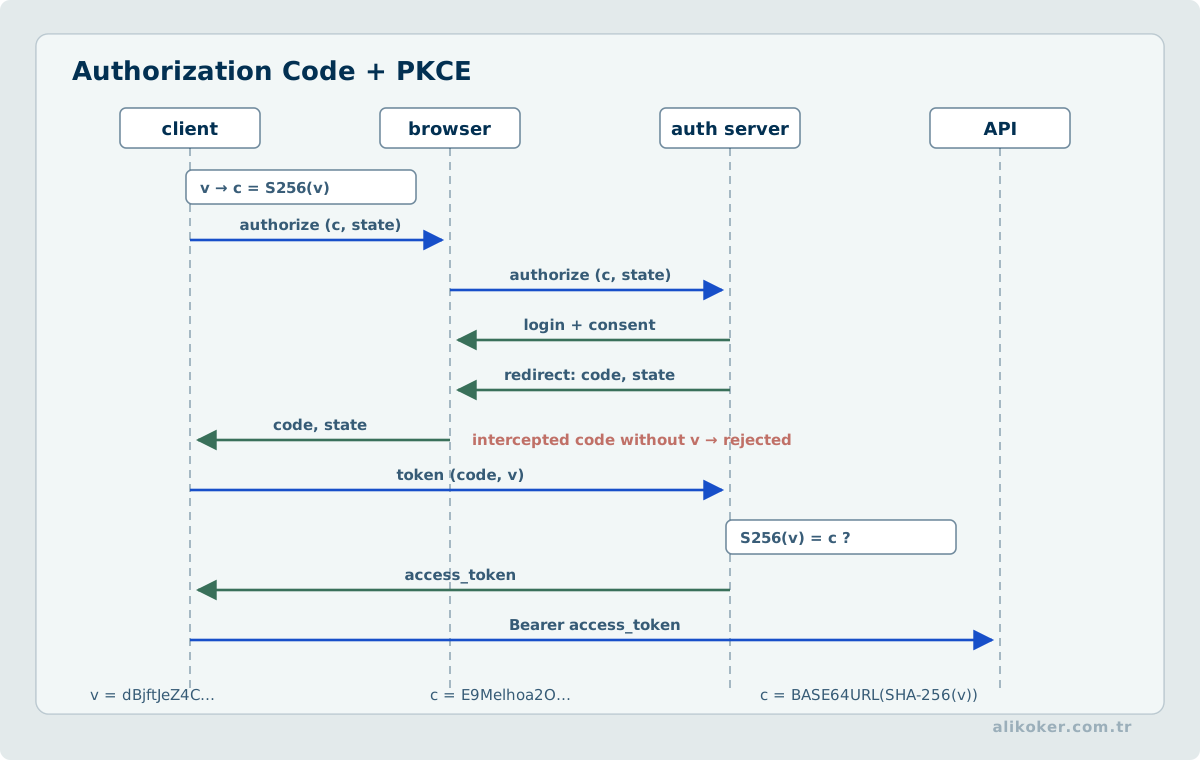
principal + action + resource + context -> decisionRBAC makes role-based decisions; ABAC uses attributes and policy. MAC and DAC represent different access-control models. Client-provided claims must not be treated as authoritative without server-side enforcement.
4.3. Privileged Access
Administrative identities should be separated from routine accounts and protected through strong authentication, short-lived privilege, audit trails, and approval for high-impact actions where appropriate.
4.4. Separating Authentication from Authorization
Authentication and authorization are different security functions. Engineering requires a strict distinction:
- Authentication: establish who or what the subject is.
- Authorization: determine what the authenticated subject may do.
- Accounting/Auditing: record what was done.
Merging these functions creates authorization defects, especially in APIs, microservices, and distributed systems.
Public-key encryption, digital signatures, and access authorization solve different problems. Verifying a signature does not establish a real-world identity unless a trusted binding to the key owner exists; even authenticated identity does not automatically grant permission to read a particular record. Successful cryptographic verification at login must not replace object-level authorization on subsequent requests. Key management, identity lifecycle, and the current scope of permission need separate treatment.
4.5. Authentication Factors
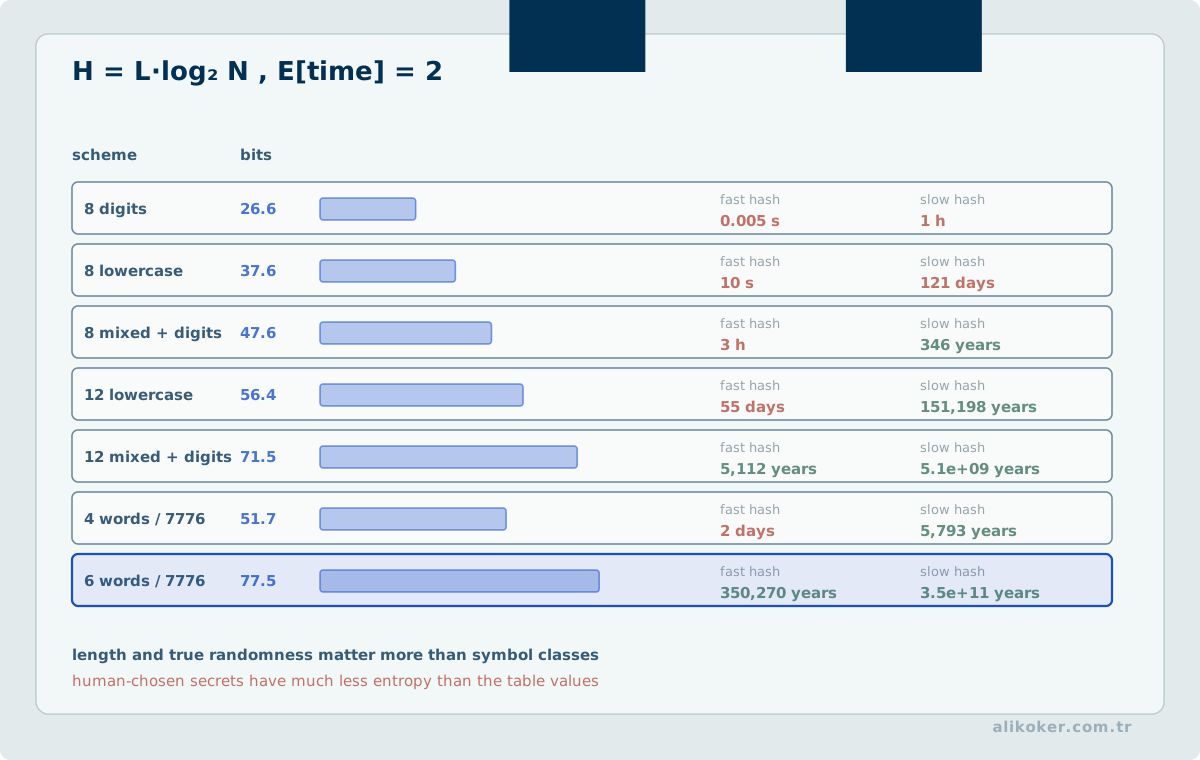
The classical factor classes are:
- something you know,
- something you have,
- something you are.
Two steps are not automatically two factors. Two passwords still belong to one factor class. For phishing resistance, public-key approaches such as FIDO2/WebAuthn can offer materially stronger properties than reusable shared secrets.
4.6. Biometric Security Model
Biometric data is not a replaceable secret. Biometric verification has thresholds, false-accept rates, and false-reject rates. If a biometric template is compromised, the user cannot simply choose a new fingerprint or face. Biometrics should therefore be designed together with sensor trust, liveness detection, device binding, and additional authentication factors.
4.7. Access-Control Models
The source includes RBAC, ABAC, mandatory access control, and related models. They solve different problems:
- RBAC: maps permissions to organizational roles.
- ABAC: evaluates subject, resource, action, and environmental attributes.
- MAC: applies centrally enforced classification policy.
- DAC: permits controlled discretion by resource owners.
Large systems often combine models. A role can grant baseline access while attributes such as device trust, time, location, or data classification further constrain a decision.
4.8. Least Privilege and Separation of Duties
Least privilege means granting the smallest set and duration of privilege necessary for the task. Just-in-time elevation, time-limited roles, and approval-based access follow directly from this principle.
Separation of duties prevents one individual from controlling an entire critical process. Payment creation and approval, code authoring and production release, or key generation and key use can be deliberately separated.
Unit 5: Network Foundations, Protocol Stack, and Network Defense
5.1. Network Security
Network security combines topology, protocols, segmentation, routing, name resolution, transport security, and observability.
5.2. Segmentation
The purpose of segmentation is to reduce the blast radius of a compromise, not merely to create VLANs.
client network -> application tier -> data tier
                       |
                  management plane
Flows should be justified and restricted by default.
5.3. Firewalls
Stateful firewalls track connection state; application-aware controls can inspect additional protocol context. No firewall automatically fixes broken authorization or unsafe application logic.
5.4. DNS, TLS, and VPNs
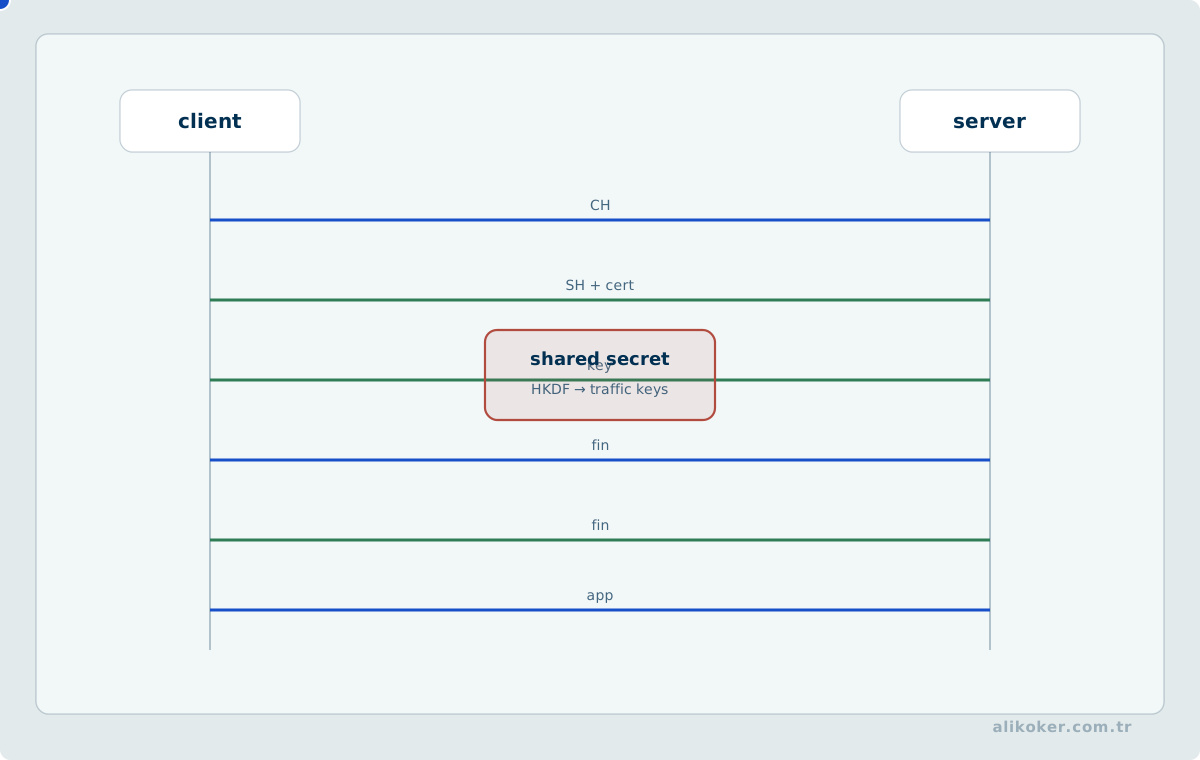
DNS is a security dependency because name resolution influences where clients connect. TLS protects confidentiality and integrity in transit when certificate validation and key management are correct. A VPN protects a path but does not automatically make a device or user trustworthy.
5.5. Communication Models and Security Boundaries
Communication, channels, encoding, noise, and feedback also have security implications. In security engineering these ideas become protocol questions:
who sends?
what is sent?
over which channel?
to whom?
under which identity?
with what integrity protection?
can the message be replayed?
what trust assumption governs the response?
Noise also has an operational meaning: detection systems must separate a low-volume malicious signal from high-volume legitimate activity.
5.6. Observability and Trust Boundaries in Encrypted Traffic
Packet capture does not imply that all transmitted data are readable at the application layer. In TLS-protected sessions, a network observer may measure connection timing, packet lengths, directions, volume, and certain visible protocol fields; recovering application content requires separate capabilities such as authorized endpoint or key access. DNS and TLS privacy extensions may further change metadata visibility.
Classifications derived from flow features must not be reported as conclusive evidence of communication content. Models may produce false positives and negatives because of traffic shaping and overlapping patterns among legitimate applications. Correlation between endpoint telemetry and network observations requires explicit identity, time, and session association rules.
5.6.1. Classification of Observable Fields in Encrypted Communications
Encrypted-traffic analysis distinguishes network headers, exposed handshake attributes, traffic shape, and encrypted application content. Depending on the observation point, source and destination IP addresses, ports, directions, sizes, and timing may be observable. Visibility of TLS handshake fields varies with protocol version and features such as Encrypted ClientHello. Processing QUIC Initial payloads does not make 1-RTT application contents accessible.
Analytical features can be represented as f=(duration, packet_count, byte_count, direction_ratio, size_distribution, timing). These can support classification of applications or behaviors, but shared IP addressing, NAT, VPNs, connection coalescing, and background traffic constrain identification certainty. Content inferred from traffic timing or sizes must not be reported as directly observed plaintext.
A security control should separately record what is measured, what is model-derived, and what remains unavailable because of encryption. Classification performance must be tested under false positives and distribution shifts without implying that encrypted payloads were decrypted.
5.7. Network Protocol Foundations of Security Controls
The source's OSI, Ethernet, IP, topology, IPv4/IPv6, and subnetting material is directly relevant to security design. Controls can only be placed correctly when engineers understand how data is represented and forwarded.
The OSI model is not a perfect picture of implementation; it is a useful decomposition model. For example:
- MAC addressing and VLAN behavior are primarily link-layer concerns,
- IP routing is a network-layer concern,
- TCP/UDP ports are transport-level concepts,
- HTTP, DNS, SMTP, and proprietary protocols operate at application layers.
Each layer exposes different security mechanisms and failure modes.
5.8. Ethernet and Local-Network Security
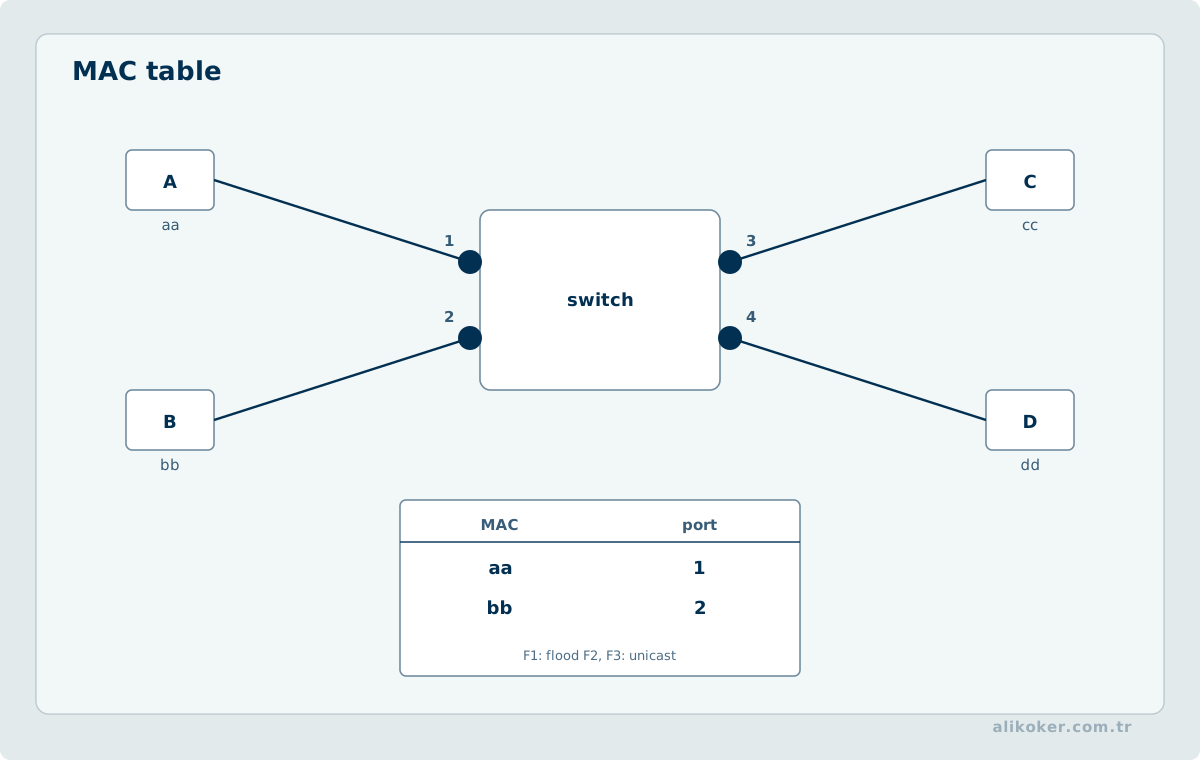
A source or destination MAC address is not a strong identity. MAC spoofing is practical and modern clients may randomize addresses for privacy. Switched Ethernet still faces risks such as ARP poisoning, incorrect VLAN configuration, and unauthorized device attachment.
Local defense can combine:
- switch-port controls,
- VLAN segmentation,
- 802.1X/NAC,
- DHCP snooping and Dynamic ARP Inspection where appropriate,
- access logging,
- visibility into east-west traffic.
5.9. Security Effects of IP Addressing and Subnetting
Subnetting is more than address conservation; it can help express trust boundaries. Management, user, server, production, and guest networks can be separated. A VLAN boundary alone, however, is not an access-control decision. Traffic between segments should pass through an enforcement point or equivalent distributed policy.
IPv6 changes some scanning assumptions but does not eliminate the security problem. Neighbor Discovery, Router Advertisement, dual-stack behavior, and fallback paths need explicit treatment.
5.10. Topology and Common Failure Points
Bus, star, ring, tree, mesh, and hybrid topologies can be interpreted in security terms by asking which compromise or failure can affect which region.
A centralized star design can simplify management while creating a critical hub. Mesh designs can improve availability but create more trust relationships and policy complexity. Security architecture should consider topology together with availability and blast radius.
5.11. DNS Security
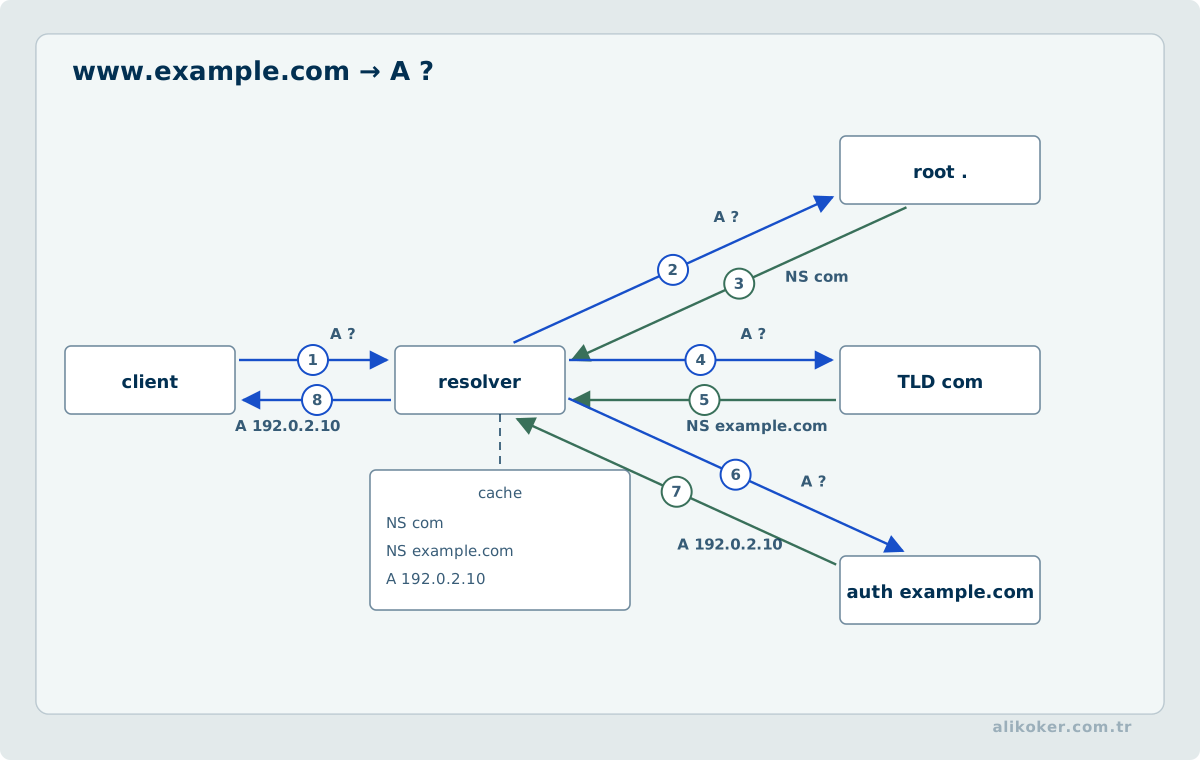
DNS is not merely a convenience service. It can support reconnaissance, command-and-control, phishing, and data exfiltration. Defensive design includes:
- controlled resolver use,
- query/response logging,
- DNSSEC validation where appropriate,
- avoiding reputation-only decisions,
- monitoring unusual high-entropy or long queries,
- correct separation of internal and external DNS roles.
5.12. TCP/UDP and State
TCP maintains connection state; UDP is connectionless. This matters for firewall and IDS behavior. A stateful firewall can make decisions based on connection state, but malicious application content can still travel through a valid TCP session. Transport validity is not application security.
5.13. Firewall Architecture
A firewall is a policy-enforcement point, not a device that “makes the Internet safe.” Packet filters, stateful firewalls, application proxies, and next-generation firewalls inspect different amounts of context. Good rule design generally favors:
- default deny,
- opening only what is required,
- explicit source/destination/service scope,
- expiration for temporary rules,
- removal of shadowed or obsolete rules,
- auditable change control,
- separation of management and data planes.
An any-any rule is not only broad access; it also makes it harder to determine which flows were expected during incident analysis.
5.14. Distinguishing NAT from Access Control
NAT can hide internal addressing from direct external use, but it does not replace policy enforcement. Port forwarding, state tables, outbound sessions, and proxies make “NAT means firewall” a false assumption. Address translation and authorization solve different problems.
5.15. VPN and Tunnel Security
A VPN protects traffic between endpoints; it does not prove that either endpoint is trustworthy. A compromised client can carry apparently legitimate traffic through the tunnel. VPN design therefore includes identity, device posture, access scope, split tunneling, certificate/key lifecycle, and logging.
5.16. DoS and DDoS Engineering
Denial of service can exhaust different resources:
- bandwidth,
- connection/state tables,
- TLS handshake CPU,
- thread or connection pools,
- database execution,
- disk or queues,
- expensive API operations.
Mitigation must match the bottleneck: rate limits, connection limits, caching, per-request budgets, circuit breakers, upstream filtering, and horizontal scaling solve different failure modes. Capacity testing should measure saturation behavior and tail latency, not only average throughput.
5.17. Spoofing and Source Identity
IP addresses, MAC addresses, e-mail From fields, and HTTP headers are not inherently trustworthy identities. Source verification must depend on the actual guarantees of the protocol and surrounding control plane. Reverse DNS or client IP is often insufficient as an identity mechanism, especially through proxies and NAT.
5.18. ARP, DHCP, and Local-Network Attacks
ARP lacks authentication and can be poisoned. Rogue DHCP can distribute malicious gateways or DNS servers. Defense may include DHCP snooping, Dynamic ARP Inspection, port security, and 802.1X in addition to endpoint security.
5.19. Wireless-Network Security
Wireless networks remove the physical cable boundary. Hidden SSIDs are not a security control. WPA2/WPA3 configuration, enterprise authentication, sound EAP methods, certificate validation, and guest/corporate separation matter. Evil-twin access points become particularly effective when clients fail to validate the authentication server.
5.20. Protocol Stacks and Attack Surface
Protocol knowledge is not only a networking concern. Security engineers need to understand which layer a control can observe, because a control cannot reliably protect what it cannot interpret. The OSI model is not a literal blueprint of modern applications, but it remains useful for separating responsibilities.
5.21. Trust Assumptions Across Layers
A simplified path is:
application data
 -> transport (TCP/UDP/QUIC, etc.)
    -> network (IP)
       -> link (Ethernet/Wi-Fi)
          -> physical medium
Each layer depends on assumptions about lower layers. TLS does not eliminate ARP spoofing on a local network, but correct certificate validation and end-to-end encryption can limit what a local attacker learns from transport interception. Likewise, segmentation does not repair a broken application authorization model.
5.22. Ethernet, MAC Addresses, and Local Trust
A MAC address is not a trustworthy user identity. It can be spoofed and a single device may use different addresses on different interfaces. Switch forwarding tables, VLANs, and port controls affect local behavior. A VLAN is not a cryptographic trust boundary; trunk misconfiguration or management-plane compromise can defeat isolation.
5.23. IPv4/IPv6 and Filtering
An IP address is context, not identity. Many clients may share one external address behind NAT, and dynamic assignments change over time. IPv6 introduces large address spaces, link-local addressing, Neighbor Discovery, and multiple simultaneous addresses. Controls written under IPv4-only assumptions can leave IPv6 as an unintended policy path.
Filtering can evaluate protocol, direction, session state, application identity, and—where available—user and device context in addition to source and destination addresses.
5.24. TCP State and Security
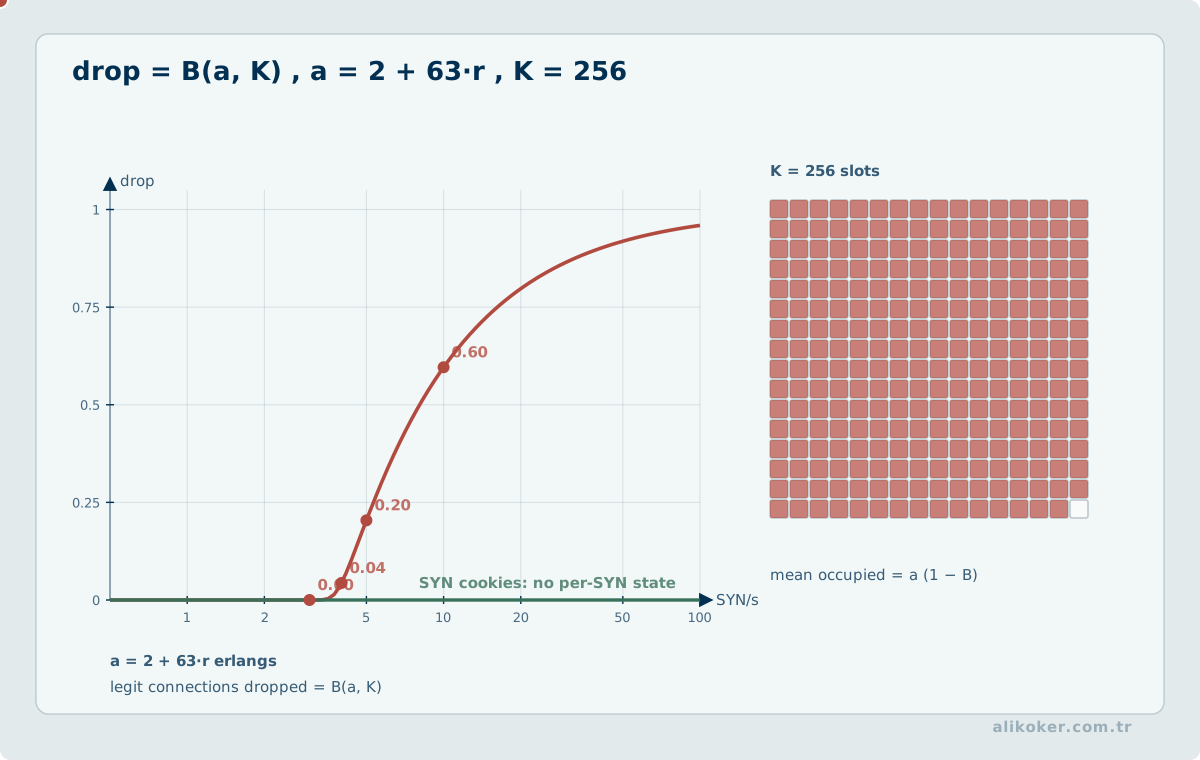
A TCP connection is more than “an open port.” Handshake state, sequence numbers, retransmission, windows, and close behavior affect how security devices reason about sessions. Stateful firewalls have more context than static ACLs, but their state tables also become resources that can be exhausted under attack.
UDP is connectionless, yet DNS, NTP, QUIC, and many real-time systems depend on it. “UDP is connectionless, therefore insecure” is not a valid conclusion; upper-layer protocols can provide authentication, confidentiality, and reliability properties.
5.25. DNS as a Security Dependency
DNS influences where users and applications connect. Cache poisoning, bad delegation, compromised authoritative infrastructure, or client resolver manipulation can redirect traffic. DNSSEC provides cryptographic origin/integrity validation for DNS data; it does not provide confidentiality and does not make a malicious but correctly signed domain trustworthy.
Enterprise DNS is also valuable telemetry. Newly observed domains, abnormal query volume, DGA-like patterns, and unexpected external resolvers can be useful signals.
5.26. Application Protocols and Plaintext Legacy
Protocols such as HTTP, SMTP, FTP, and Telnet were created in environments where security was often added later. Modern assessment must consider not only whether encryption exists, but also downgrade paths, certificate validation, credential exposure, session management, and metadata leakage.
Management protocols belong on a stronger trust boundary. Exposing infrastructure management interfaces to ordinary user networks can turn one application compromise into control-plane compromise.
5.27. Egress Control
A defense that watches only inbound traffic can miss command-and-control and exfiltration after compromise. Egress policy defines which external services and protocols a system actually needs. Excessively strict policy can break operations; unrestricted outbound traffic gives an attacker unnecessary freedom.
Unit 6: Endpoint and Platform Security
Operating systems, hypervisors, container runtimes, and firmware form the trust base below applications.
Typical controls include:
- supported and patched versions,
- least-privileged service identities,
- disabled unnecessary services,
- hardened defaults,
- application allowlisting where justified,
- disk encryption,
- trusted boot,
- endpoint telemetry,
- configuration-drift detection.
Hardening is not a one-time installation step. Expected configuration should be continuously compared with actual state.
Unit 7: Application, API, Software Vulnerabilities, and Runtime Defense
7.1. Application and API Security
OWASP Top 10 is an awareness document, not a complete verification standard. As of 2026, the current released edition is OWASP Top 10:2025, led by Broken Access Control, Security Misconfiguration, and Software Supply Chain Failures.
Major application-risk classes include access-control defects, misconfiguration, supply-chain compromise, cryptographic failures, injection, insecure design, authentication failures, software/data integrity failures, logging and alerting failures, and mishandling of exceptional conditions.
Threat modeling, XSS, SQL injection, SSRF, CSRF, OAuth/OIDC, CI/CD security, and generative-AI application security are treated in depth in Secure Software Engineering.
7.2. Classifying Software Vulnerabilities
The source groups software weakness around memory management, structured-output/injection, race conditions, and side channels. These remain durable classes even as specific technologies change.
7.2.1. Memory Safety
Use-after-free, out-of-bounds access, and buffer overflow remain important in memory-unsafe environments. Controls include memory-safe languages where suitable, safer APIs, compiler hardening, ASLR/DEP, sanitizers, and fuzzing.
7.2.2. Injection and Structured Output
SQL, shell, LDAP, XPath, and template injection share a boundary failure between code and data. Escaping lists alone are fragile; parameterized or structural APIs are preferable.
7.2.3. Race Conditions
TOCTOU flaws and concurrent state changes can invalidate security decisions. A check and the protected operation should not be separated by an attacker-controllable window.
7.2.4. Side Channels
Timing, power, cache behavior, error messages, and packet sizes can leak information. Cryptographic implementations therefore care about constant-time behavior and controlled failure responses.
7.3. Prevention, Detection, and Mitigation
The source separates three approaches:
- Prevention: make classes of defect harder to create using language choice, type systems, safe APIs, and secure defaults.
- Detection: SAST, DAST, SCA, fuzzing, code review, and testing.
- Mitigation: limit impact when defects remain through sandboxing, least privilege, exploit mitigations, and segmentation.
They are complementary layers. A scanner is not a substitute for secure design.
7.4. Runtime Defense
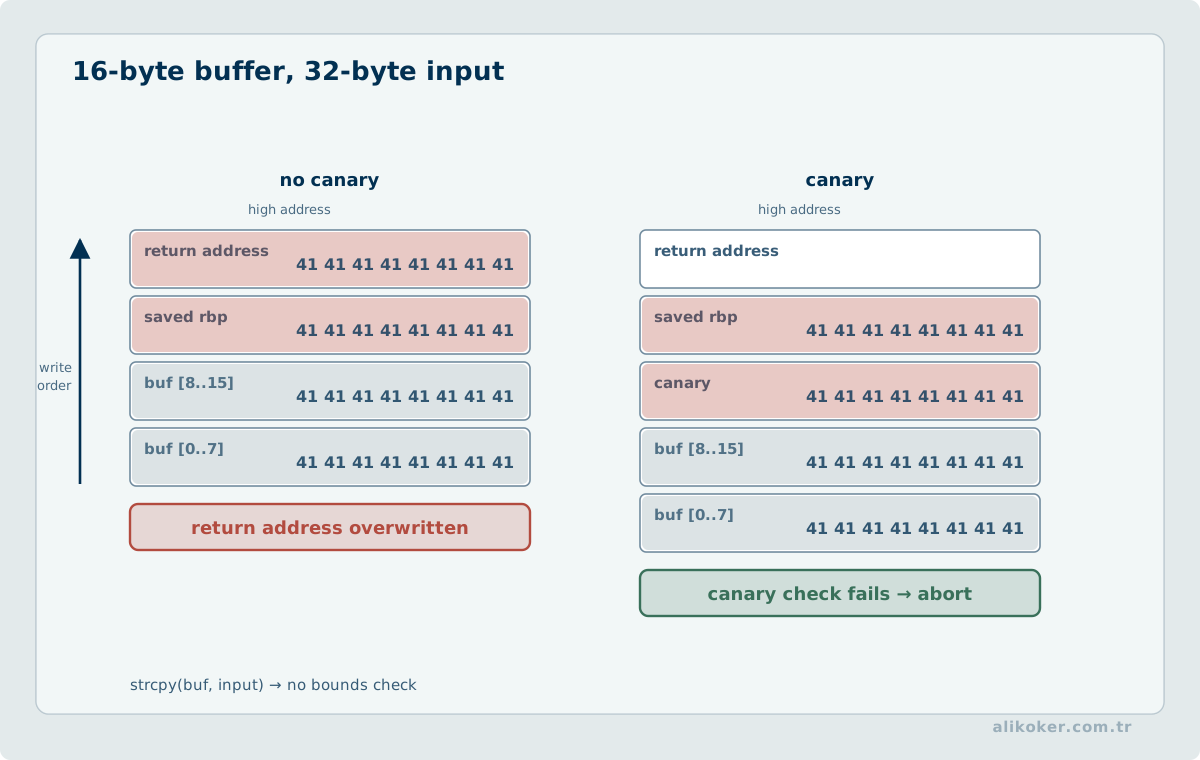
Sandboxing, OS privilege boundaries, container isolation, seccomp-style restrictions, and application authorization can reduce blast radius. A sandbox accepted as a security boundary must itself be threat-modeled for escape paths and host privileges.
7.5. Trusted and Measured Boot
Trusted/measured boot records or validates the system's boot chain. It does not make compromise impossible; it provides additional evidence about startup state and critical components. TPM-backed measurements can support attestation scenarios.
7.6. Web-Session Security
After login, web identity is usually represented by a cookie or token. Theft of that value can bypass password knowledge. Controls include:
- high-entropy session identifiers,
- mandatory TLS,
Secure,HttpOnly, and appropriateSameSite,- session rotation after authentication,
- logout and expiration,
- reauthentication for critical actions.
7.7. CSRF versus XSS
XSS executes attacker-controlled script in a victim's browser context. CSRF causes the browser to send authenticated requests on the victim's behalf. They are different problems. XSS can often bypass CSRF defenses, so output encoding/CSP and CSRF tokens/SameSite controls address different threat classes.
7.8. File-Upload Security
File extensions are insufficient validation. Content type, magic bytes, size, archive expansion, path traversal, and parser risk must be considered. Uploaded content should not become executable inside the web root; expensive parsing should run in isolated workers with explicit resource budgets where practical.
7.9. Software-Integrity Controls
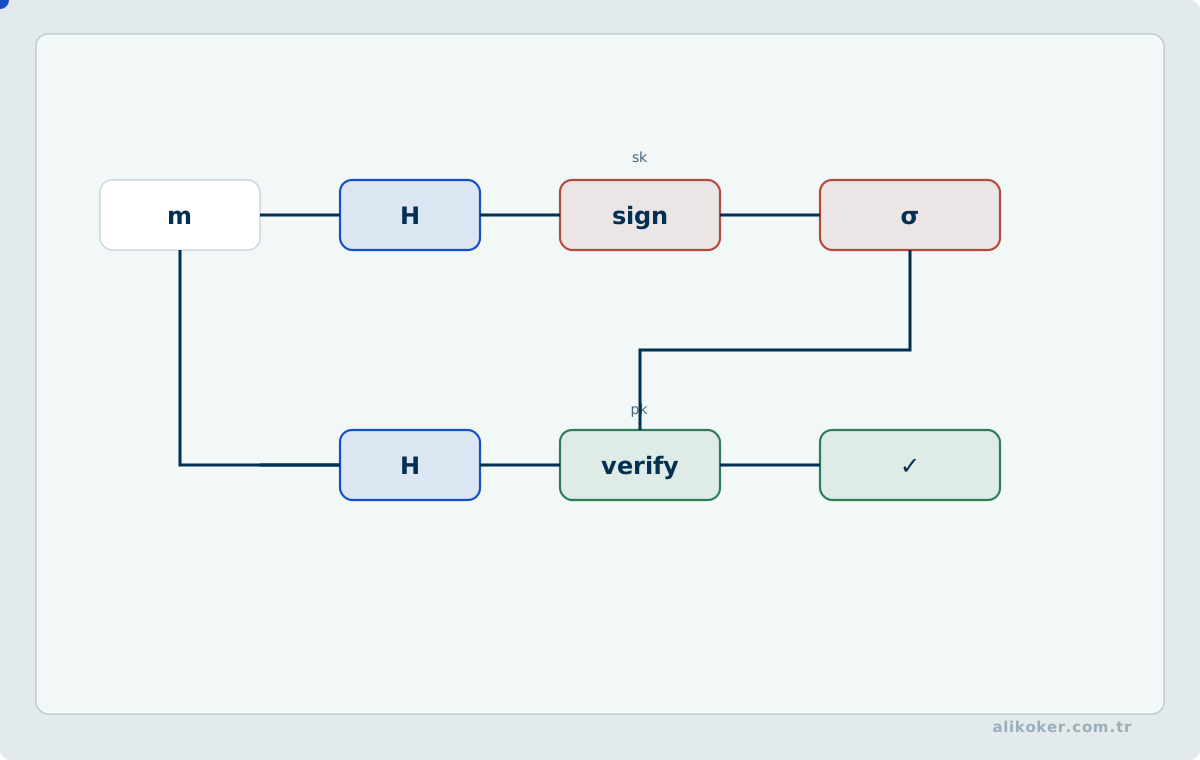
The source treats software integrity as a separate concern. Modern practice extends beyond manually comparing hashes to signed artifacts, provenance, SBOMs, trusted build pipelines, and deployment verification. A signed package is not automatically safe if the signing key or build process is compromised.
7.10. Runtime Mitigation
ASLR, DEP/NX, stack canaries, CFI, sandboxing, and privilege reduction can make exploitation harder or reduce impact. They do not repair the underlying defect. Defense should combine mitigation with actual remediation.
7.11. Preserving Trust Boundaries Across Parser Disagreements
When the same HTTP bytes are parsed differently by intermediary components, distinct security decisions may be applied to what appears to be one request. A reverse proxy and an application server may disagree on header interpretation or message boundaries, allowing hidden or misrouted requests. The underlying weakness is inconsistent protocol interpretation across components rather than one uniquely dangerous character. Client-side sanitization does not replace validation at the server trust boundary.
A defensive design establishes strict parsing and canonicalization at the ingress boundary. Conflicting length indicators, ambiguous duplicated headers, and disallowed encodings should be rejected rather than forwarded into another parser. Identity and authorization context must remain consistent across proxy, application, and data-access boundaries. Framing rules from different HTTP protocol versions must not be conflated; translation between versions is itself a component requiring tests.
Regression tests can validate the defensive contract without publishing exploit payloads: two parsing stages must agree on the canonical method, path, headers, and body boundaries for each accepted input, or the request must be rejected. Diagnostic evidence should identify the stage making that decision without recording raw credentials or personal data. Security observability therefore needs its own data-minimization boundary.
Unit 8: Cryptographic Engineering and the Key Lifecycle
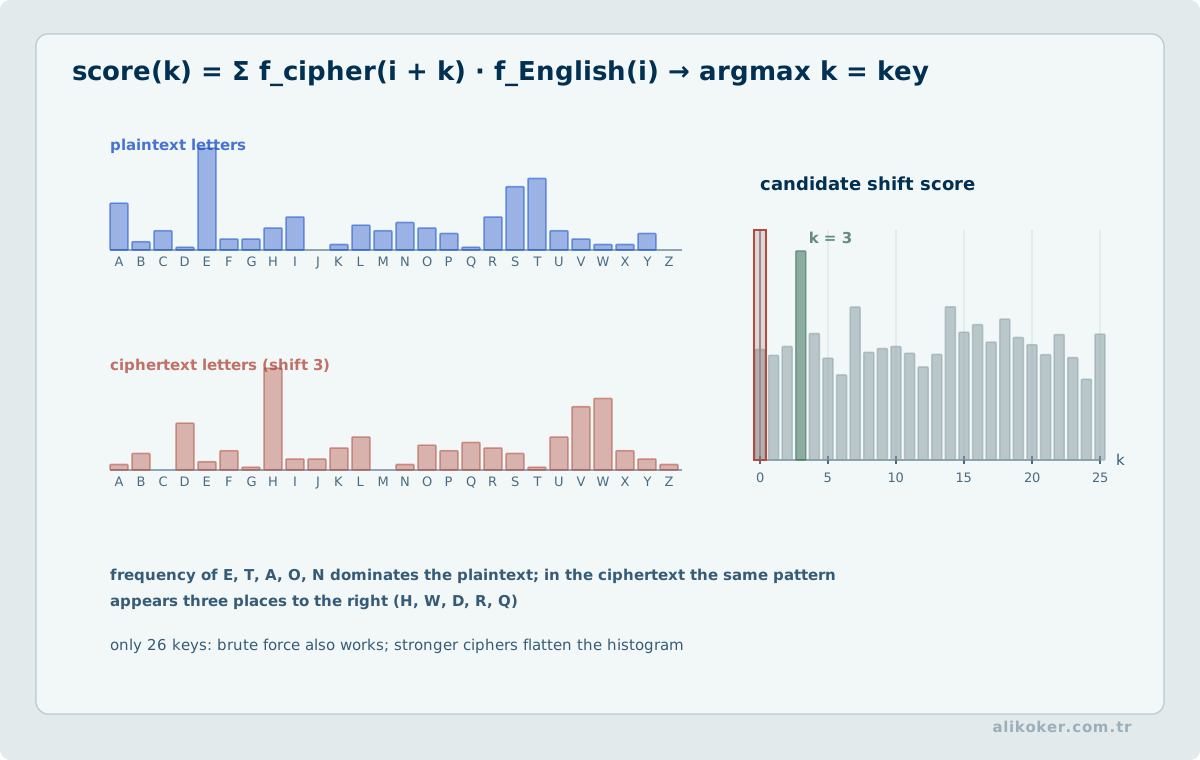
8.1. Cryptography and Key Management
Different primitives solve different problems:
encryption -> confidentiality
hash       -> digest / integrity checking
MAC        -> integrity + shared-secret authentication
signature  -> integrity + private-key authentication
Key lifecycle is often more important than algorithm branding. Generation, storage, access, rotation, backup, revocation, and destruction must be designed.
“Encryption is enabled” is not a sufficient security statement. Modes, nonces, certificate validation, key access, and error behavior matter.
8.2. TLS and PKI
TLS protects confidentiality and integrity in transit; binding the channel to the intended server or client depends on certificate validation. Certificate chain, hostname verification, validity period, key usage, and revocation behavior matter.
root CA
  ↓
intermediate CA
  ↓
leaf certificate
  ↓
private key + identity binding
Protecting the private key is more important than protecting the public certificate. Reusing one private key across many hosts increases blast radius.
8.3. Separate Cryptographic Objectives
Cryptography contains different primitives:
- symmetric encryption provides confidentiality,
- MAC/HMAC provides integrity and authentication,
- hashing produces a fixed-size digest,
- digital signatures support integrity and signer-key verification,
- key agreement derives shared secrets.
A hash is not encryption and has no decryption key. Password storage should use salted, deliberately expensive password KDFs rather than fast general-purpose hashes.
8.4. Key Management Can Be Harder Than Algorithm Selection
A strong algorithm fails under poor key management. The lifecycle includes:
generation -> distribution -> storage -> use -> rotation -> revocation -> destructionSecrets embedded in source code, logs, or configuration repositories remain severe weaknesses regardless of algorithm strength. HSMs, TPMs, secure enclaves, and centralized secret managers can form trust boundaries appropriate to different use cases.
8.5. Cryptographic Agility
Algorithms and key sizes should not be assumed permanent. Cryptographic agility allows controlled migration when standards or threat models change. Agility should not mean exposing arbitrary weak algorithm selection at runtime; the supported profile must remain constrained.
8.6. Collision Resistance versus Password Guessing
The collision examples in the source illustrate an important distinction. A hash collision is two inputs producing the same digest. Password guessing compares candidate passwords against stored verification material. A collision weakness does not automatically mean all password hashes can be inverted efficiently.
Cryptographic engineering is more than choosing an algorithm. A strong primitive can be undermined by a bad protocol, nonce reuse, weak key storage, or incorrect certificate validation.
8.7. Roles of Symmetric and Asymmetric Cryptography
Symmetric encryption is efficient for high-volume data but requires parties to share secret key material. Asymmetric mechanisms can solve key-establishment and digital-signature problems at greater computational cost. Modern protocols are commonly hybrid:
asymmetric/key agreement
 -> session key
    -> symmetric authenticated encryption
A digital signature does not provide confidentiality. Encryption by itself may not provide integrity. AEAD constructions are designed to provide confidentiality and authenticated integrity together.
The security of an encryption primitive and the security of the system deploying it are different claims. AES supplies a block-cipher foundation for confidentiality when keys and modes are handled correctly; it does not itself authenticate a user, authorize access, establish that a key has not been stolen, or verify message integrity. When using AEAD, plaintext must not be released to downstream systems until its authentication tag has been successfully verified. Key generation, distribution, storage, rotation, and revocation remain separate trust boundaries.
A post-quantum migration assessment distinguishes public-key agreement and digital-signature assumptions from symmetric data encryption. Conventional public-key schemes exposed to Shor-type attacks and brute-force symmetric-key search affected by Grover-type speedups have different attacker models. Migration planning considers data confidentiality lifetime, protocol agility, key inventories, and interoperability; deploying AES alone is not a substitute for those system-level controls.
8.8. Hashes, MACs, and Password Derivation
A cryptographic hash is unkeyed. A MAC uses a secret key. Password storage is a different problem and should use a password-oriented, deliberately expensive KDF rather than a fast general-purpose hash. A salt prevents identical passwords from producing identical stored values; it does not make guessing impossible.
8.9. Nonce and IV Reuse
For many modes, nonce or IV uniqueness is part of the security assumption. Reusing a nonce under the same key can catastrophically damage confidentiality or integrity in stream/AEAD constructions. Nonce generation is therefore protocol design, not an incidental call to a random-byte function.
8.10. PKI and Certificate Validation
An X.509 certificate does not mean “this server is safe.” It binds a key to an identity under a trust chain. A client must validate:
- chain construction,
- hostname/SAN matching,
- validity period,
- relevant key-usage/policy constraints,
- revocation status where required.
Training users to bypass certificate warnings as a normal workflow destroys the trust model.
8.11. Key Lifecycle
Key security spans:
generation -> distribution -> storage -> use -> rotation -> revocation -> destructionSecrets embedded in source repositories, long-lived shared credentials, or uncontrolled backup copies weaken a system even when the algorithm is strong. HSM/KMS-style services can reduce direct exposure of keys, but authorization and audit remain necessary.
8.12. Cryptographic Agility — Deeper Treatment
Algorithms, key sizes, and protocols evolve. Hard-wiring one cryptographic choice into persistent data structures and business logic creates migration debt. Agility means versioned, planned transition—not arbitrary runtime algorithm selection.
8.13. Key Lifecycle, Versions, and Compromise Scope
Cryptographic control selection begins with the lifetime of protected data rather than a product list. Identify which records a key protects, how many records it covers, and which service role uses it, then define generation, distribution, active use, rotation, suspension, and destruction. In an incident, replacing a key file is insufficient: the inventory of affected ciphertext, continuing decryption needs, and access policies must be assessed together. Forward secrecy of past sessions and long-term encrypted archival storage are different risk problems.
The existence of NIST's 2024 ML-KEM, ML-DSA, and SLH-DSA standards does not mandate indiscriminate immediate replacement of every deployed RSA/ECC system. Migration begins with the secrecy horizon of stored or transmitted data, hybrid protocol support, device and library compatibility, and certificate lifecycle. RFC 9846 supersedes RFC 8446 while retaining TLS version 1.3; its rules on KeyShare reuse and obsolete-version negotiation illustrate why implementation controls must be revised independently of version labels. Mathematical constructions are developed in Cryptology; the cybersecurity engineering concern here is operational risk and control selection.
Unit 9: Vulnerability Management, Vulnerability Discovery, and Assurance Techniques
9.1. Vulnerability and Patch Management
Vulnerability management is a lifecycle:
inventory
 -> discovery
 -> validation
 -> contextual risk
 -> ownership
 -> remediation / mitigation
 -> retest
 -> closure
CVSS helps describe technical severity, but business value, exposure, exploit availability, and compensating controls determine local priority.
Patch management contains two risks: leaving known vulnerabilities unresolved and destabilizing production through uncontrolled change. Testing, phased rollout, rollback, and maintenance windows are therefore security controls as well as operational practices.
9.1.1. Verification Chain for Automated Vulnerability Findings
Agent-assisted security scanning may report a candidate vulnerability; actual risk depends on input reachability, exploitation preconditions, privileges, and the affected asset. A static-analysis data flow may not model every runtime defense, while a clean dynamic scan does not establish safety for untested paths.
The vulnerability record should include version, affected component, reproduction procedure, trust boundary, impact, and remediation evidence. False positives and unverified reports need distinct states. Automated analysis can support vulnerability prioritization but cannot authorize production changes.
9.2. Risk-Based Vulnerability Management
CVE and CVSS provide common vocabulary, but local priority cannot be derived from CVSS alone. Internet exposure, exploit availability, asset criticality, prerequisites, compensating controls, and business impact all matter.
technical severity
× exposure
× exploitability
× asset value
× control effectiveness
→ local risk priority
9.3. Patch Management and Change Risk
Failing to patch creates risk; untested patching can also create risk. Critical environments can use:
- inventory and affected-version detection,
- technical/business risk assessment,
- testing,
- staged rollout,
- rollback planning,
- verification,
- exception and compensating controls.
9.4. Vulnerability Discovery and Security Assurance
Vulnerability engineering can be separated into classification, prevention, detection, and mitigation. That remains a useful engineering distinction because no single technique can find or prevent every defect.
9.5. Static Analysis
Static analysis inspects source or intermediate code without normal execution. Data flow, control flow, taint, type systems, and pattern rules can identify candidate defects. Its advantage is broad path coverage; its cost is false positives and model limits. Findings need contextual prioritization.
9.6. Dynamic Analysis and Sanitizers
Dynamic techniques observe actual executions and can expose memory violations, races, and undefined behavior. They see only executed paths, so coverage and input quality are critical.
9.7. Fuzzing
Fuzzing is especially effective against parsers and protocol surfaces. Structure-aware or coverage-guided fuzzers use knowledge of input grammar or execution coverage. A crash is not automatically remote code execution, but it is a reproducible anomaly that deserves security triage.
A mature fuzzing pipeline retains deterministic seeds, deduplicates and minimizes crashes, and produces reproducible test cases. “Inputs per second” alone is not a quality metric.
9.8. Evidence of Exposure and Remediation in Runtime Vulnerabilities
A CVE identifier, component version, distribution patch status, reachable code path, and exposed attack surface are distinct facts. Equating a packaged version directly with an upstream release can yield incorrect vulnerability conclusions when fixes are backported. Prioritization considers actual reachability, exploit prerequisites, data sensitivity, and compensating controls.
Remediation evidence goes beyond reporting an updated package: confirm the effective binary or source patch, negative-test results, runtime restart status, and relevant dependent components. Claims of protection remain bounded by the specified attacker capabilities and deployment configuration.
Unit 10: Detection, Telemetry, Security Operations, and Measurability
10.1. Detection, Telemetry, and Security Operations
Useful detection starts with meaningful data sources:
- identity providers,
- operating systems,
- EDR,
- DNS,
- firewalls and proxies,
- application audit logs,
- databases,
- cloud control planes,
- flows and packet capture where justified.
10.2. IDS/IPS and SIEM
IDS/IPS systems detect patterns or behavior; SIEM platforms aggregate, normalize, and correlate events. Collecting more logs does not automatically create better detection. Semantic quality, time synchronization, retention, and low-noise rules matter.
10.3. MITRE ATT&CK
ATT&CK organizes adversary behavior into tactics and techniques. It is not a risk score or product checklist. A useful application is visibility mapping: which behaviors are observable, and where are the blind spots?
10.4. Accountability and Trustworthy Logging
The source emphasizes logs as a basis for accountability. A strong logging design requires:
- a consistent time source,
- identity and session context,
- protection from unauthorized modification,
- centralized collection,
- access control,
- retention policy,
- scalable search and correlation.
Logs alone do not create accountability. Shared accounts, shared API keys, and clock drift make attribution difficult.
10.5. Threat Intelligence and Telemetry
Threat intelligence is more than a list of IOCs. Strategic, operational, tactical, and technical intelligence differ in purpose. IP/domain/hash indicators can decay quickly, while behavior and TTP information often lasts longer. Intelligence becomes useful when mapped to the organization's assets and detection capabilities.
10.6. SIEM and Correlation
A SIEM collects and correlates events; it cannot turn semantically poor logs into reliable evidence. Engineers must first understand time, identity, field meaning, and missing-record behavior. Coverage of high-value attack paths is more useful than an ever-growing count of generic rules.
10.7. IDS/IPS Boundaries
Signature-based detection is strong against known patterns; anomaly methods can identify new variants but typically produce more false positives. An IPS can interrupt service when it makes a wrong decision, so blocking policy must account for availability risk as well as detection accuracy.
10.8. Continuity and Measurability in Security Operations
Security operations should reduce unacceptable risk, not merely generate alerts. Metrics should therefore emphasize detection quality, response delay, and control effectiveness rather than raw alert volume.
10.9. Telemetry Quality
Collecting logs is not the same as observability. Reconstructing events requires consistent identity, time, source, destination, action, and outcome fields. Clock synchronization and stable event identifiers are core correlation dependencies.
10.9.1. Construction and Validity of TLS Handshake Fingerprints
TLS fingerprints summarize observed and normalized client or server handshake parameters. JA3 derives a client fingerprint from selected protocol version, cipher-suite, extension, and supported-group attributes; JA3S uses server-handshake attributes. JA4-family methods use distinct normalization rules and attribute selection. The exact scheme, version, and extracted fields must be specified.
Handling of GREASE values, attribute ordering, incomplete handshakes, and TLS implementation updates can change the output. Different clients may share one fingerprint; one client may produce different fingerprints across versions or configurations. A fingerprint is therefore not a user identity, definitive device identity, or malware diagnosis.
Validation should separate collision rate, sample coverage, stability across versions, and known versus unknown classes. A network observer can interpret a fingerprint reliably only in conjunction with capture completeness and parsing status.
10.9.2. Passive Device Profiling from TCP/IP and DHCP Attributes
Passive device profiling compares observable properties such as TCP SYN option ordering, MSS, window scale, TTL class, TCP window size, and DHCP option sets against reference patterns. Features from different layers do not have identical reliability: routers decrement TTL, NATs and proxies may transform headers, and a DHCP client library may not uniquely identify the host operating system.
Outputs should describe candidate_class, matching_features, contradictions, confidence_interval rather than asserting a certain operating-system identity. Abstaining when the capture lacks required features is a valid analytical outcome. Self-declared application values such as User-Agent are not independent identity evidence unless corroborated by other observations.
Validation should span network topologies, middleboxes, virtual machines, and current software versions; device diversity and class imbalance in the reference dataset should be documented.
10.10. Event, Signal, Alert, and Case
raw event
 -> signal
    -> alert
       -> correlated case
          -> confirmed incident
Not every event should become an alert. Otherwise analyst capacity is consumed by noise. Detection engineering defines the intended threat behavior, required data sources, known false-positive causes, and test cases for a rule.
10.11. Contextual Anomaly Detection in User and Entity Behavior Analytics
UEBA evaluates access events using user roles, assigned tasks, document classifications, access channels, and temporal patterns rather than frequency thresholds alone. An observation vector may be expressed as x=(principal, resource, action, time, context). An anomaly score s(x) can measure rarity but does not directly establish unauthorized or malicious behavior. Seasonal patterns, shifts, and changes in assigned duties must be represented in the baseline.
Alarm thresholds require consideration of verified incident base rates and review capacity. Even high specificity may yield poor positive predictive value for rare events. Concept drift and entitlement changes require periodic reassessment. Data minimization and access controls are mandatory for the behavior-analytics system itself.
10.12. Limits of MTTD and MTTR
Mean detection or response time can hide long-tail incidents. A team may close most alerts quickly while one severe compromise remains undetected for days. Percentiles and severity-stratified measures often expose the operational distribution more clearly.
10.13. False-Alert Budgets and Leakage in Neural Threat Detection
If event prevalence is 0.1% in one million records, there are 1,000 actual events. With 90% recall and 1% false-positive rate, a detector raises roughly 900 true and 9,990 false alerts; precision is 900/(900+9,990)≈8.26%. This example shows why a promising single metric cannot establish operational feasibility.
If splits ignore attack campaigns, hosts, or time blocks, a model can learn source fingerprints instead of attack behavior. Report PR-AUC, alert-volume budgets, detection delay, and analyst workload. Using a quantum-inspired network does not remove these validation requirements.
10.14. Relating Physical Emissions to Security Telemetry
Network logs, endpoint events, and electromagnetic measurements are different kinds of observations. An RF spectral anomaly does not by itself prove exfiltration; missing network connections do not demonstrate absence of physical emissions. Correlation requires timestamps, clock synchronization, device operating state, measurement band, and plausible alternative noise sources.
Physical observations should be treated as corroborating evidence rather than definitive security diagnoses. False positives can arise from power converters, nearby wiring, other devices, and the measurement arrangement itself. Findings should be assessed against bounded, testable hypotheses and other authorized evidence.
10.15. Red Flags, Alerts and Verified Incidents
A red flag is a contextual or rule-based reason to investigate, not necessarily a statistical outlier. A network traffic surge may reflect backup activity, maintenance or attack. Raw observations, anomaly scores, thresholds, correlated cases and independent findings should remain separate. With rare attacks, false alerts can exceed analyst capacity; grouping and prioritisation are part of detection performance. Statistical decision theory is developed in Anomaly Detection.
Unit 11: Incident Response, Recovery, and Secure Return to Service
11.1. Incident Response
NIST SP 800-61 Rev. 3, finalized in April 2025, superseded Rev. 2 and reframed incident response as a risk-management capability spanning CSF 2.0.
A practical flow remains recognizable:
preparation
 ↓
detection and validation
 ↓
containment
 ↓
eradication
 ↓
recovery
 ↓
learning and improvement
Containment decisions affect business continuity and evidence. Immediately powering down a compromised system may stop damage but can also destroy volatile evidence. Digital Forensics Engineering covers that trade-off in detail.
11.2. Incident Response versus Digital Forensics
Incident response prioritizes limiting attacker impact and protecting service. Digital forensics places stronger emphasis on repeatable evidence analysis. The goals can conflict: powering down a system can stop damage while destroying volatile evidence. Containment decisions therefore balance business impact, security impact, and evidential value.
11.3. Trusted Recovery
Recovery is more than restarting servers. Restoring before root cause and persistence are removed can reintroduce the adversary. Trusted recovery combines:
- clean or verified images,
- credential rotation,
- persistence checks,
- vulnerability remediation,
- increased monitoring,
- data-integrity verification.
Unit 12: Malware, Botnets, Ransomware, and Persistence
12.1. Malware, Ransomware, and Persistence
Malware labels describe behaviors and objectives rather than mutually exclusive categories. A sample can simultaneously be a downloader, credential stealer, persistence mechanism, and ransomware component.
Ransomware resilience requires more than antivirus:
- reduce initial-access paths,
- constrain privilege escalation,
- restrict lateral movement,
- protect high-value identities,
- maintain isolated or immutable backups,
- test restoration,
- detect and isolate rapidly.
A backup is not a recovery capability until restoration time and integrity have been tested.
12.2. Malware, Botnets, and Persistence Engineering
Malware has historically been labeled as viruses, worms, Trojans, rootkits, spyware, and ransomware. Modern samples can combine several behaviors, so defenders often gain more value by modeling capabilities rather than relying only on family labels.
12.2.1. Behavioral Analysis of Malicious Application Traffic
Analysis of malicious application traffic combines command syntax, session direction, repetition patterns, payload sizes, and connection failures. Matching a named malware-family signature only establishes an investigative hypothesis because versions, packing, encryption, and configuration can vary.
A protocol parser must derive read-only fields without executing untrusted commands. Command types must be distinguished from payload content; unknown messages must not silently be interpreted as valid commands under a permissive fallback. Features for possible command-and-control behavior include interarrival distributions, message lengths, bidirectional flow ratios, and destination diversity.
Evaluation must include benign remote-administration traffic with similar characteristics as well as confirmed malicious samples. Detection scores are not independent proof of attribution, unauthorized action, or endpoint compromise.
12.3. Behavioral Dimensions
A malicious component may combine:
- execution,
- privilege escalation,
- credential access,
- persistence,
- discovery,
- lateral movement,
- command and control,
- collection,
- exfiltration,
- impact.
This model allows controls to map to behavior instead of a product or malware family name.
12.4. Persistence
Persistence varies across operating systems and application ecosystems: startup mechanisms, scheduled tasks, services, extensions, credentials, cloud access keys, and authorized application integrations can all become persistence channels. The deeper question is not simply “which malicious file remains?” but “which trust relationship gives the attacker renewed access?”
12.5. Rootkits and Visibility
Rootkits attack the reliability of the defender's observation mechanism. A tool running inside the same compromised host can receive a manipulated view from user-space or kernel-level hooks. High-assurance investigations may therefore correlate several observation planes:
host telemetry
+ network telemetry
+ hypervisor/EDR view
+ trusted external acquisition
Independent perspectives reduce common blind spots.
12.6. Botnet Architecture
A botnet coordinates many compromised nodes under attacker control. Centralized command and control is easier to operate but can be fragile if key servers are removed. P2P or multi-tier C2 can increase resilience. Domain generation, fast flux, proxy chains, and abuse of legitimate cloud services can complicate detection.
Botnets are not limited to DDoS. They can provide spam, credential theft, proxy services, cryptomining, or data theft.
12.7. DDoS as a Resource Problem
DDoS attacks can exhaust different resources:
- network bandwidth,
- connection state,
- TLS/cryptographic CPU,
- application threads,
- database connections,
- third-party quotas or cost budgets.
Defenses must match the exhausted resource. Rate limiting, SYN protection, CDN/Anycast, caching, queue bounds, and application-cost controls solve different problems.
12.8. Long-Running Targeted Operations
“APT” is not one tool or malware type. It is a framing for sustained, objective-driven threat operations with meaningful resources. For defense, the useful questions are dwell time, goals, techniques, and detection/response capability rather than the label itself.
Attack progression is rarely perfectly linear. An adversary can move repeatedly among discovery, credential access, persistence, and lateral movement. Defenses therefore need multiple opportunities for detection and interruption.
Unit 13: Cloud, Mobile, IoT, OT, Distributed, and Cyber-Physical Security
13.1. Cloud, Mobile, IoT, and OT Security
Cloud security depends on the shared-responsibility boundary, which differs across IaaS, PaaS, and SaaS. Identity and control-plane events can be more important than the traditional network perimeter.
Mobile security combines application sandboxing, hardware-backed keys, device integrity, local storage, and backend API controls.
IoT and OT environments add constraints such as long device lifecycles, limited update capacity, real-time requirements, physical consequences, legacy protocols, and safety obligations. Patching an industrial controller is not operationally equivalent to patching a stateless web server.
13.2. Trust in Distributed Systems
The source devotes substantial attention to decentralized P2P systems, clustering, coordination, and distributed-system vulnerabilities. Security is not achieved by hardening each node independently. Inter-node identity, message integrity, replay handling, membership, and coordination protocols are themselves trust boundaries.
Representative threats include:
- Sybil attacks using many false identities,
- Eclipse attacks that isolate a node behind adversary-controlled peers,
- routing attacks,
- pollution or index poisoning,
- collusion among malicious nodes,
- denial of service against resources or coordination mechanisms.
13.3. Distinguishing CAP Properties from Security Guarantees
The source connects consistency, availability, and partition behavior with attack scenarios. A conceptual boundary is important: CAP is not itself a security theorem. It describes behavior under network partition. An adversary can nevertheless create or exploit partition-like conditions, making architectural trade-offs visible during a security incident.
13.4. Consensus and Commit Protocols
Two-phase commit coordinates atomic transactions but is not a Byzantine-fault-tolerant security protocol. Raft/Paxos-family designs generally address crash-fault assumptions, while Byzantine-fault-tolerant systems use different fault models. Security properties must be derived from the protocol's actual assumptions.
13.5. Security and Safety in Cyber-Physical Systems
The source covers CPS domains such as aerospace, automotive, energy, healthcare, manufacturing, and building automation. Cyber incidents in these systems can produce physical consequences. The problem becomes:
cybersecurity risk
      +
physical process state
      +
safety constraint
      +
real-time requirement
      = CPS security problem
A firewall or inspection gateway can itself influence latency and deterministic timing, so security changes require engineering validation against process constraints.
13.6. Defense Layers for CPS
Useful layers include:
- physical access control,
- IT/OT segmentation,
- secure remote access,
- protocol and asset inventory,
- allow-listing,
- passive network visibility,
- controlled change management,
- verified backups and recovery,
- plans for transitioning to a safe physical state.
“Patch immediately” can be infeasible when production downtime, certification, or vendor support is constrained. Compensating controls then become essential.
13.7. Critical Infrastructure and Sector Security
Cyber effects in energy, transportation, communications, healthcare, and other critical sectors can produce physical or societal consequences. In these environments, confidentiality is only one objective; safety, continuity, and physical-process integrity may dominate.
13.8. IT versus OT Constraints
In enterprise IT, patching or restarting a host can be ordinary maintenance. In OT/CPS environments the same action can stop production or affect a safety function. Long-lived devices and legacy protocols may lack modern authentication or encryption.
OT defenses commonly rely on:
- asset inventory,
- zones and conduits / segmentation,
- controlled remote access,
- allow-listing where feasible,
- passive visibility,
- disciplined change control,
- secure maintenance procedures,
- independent safety layers.
13.8.1. Function Codes and Transaction Semantics in Industrial Protocols
Industrial protocols such as Modbus TCP, EtherNet/IP, and IEC 60870-5-104 require application-field and transaction-state parsing, not merely transport-port identification. In Modbus TCP, the MBAP Transaction Identifier, Unit Identifier, and length fields affect response correlation; function codes and exception responses have different semantics. For IEC 60870-5-104, frame categories, sequence fields, and ASDU contents establish communication state.
Observation of a control message does not prove that the requested physical operation occurred. The request, protocol response, field-device state, and independent process measurement are separate evidence layers. Repeated commands, disconnections, and restart behavior can have different safety and security consequences.
A parser must consume bounded data for unknown function codes, validate declared lengths, and avoid inventing values for unread fields. Passive monitoring carries a risk profile distinct from active queries in critical systems.
13.9. Safety versus Security
Safety engineering prevents hazardous physical states. Security controls unauthorized or malicious behavior. They interact but are not the same problem. Because a cyberattack can target a safety system, cyber risk analysis must include credible physical hazard scenarios.
13.10. Physical Access
Ports, cabinets, serial links, maintenance laptops, and removable media can be as important as network controls. “Not connected to the Internet” is not a security architecture when vendor maintenance paths or portable media still cross the boundary.
13.11. Sector-Specific Risk
Technical severity alone is insufficient. Physical process impact, human safety, environmental consequences, production loss, regulation, and recovery time affect risk. The same software flaw can be moderate on an office workstation and unacceptable on a safety-critical controller.
13.12. Faraday Cages and RF Shielding in Defense in Depth
A Faraday cage is a conductive enclosure intended to reduce propagation of specified field components across a boundary. Device enclosures, shielded cables, and room-sized structures share electromagnetic principles but cannot be evaluated with identical frequencies, fixtures, or acceptance conditions. Doors, apertures, contact resistance, and cable penetrations may dominate performance. Bulk material conductivity and installed-enclosure effectiveness therefore are different properties.
Within defense in depth, RF shielding complements physical access control, endpoint protection, secure configuration, cryptography, logging, and incident response. Weakening radio links does not automatically block other communication paths, processes executing inside the enclosure, or physical access. Security engineering must account for false-negative tests, discontinuities introduced during maintenance, and unexpected device interfaces.
Field theory belongs in Electronics I and II, measurement methodology in Measurement Systems, and mobile-evidence isolation in Digital Forensics Engineering. Cybersecurity integrates these disciplines through threat modeling and control assurance.
13.13. Testing Electromagnetic Controls and Residual Risk
A shielding requirement cannot be reduced to a single attenuation number. Evaluation identifies frequency range, electric or magnetic field component, near- or far-field behavior, equipment operating modes, accessible measurement points, and reproducibility. Containing emissions originating inside the enclosure and protecting a device against external interference are distinct experimental directions; reciprocity applies only under appropriate physical conditions.
A test plan records baseline conditions, instrument calibration, repetitions, detection limits, and worst-case observation conditions. Good attenuation at one frequency cannot establish performance in every band. Opening doors or changing cable penetrations alters boundary conditions, potentially requiring verification after maintenance.
IEEE 299-2006 is a historical test standard and is inactive as of 2026; an ongoing P299 revision project is not equivalent to a newly published replacement standard. The academic treatment should emphasize clearly defined testing scope rather than unconditional reliance on a named edition.
Unit 14: Software and Supply-Chain Security
The real software supply chain includes far more than source code:
source code
+ dependencies
+ compiler
+ build runner
+ package registry
+ base image
+ deployment manifest
+ firmware
= actual supply chain
An SBOM improves visibility but does not automatically establish trust. Package provenance, signatures, build isolation, secret management, dependency policy, and update processes remain necessary.
NIST SSDF v1.1 is the current final SSDF publication. NIST published Version 1.2 as an initial public draft in late 2025; draft and final status should not be conflated.
14.1. SCA, Inventories, and SBOMs
Modern applications depend on direct and transitive third-party components. Software Composition Analysis can provide visibility into versions, known vulnerabilities, and licensing. An SBOM is a shareable representation of the component inventory. Neither proves that an application is secure; both are inputs to risk management.
14.2. Build and Source Integrity
Source repositories, CI systems, package registries, build agents, and signing keys are part of the software supply chain. A secure codebase can still be compromised through an untrusted build path.
A stronger pipeline is:
reviewed source
 -> controlled build
    -> dependency verification
       -> signed artifact
          -> signature/policy validation at deployment
14.2.1. Repository Instructions and the Software Supply Chain
Dependency documentation, sample scripts, and repository instructions read by coding agents form a supply-chain surface through which untrusted content can influence execution decisions. A third-party installation script does not have the same authority as an authorized user request. Component provenance, integrity, expected execution effects, and permission boundaries require separate assessment.
Adding packages, downloading scripts, or altering build steps during remediation introduces further review obligations. Software composition analysis and SBOMs improve component visibility but do not necessarily detect malicious instructions or eliminate every execution risk. Secure delivery requires both source validation and operation authorization.
Unit 15: People, Culture, Social Engineering, Espionage, and Threat Intelligence
15.1. People, Process, and Social Engineering
Calling people “the weakest link” can hide design failures. Secure processes should limit the impact of predictable human error.
For example, a high-risk payment change that requires an independent verification channel is more resilient to phishing than a process that accepts e-mail instructions alone.
Awareness training should be combined with MFA, transaction verification, separation of duties, permission boundaries, and anomaly detection.
15.2. Human Factors Are Part of the System
The source treats governance, culture, awareness, education, and testing as distinct human-security concerns. Describing users as the “weakest link” can hide design failures. Secure systems should not require exceptional vigilance for routine operation.
Good security UX tends to:
- make critical warnings rare and meaningful,
- use secure defaults,
- make phishing-resistant authentication usable,
- support recovery from mistakes,
- reduce security fatigue.
15.3. Awareness, Education, and Exercises
Awareness means recognizing that a threat exists; education teaches correct behavior; exercises develop the ability to act under pressure. Phishing simulations and tabletop exercises should reveal process friction and incentive problems rather than merely produce failure percentages.
15.4. Insider Threat and Industrial Espionage
Valuable assets include research, manufacturing recipes, engineering designs, pricing, bid strategy, customer data, and source code—not only passwords and personal information. Insider risk can be malicious or accidental. Controls can include:
- data classification,
- need-to-know access,
- DLP and telemetry,
- privileged-access control,
- joiner/mover/leaver processes,
- monitoring sensitive export channels.
15.5. Auditing Low-Volume and Long-Duration Data Exfiltration
Policy violations are not limited to large transfers in a single session. Low-volume exports spread across long intervals may evade instantaneous bandwidth or document-count thresholds. Document sensitivity, entitlement, business process, export channel, and repeated access patterns should be correlated across time windows.
Cumulative risk analysis must account for multiple seemingly independent access events that may belong to the same legitimate task. Reading, viewing, copying, and external transmission are distinct events; a source-read record does not prove exfiltration. Security findings also require access restrictions, integrity protection, and retention controls.
15.6. Social Engineering Is Also a Technical-Control Problem
Training alone cannot solve social engineering. E-mail authentication, phishing-resistant MFA, out-of-band approval for critical changes, macro/script controls, safe document handling, and least privilege reduce the amount of damage that one deceptive message can cause.
15.7. Verification of Open-Source Findings
Technical findings collected from open sources should be assessed by source identity, publication time, observation time, collection method, and susceptibility to later edits. Numerous pages copying the same claim do not constitute independent corroboration. Verification asks whether independent channels support an event through distinct primary evidence.
An address, domain, communication trace, or file digest is an observed technical indicator, not attribution to a particular actor. Reused infrastructure, dynamic addressing, forged records, and temporal mismatch can lead to false associations. Each finding should retain a source URI or record identity, access timestamp, content digest, relevant time interval, and verification state; confidence must be justified by the quality of evidence.
Unit 16: Resilience, Continuity, and Integrated Security Engineering
16.1. Resilience Assessment
Perfect prevention is not realistic. A strong security system aims to:
make attack harder
detect early
limit blast radius
preserve evidence
recover safely
feed root cause back into design
Cybersecurity engineering is therefore a discipline of system design and risk management under uncertainty. Products and attack techniques evolve, but asset visibility, explicit trust boundaries, least privilege, defense in depth, observability, incident readiness, and verified recovery remain durable principles.
16.2. Cyber Resilience
Resilience is the ability to continue critical service at an acceptable level during attack and recover to a trusted state. Core capabilities include:
- inventory of critical assets and dependencies,
- offline or immutable backups,
- tested restoration,
- segmentation,
- alternate communication paths,
- predefined incident roles and decision authority,
- explicit RTO/RPO,
- post-incident learning.
Creating backups and successfully restoring service are different capabilities; untested backups are not a resilience guarantee.
16.3. Backup Resilience Against Ransomware
Having backups does not guarantee recoverability. Backup credentials should be isolated where practical, destructive access should be constrained, and restores should be tested. If an attacker controls the backup management identity, the number of copies alone does not create resilience.
16.4. Business Continuity and Disaster Recovery
Business Continuity aims to preserve business functions; Disaster Recovery focuses more directly on restoring technology and data services. RTO represents an acceptable service-outage target and RPO an acceptable data-loss window. These objectives drive architecture and cost; “zero loss and zero downtime” can be prohibitively expensive or physically unattainable.
16.5. Exercises and Verification
A tabletop exercise, technical failover test, and real restore test validate different things. Critical systems should seek evidence that recovery procedures work, not merely that documents exist. Exercise findings should become tracked remediation work.
Unit 17: Cryptographic Algorithm Security Status and Lifecycle
Older exams often reduce cryptography to algorithm names and key lengths. Modern security engineering starts with the security service that is required and then verifies the current status of the algorithm and protocol.
17.1. Encryption, Hash, MAC, Signature, and Key Agreement Are Different Services
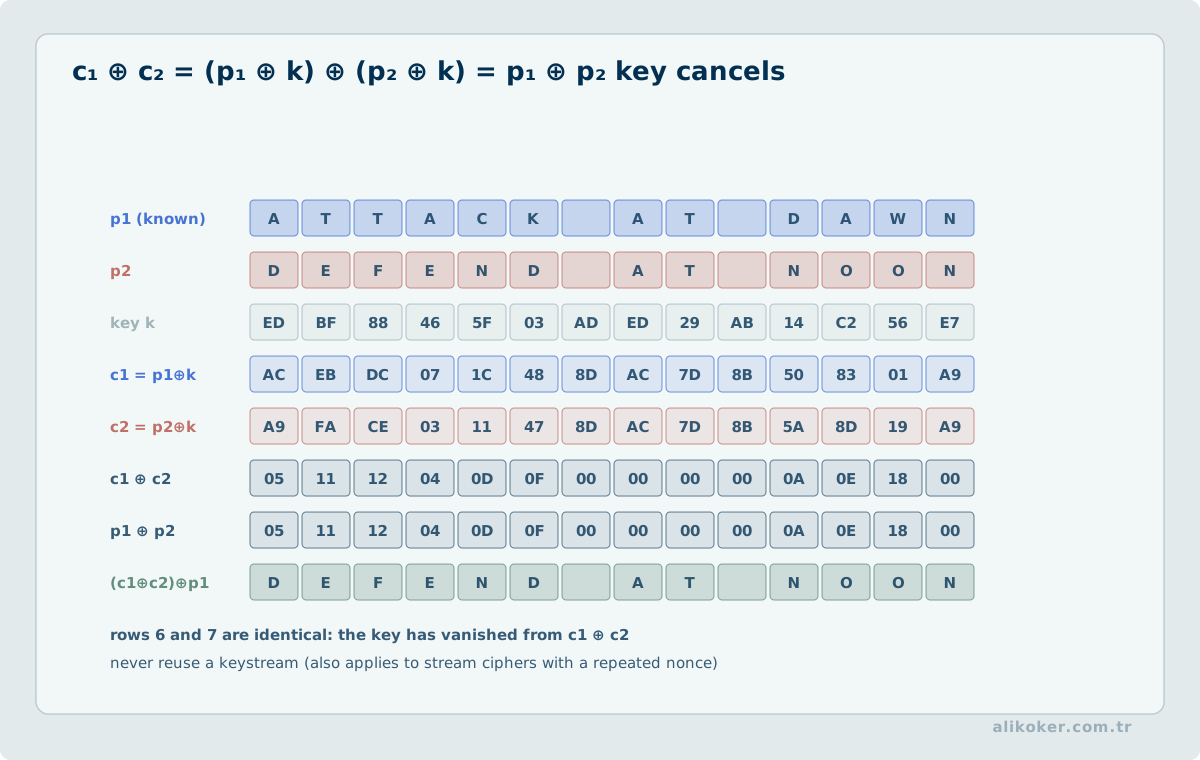
encryption:
  confidentiality

hash:
  unkeyed digest / integrity building block

MAC:
  keyed integrity + source authentication among key holders

digital signature:
  private-key signing
  public verification
  integrity + origin/authenticity

key agreement:
  parties derive shared key material
A hash alone does not authenticate a sender, and a digital signature does not provide confidentiality.
17.2. DES and TDEA/3DES
DES is historically important but is not an appropriate choice for new encryption designs.
TDEA/3DES extended the lifetime of DES as a transition mechanism. NIST transition guidance disallows three-key TDEA for applying new cryptographic protection after 2023, and the TDEA recommendation was withdrawn in 2024. Legacy processing of previously protected information is a different case.
Exam recognition is therefore useful, but historical knowledge must not be interpreted as a modern recommendation.
17.3. AES
AES is a modern symmetric block-cipher family using a 128-bit block and 128-, 192-, or 256-bit keys.
The algorithm name alone does not define a secure system. Mode of operation, IV/nonce handling, authentication, and key management also matter.
Authenticated-encryption designs are generally preferable when both confidentiality and integrity/authenticity are required.
17.4. Separate the Roles of RSA
RSA should not be modeled simply as "encrypt all application data with the public key."
Asymmetric cryptography can participate in key establishment/key transport, digital signatures, and certificate/PKI identity.
Padding and scheme selection are part of the security contract.
17.5. Diffie-Hellman and ECDH
Diffie-Hellman establishes shared key material; it does not authenticate the peer by itself.
Real protocols can combine:
key agreement
+
authentication
+
key derivation
+
context/transcript binding
ECDH applies the key-agreement idea to elliptic-curve groups.
17.6. WEP, WPA2, and WPA3
WEP is a historical wireless-security technology and should not be treated as a modern security solution.
WPA2 remains deployed in many environments; security depends on configuration, credentials/EAP method, certificate validation, and patch state.
WPA3 provides newer wireless-security mechanisms, but secure deployment still depends on the whole authentication and update chain.
Hidden SSIDs and MAC filtering are not replacements for cryptographic protection.
17.7. AH and ESP in IPsec
AH is associated with packet integrity/authentication services and does not provide encryption.
ESP can provide payload confidentiality and can be configured with integrity/authentication services.
NAT and deployment realities can make AH difficult to use. Current profile support should be verified for the actual environment.
17.8. Cryptographic Lifecycle Instead of Algorithm Trivia
Cryptographic status changes over time:
acceptable
-> deprecated
-> legacy-only
-> disallowed / withdrawn
The existence of an algorithm in an exam source does not make it appropriate for a new design.
Security engineering should jointly evaluate required service, current standard status, parameters, protocol binding, and key lifecycle.
Unit 18: DDoS Resilience, Resource Asymmetry, and Layered Defense
The central engineering question in DoS/DDoS is not "which attack tool was used?" but which scarce defender resource can be consumed at low or distributed attacker cost. This resource model remains useful even when specific packet names and attack tools change.
18.1. Three Primary Resource Axes
Real attacks can combine several mechanisms, but a useful design classification is:
volumetric       → link capacity / packets per second
state exhaustion → connection tables / memory / kernel state
application cost → CPU / threads / database / dependency / billing quota
If the access link is saturated, an application rate limiter may never see the packets it is supposed to reject. Conversely, a low-bandwidth request can consume expensive database or application work. A mitigation must therefore be placed before the resource it protects becomes the bottleneck.
18.2. Reflection and Amplification
With some UDP-based services, an attacker can send a request carrying a spoofed victim source address to a third-party service; the reply is then sent to the victim. The third-party service acts as a reflector. If the response is substantially larger than the request, the mechanism also creates amplification.
A conceptual amplification factor is:
amplification ≈ response bytes / request bytesThe ratio is not a complete capacity model. Reflector population, response-rate limiting, path MTU and fragmentation, upstream filtering, and packet rate all matter.
An important part of defense therefore lies outside the victim: reducing the ability of networks to emit packets with forged source addresses. Source-address validation described by BCP 38 / RFC 2827 and RFC 3704 is an ecosystem-level control for this reason.
18.3. SYN Flooding and State Cost
A TCP server can retain temporary state during connection establishment. A SYN flood attempts to exploit the rate of new connection attempts and the lifetime of half-open state to consume backlog or related resources.
Robust defense is not simply "increase the queue." RFC 4987 discusses multiple mitigations and their trade-offs. Engineering options can include:
- source-address filtering,
- SYN cache/cookie mechanisms,
- connection or SYN proxies,
- measured timeout and queue sizing,
- upstream filtering.
A proxy can move state away from a backend, but it does not eliminate attack cost; it changes where the cost is paid. The proxy's own CPU, memory, and connection-state capacity must be tested.
18.4. Cost Asymmetry at the Application Layer
A small HTTP request is not necessarily cheap. One request can trigger:
TLS work
+ authentication
+ expensive search
+ cache miss
+ DB join/sort
+ external-service call
+ large response
Application defense can therefore benefit from cost-aware budgets rather than one global request-per-second number. Endpoint class, authenticated versus anonymous identity, query complexity, concurrency, and downstream cost can justify different budgets.
In critical services, rate limiting can itself harm legitimate availability. Limits should follow trust boundaries and service priorities; a small abusive population should not be able to consume a global budget that punishes all authenticated users.
18.5. Layered DDoS Defense Architecture
No single control covers every resource axis:
source validation / anti-spoofing
        ↓
upstream capacity + filtering / scrubbing
        ↓
Anycast / CDN / edge distribution
        ↓
L3/L4 state protection
        ↓
L7 admission + rate/cost control
        ↓
application backpressure
        ↓
database / dependency protection
Anycast can distribute traffic across locations but does not create infinite capacity. A scrubbing service moves filtering upstream while introducing routing, latency, failover, and operational dependencies. CDNs are highly effective for cacheable traffic, while authenticated and dynamic origin work still requires protection.
18.6. Backpressure and Load Shedding
Accepting unlimited work and allowing every request to time out is often the worst overload behavior. Unbounded queues increase latency and memory consumption, while client retries can create a positive feedback loop.
A controlled design can combine:
bounded queues
+ concurrency limits
+ admission control
+ deadlines / timeouts
+ retry budgets
+ graceful degradation
Load shedding rejects lower-priority work early so that scarce capacity remains available for critical work. Which requests may be shed is not purely a technical choice; it depends on product and SLA semantics.
18.7. Capacity Testing and Observability
DDoS preparation should not begin with the first production attack. Controlled tests should observe at least:
- throughput and packet rate,
- p50/p95/p99 latency,
- error and timeout rate,
- concurrent connection/state counts,
- CPU and memory,
- queue depth,
- DB-pool and downstream saturation,
- dropped or rejected work.
The goal is not a single "maximum RPS" value. It is to understand how the system degrades after saturation begins. Fail-open can violate security; fail-closed can violate availability. The intended failure mode must be designed for each trust boundary.
18.8. Evidence and Safe Rollback During an Incident
An emergency rule can cause a second outage if deployed without control. Temporary blocks or rate-limit changes should record:
purpose
scope
start time
expected effect
rollback condition
owner
After the incident, temporary controls should not silently become permanent configuration. A post-incident review should use telemetry to verify which mechanism actually reduced resource pressure. DDoS resilience is therefore a discipline of measurable capacity, controlled degradation, reversible intervention, and evidence-based improvement, not merely packet blocking.
18.9. Reliable Defense and DoS Resilience in Cybersecurity
Security and reliability are not independent bolt-on features; both shape how a system contains faults and abuse. In cybersecurity engineering, blast radius is constrained by designing network, identity, data, and resource boundaries together; least privilege, secure defaults, recovery procedures, and post-incident learning are complementary layers of the same defensive model. In denial-of-service scenarios in particular, the protection mechanism itself must not consume the availability it is intended to preserve.
- Test that a defense control does not become the bottleneck under overload.
- Apply privilege separation and multi-party approval to critical actions based on risk.
- Design secure recovery and evidence preservation together in incident response.
References
- Celozzi, Salvatore; Araneo, Rodolfo; Lovat, Giampiero. Electromagnetic Shielding. Wiley-IEEE Press, 2008. ISBN 978-0-470-05536-6.
- Center for Internet Security. CIS Critical Security Controls v8.1. https://www.cisecurity.org/controls/v8-1
- Eric, Mihail. The Modern Software Developer (CS146S). Stanford University, course materials, 2025–2026. https://themodernsoftware.dev/
- Heather Adkins; Betsy Beyer; Paul Blankinship; Piotr Lewandowski; Ana Oprea; Adam Stubblefield. Building Secure & Reliable Systems: Best Practices for Designing, Implementing, and Maintaining Systems. O’Reilly Media, 2020.
- Hjelmvik, E. NetworkMiner 3.2 Source Code: PacketParser and PacketHandlerFramework. NETRESEC.
- IETF. RFC 2827 / BCP 38, Network Ingress Filtering: Defeating Denial of Service Attacks which employ IP Source Address Spoofing. https://www.rfc-editor.org/info/rfc2827
- IETF. RFC 3704 / BCP 84, Ingress Filtering for Multihomed Networks. https://www.rfc-editor.org/info/rfc3704
- IETF. RFC 4732, Internet Denial-of-Service Considerations. https://www.rfc-editor.org/info/rfc4732
- IETF. RFC 4987, TCP SYN Flooding Attacks and Common Mitigations. https://www.rfc-editor.org/info/rfc4987
- IETF. RFC 9000. QUIC: A UDP-Based Multiplexed and Secure Transport. https://www.rfc-editor.org/rfc/rfc9000
- IETF. RFC 9846, TLS 1.3, 2026. https://www.rfc-editor.org/info/rfc9846
- ISO/IEC 27001:2022. Information security management systems — Requirements. https://www.iso.org/standard/27001
- MITRE. ATT&CK. https://attack.mitre.org/
- Modbus Organization. MODBUS Application Protocol Specification V1.1b3. 2012.
- Moolchand Sharma, Nebojsa Bacanin, and Tarik Ahmed Rashid (eds.). Quantum-Inspired Neural Networks: Future Perspectives and Challenges. CRC Press, DOI: https://doi.org/10.1201/9781003682950 (supplied copyright page ©2027).
- NIST SP 800-160 Vol. 1 Rev. 1. Engineering Trustworthy Secure Systems. https://csrc.nist.gov/pubs/sp/800/160/v1/r1/final
- NIST SP 800-207. Zero Trust Architecture. https://csrc.nist.gov/pubs/sp/800/207/final
- NIST SP 800-218. Secure Software Development Framework (SSDF) Version 1.1. https://csrc.nist.gov/pubs/sp/800/218/final
- NIST SP 800-53 Rev. 5. Security and Privacy Controls for Information Systems and Organizations. https://csrc.nist.gov/pubs/sp/800/53/r5/upd1/final
- NIST SP 800-61 Rev. 3. Incident Response Recommendations and Considerations for Cybersecurity Risk Management, 2025. https://csrc.nist.gov/pubs/sp/800/61/r3/final
- NIST. Cybersecurity Framework (CSF) 2.0, 2024. https://www.nist.gov/cyberframework
- NIST. FIPS 197: Advanced Encryption Standard (AES). Updated 2023. https://csrc.nist.gov/pubs/fips/197/final
- NIST. FIPS 203: ML-KEM, 2024. https://csrc.nist.gov/pubs/fips/203/final
- NIST. SP 800-131A Rev. 2: Transitioning the Use of Cryptographic Algorithms and Key Lengths. 2019. https://csrc.nist.gov/pubs/sp/800/131/a/r2/final
- NIST. SP 800-56B Rev. 2: Recommendation for Pair-Wise Key-Establishment Using Integer Factorization Cryptography. 2019; reaffirmed 2026. https://csrc.nist.gov/pubs/sp/800/56/b/r2/final
- OWASP Foundation. OWASP Top 10:2025. https://top10.owasp.org/2025/
- OWASP GenAI Security Project. OWASP Top 10 for LLM Applications. 2026. https://github.com/GenAI-Security-Project/GenAI-LLM-Top10
- RFC 8446. The Transport Layer Security (TLS) Protocol Version 1.3. https://www.rfc-editor.org/rfc/rfc8446
- Ross Anderson. Security Engineering. 3rd ed., Wiley, 2020.
- Dhruba Kumar Bhattacharyya; Jugal Kumar Kalita. Network Anomaly Detection: A Machine Learning Perspective. CRC Press, 2014. https://www.routledge.com/Network-Anomaly-Detection-A-Machine-Learning-Perspective/Bhattacharyya-Kalita/p/book/9780429166877