


Web Programming


A modern web-programming course covering DNS/URL/HTTP/TLS, HTML, CSS, JavaScript, DOM, Fetch/CORS, accessibility and security together with the browser style/layout/paint/composite pipeline, process model, bfcache, and performance.
Web programming is not merely the study of HTML tags or a particular server framework. It requires an understanding of how the browser, DNS, URLs, HTTP, TLS, HTML, CSS, JavaScript, accessibility, security, caching, client state, and server-side application models interact. Historical technologies are placed in context while the current Web platform is treated through standards rather than product-specific recipes.
The Web is continuously evolving. HTML and Fetch are living standards, ECMAScript versions the JavaScript language, and HTTP semantics are intentionally separated from individual transport versions. The goal is therefore to learn durable platform and protocol principles rather than a particular editor, browser, or framework release.
Unit 1: Web Architecture, Addressing, and HTTP Foundations
An HTTP interaction starts by identifying resource identity, request method, preconditions, and expected side effects. A successful status code does not by itself prove application-level integrity; validation and authorization are separate concerns. Relate repeated requests to the method's idempotence semantics. The client-server contract should explain how to handle uncertain completion after network loss or a missing response.
1.1. The Internet and the Web Are Not the Same System
The Internet is the global infrastructure interconnecting IP networks. The Web is an application ecosystem built on that infrastructure using URLs, HTTP, HTML, and browser APIs. E-mail, SSH, DNS, and many other protocols use the Internet without being part of the Web.
This distinction matters architecturally. A web interface may use HTTP while downstream services use a database protocol, message broker, or another transport.
1.2. From client-server to a Distributed Web Request Path
The simplest model has a browser as client and an application as server. A production request often follows a longer path:
browser
-> recursive DNS resolver
-> CDN / edge
-> load balancer / reverse proxy
-> web application
-> cache / database / message broker / downstream service
Every layer changes latency, failure, security, and caching behavior. A page displayed as one UI can contact many origins and services.
1.3. DNS: Resolution and Delegation
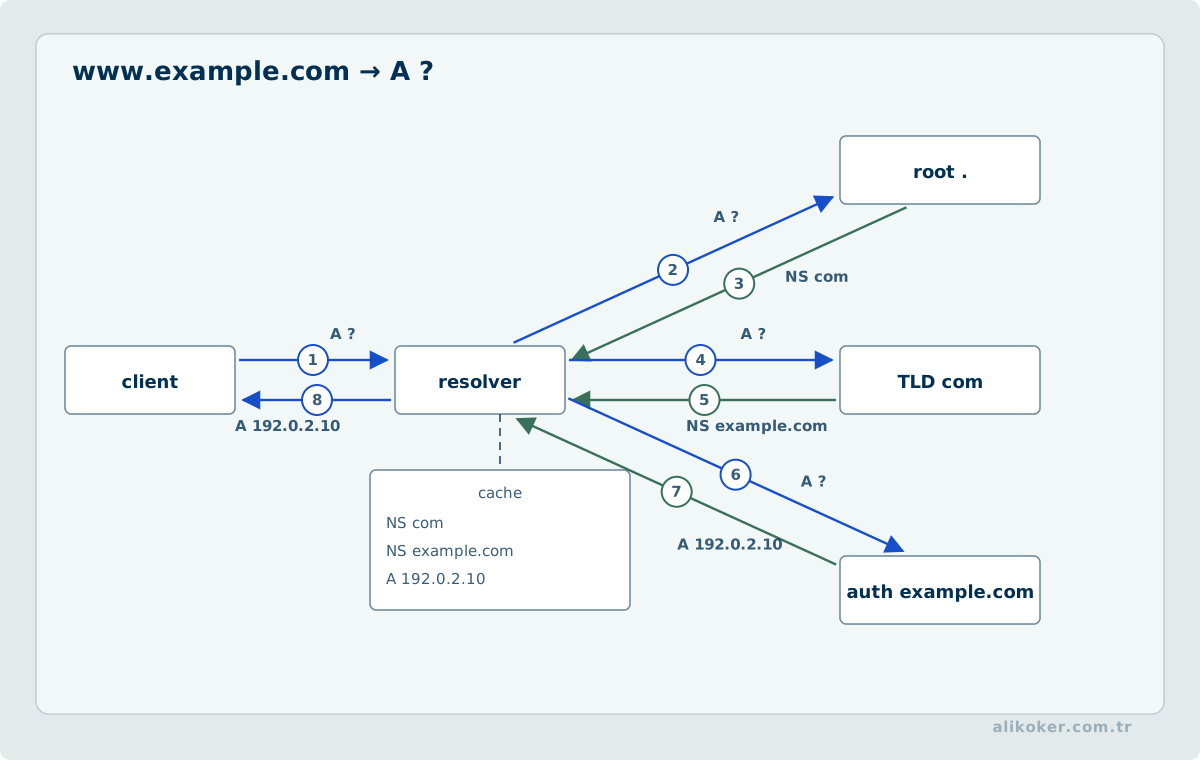
DNS is not merely a hostname-to-IP table. It is a hierarchical distributed naming system. A and AAAA records carry addresses, CNAME aliases, MX mail routing, and TXT various policy or verification data.
browser
   |
   v
recursive resolver
   |
   +--> root
   |      |
   |      v
   +--> TLD
   |      |
   |      v
   +--> authoritative DNS
   |
   v
IP address + TTL
Responses can be cached according to TTL, so a record update is not necessarily visible everywhere immediately. DNSSEC provides an authenticated chain for DNS data integrity and origin; it does not replace TLS or application authentication.
1.4. URL, URI, Origin, and Site
A typical HTTP URL contains scheme, host, optional port, path, query, and fragment:
https://api.example.org:8443/v1/items?id=42#detailsAn origin is the scheme + host + port tuple. https://a.example and https://b.example are different origins. The browser's notion of a site, used by cookie and related policies, is a different concept and should not be treated as a synonym for origin.
A URL fragment is normally not sent in the HTTP request; it is handled by browser navigation or client-side state.
1.5. HTTP Semantics Are Separate from Transport Versions
HTTP defines request-response semantics around resources. HTTP/1.1, HTTP/2, and HTTP/3 share the same core method and status semantics while using different transports and message encodings. HTTP/2 multiplexes streams and compresses fields over a connection. HTTP/3 uses QUIC, a secure multiplexed transport over UDP rather than TCP.
Choosing GET, POST, PUT, PATCH, or DELETE is not just assigning CRUD labels. Safe and idempotent method semantics influence retry, caching, and intermediary behavior.
The idempotent semantics of an HTTP method do not automatically make every application operation safe under network retries. If a payment-creation request is transmitted twice after a connection timeout, two records may be created unless the server supplies an explicit deduplication contract. A timeout does not reveal whether the first request completed. Retryable mutations can use a scoped request identifier, stored outcome, and conflict policy. The identifier's lifetime and the treatment of a repeated key with a different payload must be defined as part of the API contract.
1.6. Anatomy of a Request and Response
A message carries start-line information, headers, and an optional body:
GET /api/devices/42 HTTP/1.1
Host: example.org
Accept: application/json
If-None-Match: "v17"
HTTP/1.1 200 OK
Content-Type: application/json; charset=utf-8
Cache-Control: private, max-age=60
ETag: "v17"
{"id":42,"state":"active"}Headers are protocol metadata. Application data should not be moved into arbitrary custom headers when standard semantics or a body model are more appropriate.
1.7. Do Not Hide Application Failure Inside HTTP Success
Status codes classify the protocol-level result:
2xx: request was successfully processed,3xx: redirection or conditional/cache outcome,4xx: request/access issue attributable to client context,5xx: server could not fulfill the request.
Returning 200 OK with {"success":false} can obscure protocol semantics. Conversely, treating every business-rule rejection as 500 is also incorrect. An API contract should define HTTP status and structured domain error together.
1.8. HTTPS and TLS
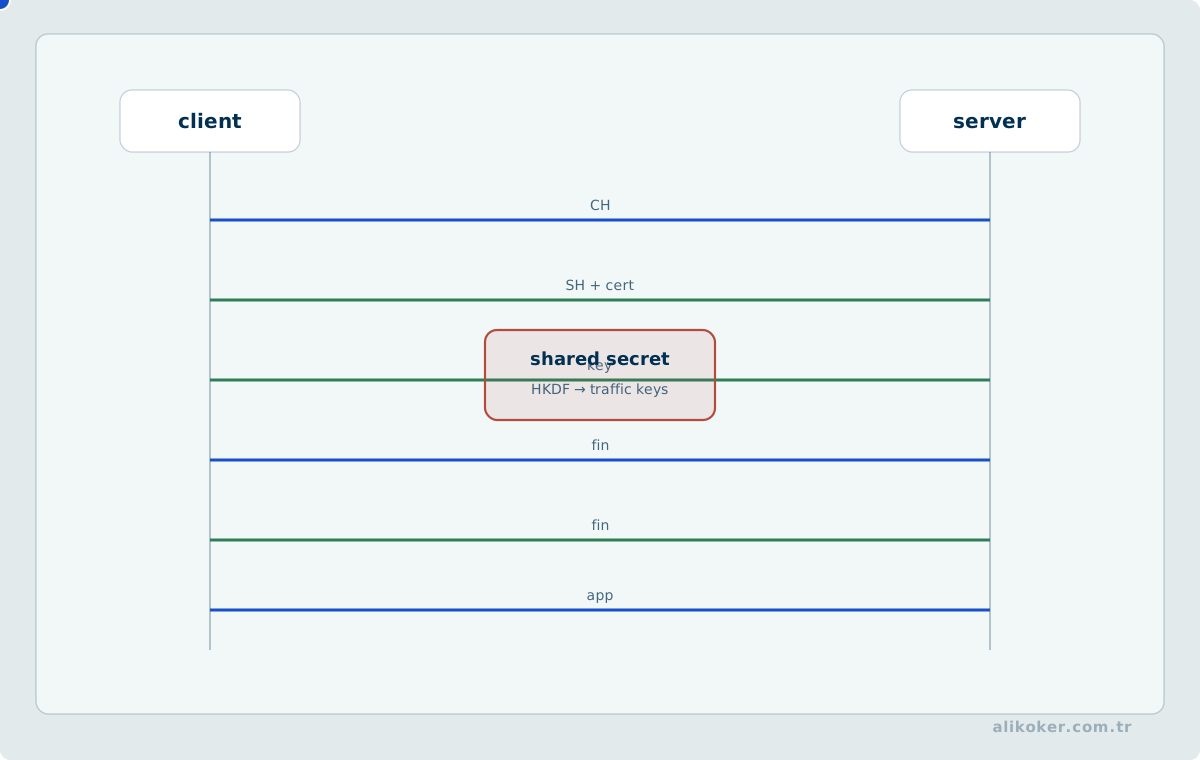
HTTPS is HTTP carried over TLS. TLS provides endpoint authentication through certificates, transport confidentiality, and integrity.
TLS is not application authorization. A correctly certified server can still expose the wrong record to an authenticated user. HTTPS also does not eliminate XSS or injection flaws.
Production deployments should manage HTTP-to-HTTPS redirection, HSTS, modern TLS configuration, and certificate lifecycle as one operational concern.
Unit 2: Browser Platform, HTML, CSS, and JavaScript
2.1. HTML Is the Semantic Content Layer
HTML is a markup language, not a programming language. It defines document semantics and application surfaces. Current HTML is maintained as a living standard, so durable knowledge comes from semantic elements and conformance rather than memorizing an old "HTML5 version."
<main>
  <article>
    <header><h1>System Status</h1></header>
    <p>Updated <time datetime="2026-09-16T09:30:00+03:00">09:30</time>.</p>
  </article>
</main>
A generic div can contain almost anything, but main, nav, article, button, and label provide stronger semantics, accessibility behavior, and maintenance contracts.
2.2. HTML Parsing Is Deliberately Error Tolerant
text/html is not parsed as strict XML. The HTML Standard defines detailed error-recovery rules. Malformed markup can appear to work while producing a DOM tree different from what the source text visually suggests.
The reliable approach is valid semantic markup, conformance checking, and inspection of the actual DOM produced by the browser.
2.3. Forms, Native Controls, and Validation
Native form controls provide keyboard behavior, serialization, accessibility semantics, and built-in constraints.
<form id="device-form">
  <label for="serial">Serial number</label>
  <input id="serial" name="serial" required minlength="6" autocomplete="off">
  <button type="submit">Save</button>
</form>
Client validation improves UX but is not a security boundary. The server must validate all external input again. Disabled fields, checkbox/radio serialization, and multipart file uploads all affect the server contract.
2.4. CSS: Cascade, Layout, and Responsive Composition
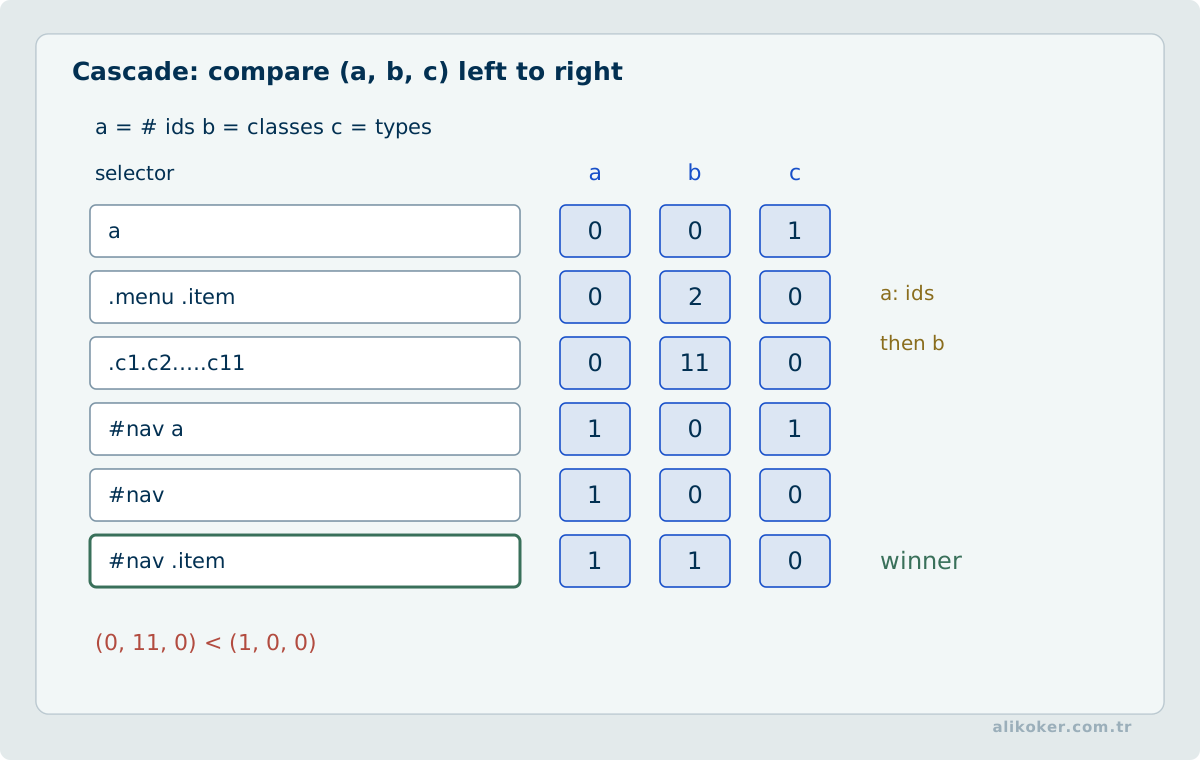
CSS defines much more than color and fonts. Cascade, specificity, inheritance, the box model, and formatting contexts determine layout behavior. Flexbox and Grid are the primary modern layout primitives; media and container queries can express responsive conditions.
.cards {
  display: grid;
  grid-template-columns: repeat(auto-fit, minmax(18rem, 1fr));
  gap: 1rem;
}

.card { container-type: inline-size; }
Large piles of inline style and !important rules usually trade a local fix for global unpredictability. A constrained selector strategy and explicit design tokens are easier to reason about.
2.5. Responsive Design Is Not a List of Screen Resolutions
Responsive design preserves usability across viewport size, zoom, font scaling, input method, and content variation.
Testing only a few pixel breakpoints misses long translations, OS text scaling, keyboard focus, touch targets, reduced-motion preferences, high contrast, and orientation changes.
2.6. Web Accessibility
Accessibility is not an ARIA patch applied at the end. Native semantic HTML is the first option. A real button already carries keyboard, focus, and role behavior that a clickable div does not.
Core checks include meaningful heading order, programmatic form labels, complete keyboard operation, visible focus, non-color-only information, purposeful alternative text, sufficient contrast, and accessible announcements for dynamic state.
WCAG 2.2 is the current W3C Recommendation; automated testing should be complemented by keyboard and assistive-technology review.
2.7. JavaScript and ECMAScript
JavaScript's standardized language is ECMAScript. ECMAScript 2026 is the 17th edition of ECMA-262. Modern code can rely on language/platform primitives such as let/const, modules, promises, async/await, iterators, classes, and typed arrays according to its browser support target.
const state = Object.freeze({ retries: 3 });

export function normalize(value, min, max) {
  if (max <= min) throw new RangeError("invalid range");
  return (value - min) / (max - min);
}
Dynamic typing does not remove the need to validate untrusted external data.
2.8. DOM and the Event Model
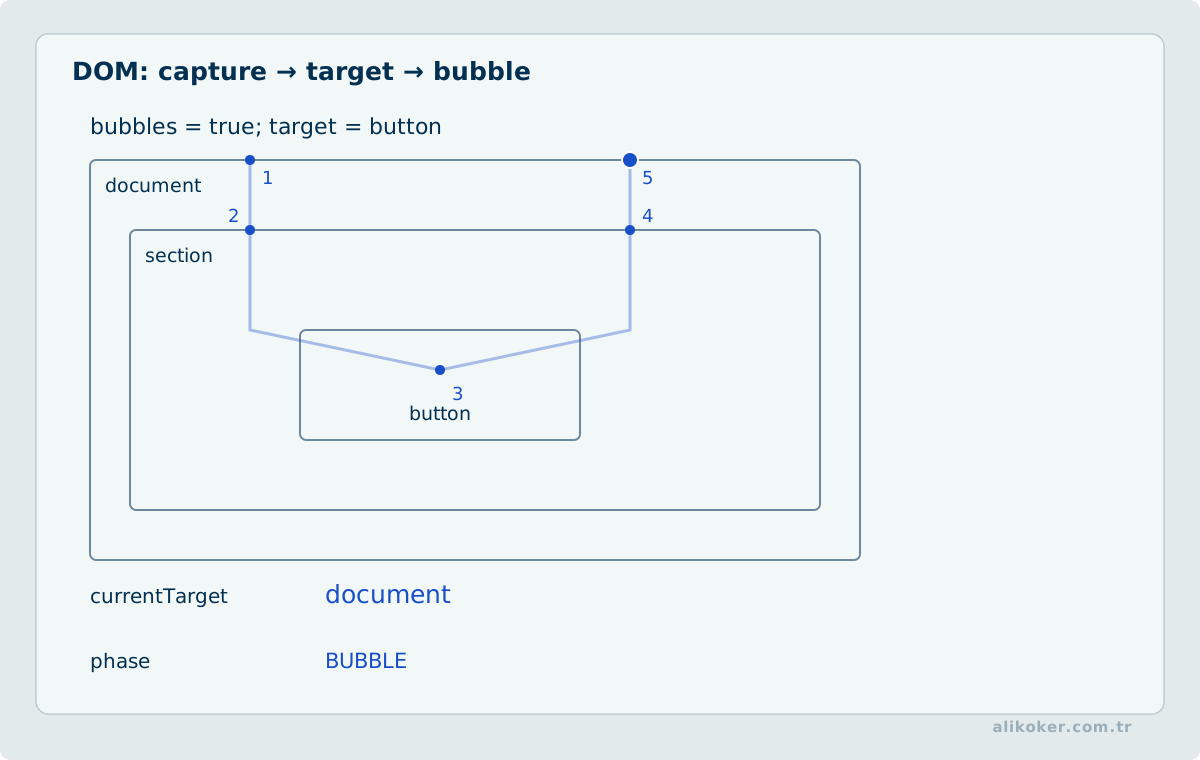
The browser represents an HTML document as a DOM tree. JavaScript reads and mutates the tree through standardized APIs.
const button = document.querySelector("#refresh");
const output = document.querySelector("#status");

button.addEventListener("click", async () => {
  output.textContent = "Loading";
  const response = await fetch("/api/status");
  output.textContent = response.ok ? "Ready" : `Error ${response.status}`;
});
External listeners separate behavior from markup and work better with restrictive CSP policies. Events may travel through capture, target, and bubble phases; delegation can avoid thousands of duplicate listeners for homogeneous elements.
2.9. 16A. Browser Rendering Pipeline and Process Model
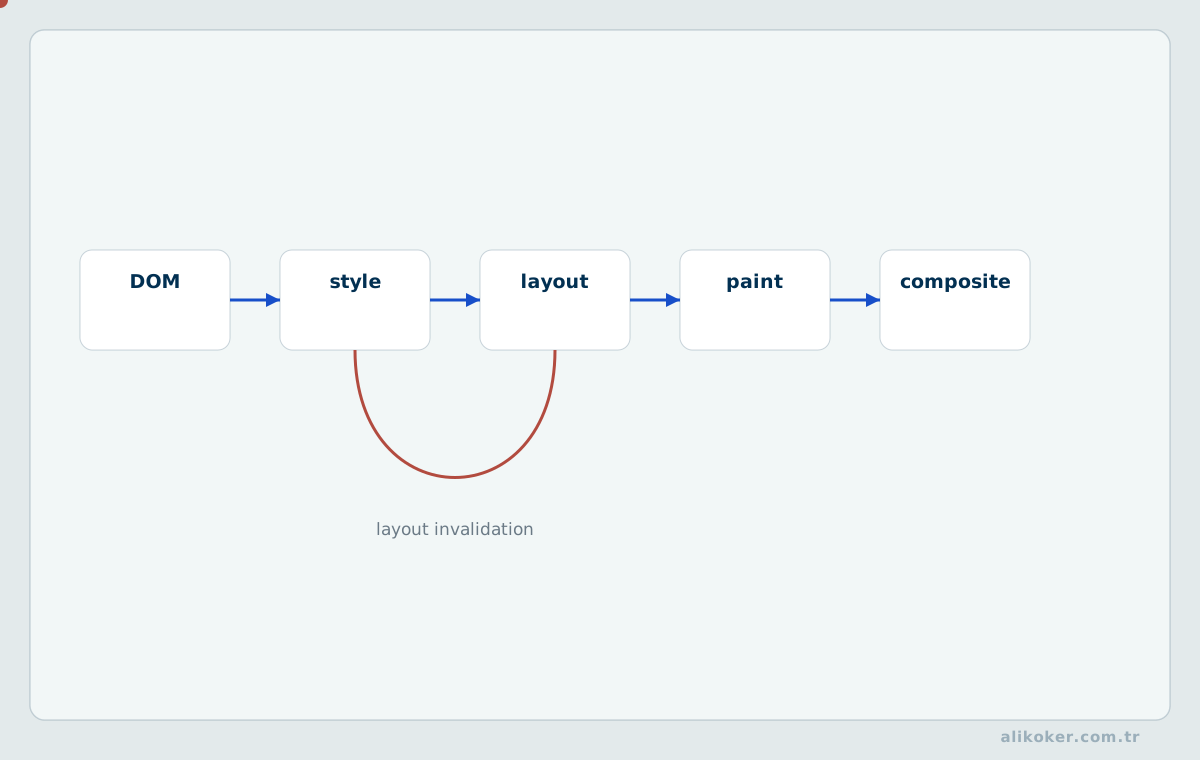
A DOM mutation is not a direct pixel mutation. The browser transforms HTML, CSS, and JavaScript state into visual output through several stages.
2.9.1. Style, Layout, Paint, and Composite
A simplified rendering path is:
DOM + CSSOM
    ↓
style calculation
    ↓
layout
    ↓
paint
    ↓
layer/composite
    ↓
screen
Style calculation determines which CSS rules apply to elements. Layout computes geometry and position. Paint creates drawing commands for text, backgrounds, borders, and other visual content. Compositing combines layers into the final frame.
Not every change must trigger the entire chain. Some transform or opacity animations can avoid layout or paint when suitable compositor layers are available, whereas geometry-changing properties can require broader recalculation.
2.9.2. Layout Thrashing
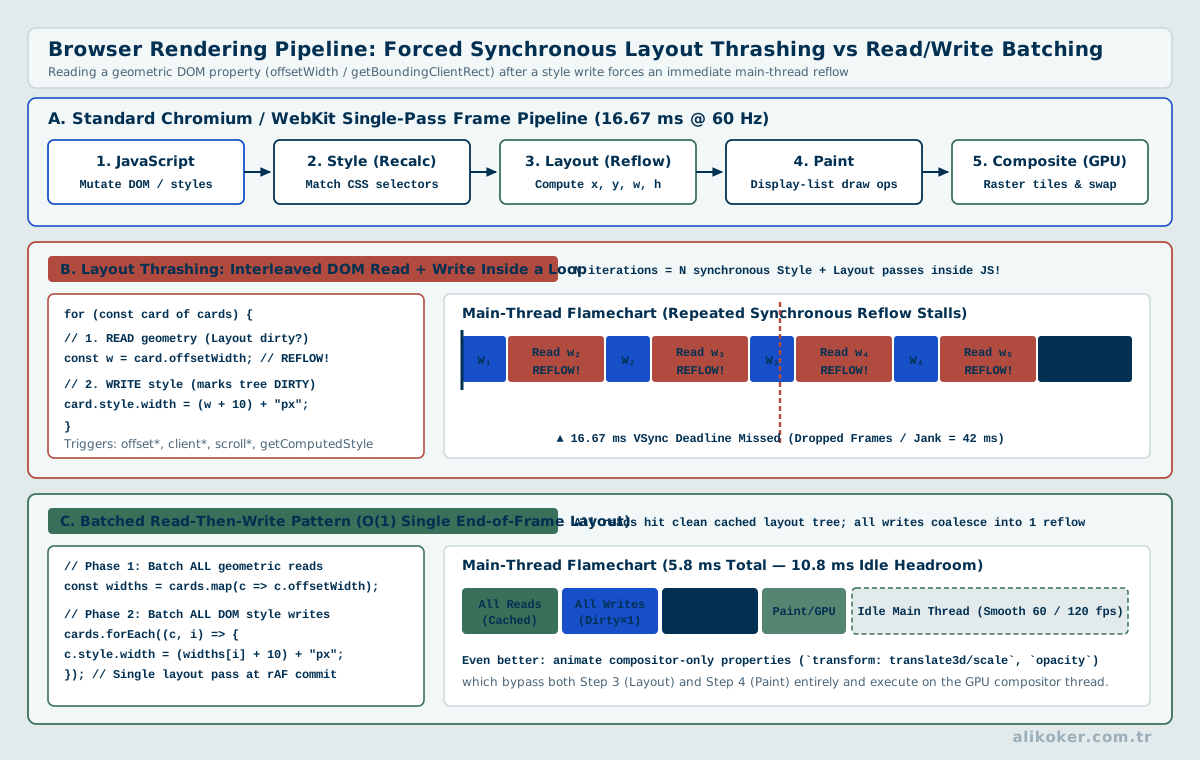
If JavaScript writes to the DOM and immediately reads geometry, the browser may be forced to complete pending style or layout work synchronously.
Poor pattern:
write DOM
read layout
write DOM
read layout
...
Related reads and writes should instead be grouped where practical. The actual performance impact should be verified with browser profiling and realistic workloads rather than assumed from the source code.
2.9.3. Main Thread and Compositor
JavaScript, DOM work, and much of rendering compete for main-thread time. A long JavaScript task can delay both input processing and visible frame production.
A compositor thread can advance some layer operations independently, but this does not mean that every CSS animation is free. Layer count, GPU memory, and paint work remain finite resources.
2.9.4. Browser Process Model
Modern browsers do not need to run an entire tab set inside one operating-system process. Browser, renderer, GPU, and utility responsibilities can be isolated in separate processes. Mechanisms such as site isolation can strengthen origin boundaries at the process level.
The exact architecture is browser-dependent; a web application should not rely on a particular number of processes.
2.9.5. Navigation and Bfcache
Navigating away does not always destroy the previous page completely. An eligible page can be frozen in the back/forward cache (bfcache) and restored quickly during history navigation.
The lifecycle should therefore not be modeled only as:
load -> unloadpageshow, pagehide, visibility changes, and persistent resources should be tested together with navigation behavior.
The central performance principle is that network time, JavaScript execution, layout/paint, and user-visible latency are different measurements. Improving one does not automatically improve the others.
2.10. Modules and Loading Behavior
Modern browser modules use type="module", have module scope, and support import/export.
<script type="module" src="/assets/app.js"></script>A bundler is not mandatory. Bundling, minification, tree-shaking, and code splitting should be chosen according to target browsers, cache strategy, and delivery cost.
Unit 3: Client State, Identity, and Browser Security
When retaining client-side state, distinguish information needed for user continuity from state for which the server remains authoritative. Test cross-tab changes, back navigation, and expired sessions as separate scenarios. Hiding a control in the interface is not authorization. The client must respect server-side checks and must not present missing or failed data as successful completion.
3.1. The Event Loop and Asynchronous Execution
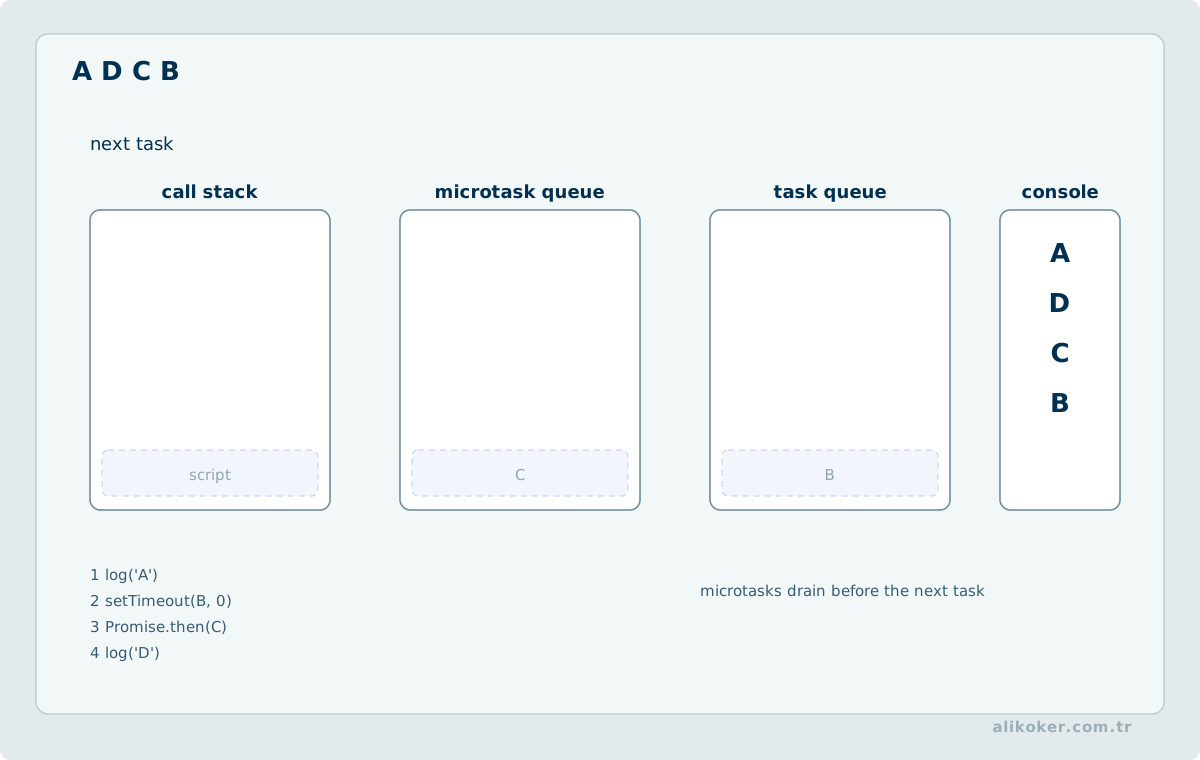
JavaScript call stack
          |
          v
      event loop
       /
      v        v
microtask    task queue
 queue         |
             /
       v     v
   render opportunity
Browser JavaScript runs through an event-loop model. Promise continuations use the microtask queue, while timers and user events arrive through task sources. Long CPU work can block input and rendering.
For CPU-heavy work, chunking, Web Workers, or appropriate WebAssembly modules can be considered. async/await does not automatically move work to another thread; it structures promise-based asynchronous control flow.
3.1.1. Preventing a Stale Asynchronous Response from Overriding Newer User Intent
Browser completion order does not have to match user-action order. A user can select filter A and immediately switch to filter B while the request for A finishes later on the network. If every response is committed directly to the DOM, A can overwrite B even though the server behaved correctly; the defect belongs to the client lifecycle.
Two common controls address the problem. The obsolete request can be cancelled with AbortController, or each request can receive a monotonically increasing generation number and only the newest generation may commit its result. Because cancellation is not always a complete end-to-end guarantee across every layer, generation checking can provide an additional guard in critical interfaces.
request A ---- slow -----\
                         X--> stale result ignored
request B -- fast --> committed to the view
The pattern matters in search, autocomplete, tab changes, date filters, and periodic refresh. Cancellation should not normally be presented as an application error; it often represents a normal lifecycle event caused by the user making a newer decision.
Rendering cost belongs to the same flow. If frequent small updates repeatedly trigger layout work, UI latency can rise even when networking is fast. Batching suitable visual updates with requestAnimationFrame moves them toward the next paint boundary and separates data arrival from rendering cadence. This is particularly useful in data-dense interfaces and connects directly to UI/UX Engineering.
3.2. Fetch API
The Fetch Standard unifies requests, responses, redirects, CORS, credentials, and service-worker interaction.
async function loadDevice(id, signal) {
  const response = await fetch(`/api/devices/${encodeURIComponent(id)}`, {
    headers: { Accept: "application/json" },
    signal
  });

  if (!response.ok) throw new Error(`HTTP ${response.status}`);
  return response.json();
}
Fetch generally rejects on a network-level failure, not because a server returned 404 or 500; status handling is an application responsibility.
3.3. Same-origin Policy and CORS
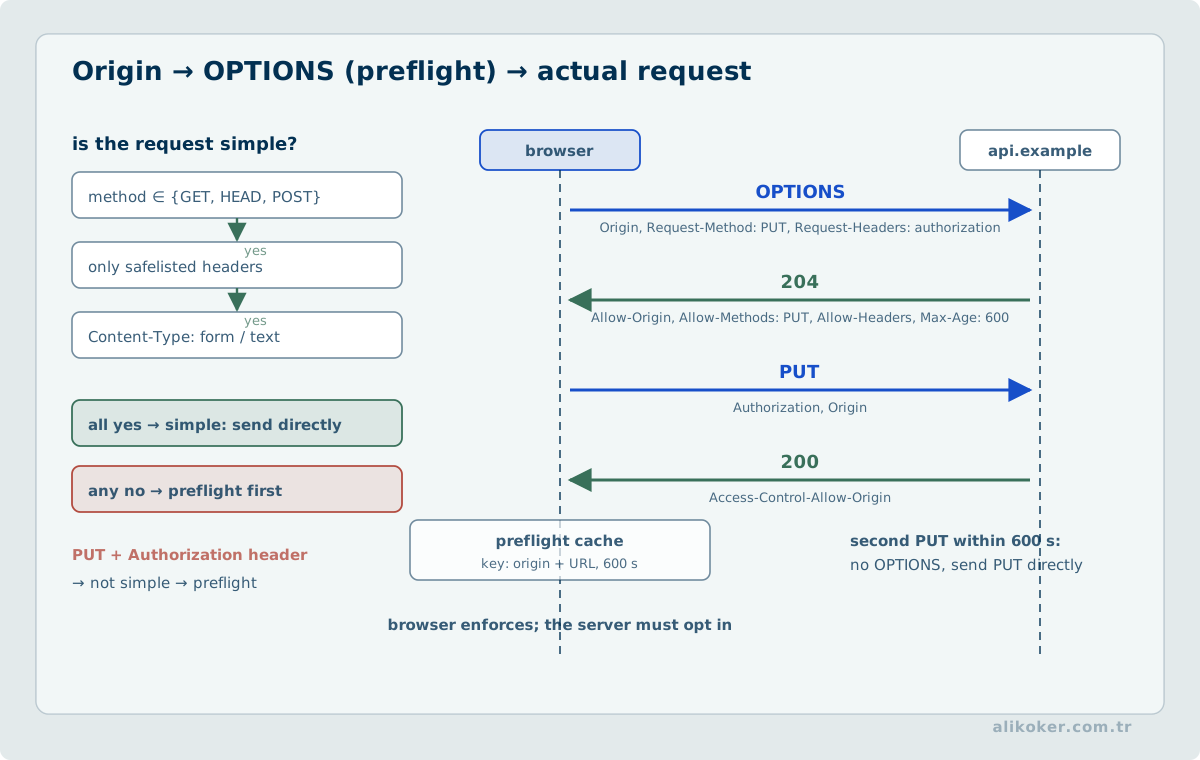
The same-origin policy limits how code from one origin can read resources from another. CORS is an HTTP opt-in mechanism allowing a server to expose selected cross-origin responses.
CORS is not authentication and is not server-side authorization. A non-browser client can still issue the request; CORS primarily governs whether browser code may access the response.
Credentialed CORS requires particular care around allowed origins and preflight behavior.
3.4. Cookies, Sessions, and Browser Storage
Cookies can be attached to HTTP requests automatically. Secure, HttpOnly, and SameSite should be selected according to the session model.
Set-Cookie: session=opaque-value; Path=/; Secure; HttpOnly; SameSite=LaxlocalStorage and sessionStorage are readable by page JavaScript and therefore exposed to successful XSS. IndexedDB is a better primitive for larger structured client data.
A server-side session is not the cookie itself; the cookie may contain only an opaque session identifier while state lives on the server.
3.5. Authentication and Authorization
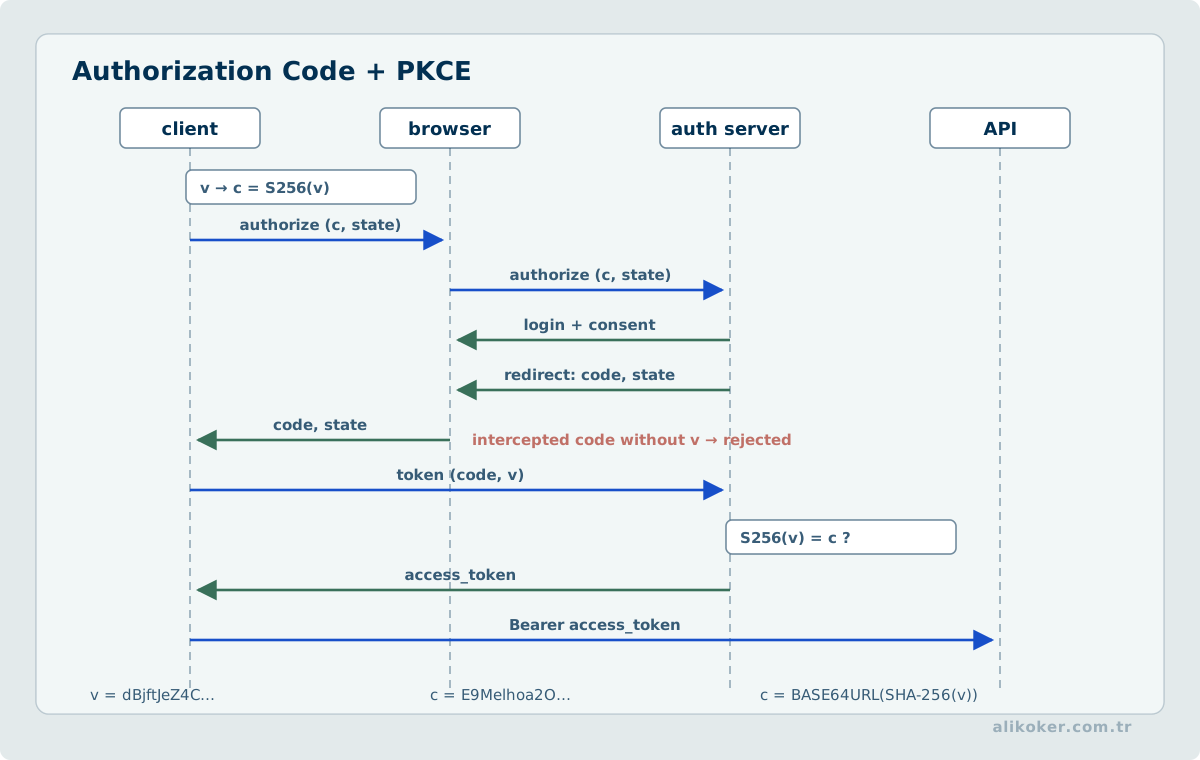
Authentication answers "who is this?"; authorization answers "what may this principal do?" Session cookies, bearer tokens, OAuth/OIDC, and passkeys create different trust and lifecycle models.
Authorization must be enforced at the server endpoint and object level. Hiding a button in the UI is not access control.
3.6. CSRF, XSS, and Injection
CSRF abuses automatically attached browser credentials. SameSite cookies reduce some exposure; some architectures still require CSRF tokens or origin checks.
XSS occurs when untrusted data reaches an executable HTML/JavaScript context. Context-correct output encoding, safe DOM APIs, template auto-escaping, and CSP form layered defenses.
SQL, command, and template injection occur when data is concatenated into executable syntax. Parameterized APIs are the primary control.
3.7. Content Security Policy
CSP restricts which resources a page may load or execute and can limit the impact of script injection.
Content-Security-Policy: default-src 'self'; script-src 'self'; object-src 'none'; base-uri 'self'It is a defense-in-depth mechanism, not a replacement for secure data handling. Broad wildcards and a dependency on inline script weaken the policy.
3.8. Separating HTTPS from Application Sessions
HTTPS protects the client-server channel but does not by itself prevent stolen session tokens, client-side XSS, or incorrect application authorization. A secure session begins with TLS certificate identity checking, then a cryptographically random session identifier and appropriately scoped Secure, HttpOnly, SameSite, Path, and Domain cookie settings. Authorization must still be enforced server-side on every request.
CSRF defenses address a different threat from channel encryption. Session regeneration, logout, expiration, and privilege elevation tests reveal replay and fixation risks. TLS 1.3 key derivation belongs to Cryptology; this unit examines the web application's trust decisions.
Unit 4: Web APIs, Real-Time Delivery, and New Execution Models
4.1. OWASP Top 10:2025 as a Design Checklist
OWASP Top 10:2025 highlights broken access control, security misconfiguration, software supply chain failures, cryptographic failures, injection, insecure design, authentication failures, software/data integrity failures, logging and alerting failures, and mishandling of exceptional conditions.
The list is an awareness baseline rather than a complete security specification. Threat modeling, abuse cases, dependency provenance, secret management, and safe failure behavior remain necessary.
4.2. REST, Resources, and JSON
REST is not a JSON format. It uses resource-oriented identifiers and standard HTTP semantics, with stateless/cache-aware interactions where appropriate.
POST /api/devices
Content-Type: application/json

{"serial":"A-1042","enabled":true}
JSON contracts should define dates, money, large integers, binary data, and polymorphic payloads explicitly. API versioning is a compatibility policy, not merely a /v1 prefix.
4.2.1. Contract Checks for Generated API Code
A REST endpoint produced by an agent is not complete merely because it returns a successful HTTP response. Resource identity, input validation, error codes, authorization, replay behavior, and the response schema expected by clients must be verified together. A 200 OK response with malformed JSON or the wrong content type can violate the client contract. Whether repeated POST operations need idempotency depends on business rules; the HTTP method alone does not guarantee safe replay.
Contract tests should cover invalid requests, unauthorized access, missing resources, and server failures. A description such as OpenAPI supports documentation and automated checking, but its correspondence with runtime behavior still needs validation. Separate frontend and backend tests do not replace an end-to-end scenario covering their integration.
4.3. Where XML Fits Today
XML remains useful for document interchange, enterprise integrations, signed structures, and configuration. It is not a replacement for HTML.
For browser documents, text/html is the normal syntax. WHATWG explicitly does not recommend the XML syntax for new HTML content because it is essentially unmaintained and does not evolve with HTML features.
4.4. WebSocket, Server-Sent Events, and real-time Delivery
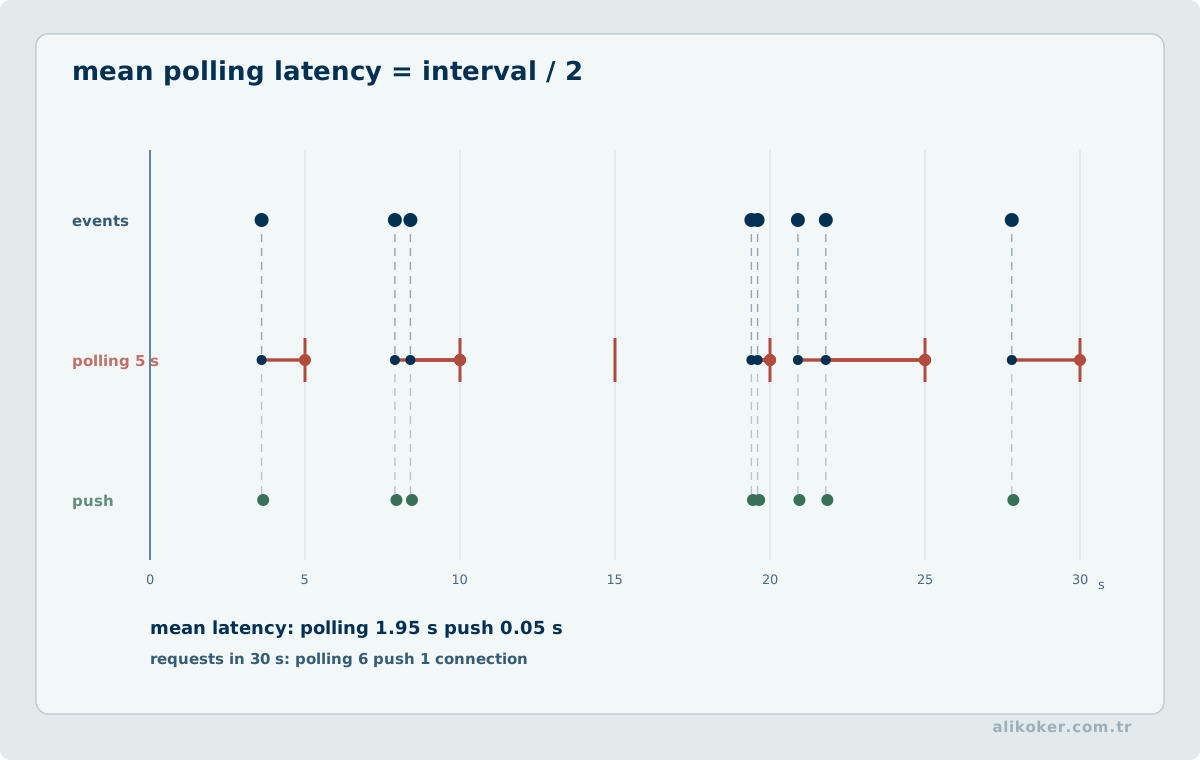
Polling is not the only delivery model. Server-Sent Events can provide a one-way event stream, while WebSocket gives a long-lived bidirectional channel.
Selection should consider connection count, proxy timeouts, reconnection, backpressure, ordering/duplication, authentication renewal, and horizontal fan-out. "WebSocket is faster" is not sufficient architecture analysis.
4.5. Service Workers and Progressive Web Apps
A service worker is an event-driven browser component operating between a page and network resources. It can provide offline caches and programmable fetch strategies.
Cache-first behavior suits immutable assets but can be dangerous for personalized or rapidly changing data. Service-worker cache is separate from the normal HTTP cache and needs its own invalidation lifecycle.
4.6. Request Races and Stale Responses in the Browser
When a user starts searches A and B in succession, A is not guaranteed to finish first. If A completes after B, a naïve interface can overwrite the current results with those of an obsolete search. The defect arises from binding UI state to response arrival order rather than to the currently selected query.
Assigning a monotonically increasing generation number to each request permits a response to update the interface only when its generation is current. AbortController can cancel an unneeded fetch, but cancellation does not guarantee that the server stopped processing or rolled back side effects. Generation validation therefore remains necessary independently of cancellation. Even a finally handler clearing a loading indicator must verify that it does not clear the state of a newer request.
The search field, selected record, and detail pane must share the same query context. Displaying results from B while keeping a detail item from A can lead to a misleading interpretation. Query identity, results, loading state, error, and selection are managed as one lifecycle. Suspending rendering loops in hidden tabs is not merely a performance measure; it also prevents obsolete state from overwriting the view when that tab becomes visible again.
Unit 5: Caching, Performance, Media, and Server-Side Computing
5.1. WebAssembly
The W3C WebAssembly Core Specification dated 12 August 2026 describes release 3.0 and is published as a Candidate Recommendation Draft. WebAssembly is a safe, portable, low-level code format useful for compute-heavy modules, codecs, simulation, and bringing libraries from other language ecosystems to the web; it is not a general replacement for JavaScript or the DOM.
A Wasm module interacts with the host through explicitly provided imports, which is part of its sandbox model.
5.2. Caching and Conditional Requests
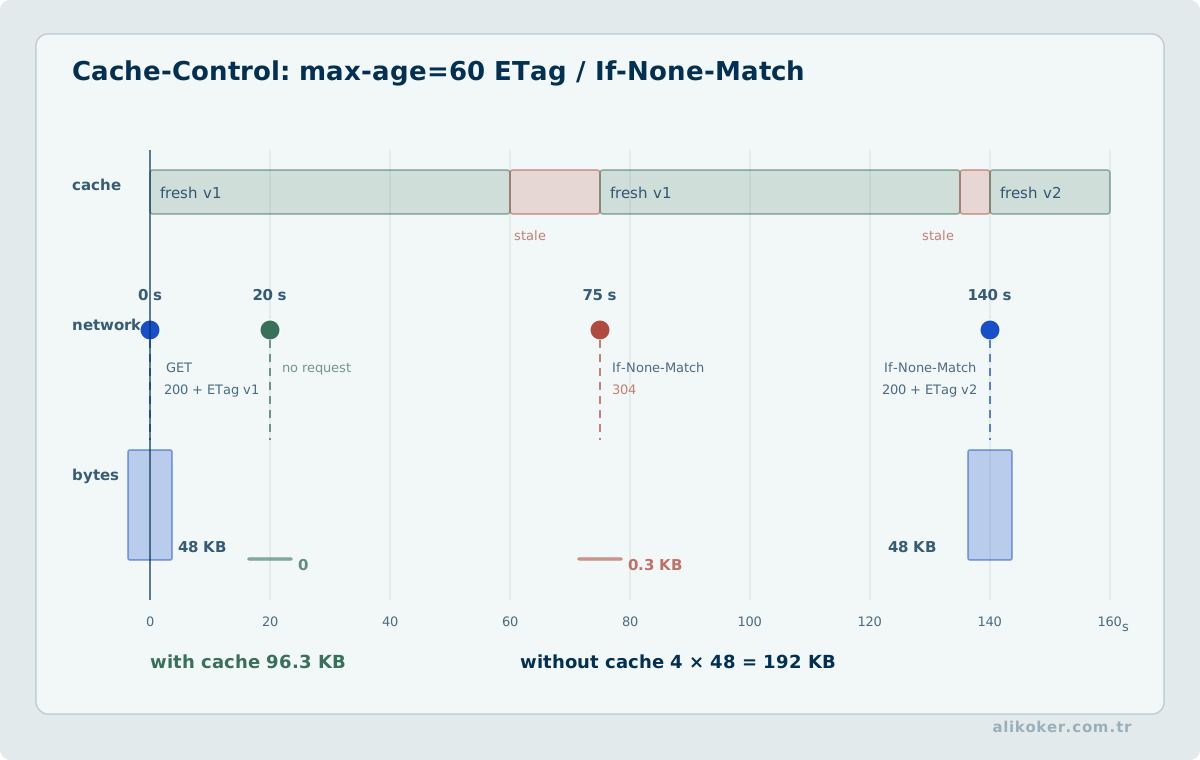
Avoiding unnecessary transfer is often cheaper than accelerating it. Cache-Control, ETag, Last-Modified, If-None-Match, and Vary allow browsers and intermediaries to reuse or revalidate content.
browser cache
      |
      v
CDN / edge cache
      |
      v
reverse-proxy cache
      |
      v
application cache
      |
      v
database / origin system

TTL / ETag / Last-Modified -> freshness decision
Cache-Control: public, max-age=31536000, immutableThat policy suits hash-named immutable assets but should not be copied to personalized pages or authorization-dependent API responses.
Lookup order in a two-level cache is an application contract. Registering two cache managers in sequence does not necessarily mean that a key miss in the first cache triggers a value lookup in the second. A composite manager may resolve the cache object first; L1 miss handling and L2 fallback require an explicit implementation. Define promotion from L2 to L1, negative caching, differing TTLs, and invalidation order as part of the design.
HTTP validators such as ETag and Last-Modified do not by themselves guarantee correct server-side state. Sharing user- or permission-scoped responses under the wrong cache key risks data disclosure, not merely reduced performance. Tests should establish tenant/user isolation, an accepted stale-data bound after updates, and correct representation-version handling for conditional requests.
5.3. Performance Spans Network and Rendering
User-perceived latency includes DNS, TCP/QUIC/TLS setup, server time, payload size, parsing, JavaScript, style/layout, and painting.
A useful optimization order is to measure first, remove unnecessary requests, reduce payload/image size, fix caching, reduce render-blocking work, split long main-thread tasks, and control DOM/layout churn.
A fast response is not necessarily a fast interface. Improving server time to first byte can leave client JSON parsing, DOM updates, and main-thread long tasks unchanged. Compressing a large response may reduce transferred bytes while increasing CPU consumption on both server and browser. Measure TTFB, transfer duration, applicable long-task observations through PerformanceObserver, and elapsed time from user action to usable UI separately.
When testing a new JSON serialization setting, regression checks must preserve response completeness, field names, encoding, and numeric precision. A smaller payload is a win only if its meaning remains correct. A desktop result on a warm local network cannot stand in for mobile experience without specifying network profile and cache state.
5.4. Images and Media
Responsive images can use srcset and sizes; noncritical images can use native lazy loading.
<img
  src="/img/device-800.webp"
  srcset="/img/device-400.webp 400w, /img/device-800.webp 800w"
  sizes="(max-width: 600px) 100vw, 800px"
  width="800"
  height="450"
  alt="Device telemetry panel">
Explicit dimensions reduce layout shifts. Indiscriminate lazy loading of above-the-fold critical content can make performance worse.
5.5. Server-side Programming Independent of Framework
Regardless of language, a typical request crosses similar responsibilities:
request parsing
-> authentication/authorization
-> validation
-> domain logic
-> transaction / external calls
-> response mapping
Java/Spring Boot, C#/.NET, Go, Python, PHP, Node.js, and other stacks expose different APIs around the same concerns.
HTTP request/session objects should not become domain-model dependencies without a clear reason.
5.6. What CGI, Classic ASP, and Web Forms Teach Historically
CGI, Classic ASP, VBScript, and ASP.NET Web Forms are not current default choices for new general web applications, but their designs explain the evolution of server-side web programming.
CGI made per-request process costs obvious. Classic ASP popularized server-side scripting. Web Forms attempted to project a desktop event model onto stateless HTTP using ViewState, server controls, and postback.
Modern server-rendered frameworks and APIs expose HTTP semantics more directly. The durable concepts behind old Request, Response, Session, form GET/POST, and XML examples remain relevant.
5.7. jQuery, VBScript, Flash, and Historical Editors
jQuery solved real browser-normalization, selector, AJAX, and event problems when browser APIs differed substantially. Modern DOM APIs, querySelector, Fetch, and standardized events remove many basic reasons to add it, although existing applications can still depend on it.
Browser VBScript is not part of the modern web platform, and the Flash plug-in model has disappeared from the mainstream platform. They belong in migration/history sections rather than current implementation guidance.
Product names such as FrontPage, HomeSite, and Visual InterDev are not durable web knowledge. Standards-conformant output, version control, build/testing, and deployment are.
5.8. E-mail, FTP, and Telnet in Web Systems
SMTP, IMAP, and POP are e-mail protocols, not Web protocols. Web applications may reach mail infrastructure through SMTP or an HTTP mail API.
FTP was historically common for publishing files; SFTP/SSH or HTTPS-based deployment is generally preferred when secure transport is required. Telnet is not a secure remote administration channel; SSH is its common secure operational replacement.
The durable lesson is to understand protocol security and transport properties rather than memorize old client software names.
5.9. Native Extension and Parser Security in Server Runtimes
A server-side language may provide memory management while file uploads, compression, image decoding, and protocol parsing still depend on native code. HTTP request bodies and multipart forms cross trust boundaries from content-type handling through parsing and file-system access. Security design must extend beyond filename-extension checks to size limits, decoded content, resource consumption, and error paths.
Native libraries and extension versions belong in the application dependency inventory. A request-size limit does not imply that every intermediate parser allocation obeys the same bound. Secure deployment includes runtime patches, least privilege, isolated temporary storage, processing deadlines, and regression tests using malformed inputs.
Unit 6: Deployment, Discoverability, Testing, and Production Reliability
6.1. Deployment: from Hosting Upload to Delivery Pipeline
Publishing a web application can involve artifact/image production, immutable version identifiers, configuration and secret separation, migration ordering, health/readiness checks, reverse proxy/TLS, DNS/CDN configuration, staged rollout, and rollback.
A static site, a monolith, and a distributed service should not be forced through the same deployment strategy.
6.1.1. Deployment Boundary for Agent-generated Changes
Compiling automatically generated web code is not sufficient evidence for deployment. The deployed artifact must be linked to the source revision, environment configuration must be managed without embedded secrets, and behavior affecting existing API consumers must be tested. Changes to dependency versions or build tooling are material changes to artifact provenance.
Before deployment, the permitted scope, verified paths, rollback to the previous release, and user-visible failure behavior should be explicit. Agents can accelerate preparation and testing, but release authority follows the system's security and change-management policy. Traceable delivery links the validated change to the deployed artifact.
6.2. SEO, Metadata, and Machine Discoverability
title, meta descriptions, canonical links, robots directives, structured data, and sitemaps serve different discovery functions.
Historical meta keywords practices are not a modern SEO center. Robots directives are not access control and cannot protect confidential content.
Semantic HTML, useful content, stable URLs, and correct HTTP status codes are core technical SEO properties.
6.3. Testing Strategy
Web testing should be layered:
- unit tests for pure business rules,
- integration/contract tests for HTTP contracts,
- realistic integration tests for persistence,
- browser end-to-end tests for critical journeys,
- automated and manual accessibility tests,
- security testing including dependencies and targeted attacks,
- performance tests using production-like load and browser profiles.
Using E2E tests for every detail creates a slow and brittle suite. Prefer the cheapest deterministic layer that can prove the property.
6.4. Production Reliability
Browsers and networks are unreliable components. Requests can be cancelled, users can double-submit, proxies can time out, and retries can race with late responses.
Critical endpoints should therefore consider idempotency, timeout, cancellation, bounded retry, and duplicate handling. Optimistic UI also needs reconciliation and rollback behavior.
6.5. Related Courses
For server-side Java development see Spring Boot; for C#/.NET see C# Programming; for language semantics see Programming Languages; for transport and routing see Computer Networks; for persistence see Database Management Systems; and for legal constraints see Information Technology Law.
6.6. Idempotency, Retries, and the HTTP Boundary
A client not receiving a response does not mean the server failed to process the request; the connection can fail after the side effect but before the response arrives. Retry behavior must therefore follow HTTP semantics and the idempotency of the business operation.
GET, PUT, and DELETE are defined as idempotent at the protocol level, while operations such as payment creation often need an explicit idempotency key when exposed through POST.
Retries require a total deadline, exponential backoff, jitter, and a clear set of retryable failures. Otherwise synchronized retries can amplify an outage.
6.7. Verifying Web Behavior End to End
Browser, CDN/proxy, application server, and database all influence different parts of a request. A failure cannot always be explained from only the browser console or only server logs; request IDs and timelines help connect layers.
Tests should preserve HTTP semantics. Cache headers, idempotency, redirects, CORS, cookie attributes, and content types are broader contracts than “the page loads.”
Browser behavior can be version-dependent. Platform features should be checked against primary/standards sources such as MDN, WHATWG, or W3C together with support data. Progressive enhancement can preserve core functionality when a feature is unavailable.
6.8. Backpressure and Data Evolution in Web Systems
In data-intensive systems, reliability, scalability, and maintainability are different consequences of the same design decisions. The data-path latency of a web request is not determined by endpoint code alone; indexing, data encoding and serialization, connection and transaction boundaries, cache and replication behavior, and streaming or pagination strategy together determine whether the end-to-end query path remains predictable. Derived data should have an explicit source of truth, reproducibility path, and latency budget.
- Manage API versioning and data-schema evolution independently but coherently.
- Apply bounded queues or load shedding when admission rate exceeds downstream capacity.
- Tie cache invalidation policy to source-of-truth and consistency expectations.
References
- Brendan Gregg. Systems Performance: Enterprise and the Cloud. Pearson Education, 2014.
- Ecma International, ECMA-262 — ECMAScript 2026 Language Specification. https://ecma-international.org/publications-and-standards/standards/ecma-262/
- Eric, Mihail. The Modern Software Developer (CS146S). Stanford University, course materials, 2025–2026. https://themodernsoftware.dev/
- IETF, RFC 9110 — HTTP Semantics. https://www.rfc-editor.org/rfc/rfc9110
- IETF, RFC 9113 — HTTP/2. https://www.rfc-editor.org/rfc/rfc9113
- IETF, RFC 9114 — HTTP/3. https://www.rfc-editor.org/rfc/rfc9114
- Martin Kleppmann. Designing Data-Intensive Applications. 1st ed. O’Reilly Media, 2016.
- MDN Web Docs, Web platform documentation. https://developer.mozilla.org/
- OWASP, OWASP Top 10:2025. https://top10.owasp.org/2025/
- W3C WebAssembly Working Group, WebAssembly Core Specification 3.0. https://www.w3.org/TR/wasm-core/
- W3C, Content Security Policy Level 3. https://www.w3.org/TR/CSP3/
- W3C, Web Content Accessibility Guidelines (WCAG) 2.2. https://www.w3.org/TR/WCAG22/
- WHATWG, Fetch Living Standard. https://fetch.spec.whatwg.org/
- WHATWG, HTML Living Standard. https://html.spec.whatwg.org/
- IETF. RFC 9846, TLS 1.3, 2026. https://www.rfc-editor.org/info/rfc9846